
An AI client can diagnose time-series dependence and compute bootstrap confidence intervals for mean, median, standard deviation, or variance.
Also known as astrogilda/tsbootstrap
- Stars
- 97
- Tools
- 2
- Downloads, 30 days
- 3,620
- Latest version
- 0.7.3
- Last commit
- Nov 14, 2026
- License
- MIT
What is tsbootstrap MCP?
tsbootstrap is an AI client can diagnose time-series dependence and compute bootstrap confidence intervals for mean, median, standard deviation, or variance. It exposes 2 tools, such as diagnose_series, bootstrap_confidence_interval.
Summary generated from the project's README
About tsbootstrap MCP server
tsbootstrap provides a specialized toolkit for time-series bootstrapping and uncertainty quantification. It is designed for developers and data scientists who need to compute confidence intervals or prediction bands while accounting for temporal dependence in their data. The library supports various resampling strategies, including IID, moving block, circular block, and stationary block methods, as well as more complex model-based approaches like ARIMA, VAR, and sieve bootstraps.
Users can interact with the library directly in Python or use the included read-only MCP server via stdio transport. The MCP server allows an AI client to perform diagnostics and statistical calculations without writing custom code. This server is limited to series with up to 500 observations and 500 replicates. For larger datasets or advanced uncertainty workflows like EnbPI, users should use the core library locally. The system is optimized for performance, offering compiled reducers that can significantly reduce peak memory usage and execution time compared to standard materialization methods.
What you can do with it
- 1Generate forecast prediction bandsUsers can create forward-looking forecast intervals for an autoregressive model.
Written from the project's README. Every use case is checked against a quote from it.
How to install tsbootstrap MCP
Formats verified 10 Nov 2026Add to CursorAdd to GooseInstall tsbootstrap MCP in Claude Code
$ claude mcp add tsbootstrap -- uvx --from 'tsbootstrap[mcp]' tsbootstrap-mcpInstall tsbootstrap MCP in Cursor
~/.cursor/mcp.json
{
  "mcpServers": {
    "tsbootstrap": {
      "command": "uvx",
      "args": [
        "--from",
        "tsbootstrap[mcp]",
        "tsbootstrap-mcp"
      ]
    }
  }
}Install tsbootstrap MCP in VS Code
.vscode/mcp.json
{
  "servers": {
    "tsbootstrap": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "--from",
        "tsbootstrap[mcp]",
        "tsbootstrap-mcp"
      ]
    }
  }
}Install tsbootstrap MCP in VS Code CLI
$ code --add-mcp '{"name":"tsbootstrap","type":"stdio","command":"uvx","args":["--from","tsbootstrap[mcp]","tsbootstrap-mcp"]}'Install tsbootstrap MCP in Claude Desktop
claude_desktop_config.json
{
  "mcpServers": {
    "tsbootstrap": {
      "command": "uvx",
      "args": [
        "--from",
        "tsbootstrap[mcp]",
        "tsbootstrap-mcp"
      ]
    }
  }
}Install tsbootstrap MCP in Codex
$ codex mcp add tsbootstrap -- uvx --from 'tsbootstrap[mcp]' tsbootstrap-mcpInstall tsbootstrap MCP in Codex config.toml
~/.codex/config.toml
[mcp_servers.tsbootstrap]
command = "uvx"
args = ["--from", "tsbootstrap[mcp]", "tsbootstrap-mcp"]
Install tsbootstrap MCP in Gemini CLI
$ gemini mcp add -s user tsbootstrap uvx -- --from 'tsbootstrap[mcp]' tsbootstrap-mcpInstall tsbootstrap MCP in Gemini settings.json
~/.gemini/settings.json
{
  "mcpServers": {
    "tsbootstrap": {
      "command": "uvx",
      "args": [
        "--from",
        "tsbootstrap[mcp]",
        "tsbootstrap-mcp"
      ]
    }
  }
}Started by HostedMCP on 16 Nov 2026
We ran this command for tsbootstrap 0.7.3 in an isolated container with no network and no keys. It answered and listed 2 tools.
tsbootstrap MCP tools 2
Read from the server with tools/listdiagnose_seriesRead-onlyRead-only. Diagnose a short univariate time series: serial dependence, stationarity, a recommended Politis-White block length, and which bootstrap methods this server supports for it. Accepts at most 500 observations. For larger series, model-based methods, or the uq layer, use the tsbootstrap library directly in a local script.
bootstrap_confidence_intervalRead-onlyRead-only. Compute a percentile confidence interval for a statistic (mean/median/std/variance) of a short series using a block or i.i.d. bootstrap. Accepts at most 500 observations and at most 500 replicates; random_state is required for reproducibility. For larger series, model-based methods, or the uq layer, use the tsbootstrap library directly in a local script.
| diagnose_series | Read-only. Diagnose a short univariate time series: serial dependence, stationarity, a recommended Politis-White block length, and which bootstrap methods this server supports for it. Accepts at most 500 observations. For larger series, model-based methods, or the uq layer, use the tsbootstrap library directly in a local script. | Read-only |
| bootstrap_confidence_interval | Read-only. Compute a percentile confidence interval for a statistic (mean/median/std/variance) of a short series using a block or i.i.d. bootstrap. Accepts at most 500 observations and at most 500 replicates; random_state is required for reproducibility. For larger series, model-based methods, or the uq layer, use the tsbootstrap library directly in a local script. | Read-only |
Automated checks
Ran Nov 16, 2026Full report →Passed our automated checks. That is not a security audit: read the code and give the server the narrowest access it needs. How checks work

- Source repository linked and reachableastrogilda/tsbootstrap is public and reachablegithub.com/astrogilda/tsbootstrap ↗Pass
- Package names this repository as its sourcetsbootstrap names astrogilda/tsbootstrap as sourcepypi.org/project/tsbootstrap/ ↗Pass
- Build provenance (Sigstore attestation)Sigstore attestation for tsbootstrappypi.org/project/tsbootstrap/ ↗Pass
- Open source license (OSI)MITspdx.org/licenses/MIT.html ↗Pass
- Commit or release in the last yearLast commit or release 2026-11-14github.com/astrogilda/tsbootstrap ↗Pass
- OpenSSF ScorecardOpenSSF Scorecard 7.4 / 10; weakest: Code-Review 0, CII-Best-Practices 0, Security-Policy 0scorecard.dev/viewer/?uri=github.com/astrogilda/tsbootstrap ↗Pass
- Package name not close to a popular packageNo popular package one edit away from tsbootstrapPass
- No critical advisory in the package or its dependencies10 resolved dependencies checked; no critical advisoryosv.dev ↗Pass
- No hidden instructions to the model2 tool descriptions and the README read; no override phrases, credential paths or hidden charactersPass
- Destructive tools are labelledNo tool named like delete, drop or execPass
- Remote endpoint answers the MCP handshakeNot checked
README
View on GitHub
tsbootstrap makes the sampling design explicit through typed method specifications,
assumption metadata, and replayable run metadata. Its optional compiled reducers
calculate statistics while generating resamples, and its panel API supports
unequal-length series.
| Measured proof | Result | Scope and receipt |
|---|---|---|
Four shared methods against arch.apply |
Faster in all 16 measured cells; 4.7x to 33x on the longer series | IID, moving, circular, stationary; mean statistic; n=2,000, B=999 or 10,000; optional compiled reducer on eight cores; settled-min receipt and methodology. |
| Ten thousand series, one fused pass | 220x faster than a per-series reduce loop | Time, B=1,000, n=200, MovingBlock(20) mean; panel benchmark. |
| Same panel, without the resampled-path tensor | 141x less peak memory than materialize-then-reduce | Memory, same workload; materialization is a different baseline from the time comparison; panel benchmark. |
Read the engineering behind these results in Count the bytes, not the FLOPs and Ten thousand series, one pass.
| Capability | In tsbootstrap |
Comparison boundary |
|---|---|---|
| Shared observation bootstrap methods | IID, moving block, circular block, stationary block | All four are also in arch.bootstrap and are covered by the measured comparison. |
| Additional resampling | Non-overlapping and tapered blocks; recursive AR, ARIMA, VAR and sieve bootstraps; wild and block-wild innovations | Outside the four-method head-to-head benchmark. |
| Uncertainty workflows | Bootstrap confidence intervals, AR forecast bands, EnbPI and adaptive conformal calibration | These workflows are not part of the speed comparison. |
| Large panels and tooling | Ragged-panel reducers, method diagnostics and metadata, optional read-only MCP tools | The panel benchmark compares three tsbootstrap workflows, not arch. |
The speed numbers describe the compiled named-statistic reduce path; the
default NumPy backend, arbitrary Python statistics, materialized samples, and
single-thread execution have distinct performance profiles. See the
full benchmark grid for those paths. The arch bootstrap
module also offers independent-samples bootstrapping, and the broader arch
package includes econometric tools. Neither is covered by this four-method
comparison.
📒 Table of Contents
- 🚀 Getting Started
- ⚡ Performance
- 📚 Articles
- 🧩 Modules
- 🗺 Roadmap
- 🤝 Contributing
- 📄 License
- 📍 Time Series Bootstrapping Methods intro
- 👏 Contributors
🚀 Getting Started
🎮 Using tsbootstrap
tsbootstrap exposes one typed entry point, bootstrap, configured with a method
specification. The same call works for every method.
import numpy as np
from tsbootstrap import bootstrap, MovingBlock

rng = np.random.default_rng(0)
innovations = rng.standard_normal(200)
x = np.empty_like(innovations)
x[0] = innovations[0]
for t in range(1, len(x)):
    x[t] = 0.6 * x[t - 1] + innovations[t]

result = bootstrap(x, method=MovingBlock(block_length="auto"), n_bootstraps=999, random_state=0)

samples = result.values()  # (n_bootstraps, n) resampled series
oob = result.get_oob_mask()  # (n_bootstraps, n) out-of-bag mask
Choose a method spec for the structure you need (block lengths default to the automatic Politis-White selection):
from tsbootstrap import StationaryBlock, ResidualBootstrap, SieveAR, AR, ARIMA, diagnose

bootstrap(x, method=StationaryBlock(avg_block_length="auto"))

# recursive model-based bootstraps; only ARIMA needs the models extra
bootstrap(x, method=ResidualBootstrap(model=AR(order=2)))
bootstrap(x, method=ResidualBootstrap(model=ARIMA(order=(1, 1, 1))))
bootstrap(x, method=SieveAR())

# not sure which fits? ask:
print(diagnose(x).recommended_methods)
Inputs can be NumPy arrays, lists, or pandas / Polars DataFrames and Series. The
result is a BootstrapResult carrying the samples, provenance metadata, and
out-of-bag / in-bag primitives. For the sktime ecosystem, the same methods are
also available as estimator classes (MovingBlockBootstrap, ARResidualBootstrap,
SieveBootstrap, and the rest) under tsbootstrap.adapters.
Uncertainty quantification
The uq layer turns resampled series into prediction intervals. forecast_intervals
gives forward forecast bands for an AR model; EnbPIEnsemble produces out-of-bag
prediction intervals for an sklearn-style regressor, with calibrators for stationary,
volatility-clustered, and drifting data (static, sliding window, and the adaptive ACI,
AgACI, and NexCP schemes); and bootstrap_reduce streams a per-replicate statistic so
calibration scales to large replicate counts without holding every path in memory.
from tsbootstrap import AR, forecast_intervals

lower, upper, median = forecast_intervals(x, model=AR(order=2), horizon=12, alpha=0.1)
For a confidence interval on a statistic of one series, conf_int runs the bootstrap
and reads the interval in one call:
from tsbootstrap import IID, conf_int

lower, upper, point = conf_int(x, "mean", method=IID(), kind="bca", alpha=0.1)
The conformal pieces (EnbPIEnsemble and the calibrators) need the uq extra
(scikit-learn). The interactive
tutorial gallery
works through every method on real and synthetic data, including a "which bootstrap
should I use?" decision guide.
MCP server
tsbootstrap ships a read-only Model Context Protocol
server so an MCP client (an LLM agent, an IDE) can diagnose a short series and compute a
bootstrap confidence interval without writing any Python. Run it with no install step:
uvx --from "tsbootstrap[mcp]" tsbootstrap-mcp
It speaks the stdio transport and exposes exactly two read-only tools:
diagnose_series: serial-dependence and stationarity diagnostics, a recommended Politis-White block length, and the bootstrap methods the server supports for the series.bootstrap_confidence_interval: a percentile confidence interval for the mean, median, std, or variance, using an i.i.d. or block bootstrap.
Both tools accept at most 500 observations and run at most 500 replicates. For larger series, model-based methods, or the uncertainty layer, use the library directly in a local script.
📦 Installation
Requires Python 3.10 or higher.
# with uv (recommended):
uv add tsbootstrap                   # core: i.i.d. and block methods
uv add "tsbootstrap[models]"         # adds statsmodels for ARIMA

# with pip:
pip install tsbootstrap
pip install "tsbootstrap[models]"
AR, VAR, and sieve fitting use the core NumPy implementation. ARIMA imports
statsmodels lazily and requires the models extra.
⚡ Performance
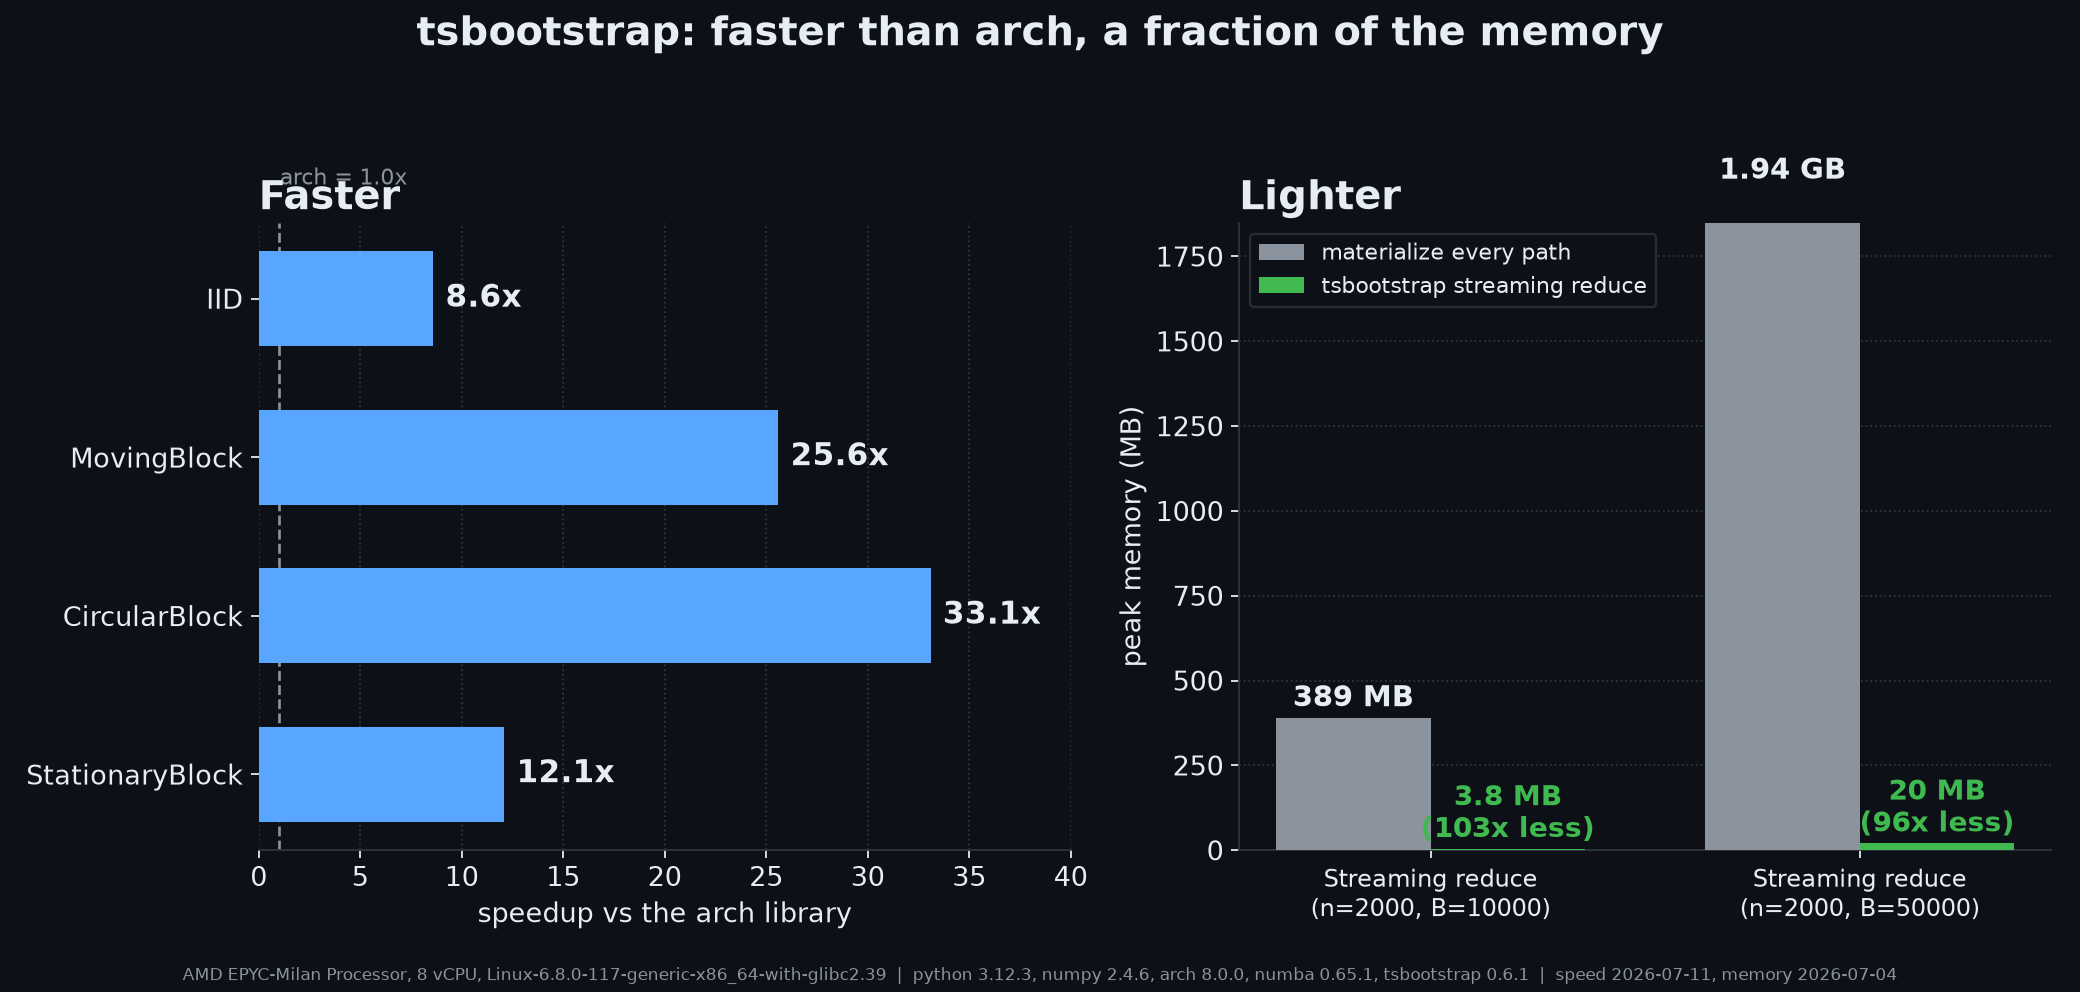
Left: speedup of the compiled reduce path over the arch library on the four overlapping methods. Right: peak memory before and after on the two headline reduce workloads (baseline = materialize every path, then reduce). The figure and the table below are generated from the committed benchmark data in benchmarks/results/; regenerate with python benchmarks/plot_launch.py.
tsbootstrap ships an optional compiled backend (backend="compiled", via the
[accel] extra). On the measured mean-reduction workload it is faster than
arch.apply for each of the four shared
resampling methods. The table below is the speedup of
the streaming reduce path over arch.apply on an 8-core CPU (higher is better),
read from benchmarks/results/vs_arch_ccx33_2026-07-11_settled.json
(the settled-min statistic; methodology in benchmarks/README.md).
| Method | n=200, B=999 | n=200, B=10000 | n=2000, B=999 | n=2000, B=10000 |
|---|---|---|---|---|
| IID | 15x | 19x | 4.7x | 8.6x |
| MovingBlock | 38x | 61x | 9.8x | 26x |
| CircularBlock | 41x | 66x | 13x | 33x |
| StationaryBlock | 19x | 24x | 6.8x | 12x |
Read these as sustained gains of roughly 4.7x to 33x on the larger n=2000
workloads; the very large small-n multiples come from arch's per-replicate
Python callback in bs.apply, whose overhead dominates its runtime when each
resample is cheap, so they measure that overhead as much as the compiled kernel.
The compiled reduce fuses index build, gather, and reduction into one pass, so
peak memory stays flat in the number of replicates: at n=2000 the streaming
reduce holds about 20 MB at B=50000 where materializing every replicate takes
about 1.94 GB (roughly 96x lighter), from
benchmarks/results/membench_2026-07-04.json.
The multivariate and ragged-panel reduce
paths have no equivalent in arch. The panel reduce
(bootstrap_reduce_panel) returns the full per-series bootstrap distribution
of the statistic (n_bootstraps x num_series), so quantile and tail workflows
on an estimator are served directly with no replicate tensor. Use the
materializing path only when the workflow consumes the resampled paths
themselves. Full methodology,
single-thread behavior, and the reproduction script are in
benchmarks/README.md.
# install the compiled backend
uv add "tsbootstrap[accel]"
# or
pip install "tsbootstrap[accel]"
📚 Articles
Deep dives on the statistics and engineering behind the library, with worked examples and animations:
- Your bootstrap is lying to you: why the ordinary i.i.d. bootstrap collapses on autocorrelated data (a nominal 90% interval that covers 49.6% of the time) and how block resampling repairs it.
- When your errors aren't equal: the wild bootstrap for heteroskedastic errors, and what a block-wild variant preserves.
- Count the bytes, not the FLOPs: the memory-wall engineering behind the compiled backend, with hardware-counter receipts.
- Ten thousand series, one pass: the panel benchmark, its separate time and memory baselines, and the ragged-panel design.
🧩 Modules
Package layout:
| Area | Module(s) | Role |
|---|---|---|
| Public API | api.py, methods.py, results.py, errors.py, diagnostics.py |
the bootstrap() entry point, typed method specs, structured results, error taxonomy, and diagnose() |
| Infrastructure | rng.py, validation.py, dispatch.py, metadata.py |
deterministic RNG contract, input coercion (incl. the narwhals DataFrame boundary), spec to executor dispatch, method metadata |
| Block methods | block/ |
vectorized index kernels, true Politis-Romano stationary, energy-normalized tapering, PWSD block length, OOB primitives |
| Model methods | model/, engines/ |
model fitting, stability guards, and recursive AR/ARMA/VAR simulation |
| Uncertainty quantification | uq/ |
classical confidence intervals (percentile, basic, studentized, BCa) via conf_int, EnbPI prediction intervals, the static / sliding-window / ACI / AgACI / NexCP calibrators, and AR forecast intervals |
| Ecosystem | adapters/ |
skbase / sktime estimator classes over the functional core |
🗺 Roadmap
The full, living roadmap is issue #181. Highlights:
Near term:
- Out-of-sample forecast intervals for ARIMA and VAR (currently AR-only).
Candidate methods (good first issues):
- Generalized block (#104), local block (#105), and frequency-domain (#107) bootstraps.
- A GARCH / volatility residual bootstrap, and the smooth-kernel dependent-wild bootstrap.
Distributed execution (Dask / Spark / Ray), an async layer, and a string-keyed
factory were considered and deliberately left out. The library is a CPU-bound,
single-process toolkit.
🤝 Contributing
See our good first issues for getting started.
Developer setup
-
Fork the tsbootstrap repository
-
Clone the fork to local:
git clone https://github.com/astrogilda/tsbootstrap
- In the local repository root, sync the locked development environment with uv:
uv sync --extra dev
-
uv creates an isolated virtual environment from
uv.lockand editable-installs the package, so changes to the package are reflected in your environment automatically. Run tools through the environment withuv run(for exampleuv run pytest). -
Install the pre-commit hooks:
uv run pre-commit install
The hooks run ruff, formatting, and the other code-quality checks on each commit.
Verifying the Installation
Verify the installation:
python -c "import tsbootstrap; print(tsbootstrap.__version__)"
This prints the installed version.
Contribution workflow
- Create a new branch with a descriptive name (e.g.,
new-feature-branchorbugfix-issue-123).
git checkout -b new-feature-branch
- Make changes to the project's codebase.
- Commit your changes to your local branch with a clear commit message that explains the changes you've made.
git commit -m 'Implemented new feature.'
- Push your changes to your forked repository on GitHub using the following command
git push origin new-feature-branch
- Create a new pull request to the original project repository. In the pull request, describe the changes you've made and why they're necessary.
🧪 Running Tests
To run all tests, in your developer environment, run:
uv run pytest tests/
That runs in a single process. Add the pytest-xdist flags CI uses to run the suite in parallel, which is several times faster on a multi-core machine:
uv run pytest tests/ -n auto --dist loadscope --max-worker-restart 3
The sktime adapter classes can be validated with sktime's estimator checks:
from sktime.utils import check_estimator
from tsbootstrap.adapters import MovingBlockBootstrap

check_estimator(MovingBlockBootstrap)
Contribution guide
See CONTRIBUTING.md for details.
📄 License
This project is licensed under the ℹ️ MIT License. See the LICENSE file for additional info.
👏 Contributors
Contributors:
This project follows the all-contributors specification. Contributions of any kind welcome!
📍 Time Series Bootstrapping
tsbootstrap implements bootstrap methods for univariate and multivariate time
series. Block methods resample nearby observations together; model-based
methods simulate new paths from fitted dynamics.
Overview
An i.i.d. bootstrap breaks serial dependence by resampling individual observations. Block and model-based methods retain aspects of dependence under their stated assumptions. Interval coverage still depends on the data regime, the statistic, and the method choice; see the uncertainty guide.
Bootstrapping methodology
tsbootstrap resamples either the observations directly (i.i.d. and block methods) or
the innovations of a fitted model (residual and sieve methods), respecting the
chronological order and dependence structure of the data.
Block bootstrap
Block methods resample blocks of consecutive observations to preserve short-range dependence. The block length defaults to the automatic Politis-White (2004) selection.
- Moving block (
MovingBlock): overlapping fixed-length blocks (Kunsch 1989). - Circular block (
CircularBlock): blocks wrap around the series end (Politis-Romano 1992). - Stationary block (
StationaryBlock): geometric block lengths with independent uniform restart points (Politis-Romano 1994). - Non-overlapping block (
NonOverlappingBlock): disjoint blocks (Carlstein 1986). - Tapered block (
TaperedBlock(window=...)): blocks weighted by an energy-normalized window (Bartlett, Blackman, Hamming, Hann, or Tukey; Paparoditis-Politis 2001).
Residual bootstrap
For dependent data with a good model fit, ResidualBootstrap(model=...) regenerates the
series recursively from the fitted dynamics and resampled, centered innovations (not
fitted + residuals). Supported models: AR, ARIMA, and VAR (multivariate). A
non-stationary fit is refused (or skipped, per stability_policy) rather than producing
explosive paths.
Sieve bootstrap
SieveAR selects an autoregressive order on the original series, then runs the AR recursion;
suited to data with autoregressive structure.
Innovation resamplers
The innovation argument on ResidualBootstrap and SieveAR controls how the centered
residuals are resampled. It defaults to IID (uniform resampling); two wild resamplers relax
the exchangeability that assumes.
- Wild (
Wild(distribution=...)): multiplies each residual in place by a mean-zero, unit-variance draw (e*_t = v_t * e_hat_t), keeping its time position and magnitude, so it stays valid under conditional heteroskedasticity (Wu 1986; Liu 1988; Rademacher default per Davidson-Flachaire 2008). - Block-wild (
BlockWild(block_length=...)): holds one multiplier constant across each block of residuals, so serial dependence left by a misspecified mean survives the resampling (piecewise-constant dependent wild bootstrap, Shao 2010).
Both require the host model's burn_in=0 and initial="fixed" defaults so the multipliers
align one-to-one with the residuals.
Deferred to a later release
Markov resampling, the distribution bootstrap, GARCH/volatility models, and frequency-domain / seasonal block methods are planned for a future version. The statistic-preserving method has been removed.
tsbootstrap MCP questions
How do I add tsbootstrap MCP to Claude Code?
Run claude mcp add tsbootstrap -- uvx --from 'tsbootstrap[mcp]' tsbootstrap-mcp in your terminal. Add --scope user to make it available in every project.
How do I add tsbootstrap MCP to Cursor?
Open ~/.cursor/mcp.json and add the server under mcpServers, using the Cursor config shown in the install section above.
What tools does tsbootstrap MCP provide?
It exposes 2 tools, including diagnose_series, bootstrap_confidence_interval.
What can the tsbootstrap MCP server do?
The server provides two read-only tools: one for diagnosing serial-dependence and stationarity, and another for computing percentile confidence intervals for statistics like mean or variance.
Are there limits to the data size the MCP server can handle?
Yes, both tools are limited to a maximum of 500 observations and up to 500 replicates.