
web-data MCP server
Commit Nov 1, 2026Provides quality-gated web scraping via Apify with schema validation, quality scoring, and RAG-ready document chunking for AI agents.
Also known as fctpe/web-data-mcp
- Stars
- 1
- Tools
- 7
- Downloads, 30 days
- —
- Latest version
- —
- Last commit
- Nov 1, 2026
- License
- MIT
What is web-data MCP?
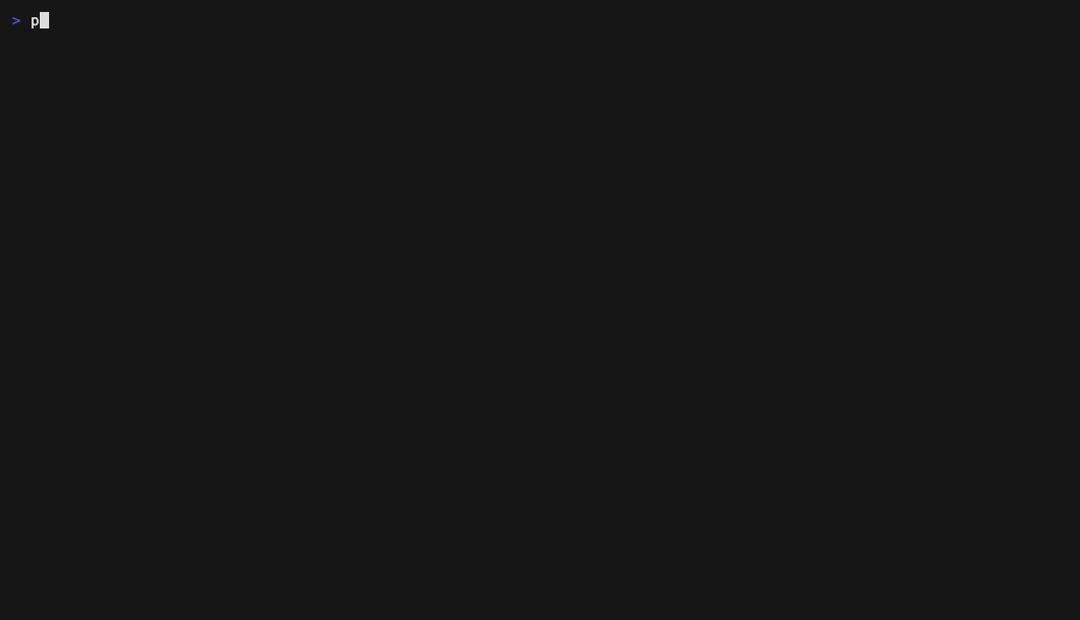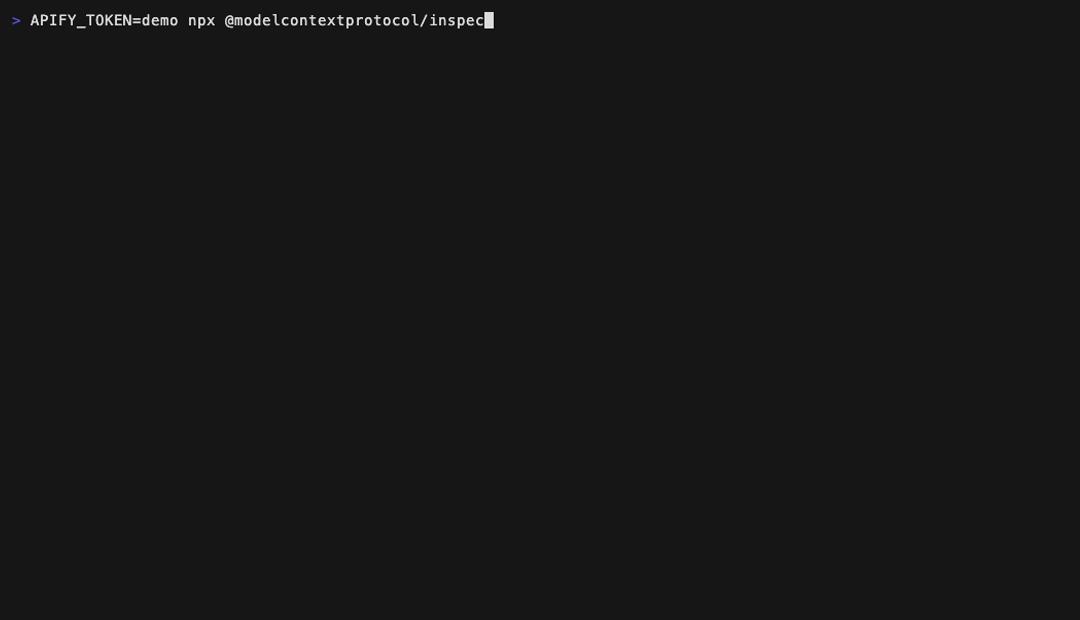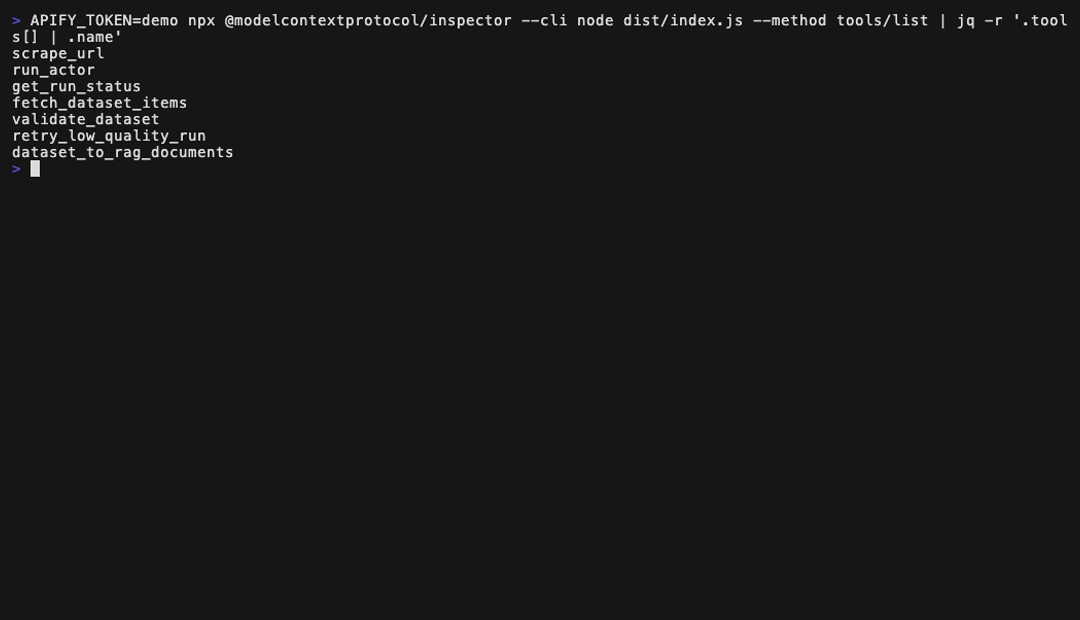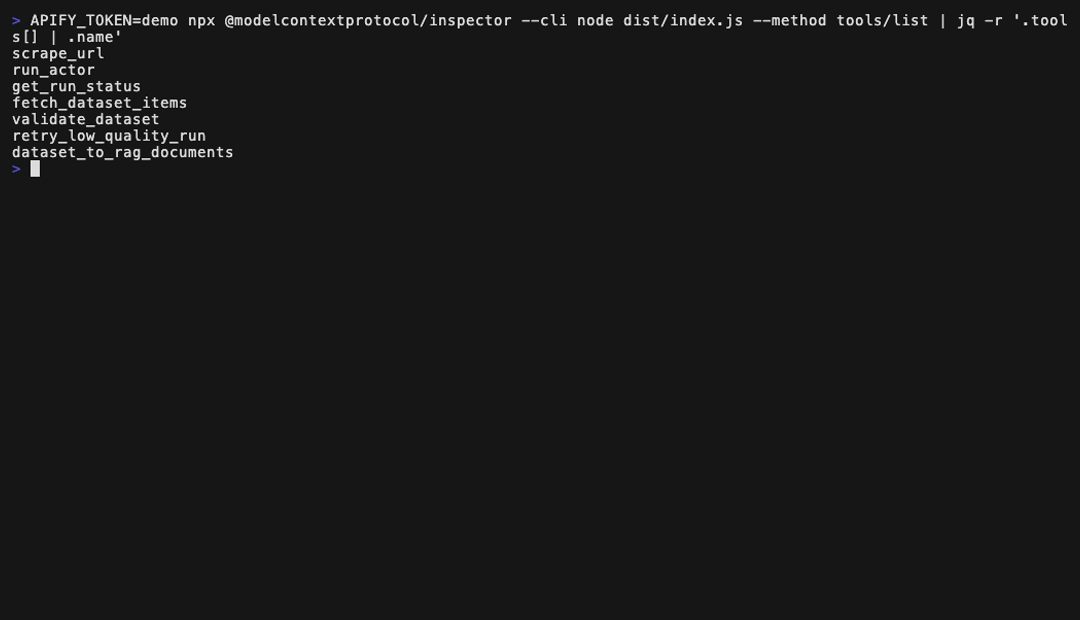
web-data provides quality-gated web scraping via Apify with schema validation, quality scoring, and RAG-ready document chunking for AI agents. It exposes 7 tools, such as scrape_url, run_actor, get_run_status.
Summary generated from the project's README
About web-data MCP server
Developers building AI agents that require reliable web data can use this server to perform quality-gated scraping via Apify. Unlike standard passthrough tools, it validates scraped content against JSON schemas, calculates quality scores, and automatically retries failed attempts using residential proxies or browser crawlers when bot-walls are detected. It is designed for use with stdio clients like Claude Desktop, Cursor, or Claude Code, and requires an Apify token for operation.
The server provides a curated set of seven tools to manage the entire data lifecycle. Users can crawl specific URLs with scrape_url, manage large-scale jobs using run_actor and get_run_status, or perform paginated reads with fetch_dataset_items. To prepare data for retrieval-augmented generation, the dataset_to_rag_documents tool transforms raw results into token-bounded, markdown or text chunks with stable content-hash IDs. This ensures that agents reason over verified, structured information rather than empty records or access denied pages.
What you can do with it
- 1Automated high-quality web scrapingAn agent can crawl a URL and automatically retry with stronger anti-blocking settings if the initial scrape fails quality checks.
- 2Validating scraped datasets against schemasA developer can verify that a large dataset meets specific structural requirements by checking its schema pass rate and completeness.
- 3Preparing data for RAG pipelinesTransform scraped datasets into embedding-ready chunks that include source attribution and content hashes for idempotent updates.
- 4Escalating scraping attempts for blocked contentIf a run returns low quality due to bot detection, the system can re-run the task using residential proxies and browser crawlers.
Written from the project's README. Every use case is checked against a quote from it.
web-data MCP tools 7
Detected from the READMEscrape_urlrun_actorget_run_statusfetch_dataset_itemsvalidate_datasetretry_low_quality_rundataset_to_rag_documents
Configuration
APIFY_TOKENOPENAI_API_KEYOTEL_EXPORTER_OTLP_ENDPOINTWEB_DATA_MCP_HTTP_TOKEN
Automated checks
Ran Nov 14, 2026Full report →Not verified yet. A server needs a score of 80, no serious finding, and enough data for us to check. How checks work · What to fix for more points

- Source repository linked and reachablefctpe/web-data-mcp is public and reachablegithub.com/fctpe/web-data-mcp ↗Pass
- Package names this repository as its sourceNot checked
- Build provenance (Sigstore attestation)Not checked
- Open source license (OSI)MITspdx.org/licenses/MIT.html ↗Pass
- Commit or release in the last yearLast commit or release 2026-11-01github.com/fctpe/web-data-mcp ↗Pass
- OpenSSF ScorecardNot checked
- Package name not close to a popular packageNot checked
- No critical advisory in the package or its dependenciesNot checked
- No hidden instructions to the model7 tool descriptions and the README read; no override phrases, credential paths or hidden charactersPass
- Destructive tools are labelledNo tool named like delete, drop or execPass
- Remote endpoint answers the MCP handshakeNot checked
README
View on GitHubweb-data-mcp


Quality-gated web data for AI agents. An MCP server that runs Apify scraping actors and — unlike a raw passthrough — validates what came back, scores it, retries with stronger anti-blocking settings when it's bad, and hands your agent embedding-ready chunks instead of a JSON dump.
Scraped data fails silently: the run "succeeds" but the dataset is a wall of Access Denied pages, half-empty records, or duplicates — and an agent that can't see quality will happily reason over garbage. This server makes data quality a first-class, machine-readable part of every tool result.
Quickstart
git clone https://github.com/fctpe/web-data-mcp && cd web-data-mcp
pnpm install && pnpm build

# poke every tool in a UI
APIFY_TOKEN=your-token npx @modelcontextprotocol/inspector node dist/index.js

# Claude Code
claude mcp add web-data --env APIFY_TOKEN=your-token -- node /path/to/web-data-mcp/dist/index.js

# Claude Desktop / Cursor / any stdio client — add to your MCP config:
{
  "mcpServers": {
    "web-data": {
      "command": "node",
      "args": ["/path/to/web-data-mcp/dist/index.js"],
      "env": { "APIFY_TOKEN": "your-token" }
    }
  }
}
(npx -y web-data-mcp will replace the node path once the first npm release is published — the bin entry is already wired.)
Free Apify accounts include $5/month of platform credit — enough for hundreds of scrape_url calls with the default cheerio crawler.
Why not the official Apify MCP server?
Use both — they solve different problems.
| apify/apify-mcp-server | web-data-mcp | |
|---|---|---|
| Scope | The whole Apify store (5,000+ actors), dynamic discovery | 7 curated tools around one workflow |
| Output | Raw dataset passthrough | Schema-validated, quality-scored, token-budgeted |
| Bad scrapes | Your agent finds out the hard way | Scored (quality.score), auto-retried with escalating anti-blocking settings |
| RAG | Bring your own chunking | dataset_to_rag_documents: token-bounded chunks, overlap, stable content-hash ids |
| Guardrails | Platform-level | Actor allowlist, SSRF guard (no private hosts), clamped memory/timeouts, hard response token caps |
flowchart LR
    A[AI agent] -->|MCP| S[web-data-mcp]
    S --> R[Run actor]
    R --> Q{Quality gate<br/>schema · completeness<br/>dupes · bot-wall}
    Q -->|score >= threshold| C[Chunked, token-bounded,<br/>hash-addressed documents]
    Q -->|score < threshold| E[Escalate: residential proxies,<br/>browser crawler] --> R
    C --> A
Tools
| Tool | What it does |
|---|---|
scrape_url |
One call: crawl a URL → wait → score → auto-retry if blocked → return markdown + quality block |
run_actor |
Start an allowlisted actor with explicit input; returns run_id / dataset_id handles |
get_run_status |
Poll a run (read-only, free) |
fetch_dataset_items |
Paginated reads with field projection, summary/items modes, hard token budget |
validate_dataset |
Score a dataset against your JSON Schema: pass rate, completeness, dupes, bot-wall rate |
retry_low_quality_run |
Re-run with residential proxies → browser crawler until quality clears your threshold |
dataset_to_rag_documents |
Emit embedding-ready chunks (jsonl/markdown/text) with source attribution + content hashes |
Every tool ships inputSchema and outputSchema (structured output), behavior annotations (readOnlyHint, openWorldHint, …), and returns failures as model-readable isError results with a concrete next step — so the calling agent can self-correct instead of stalling.
What the agent actually gets back
The point is that data quality is structured, not buried in prose. A validate_dataset result (or the quality block on scrape_url) looks like this — the agent can branch on score, and sample_failures tells it exactly what's wrong:
{
  "quality": {
    "score": 0.42,                    // composite 0..1 — below threshold, don't trust
    "item_count": 50,
    "schema_pass_rate": 0.30,         // 70% of items fail your JSON Schema
    "field_completeness": 0.61,
    "duplicate_rate": 0.12,
    "suspected_block_rate": 0.24,     // ~1 in 4 items look like a bot wall
    "sample_failures": [
      "item[3]/price: must be number",
      "item[7]: 'Attention Required | Cloudflare' in body"
    ]
  }
}
And a dataset_to_rag_documents line — token-bounded, source-attributed, content-hashed for idempotent upserts:
{ "id": "a1b2c3d4e5f6-0", "source": "https://example.com/p/12", "chunkIndex": 0,
  "chunkCount": 1, "tokenCount": 118, "content": "…clean extracted text…",
  "metadata": { "crawledAt": "2026-07-12T…" } }
How the quality gate works
Each dataset sample is scored 0..1 from four signals:
- Schema pass rate — items validated against your JSON Schema (Ajv), weighted 0.4 when present
- Field completeness — non-empty cells across the union of fields
- Duplicate rate — hash-based duplicate detection
- Bot-wall rate — items containing block markers (
Access Denied,captcha,verify you are human, …)
Blocking is a ceiling, not a deduction. The final score is min(weighted, 1 - bot_wall_rate): a batch cannot score higher than the fraction of it that is actually content. Blocking also gets its own retry trigger (suspected_block_rate > 0.2) independent of the score, because a partly blocked batch caps above the threshold — 25% walls caps at 0.75 — and a quarter of your pages being walls is exactly what a residential proxy is for. Why it is a ceiling and not a weighted term, and the test that attacks it: ADR 0005 and test/blocked-content.test.ts.
These are heuristics. The bot-wall regex catches common block pages, not all of them, and field completeness treats every field as equally important. Schema pass rate is the signal to rely on when you can supply a schema.
Below threshold, retries escalate: original input → + residential proxies → + playwright:firefox with dynamic-content waits. Attempts and both scores are reported in the structured result, and exhausted retries return an isError result that tells the agent why and what to try next — naming a bot wall as a bot wall rather than as "low quality", since a model told the content is thin will summarise the wall as if it were the page.
Results
Reproducible from this repository: 106 offline tests (pnpm test, no network, no token) plus a real stdio protocol round trip through the client library the repo already depends on — node scripts/stdio-smoke.mjs prints smoke ok — 7 tools, all with output schemas, guard + tool call live.
Beyond that, the full MCP flow (run → status → fetch → validate → RAG) was pressure-tested against three production Apify actors with real workloads. Those runs committed no artifact and are not reproducible here — reproducing them needs an APIFY_TOKEN and named actor slugs — so no quality score or item count from them is quoted. scripts/live-smoke.mjs is the documented path for anyone with a token to run the same flow against their own actor and read the numbers off their own output.
What the live runs did leave behind is checkable: two bugs the mocked tests could not catch, each now pinned by a regression test in test/review-regressions.test.ts:
- Apify's dataset
itemCountis eventually consistent — it reads 0 for a few seconds after a run finishes. Pagination now floors the total at what was actually fetched. - A 245-token CDN image URL out-lengthed the ad copy in the RAG auto-detect fallback, producing well-formed garbage embeddings. Content detection now requires prose shape (whitespace ratio, non-URL) and skips items honestly instead.
HTTP mode
WEB_DATA_MCP_HTTP_TOKEN=$(openssl rand -hex 24) node dist/index.js --transport http --port 3000
Binds to 127.0.0.1 with Host/Origin validation (DNS-rebinding protection) and constant-time bearer auth. Built on the MCP TypeScript SDK v2 (spec 2026-07-28); 2025-era clients are served through the SDK's built-in legacy fallback.
Tracing (optional)
pnpm add @opentelemetry/api @opentelemetry/sdk-trace-base @opentelemetry/exporter-trace-otlp-http
OTEL_EXPORTER_OTLP_ENDPOINT=http://127.0.0.1:4318 node dist/index.js
One span per tool call, named execute_tool <tool>, carrying gen_ai.operation.name, gen_ai.tool.name, and — for the tools that score their data — web_data_mcp.quality.score, so a bad scrape is visible in the trace and not just in the tool result. Failed calls get span status ERROR. OTEL_EXPORTER_OTLP_TRACES_ENDPOINT is honoured too and, as the standard requires, wins over the base endpoint.
Export is OTLP/HTTP only, with no console exporter — stdout belongs to the MCP protocol stream. An endpoint that is not an http(s) URL turns tracing off with a message naming the variable rather than dropping every span in silence, and with neither variable set the SDK is never imported at all, so the packages above are genuinely optional peers. The stdout/stderr rules and what the spans may carry are in SECURITY.md.
Example: LangGraph agent
examples/langgraph-agent wires the server into a LangGraph agent whose system prompt enforces the quality contract ("if score < 0.7, say so instead of trusting the content"):
cd examples/langgraph-agent
npm install
OPENAI_API_KEY=... APIFY_TOKEN=... npm start -- "https://apify.com/pricing"
Limitations
- Quality scoring is heuristic (see above). Schema pass rate is the signal to rely on when you can provide a schema.
- Escalation strategies (
crawlerType,dynamicContentWaitSecs) targetapify/website-content-crawler-style inputs; other actors get proxy escalation only, and unknown input keys are passed through untouched. retry_low_quality_runre-runs the whole actor input — it does not retry only failed URLs within a run.- No streaming: long crawls block up to the wait budget (300s default). Fire-and-forget via
run_actor+ polling is the workaround for bigger jobs. - Tested against
apify-client2.x and MCP SDK2.0.0-beta.3(pinned); the pin will move to v2 stable when it ships.
Design notes
Architecture decisions are recorded in docs/adr/: curated tools vs. dynamic discovery, SDK v2 beta, the dependency-injected gateway that keeps the whole test suite offline and sub-second, hard token budgets with explicit handles, and why blocking caps the quality score. Security posture (token handling, URL guard, transport auth) is in SECURITY.md.
Development
pnpm test        # offline test suite incl. full client<->server integration
pnpm lint && pnpm typecheck
pnpm inspect     # build + MCP Inspector
node scripts/stdio-smoke.mjs                                 # protocol round trip against dist/
OTEL_EXPORTER_OTLP_ENDPOINT=http://127.0.0.1:4318 node scripts/stdio-smoke.mjs   # same, tracing on
APIFY_TOKEN=... SMOKE_ACTOR=... node scripts/live-smoke.mjs   # pre-release live smoke
Built with AI-assisted scaffolding; architecture, quality heuristics, tool contracts, and tests are hand-designed — see the ADRs for the reasoning.
License
web-data MCP questions
What tools does web-data MCP provide?
It exposes 7 tools, including scrape_url, run_actor, get_run_status, fetch_dataset_items, validate_dataset.
How does the server handle bad scrapes or bot detection?
The server automatically retries with escalating anti-blocking settings, such as residential proxies and browser crawlers, when quality scores are low.
Can I use this for RAG applications?
Yes, it includes a tool to emit embedding-ready chunks with source attribution and stable content-hash IDs.
Does it support custom data validation?
Yes, you can validate datasets against your own JSON Schema to check for pass rates and completeness.