
hotkernel MCP server
Commit Oct 14, 2026Enables coding agents to profile, rewrite, and verify GPU kernels using Nsight, SASS, and Triton through an autonomous speedrun loop.
Also known as xinhuagu/hotkernel
- Stars
- 0
- Tools
- —
- Downloads, 30 days
- —
- Latest version
- —
- Last commit
- Oct 14, 2026
- License
- Apache-2.0
What is hotkernel MCP?
hotkernel enables coding agents to profile, rewrite, and verify GPU kernels using Nsight, SASS, and Triton through an autonomous speedrun loop.
Summary generated from the project's README
About hotkernel MCP server
Optimizing GPU kernels by automating the profiling, rewriting, and verification process is what hotkernel enables for coding agents. It provides a structured loop where an AI can identify bottlenecks, analyze SASS or PTX assembly, and rewrite kernels in Triton to achieve higher performance. The server acts as a set of hands for agents, allowing them to interact directly with hardware metrics and compiler outputs rather than guessing at optimizations.
Users can set this up locally using Claude Code as a plugin or via other MCP clients like Cursor or Codex by configuring a Python environment containing PyTorch and Triton. The server requires an NVIDIA GPU and can utilize tools like nsys, ncu, and cuobjdump to provide deep visibility into kernel execution. It uses a strict verify-and-record contract to ensure that any performance gains are statistically significant and that the mathematical correctness of the kernel remains intact throughout the speedrun loop.
What you can do with it
- 1Automated kernel speedup loopAn agent can profile a PyTorch function, identify the heaviest kernel, and iteratively rewrite it in Triton until it hits the hardware bandwidth ceiling.
- 2Scaffold new optimization targetsYou can turn any existing PyTorch function into a benchmarkable target with a baseline and a verification contract.
Written from the project's README. Every use case is checked against a quote from it.
Configuration
HOTKERNEL_PYTHON
Automated checks
Ran Nov 15, 2026Full report →Not verified yet. A server needs a score of 80, no serious finding, and enough data for us to check. How checks work · What to fix for more points

- Source repository linked and reachablexinhuagu/hotkernel is public and reachablegithub.com/xinhuagu/hotkernel ↗Pass
- Package names this repository as its sourceNot checked
- Build provenance (Sigstore attestation)Not checked
- Open source license (OSI)Apache-2.0spdx.org/licenses/Apache-2.0.html ↗Pass
- Commit or release in the last yearLast commit or release 2026-10-14github.com/xinhuagu/hotkernel ↗Pass
- OpenSSF ScorecardNot checked
- Package name not close to a popular packageNot checked
- No critical advisory in the package or its dependenciesNot checked
- No hidden instructions to the model0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersPass
- Destructive tools are labelledNot checked
- Remote endpoint answers the MCP handshakeNot checked
README
View on GitHubhotkernel
Find the hot kernel, cool it down.
An MCP server that gives your coding agent hands on Nsight and SASS, a verify-and-record contract it cannot fudge, and a kernel-speedrun loop it runs on its own on the GPU on your desk.



English | 中文
Ask Claude to "make this kernel faster" today and it guesses: it cannot see the Nsight report, does not know which kernel eats 60% of the step, has never read the SASS the compiler produced, and cannot benchmark its own rewrite on your card. hotkernel is the missing pair of hands. Ten tools wrap nsys, ncu, cuobjdump, torch.profiler and a strict verify-and-record contract; one skill turns them into a loop: profile, pick the hot kernel, read its SASS, check it against the roofline, rewrite it in Triton, verify against the baseline, record the verdict, keep or revert, repeat.
**Five targets, five autonomous agent runs, one RTX 5090: rmsnorm 3.2× faster than eager PyTorch, softmax 1.2× faster than torch.softmax, gemv level with cuBLAS. Every kernel the agent kept runs at 95–105% of the card's measured streaming bandwidth. Where the library already sat near that ceiling (cuDNN decode attention, tinygemm int4 GEMV), the agent found nothing, stopped on its own, and the board says so.**¹
¹ Each range comes from three independent
verify()calls of the agent's final kernel against the baseline, n=7 interleaved runs each, on one RTX 5090 at 575 W under WSL2. Speedups are relative to the baseline scripts inexamples/: eager PyTorch for rmsnorm,torch.softmaxfor softmax,torch.mv(cuBLAS) for gemv. "Measured streaming bandwidth" is device memcpy on the same card under the same timer, 1501 GB/s (84% of the 1792 GB/s spec), see the calibration. Raw logs for every number are inresults/.
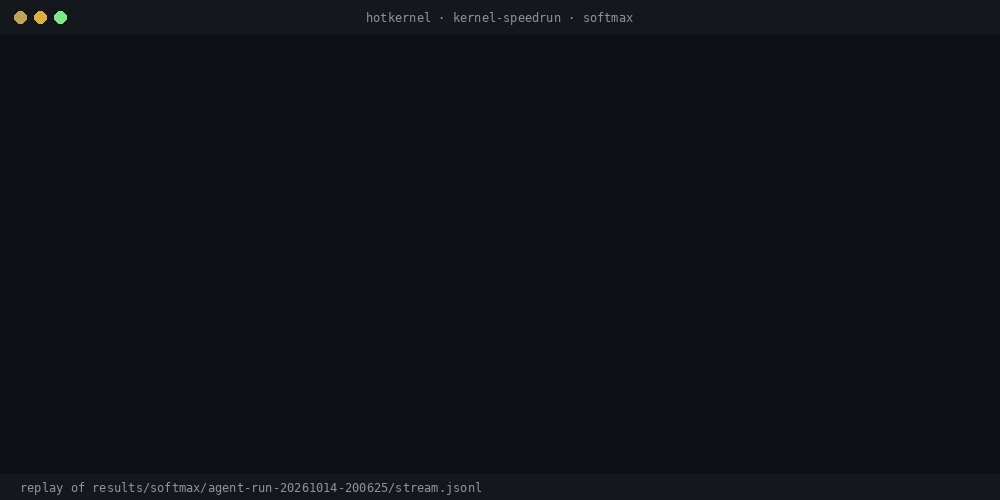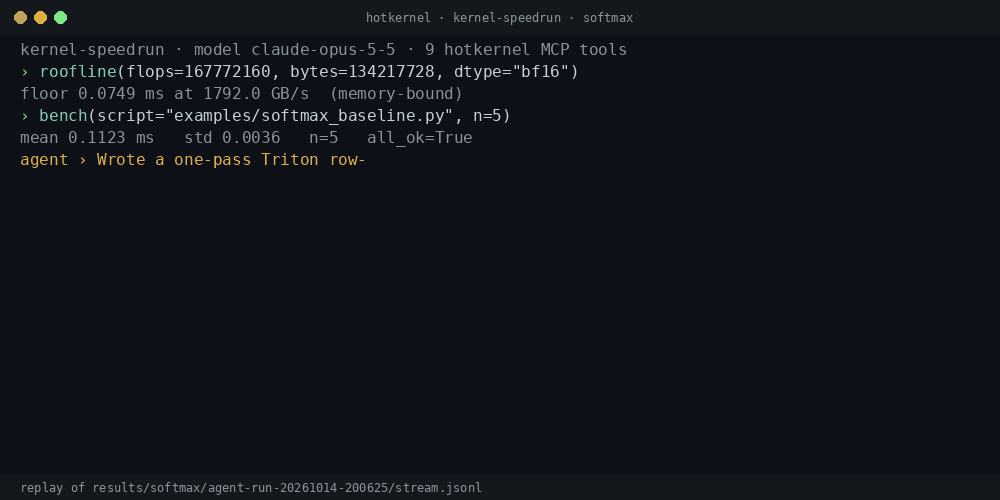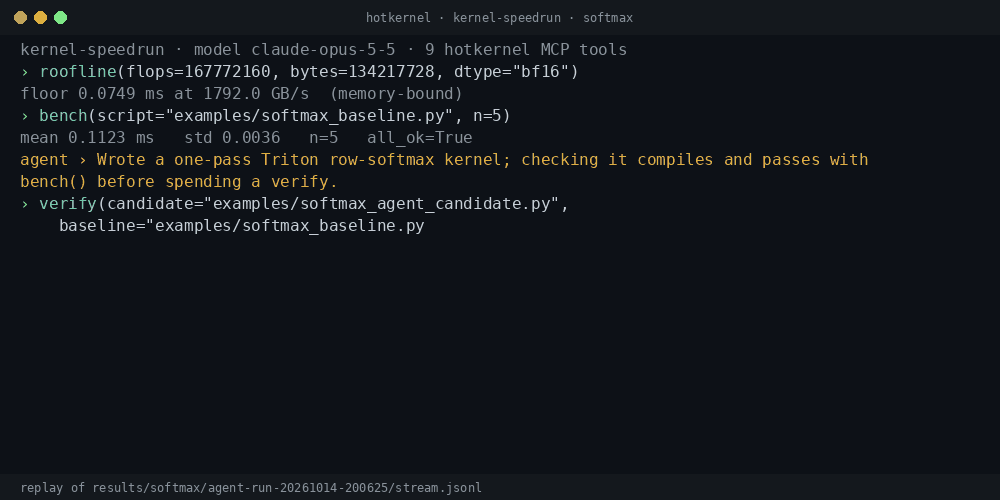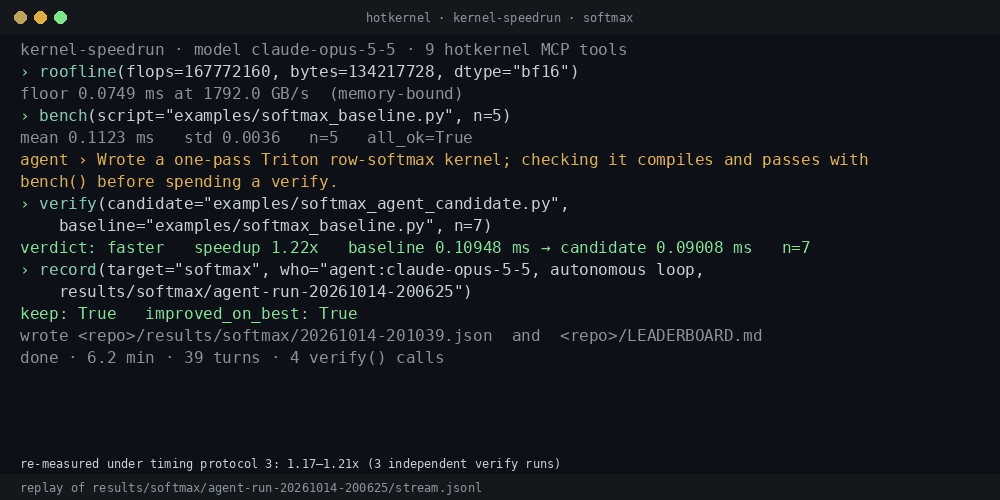
Replay of a real run, rendered from its log: results/softmax/agent-run-20261014-200625. The 1.22× on screen was measured under timing protocol 2; the same kernel re-measured under protocol 3 is 1.17–1.21×.
Install
Claude Code, one command (Claude Code 2.1.275 or later): it adds this repository as a plugin marketplace and installs the plugin, which is the MCP server plus the kernel-speedrun skill.
claude plugin install hotkernel --marketplace xinhuagu/hotkernel
Inside a session the same is /plugin marketplace add xinhuagu/hotkernel followed by /plugin install hotkernel@hotkernel. The plugin has one option, the Python that has your PyTorch and Triton: set it with /plugin configure hotkernel@hotkernel, or at install time with claude plugin install hotkernel@hotkernel --config hotkernel_python=$HOME/venvs/mytorch/bin/python. Left empty, hotkernel uses the first python on PATH that can import torch, and says so if there is none. The server itself stays torch-free and runs as uvx hotkernel.
Codex and other MCP clients (Cursor, DSH) keep the plain MCP setup:
codex mcp add --env HOTKERNEL_PYTHON=$HOME/venvs/mytorch/bin/python hotkernel -- uvx hotkernel
or {"command": "uvx", "args": ["hotkernel"], "env": {"HOTKERNEL_PYTHON": "..."}} in the client's MCP config, plus a copy of skills/kernel-speedrun/ in the agent's skills directory. Claude Code without the plugin works the same way: claude mcp add -e HOTKERNEL_PYTHON=... hotkernel -- uvx hotkernel.
Point it at your own kernel
hotkernel new turns any PyTorch function into a target with the same contract as the examples: the function becomes the baseline, its fp32 result the reference, tolerances default by dtype, and the protocol-3 timer is vendored next to the scripts, so they run in your torch interpreter whether or not hotkernel is installed there.
hotkernel new gelu --from torch.nn.functional:gelu --shape 4096x8192 --dtype bf16 --out targets
writes targets/gelu_baseline.py, targets/gelu_candidate.py (starts as the baseline; this is the file the loop edits) and targets/_hotkernel_contract.py. A function of your own works the same way, with extra inputs in call order: --from ./mykernels.py:fused --extra w:8192. Then bench the baseline for the number to beat, and verify the untouched candidate against it, which must come back inconclusive before anything changed. Agents get the same through the new_target tool. On the reference card the untouched gelu candidate benched at 0.0952 ms and verified inconclusive; a deliberately wrong one came back incorrect.
Before / after
All rows: RTX 5090 @ 575 W, bf16, timing protocol 3, n=7 per verify(); rows with a win are three independent reproductions.
| Target | Baseline | Baseline mean | Agent's kernel mean | Speedup | Share of measured bandwidth | Agent time | What the agent wrote |
|---|---|---|---|---|---|---|---|
| rmsnorm 4096×8192 | eager PyTorch (5 kernels) | 0.287–0.300 ms | 0.088–0.095 ms | 3.17–3.32× | 95–101% | 10 min, 7 experiments (a second 3-minute run found the same kernel) | one Triton program per row, row in registers, one read and one write |
| softmax 4096×8192 | torch.softmax |
0.107–0.111 ms | 0.090–0.093 ms | 1.17–1.21× | 96–99% | 6 min, 4 experiments | one program per row, max, exp and sum in registers, 8 warps |
| gemv 8192×8192 | torch.mv (cuBLAS) |
0.088–0.091 ms | 0.085–0.088 ms | 1.03–1.05×, 2 of 3 runs significant: level with cuBLAS | 101–105%² | 7 min, 3 experiments | autotuned row-block GEMV, 2 rows × 1024 columns per program |
| decode attention, 1 token, 32K context, GQA 32/8, d=128 | F.scaled_dot_product_attention, cuDNN backend (fastest of the four SDPA backends on sm_120) |
0.100–0.103 ms | 0.104–0.107 ms | no gain, 5 of 5 runs inconclusive³ | baseline at ~91% | 10 min, 5 experiments (stopped early) | split-KV Triton decode; the kernel itself beat cuDNN, the combine step ate the gain |
| int4 GEMV 8192×8192, group 128 | torch._weight_int4pack_mm (tinygemm, fastest int4 path that runs on sm_120) |
0.032–0.037 ms | 0.036–0.039 ms | no gain, 4 of 4 runs inconclusive³ | baseline at 64–76% | 11 min, 4 experiments (stopped on its own) | Triton GEMV on packed nibbles; about even on medians, behind on means |
² gemv is almost all reads; the copy ceiling is half reads and half writes, so a read-only kernel can sit slightly above it.
³ Rows without a win were not reproduced; the ranges are over the agent's own
verify()calls. Baselines for these two were picked by measuring every library path that runs on this card; the choice is logged inresults/<target>/baseline_choice.json.
Every row on LEADERBOARD.md was written by record(), including the runs that did not win and a deliberately wrong candidate that verify() rejected as incorrect. Each agent run's full transcript is in results/<target>/agent-run-*/.
What the agent gets
| Tool | What it does | Needs |
|---|---|---|
gpu_info |
card, driver, memory, power limit, compute capability | nvidia-smi |
roofline |
ridge point for this card; memory- or compute-bound verdict and attainable time for a kernel given flops and bytes, against the spec sheet or the measured bandwidth | nothing |
torch_trace |
top CUDA kernels of a script by device time, via torch.profiler |
your torch |
profile |
run a command under Nsight Systems or Nsight Compute, parsed | nsys / ncu |
top_kernels |
the n heaviest kernels from a saved report, with ncu throughput and occupancy | nothing |
disasm |
PTX or SASS of a cubin, or of the latest Triton-cache kernel by name | cuobjdump |
bench |
run a script n times, collect its {"ms": …, "ok": …} line, return mean/std/min |
your torch |
verify |
run baseline and candidate interleaved, n times each; speedup and a verdict: faster, slower, inconclusive, incorrect (any ok=false, no speedup reported), invalid (shape, dtype, seed or timing protocol changed) |
your torch |
record |
write the verify result to results/<target>/, regenerate the leaderboard from the logs, and say whether the change beats the run's best so far |
nothing |
new_target |
scaffold a target from your own function: baseline, blank candidate and the vendored contract, the same as hotkernel new |
nothing |
torch_trace, bench, verify and record work on any machine with PyTorch. Nsight is optional and only makes the picture sharper.
The loop
The skill in skills/kernel-speedrun/SKILL.md is the whole method:
benchthe baseline. That is the number to beat.torch_traceorprofileto find the kernel that actually dominates.rooflinewith the kernel's flops and bytes: memory-bound kernels want fusion, compute-bound kernels want tensor cores and bigger tiles.disasmthe Triton kernel after its first compile: register spills, uncoalesced loads, long dependency chains are all visible in SASS.- One hypothesis, one change, then
verify(candidate, baseline, n=7). It returnsfasteronly when the gap beats2 * sqrt(std_b²/n + std_c²/n)and every candidate run passed the correctness check. record()the result, win or lose. It writes the log and the leaderboard; the agent never edits the board. Keep the change only ifrecord()says it beats the run's best so far, otherwise revert.- Stop after three changes in a row that do not beat the best, or when the kernel is within 10% of the measured bandwidth floor.
It is autoresearch with kernel wall-clock as the metric instead of training loss.
Measured, not claimed
LLMs writing CUDA kernels have a credibility problem: the AI CUDA Engineer claimed 10 to 100× in 2025 and was found to be bypassing its own correctness checks, and KernelBench exists because "the kernel compiles" and "the kernel is correct and faster" are different things. hotkernel's answer is structural:
- The contract lives in the baseline. Shape, dtype, seed, reference, tolerances and the timer are in the baseline file the agent cannot edit; the candidate only supplies a function.
verifyreturnsinvalidif anything in the contract differs. - The timer was wrong twice and fixed in the open. Version 1 reused one input and let the 96 MB L2 pose as DRAM. Version 2 flushed L2 by zeroing a buffer and charged every call ~45 µs of someone else's write-backs; the softmax agent noticed that Nsight and
verifydisagreed by 2×. Version 3 rotates buffers larger than twice the L2 and was calibrated against five streaming kernels, which all land at 79–84% of the spec sheet, matching ncu's hardware counters. Old rows are kept and marked as not counted. - Wrong is loud.
verifyreports no speedup for a run whoseokis false, every row carries n and std, and the baseline is in the repo so anyone can rerun it.
Platforms
- NVIDIA GPU required. Reference card: RTX 5090 (sm_120). The roofline table covers 5090, 4090, 3090 and H100, each with its source; add yours in
src/hotkernel/gpus.py. - WSL2 is the reference platform. All nine tools are verified on an RTX 5090 under WSL2 Ubuntu 24.04, driver 617.42:
nsys2026.1.3 andncu2026.2.1 extracted into user space from NVIDIA's apt repo (no sudo),cuobjdumpandnvdisasmstraight from the Triton wheel (no CUDA toolkit needed).ncuneeds the GPU performance-counter permission once (NVIDIA Control Panel, Developer settings). Versions, commands and raw outputs:docs/platform-matrix.md. - Native Windows: the server runs (pure Python). If your torch lives in WSL2, start the server through
wsl.exe; the platform matrix has the exactclaude mcp addline. - Triton on RTX 50 series: FlashAttention 2/3/4 do not run on sm_120, which is exactly why hand-tuned Triton kernels matter on these cards.
License
Apache-2.0.
hotkernel MCP questions
What tools does hotkernel wrap for kernel optimization?
It wraps nsys, ncu, cuobjdump, and torch.profiler, providing a strict verify-and-record contract for coding agents.
How can I turn my own PyTorch function into an optimization target?
Use the hotkernel new command to scaffold a target, which creates a baseline, a candidate file, and a contract for the agent to follow.
Does hotkernel work on any hardware?
An NVIDIA GPU is required for use.