
scraper MCP server
✓ VerifiedExtract clean markdown, links, and metadata from URLs using Mozilla Readability.
Also known as ofershap/mcp-server-scraper, mcp-server-scraper
- Stars
- 6
- Tools
- 5
- Downloads, 30 days
- —
- Latest version
- 1.0.1
- Last commit
- Aug 10, 2026
- License
- MIT
What is scraper MCP?
scraper extracts clean markdown, links, and metadata from URLs using Mozilla Readability. It exposes 5 tools, such as scrape_url, extract_links, extract_metadata.
Summary generated from the project's README
About scraper MCP server
Converting web pages into clean markdown for AI analysis is what this tool enables. Developers using Claude Desktop, Cursor, or VS Code Copilot can pull content from documentation sites, blogs, and articles without manual copy-pasting. It functions as a free alternative to paid services like Firecrawl by running locally via npx without requiring any API keys, accounts, or complex configurations.
The server uses Mozilla Readability to extract text and provides specific tools for different data needs. You can use scrape_url to get markdown content, extract_links to find all hrefs and anchor text, or extract_metadata to retrieve titles, descriptions, and OG tags. It also includes search_page to find specific strings within a page and scrape_multiple to process several URLs at once to get titles and excerpts.
Because it relies on HTML parsing rather than a headless browser, it is designed for server-rendered content. It will not work for JavaScript-heavy single-page applications, but it excels at processing standard web articles and technical documentation.
What you can do with it
- 1Summarize technical documentationAsk the AI to read a specific documentation URL and provide a summary of its contents.
- 2Extract website metadataRetrieve Open Graph images and descriptions for a specific web address.
- 3Batch process multiple URLsProvide a list of links to get a brief overview and title for every page in the set.
- 4Find specific information on a pageSearch through the text of a webpage for a particular keyword or phrase.
Written from the project's README. Every use case is checked against a quote from it.
How to install scraper MCP
Formats verified 10 Nov 2026Add to CursorAdd to GooseInstall scraper MCP in Claude Code
$ claude mcp add mcp-server-scraper -- npx -y mcp-server-scraperInstall scraper MCP in Cursor
~/.cursor/mcp.json
{
  "mcpServers": {
    "mcp-server-scraper": {
      "command": "npx",
      "args": [
        "-y",
        "mcp-server-scraper"
      ]
    }
  }
}Install scraper MCP in VS Code
.vscode/mcp.json
{
  "servers": {
    "mcp-server-scraper": {
      "type": "stdio",
      "command": "npx",
      "args": [
        "-y",
        "mcp-server-scraper"
      ]
    }
  }
}Install scraper MCP in VS Code CLI
$ code --add-mcp '{"name":"mcp-server-scraper","type":"stdio","command":"npx","args":["-y","mcp-server-scraper"]}'Install scraper MCP in Claude Desktop
claude_desktop_config.json
{
  "mcpServers": {
    "mcp-server-scraper": {
      "command": "npx",
      "args": [
        "-y",
        "mcp-server-scraper"
      ]
    }
  }
}Install scraper MCP in Codex
$ codex mcp add mcp-server-scraper -- npx -y mcp-server-scraperInstall scraper MCP in Codex config.toml
~/.codex/config.toml
[mcp_servers.mcp-server-scraper]
command = "npx"
args = ["-y", "mcp-server-scraper"]
Install scraper MCP in Gemini CLI
$ gemini mcp add -s user mcp-server-scraper npx -- -y mcp-server-scraperInstall scraper MCP in Gemini settings.json
~/.gemini/settings.json
{
  "mcpServers": {
    "mcp-server-scraper": {
      "command": "npx",
      "args": [
        "-y",
        "mcp-server-scraper"
      ]
    }
  }
}scraper MCP tools 5
Detected from the READMEscrape_urlextract_linksextract_metadatasearch_pagescrape_multiple
| scrape_url | — | |
| extract_links | — | |
| extract_metadata | — | |
| search_page | — | |
| scrape_multiple | — |
Automated checks
Ran Nov 14, 2026Full report →Passed our automated checks. That is not a security audit: read the code and give the server the narrowest access it needs. How checks work

- Source repository linked and reachableofershap/mcp-server-scraper is public and reachablegithub.com/ofershap/mcp-server-scraper ↗Pass
- Package names this repository as its sourcemcp-server-scraper names ofershap/mcp-server-scraper as sourcenpmjs.com/package/mcp-server-scraper ↗Pass
- Build provenance (Sigstore attestation)No build attestation published for this releaseNot checked
- Open source license (OSI)MITspdx.org/licenses/MIT.html ↗Pass
- Commit or release in the last yearLast commit or release 2026-08-10github.com/ofershap/mcp-server-scraper ↗Pass
- OpenSSF ScorecardNot checked
- Package name not close to a popular packageNo popular package one edit away from mcp-server-scraperPass
- No critical advisory in the package or its dependencies120 resolved dependencies checked; no critical advisoryosv.dev ↗Pass
- No hidden instructions to the model5 tool descriptions and the README read; no override phrases, credential paths or hidden charactersPass
- Destructive tools are labelledNo tool named like delete, drop or execPass
- Remote endpoint answers the MCP handshakeNot checked
README
View on GitHubmcp-server-scraper


Extract clean, readable content from any URL. Returns markdown text, links, and metadata. No API keys, no config. A free alternative to Firecrawl for scraping docs, blogs, and articles.
npx mcp-server-scraper
Works with Claude Desktop, Cursor, VS Code Copilot, and any MCP client. No accounts or API keys needed.
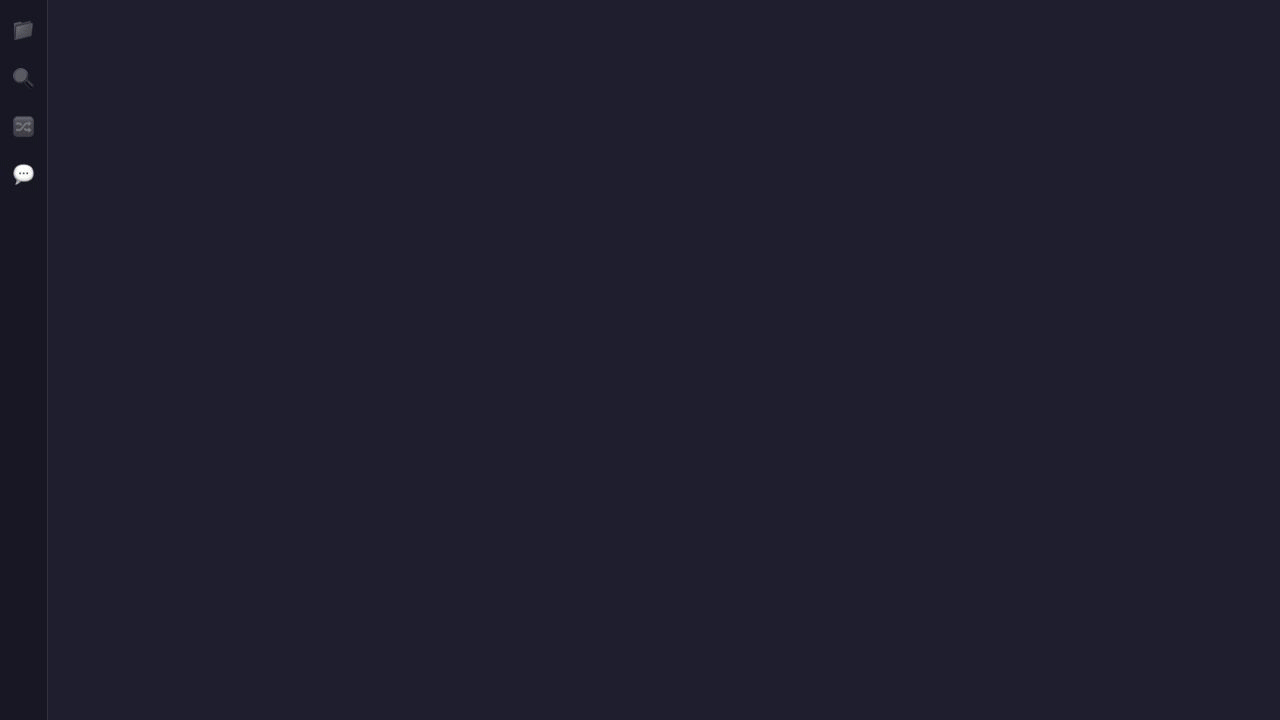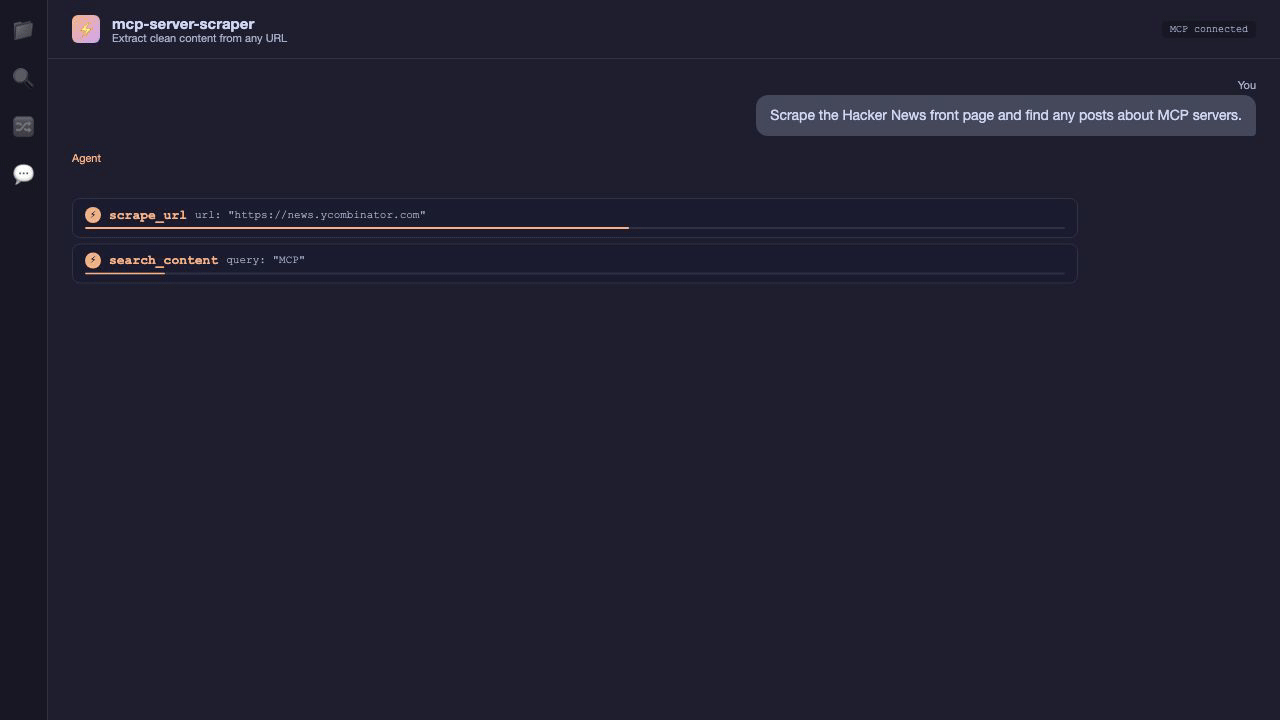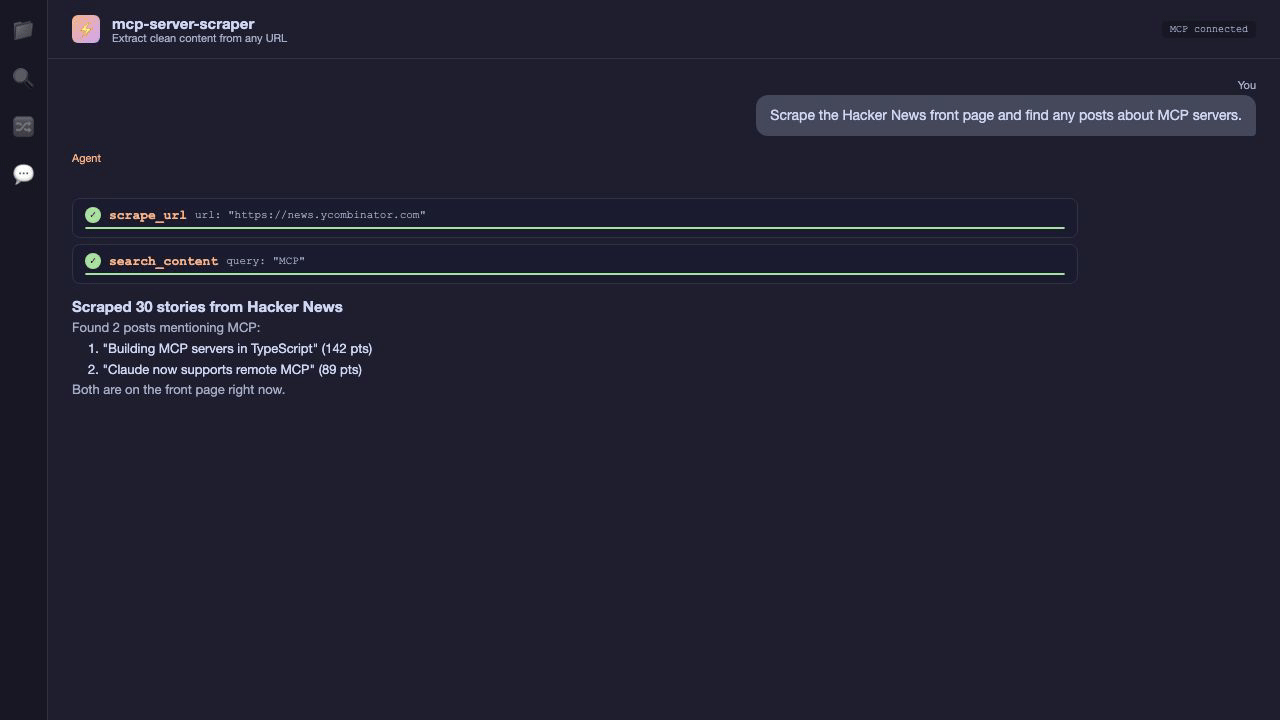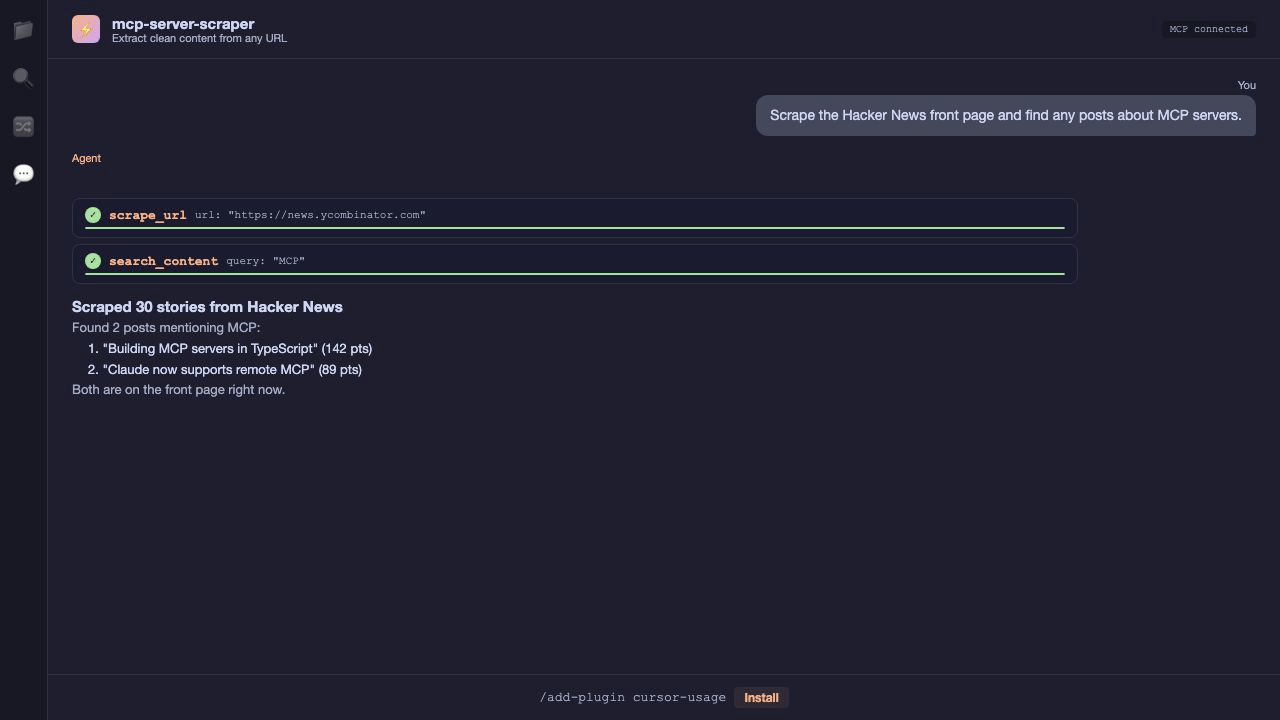
Demo built with remotion-readme-kit
Why
When you're working with an AI assistant and need to reference a docs page, a blog post, or an API reference, you usually end up copy-pasting content manually. Tools like Firecrawl solve this but require a paid API key. This server does the same thing for free. It fetches a URL, runs it through Mozilla Readability (the same engine behind Firefox Reader View), and returns clean markdown. It works well for server-rendered content like documentation sites, blog posts, and articles. It won't handle JavaScript-heavy SPAs, but for the most common use case of "read this docs page and summarize it," it does the job.
Tools
| Tool | What it does |
|---|---|
scrape_url |
Extract clean text content from a URL (Readability-powered) |
extract_links |
Get all links with href and anchor text |
extract_metadata |
Get title, description, OG tags, canonical, favicon |
search_page |
Search for a query string within the page, return matching lines |
scrape_multiple |
Batch scrape multiple URLs, get title + excerpt per URL |
Quick Start
Cursor
Add to .cursor/mcp.json:
{
  "mcpServers": {
    "scraper": {
      "command": "npx",
      "args": ["-y", "mcp-server-scraper"]
    }
  }
}
Claude Desktop
Add to claude_desktop_config.json:
{
  "mcpServers": {
    "scraper": {
      "command": "npx",
      "args": ["-y", "mcp-server-scraper"]
    }
  }
}
VS Code
Add to your MCP settings (e.g. .vscode/mcp.json):
{
  "mcp": {
    "servers": {
      "scraper": {
        "command": "npx",
        "args": ["-y", "mcp-server-scraper"]
      }
    }
  }
}
Examples
- "Scrape the API docs from https://docs.example.com and summarize them"
- "Extract all links from this page"
- "What's the OG image and description for this URL?"
- "Search this page for mentions of 'authentication'"
- "Scrape these 5 URLs and give me a summary of each"
How it works
Uses Mozilla Readability (the engine behind Firefox Reader View) plus linkedom for fast HTML parsing in Node. No headless browser needed. Works best with server-rendered pages: docs, blogs, articles, news sites.
Agent Plugins
This repo is an Agent Plugins 1.0.0 package: plugin.json, portable mcp.json, and skills/ ship together with the MCP server.
For Cursor, clone the repo and copy or symlink it to ~/.cursor/plugins/local/mcp-server-scraper, then reload the window. Skills and MCP show up under Customize > Plugins.
The Cursor and VS Code install buttons above still work: they add the same npx -y mcp-server-scraper stdio server as manual JSON.
FAQ
What is mcp-server-scraper?
A free MCP server that turns public web pages into clean markdown using Mozilla Readability. No Firecrawl or other scrape API key.
Does it run JavaScript or SPAs?
No. It fetches HTML and parses it in Node. Use a browser MCP for React dashboards and other client-rendered sites.
How is this different from Firecrawl?
Firecrawl is a hosted scrape API with billing. This server runs locally via npx, costs nothing, and fits doc/blog/article URLs.
Can I install it as an Agent Plugin in Cursor?
Yes. Use the local plugin path under ~/.cursor/plugins/local/mcp-server-scraper so the bundled web-scraping skill loads with the MCP config.
Do I need API keys or env vars?
No. Point your MCP client at npx -y mcp-server-scraper only.
Development
npm install
npm run typecheck
npm run build
npm test
See also
More MCP servers and developer tools on my portfolio.
Author
README built with README Builder
License
scraper MCP questions
How do I add scraper MCP to Claude Code?
Run claude mcp add mcp-server-scraper -- npx -y mcp-server-scraper in your terminal. Add --scope user to make it available in every project.
How do I add scraper MCP to Cursor?
Open ~/.cursor/mcp.json and add the server under mcpServers, using the Cursor config shown in the install section above.
What tools does scraper MCP provide?
It exposes 5 tools, including scrape_url, extract_links, extract_metadata, search_page, scrape_multiple.
Does it run JavaScript or SPAs?
No, it fetches HTML and parses it in Node. For React dashboards and client-rendered sites, use a browser MCP.
How is this different from Firecrawl?
Unlike Firecrawl, which is a hosted API with billing, this server runs locally via npx for free and is ideal for docs, blogs, and articles.
Do I need API keys or env vars?
No API keys or environment variables are required to use this server.