
Provides AI assistants with a searchable, cited memory of a codebase including git history, impact analysis, and documentation drift detection.
Also known as Nomannazir/codebase-brain-mcp, codebase-brain-mcp
- Stars
- 0
- Tools
- 9
- Downloads, 30 days
- —
- Latest version
- 0.2.1
- Last commit
- Nov 7, 2026
- License
- MIT
What is Codebase Brain MCP?
Codebase Brain provides AI assistants with a searchable, cited memory of a codebase including git history, impact analysis, and documentation drift detection. It exposes 9 tools, such as index_repo, search, ask_codebase.
Summary generated from the project's README
About Codebase Brain MCP server
Codebase Brain provides AI assistants with a searchable, cited memory of a codebase by indexing local folders or public git URLs. It is designed for developers using MCP clients like Claude Code, Cursor, or VS Code to help agents understand existing projects rather than just writing new code. The server runs locally on your machine using uvx, ensuring that your code never leaves your computer and no API keys are required for basic operation.
The system uses code-aware chunking for Python and JavaScript/TypeScript to maintain structural integrity during indexing. It features hybrid retrieval combining SQLite FTS5 and local embeddings via fastembed. Key tools include explain_history for tracing git commits and pull requests, impact_of_change to identify direct and transitive dependencies, and find_doc_drift to detect when documentation no longer matches the implementation. This allows an AI to provide answers with exact file and line citations.
What you can do with it
- 1Trace code evolutionAsk the assistant to explain why a specific function was implemented in a certain way by looking at its git history.
- 2Perform impact analysisDetermine what parts of the system might break if a specific class or function is modified.
- 3Detect documentation driftIdentify Markdown or reStructuredText files that contain outdated examples or references to non-existent functions.
Written from the project's README. Every use case is checked against a quote from it.
How to install Codebase Brain MCP
Formats verified 10 Nov 2026Add to CursorAdd to GooseInstall Codebase Brain MCP in Claude Code
$ claude mcp add --env 'GITHUB_TOKEN=<YOUR_GITHUB_TOKEN>' codebase-brain-mcp -- uvx codebase-brain-mcpInstall Codebase Brain MCP in Cursor
~/.cursor/mcp.json
{
  "mcpServers": {
    "codebase-brain-mcp": {
      "command": "uvx",
      "args": [
        "codebase-brain-mcp"
      ],
      "env": {
        "GITHUB_TOKEN": "<YOUR_GITHUB_TOKEN>"
      }
    }
  }
}Install Codebase Brain MCP in VS Code
.vscode/mcp.json
{
  "servers": {
    "codebase-brain-mcp": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "codebase-brain-mcp"
      ],
      "env": {
        "GITHUB_TOKEN": "<YOUR_GITHUB_TOKEN>"
      }
    }
  }
}Install Codebase Brain MCP in VS Code CLI
$ code --add-mcp '{"name":"codebase-brain-mcp","type":"stdio","command":"uvx","args":["codebase-brain-mcp"],"env":{"GITHUB_TOKEN":"<YOUR_GITHUB_TOKEN>"}}'Install Codebase Brain MCP in Claude Desktop
claude_desktop_config.json
{
  "mcpServers": {
    "codebase-brain-mcp": {
      "command": "uvx",
      "args": [
        "codebase-brain-mcp"
      ],
      "env": {
        "GITHUB_TOKEN": "<YOUR_GITHUB_TOKEN>"
      }
    }
  }
}Install Codebase Brain MCP in Codex
$ codex mcp add codebase-brain-mcp --env 'GITHUB_TOKEN=<YOUR_GITHUB_TOKEN>' -- uvx codebase-brain-mcpInstall Codebase Brain MCP in Codex config.toml
~/.codex/config.toml
[mcp_servers.codebase-brain-mcp]
command = "uvx"
args = ["codebase-brain-mcp"]

[mcp_servers.codebase-brain-mcp.env]
GITHUB_TOKEN = "<YOUR_GITHUB_TOKEN>"
Install Codebase Brain MCP in Gemini CLI
$ gemini mcp add -s user -e 'GITHUB_TOKEN=<YOUR_GITHUB_TOKEN>' codebase-brain-mcp uvx -- codebase-brain-mcpInstall Codebase Brain MCP in Gemini settings.json
~/.gemini/settings.json
{
  "mcpServers": {
    "codebase-brain-mcp": {
      "command": "uvx",
      "args": [
        "codebase-brain-mcp"
      ],
      "env": {
        "GITHUB_TOKEN": "<YOUR_GITHUB_TOKEN>"
      }
    }
  }
}Started by HostedMCP on 16 Nov 2026
We ran this command for codebase-brain-mcp 0.2.1 in an isolated container with no network and no keys. It answered and listed 9 tools.
Codebase Brain MCP tools 9
Read from the server with tools/listindex_repoActionIndex a repository so the other tools can search it. Use this first, and again after the code changes: re-running only re-embeds files whose content changed. A URL is cloned with full history (blobless), so explain_history works. Reports progress while it runs, and returns file counts and the commit indexed.
searchRead-onlyHybrid search over code and docs (BM25 keywords plus local embeddings, fused by rank). Use this for a targeted lookup, or when you need filters by folder or chunk kind; for a question you'll answer in prose, use ask_codebase instead. Returns ranked chunks, each with a path:start-end citation, its symbol and a snippet.
ask_codebaseRead-onlyGather the code and docs most relevant to a question, plus related commits, as numbered, cited sources. Use this to answer "how does X work?" or "where is Y handled?" questions. Answer from these sources only and cite each claim as path:start-end; open a source in full with read_lines. For filters, use search.
explain_historyRead-onlyWhy code looks the way it does. Use this before removing or rewriting code that looks odd, or to answer "why is it like this?". Give a symbol, or a path with an optional line range. Returns who wrote the current lines, every commit that changed them (with the relevant diff), and the title and description of the pull request behind each commit (GitHub only).
impact_of_changeRead-onlyWhat breaks if a symbol changes: code that uses it directly, code that uses that code, and the tests involved. Use this before editing a shared function, and run or update the tests it lists. Python, JavaScript and TypeScript are analysed structurally. Matches are by name, so check the same-name notes it returns.
find_doc_driftRead-onlyDocumentation that no longer matches the code. Use this to check a README or docs folder, or before a release. Finds files, functions, settings and flags that don't exist; code examples that pass parameters a function doesn't take; imports that would fail; and stale sections. Each finding has a severity, cites the doc section and suggests a fix. Changelogs are skipped.
search_historyRead-onlyFind commits by what their messages say. Use this to answer "when did we change X?" or "which commit fixed Y?". For the history of one function or file, use explain_history instead.
read_linesRead-onlyExact, numbered lines from a file in an indexed repo. Use this to open a citation in full before quoting or editing it, since search results are trimmed snippets. Refuses paths outside the repo.
list_reposRead-onlyRepositories indexed so far, with their size, languages and the commit they were indexed at. Use this first to see what's available and to get the repo names the other tools take.
Configuration
GITHUB_TOKENSecretOptional. Raises GitHub's rate limit when reading pull request titles and descriptions.
CODEBASE_BRAIN_HOMEWhere indexes and clones are stored (default ~/.codebase-brain).
CODEBASE_BRAIN_TOKEN
Automated checks
Ran Nov 14, 2026Full report →Passed our automated checks. That is not a security audit: read the code and give the server the narrowest access it needs. How checks work

- Source repository linked and reachablenomannazir/codebase-brain-mcp is public and reachablegithub.com/nomannazir/codebase-brain-mcp ↗Pass
- Package names this repository as its sourcecodebase-brain-mcp names nomannazir/codebase-brain-mcp as sourcepypi.org/project/codebase-brain-mcp/ ↗Pass
- Build provenance (Sigstore attestation)Sigstore attestation for codebase-brain-mcppypi.org/project/codebase-brain-mcp/ ↗Pass
- Open source license (OSI)MITspdx.org/licenses/MIT.html ↗Pass
- Commit or release in the last yearLast commit or release 2026-11-07github.com/nomannazir/codebase-brain-mcp ↗Pass
- OpenSSF ScorecardNot checked
- Package name not close to a popular packageNo popular package one edit away from codebase-brain-mcpPass
- No critical advisory in the package or its dependencies55 resolved dependencies checked; no critical advisoryosv.dev ↗Pass
- No hidden instructions to the model0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersPass
- Destructive tools are labelledNot checked
- Remote endpoint answers the MCP handshakeNot checked
README
View on GitHubCodebase Brain MCP


An MCP server that gives AI assistants a cited, searchable memory of a
codebase, including its history. Point it at a local folder or a public git URL. Claude, Cursor or any MCP client
can then answer questions about the code with exact path:start-end citations.
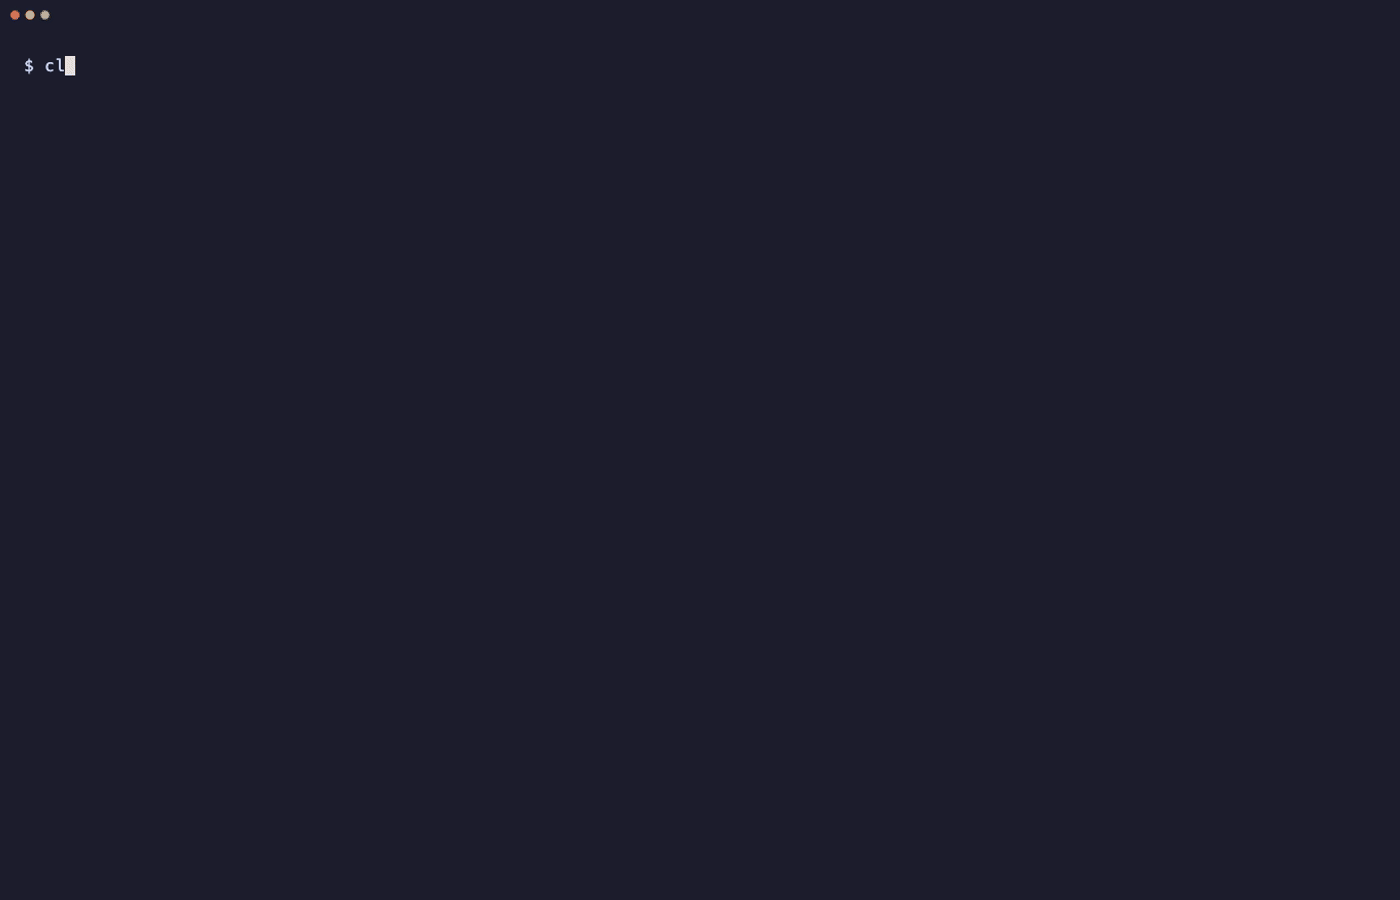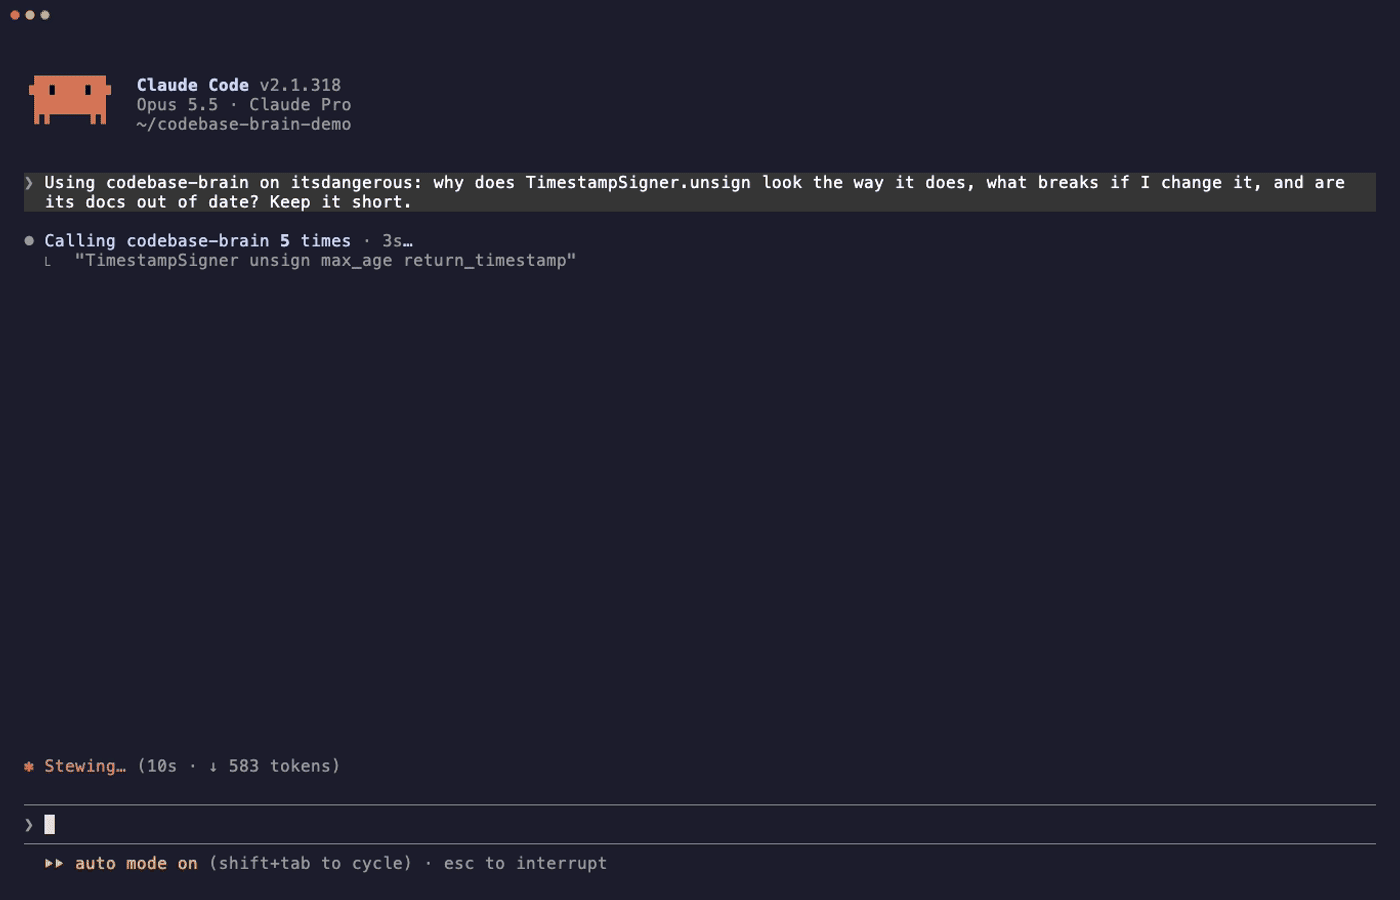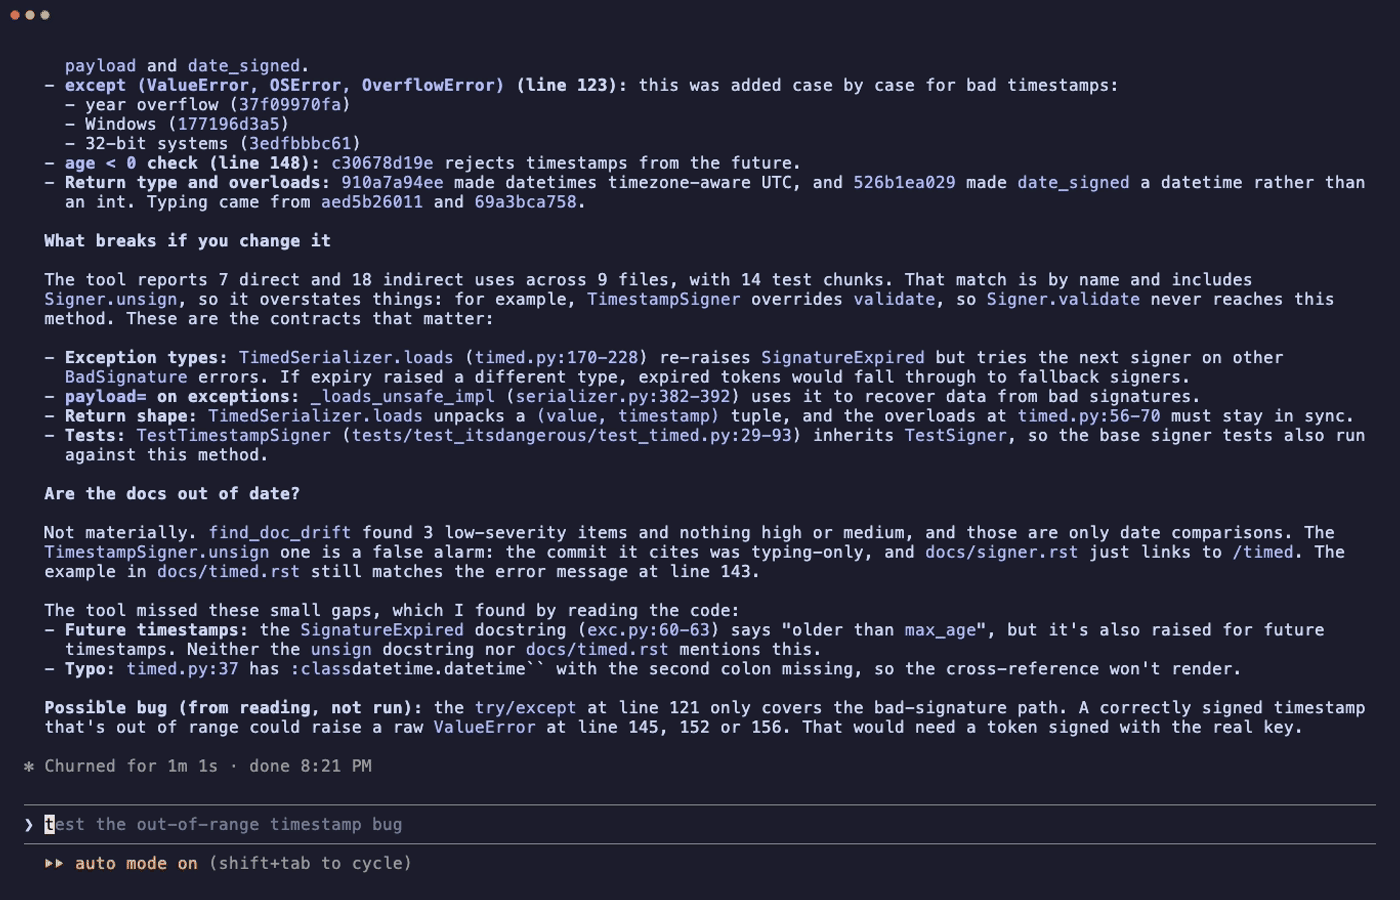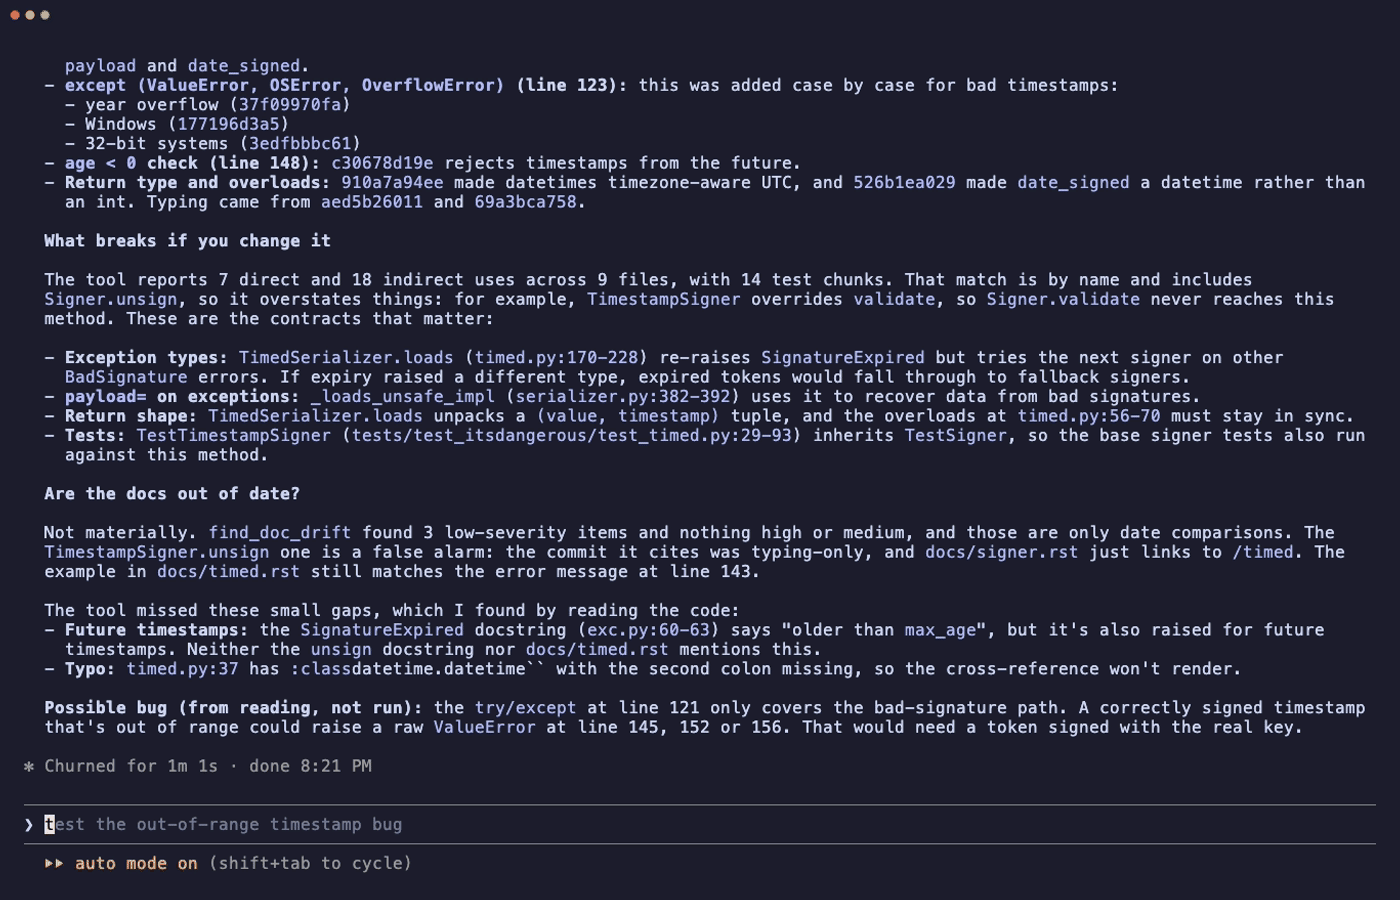
Claude Code asks why TimestampSigner.unsign looks the way it does, what breaks if it changes, and whether its
docs are current. Codebase Brain answers with commits, callers, tests and doc findings, all cited. (Waiting time
sped up.)
The problem
AI coding assistants are good at writing new code but struggle to understand code that already exists:
- They can't see the whole project. A real codebase has thousands of files. The assistant reads a few and guesses the rest, so it misses the function that matters or invents one that doesn't exist.
- You can't check their answers. "Expiry is handled in the auth module" is no use if you can't see where. Without file and line references, you have to trust the answer or re-read the code yourself.
- They don't know why code is the way it is. The code shows what it does. The reasons ("we added this check because it crashed on Windows") live in git history and pull requests, which assistants never read. So they "clean up" code that exists for a reason and bring old bugs back.
- They don't know what a change will break, or whether the documentation still matches the code.
- Many tools send your code to someone else's server to make it searchable.
What Codebase Brain gives you
A plug-in for any AI assistant that turns a codebase into something it can actually look things up in:
- Answers with proof. Every result points to the exact file and lines, and the assistant can open them.
- Search that understands code. It finds code whether you type the exact name (
calculate_invoice_total) or describe it in plain words ("how are invoices totalled?"). - The story behind the code. For any function, it shows every change made to it, who made it, why (from the commit message and pull request), and what the change was.
- What breaks if you change something. Everything that uses a function, directly or indirectly, and the tests that cover it.
- Out-of-date docs, found automatically. Documentation that mentions functions, files or settings that no longer exist, or shows examples that would no longer work.
- Private by design. Everything runs on your machine. No API keys, and your code never leaves your computer.
Why it's different (technical)
- Code-aware chunking. Python (with
ast) and JavaScript / TypeScript / JSX / TSX (with tree-sitter) are split by function, class, method, arrow function, interface, type and enum, with their doc comments. Markdown is split by heading. Each chunk knows its symbol (TimestampSigner.unsign,Ky.#retry) and exact lines, so citations point at real code. Other languages are indexed in overlapping line windows. - Hybrid retrieval. SQLite FTS5 BM25 (with
camelCase/snake_caseidentifier splitting) plus local embeddings, merged with reciprocal-rank fusion. Exact names and fuzzy questions both work. - Local and free. Embeddings run on your machine (
fastembed, ONNX). No API keys, and no code leaves your computer. - Incremental. Re-indexing only re-embeds files whose content changed. On a 42-file repo, a re-index with no changes takes about 2 seconds.
- History-aware.
explain_historyfollows a function's lines back through git (git log -L), shows who wrote the current lines, and links the pull requests behind each change. So agents can answer "why is it built this way?", not just "what does it do?". - Impact analysis.
impact_of_changelists everything that uses a function, directly and transitively, plus the tests that exercise it, before an agent changes anything. It works across Python, JavaScript and TypeScript files, and follows a constructor to the code that builds its class. - Doc-drift detection.
find_doc_driftchecks Markdown and reStructuredText docs against the code. It finds files, functions, settings and flags that don't exist; examples passing parameters a function doesn't take; imports that would fail; and sections last edited long before the code they describe changed. Each finding cites the doc section and suggests a fix ("Was it renamed tocheckout_total?"). - Agent-friendly output. Structured tool results, read-only tool annotations, progress notifications while indexing, and clear error messages the model can act on.
Tools
| Tool | What it does |
|---|---|
index_repo(source, name?) |
Index a local path or an https:// git URL (blobless clone with full history). Reports progress. |
ask_codebase(question, repo?, k?) |
The most relevant code and docs as cited sources, plus related commits, with instructions to answer only from them. |
search(query, repo?, k?, path_prefix?, kinds?) |
Raw hybrid search, filterable by path and chunk kind. |
explain_history(symbol? | path, start_line?, end_line?, repo?) |
Every commit that changed a function or line range, newest first, with the relevant diff, current authorship, and PR titles and descriptions (GitHub). |
search_history(query, repo?, k?) |
Find commits by what their messages say. |
impact_of_change(symbol, path?, depth?, repo?) |
Direct and indirect users of a function or class, and the tests involved. |
find_doc_drift(path_prefix?, check_history?, repo?) |
Documentation that no longer matches the code, by severity (high, medium, low). |
read_lines(path, start, end, repo?) |
Open the exact lines behind a citation. Refuses paths outside the repo. |
list_repos() |
What's indexed, at which commit, and in which languages. |
Also included: the resource brain://repos, and the prompt answer_with_citations.
Install
Codebase Brain runs on your own machine, so there's no server or account, and it's free. It works with any
MCP-compatible assistant. All you need is uv, and every client runs the same command:
uvx codebase-brain-mcp.
Claude Code
claude mcp add codebase-brain -- uvx codebase-brain-mcp
Cursor: ~/.cursor/mcp.json (all projects) or .cursor/mcp.json (one project)
{
  "mcpServers": {
    "codebase-brain": { "command": "uvx", "args": ["codebase-brain-mcp"] }
  }
}
Claude Desktop: Settings → Developer → Edit Config (claude_desktop_config.json), then restart the app
{
  "mcpServers": {
    "codebase-brain": { "command": "uvx", "args": ["codebase-brain-mcp"] }
  }
}
VS Code (GitHub Copilot agent mode): .vscode/mcp.json
{
  "servers": {
    "codebase-brain": { "type": "stdio", "command": "uvx", "args": ["codebase-brain-mcp"] }
  }
}
Windsurf: ~/.codeium/windsurf/mcp_config.json. Gemini CLI: ~/.gemini/settings.json. Both use the same
mcpServers block as Cursor.
OpenAI Codex CLI
codex mcp add codebase-brain -- uvx codebase-brain-mcp
Tool doesn't start? Desktop apps often don't see your shell's
PATH. Runwhich uvxand put that full path in"command", for example"/Users/you/.local/bin/uvx".
Optional: install the skill.
It tells the agent which tool fits which question, to cite every claim, to check history before removing odd code,
and to run impact analysis before editing. For Claude Code, run the commands below. Other agents that read
SKILL.md files take the same file in their own skills folder.
mkdir -p ~/.claude/skills/codebase-brain
curl -fsSL https://raw.githubusercontent.com/Nomannazir/codebase-brain-mcp/main/skills/codebase-brain/SKILL.md \
  -o ~/.claude/skills/codebase-brain/SKILL.md
Quick start
uv sync
uv run codebase-brain index https://github.com/pallets/itsdangerous
uv run codebase-brain search "how is the signature timestamp checked for expiry"
0.0313  src/itsdangerous/timed.py:72-158  method TimestampSigner.unsign
0.0311  docs/timed.rst:1-28  code
0.0301  src/itsdangerous/timed.py:170-228  class TimedSerializer
Ask why it looks like that. explain_history(symbol="TimestampSigner.unsign") returns its line-by-line history:
src/itsdangerous/timed.py:72-158
  3edfbbbc 2022-03-24 handle OverflowError in timed unsign on 32-bit systems
  177196d3 2022-03-09 catch OSError on Windows
  37f09970 2022-03-08 catching year overflow ValueError
  c30678d1 2019-05-31 don't allow timestamps from the future
  910a7a94 2020-04-17 datetimes are timezone-aware utc
  ...
Use a local checkout instead (for development)
claude mcp add codebase-brain -- uv run --directory /path/to/codebase-brain-mcp codebase-brain
Run it as a remote server (Streamable HTTP)
export CODEBASE_BRAIN_TOKEN="$(python -c 'import secrets; print(secrets.token_urlsafe(32))')"
uv run codebase-brain serve --transport streamable-http --host 0.0.0.0 --port 8765
Clients connect to http://<host>:8765/mcp with Authorization: Bearer <token>. GET /healthz is open for load
balancers. Remote mode is locked down by default:
- No token, no public port. The server refuses to listen beyond localhost without a token of at least 24 characters. Tokens are compared in constant time.
- Remote clients can't read the server's disk. Only public
https://git URLs can be indexed, not local paths, unless you setCODEBASE_BRAIN_ALLOW_LOCAL_PATHS=1. - Big repos are refused above
CODEBASE_BRAIN_MAX_FILES(default 20,000), and every git command has a timeout. - DNS-rebinding protection is on for localhost, and for any hosts listed in
CODEBASE_BRAIN_ALLOWED_HOSTS.
Docker
docker build -t codebase-brain-mcp .
docker run -p 8765:8765 -e CODEBASE_BRAIN_TOKEN="$CODEBASE_BRAIN_TOKEN" -v brain-data:/data codebase-brain-mcp
The image runs as a non-root user and includes the embedding model, so it starts fast and needs no download at
runtime. It has a health check, and keeps indexes in the /data volume. Indexing uses about 1.2 GB of memory, so
give the container 2 GB.
Configuration
| Variable | Default | |
|---|---|---|
CODEBASE_BRAIN_HOME |
~/.codebase-brain |
Indexes and clones |
CODEBASE_BRAIN_EMBEDDER |
fastembed |
hash gives an offline, deterministic embedder (used in tests) |
CODEBASE_BRAIN_EMBED_MODEL |
BAAI/bge-small-en-v1.5 |
Any fastembed text model |
CODEBASE_BRAIN_MAX_FILE_BYTES |
512000 |
Larger files are skipped |
GITHUB_TOKEN |
unset | Optional. Raises GitHub's API rate limit for PR lookups |
CODEBASE_BRAIN_FETCH_PRS |
1 |
Set to 0 to never call the GitHub API |
CODEBASE_BRAIN_TOKEN |
unset | Bearer token for HTTP mode (required unless bound to localhost) |
CODEBASE_BRAIN_ALLOWED_HOSTS |
unset | Comma-separated Host values to accept (DNS-rebinding protection) |
CODEBASE_BRAIN_ALLOW_LOCAL_PATHS |
1 (stdio) / 0 (HTTP) |
Whether index_repo may read local directories |
CODEBASE_BRAIN_MAX_FILES |
20000 |
Refuse repos with more indexable files |
PORT |
8765 |
HTTP port (platforms such as Cloud Run set this) |
Doc drift, tested honestly
On a well-maintained project (itsdangerous), find_doc_drift reports no false alarms. It only reports three
"worth a look" sections whose docs date from 2020 while the code they describe changed in 2024–2025. On docs with
planted mistakes, it catches every one: a moved file, a renamed function (with the right suggestion), an unknown
setting and flag, a keyword argument the function doesn't take, and an import that would fail. Changelogs are skipped,
because they're supposed to mention removed things.
Evaluation
Does search actually put the right code in front of the model? codebase-brain eval answers that with a benchmark.
There are two, each with 32 questions pinned to one commit, and each question lists the code or docs a good answer
must come from. The questions were written by reading the code before any results were measured, and haven't been
changed since.
Python: pallets/itsdangerous
32 questions about pallets/itsdangerous at commit 672971d, in
evals/datasets/itsdangerous.toml.
| Mode | Hit@1 | Hit@3 | Hit@5 | Hit@10 | MRR@10 (95% CI) | nDCG@10 | p50 latency |
|---|---|---|---|---|---|---|---|
| hybrid (default) | 56% | 88% | 88% | 91% | 0.697 (0.56–0.82) | 0.735 | 5 ms |
| keyword only (BM25) | 56% | 75% | 78% | 84% | 0.667 (0.52–0.80) | 0.699 | <1 ms |
| vector only (bge-small) | 56% | 72% | 75% | 94% | 0.658 (0.51–0.80) | 0.701 | 4 ms |
| Hit@5 by question type | describes behaviour (14) | about the docs (7) | names the code (11) |
|---|---|---|---|
| hybrid | 71% | 100% | 100% |
| keyword only | 64% | 71% | 100% |
| vector only | 57% | 71% | 100% |
What this shows:
- Hybrid finds a right answer in the top 3 for 88% of questions, against 75% and 72% for either method alone. The gain comes from questions written in plain words and questions about the docs. When the question names the code, every mode finds it.
- It's honest about uncertainty. With 32 questions, the confidence intervals for MRR overlap, so hybrid is better on this set but not yet proven in general. Per question, hybrid beats keyword-only on 8 questions and loses on 4.
- It has known misses. Four questions describing behaviour in very different words from the code don't reach
the top 5. They're listed in
evals/results/itsdangerous.mdand are the next thing to improve. A larger, held-out question set will come first, so any tuning isn't fitted to these 32.
TypeScript: sindresorhus/ky
32 questions about sindresorhus/ky at commit 3541888, in
evals/datasets/ky.toml.
The readme is one 2,000-line file, so docs questions must find the right section, not just the file.
| Mode | Hit@1 | Hit@3 | Hit@5 | Hit@10 | MRR@10 (95% CI) | nDCG@10 | p50 latency |
|---|---|---|---|---|---|---|---|
| hybrid (default) | 47% | 66% | 69% | 78% | 0.563 (0.41–0.71) | 0.576 | 6 ms |
| keyword only (BM25) | 38% | 44% | 53% | 62% | 0.436 (0.29–0.59) | 0.455 | 1 ms |
| vector only (bge-small) | 47% | 69% | 75% | 78% | 0.594 (0.46–0.74) | 0.604 | 5 ms |
| Hit@5 by question type | describes behaviour (14) | about the docs (7) | names the code (11) |
|---|---|---|---|
| hybrid | 36% | 100% | 91% |
| keyword only | 7% | 86% | 91% |
| vector only | 43% | 100% | 100% |
What this shows:
- Naming the code or asking about the docs works well: 91–100% in the top 5.
- Describing behaviour in plain words is the weak spot (36%). ky has about 25,000 lines of tests next to
5,000 lines of source, and the tests describe the same behaviour in plain words, so they outrank the source.
Every miss is listed in
evals/results/ky.md. - Hybrid is not better than vector-only here. The intervals overlap heavily (hybrid beats vector on 5 questions and loses on 9), so neither is proven better. Keyword-only is clearly worst: hybrid beats it on 12 questions and loses on none.
- These results are published as measured. Tuning (for example, ranking source above tests) will be checked against a new held-out set, so it isn't fitted to these questions.
Reproduce either benchmark (the first run downloads the repo and the embedding model):
uv run codebase-brain eval evals/datasets/itsdangerous.toml --out evals/results
uv run codebase-brain eval evals/datasets/ky.toml --out evals/results
How it's measured:
- Hit@k: a relevant result is in the top k.
- MRR: 1 / rank of the first relevant result.
- nDCG@10: each target is credited once, so duplicate chunks don't inflate the score.
- Confidence intervals: 95% bootstrap over questions, seeded.
- Relevance: a result is relevant if it's in the target file and, when the target names a symbol, is that symbol
or one of its methods. A docs target can name a section (
FAQ > How do I stop retrying early?), and then that section or one of its subsections counts. - Dataset rot: the harness fails if a target no longer exists at the pinned commit.
How it works
source ─► resolve (local dir / blobless https clone) ─► list files (.gitignore-aware, skips binaries and lockfiles)
       ─► chunk (ast / tree-sitter / headings / windows) ─► embed (fastembed) ─► SQLite: chunks + vectors + FTS5
query  ─► BM25 top 50 ┐
       ─► vector top 50 ┴─► reciprocal-rank fusion ─► filters ─► cited sources
Security
- Clones are blobless (
--filter=blob:none): full history, with file contents fetched only when needed. - Commit authors are shown by name only; email addresses are never stored or returned.
- Only
https://clone URLs are accepted. Git runs withGIT_ALLOW_PROTOCOL=https:fileand no terminal prompts. read_linesresolves paths and refuses anything outside the indexed repository.- Repo names are validated, so they can't escape the index directory.
- All query tools are marked read-only.
- In HTTP mode: a required bearer token (constant-time check), git URLs only, repo size limits, DNS-rebinding protection, and a non-root container.
Development
uv run pytest           # 67 tests, offline (hash embedder, temporary git repos, in-process MCP client)
uv run ruff check .     # lint
uv run ruff format .    # format
uv run pyright          # types
Roadmap
- Git history and PR discussions:
explain_history,search_history - Symbol references and transitive dependents:
impact_of_change -
find_doc_drift: Markdown and reStructuredText, signatures, imports, settings, flags, staleness - JavaScript and TypeScript (tree-sitter): chunking, references, impact analysis
- More languages (Go, Rust, Java) with tree-sitter
- Retrieval evals with confidence intervals (
codebase-brain eval) - Larger held-out eval set, then retrieval tuning (reranking, query expansion)
- Streamable HTTP with bearer-token auth, Docker image
- PyPI package, MCP Registry listing
- Hosted demo
- OpenTelemetry tracing
Codebase Brain MCP questions
How do I add Codebase Brain MCP to Claude Code?
Run claude mcp add --env 'GITHUB_TOKEN=<YOUR_GITHUB_TOKEN>' codebase-brain-mcp -- uvx codebase-brain-mcp in your terminal. Add --scope user to make it available in every project.
How do I add Codebase Brain MCP to Cursor?
Open ~/.cursor/mcp.json and add the server under mcpServers, using the Cursor config shown in the install section above.
What tools does Codebase Brain MCP provide?
It exposes 9 tools, including index_repo, search, ask_codebase, explain_history, impact_of_change.
Is my code private?
Yes, everything runs on your machine. No API keys are required, and your code never leaves your computer.
Can it explain why code was written a certain way?
Yes, it can follow a function's history through git to show who changed it, why they changed it via commit messages, and link to pull requests.
How does it handle documentation updates?
It features doc-drift detection which identifies documentation that no longer matches the code, such as missing functions or incorrect examples.
What happens if I change a function?
The impact analysis tool lists everything that uses a function, both directly and indirectly, as well as the tests that cover it.