
projectmind MCP server
Provides a persistent, compact project map and memory for AI coding agents to reduce token usage and maintain architectural context.
Also known as Nodemint-dev/projectmind, @nodemint/projectmind
- Stars
- 2
- Tools
- —
- Downloads, 30 days
- —
- Latest version
- 0.6.0
- Last commit
- Jul 6, 2026
- License
- MIT
What is projectmind MCP?
projectmind provides a persistent, compact project map and memory for AI coding agents to reduce token usage and maintain architectural context.
Summary generated from the project's README
About projectmind MCP server
projectmind provides a persistent and compact project map designed to help AI coding agents maintain architectural context without re-scanning entire codebases. By using a structured digest, agents can understand modules, dependencies, and architectural decisions using only a few hundred tokens. This approach significantly reduces token consumption and costs for developers working with large repositories.
The system operates locally on Linux, macOS, or Windows and requires Node.js. Users can initialize the environment with a single command that scaffolds the map, seeds it from the repository layout, and wires installed agents via an MCP server and rules files. It includes a git hook to keep the map updated on every commit and a local savings ledger to track estimated token and dollar savings. The server provides specific tools like mind_digest, mind_query, and mind_handoff to manage project memory and session transitions.
What you can do with it
- 1Reduce token costsAn AI agent can read a small project digest instead of scanning every file in a large repository.
- 2Seamless session handoffAn agent can leave notes about its current working state so the next session knows exactly where to resume.
- 3Automated map updatesThe system uses a git hook to automatically refresh the project map whenever changes are committed.
Written from the project's README. Every use case is checked against a quote from it.
How to install projectmind MCP
Formats verified 10 Nov 2026Add to CursorInstall projectmind MCP in Claude Code
$ claude mcp add projectmind -- npx -y @nodemint/projectmindInstall projectmind MCP in Cursor
~/.cursor/mcp.json
{
  "mcpServers": {
    "projectmind": {
      "command": "npx",
      "args": [
        "-y",
        "@nodemint/projectmind"
      ]
    }
  }
}Install projectmind MCP in VS Code
.vscode/mcp.json
{
  "servers": {
    "projectmind": {
      "type": "stdio",
      "command": "npx",
      "args": [
        "-y",
        "@nodemint/projectmind"
      ]
    }
  }
}Install projectmind MCP in VS Code CLI
$ code --add-mcp '{"name":"projectmind","type":"stdio","command":"npx","args":["-y","@nodemint/projectmind"]}'Install projectmind MCP in Claude Desktop
claude_desktop_config.json
{
  "mcpServers": {
    "projectmind": {
      "command": "npx",
      "args": [
        "-y",
        "@nodemint/projectmind"
      ]
    }
  }
}Install projectmind MCP in Codex
~/.codex/config.toml
[mcp_servers.projectmind]
command = "npx"
args = ["-y", "@nodemint/projectmind"]
Install projectmind MCP in Gemini CLI
~/.gemini/settings.json
{
  "mcpServers": {
    "projectmind": {
      "command": "npx",
      "args": [
        "-y",
        "@nodemint/projectmind"
      ]
    }
  }
}README
View on GitHubprojectmind
Persistent, compact project memory for AI coding agents. Your agent reads one small digest instead of re-scanning the codebase every session — and a local ledger shows you exactly how many tokens (and dollars) that saved.




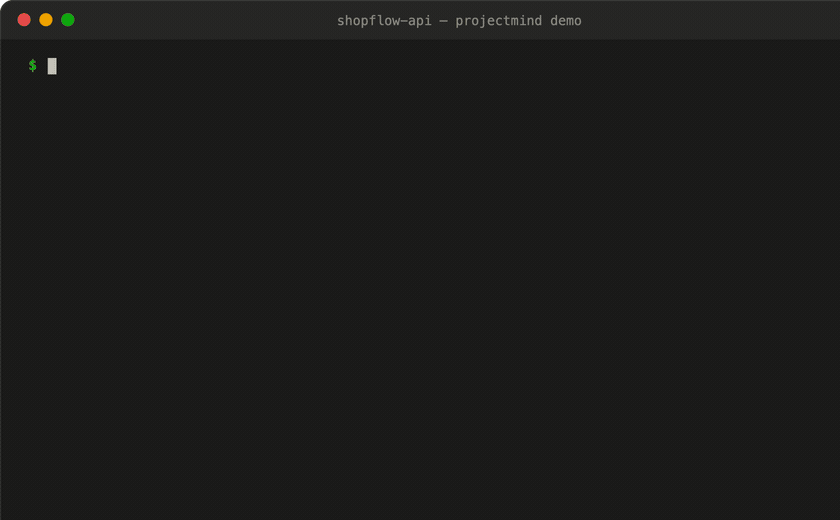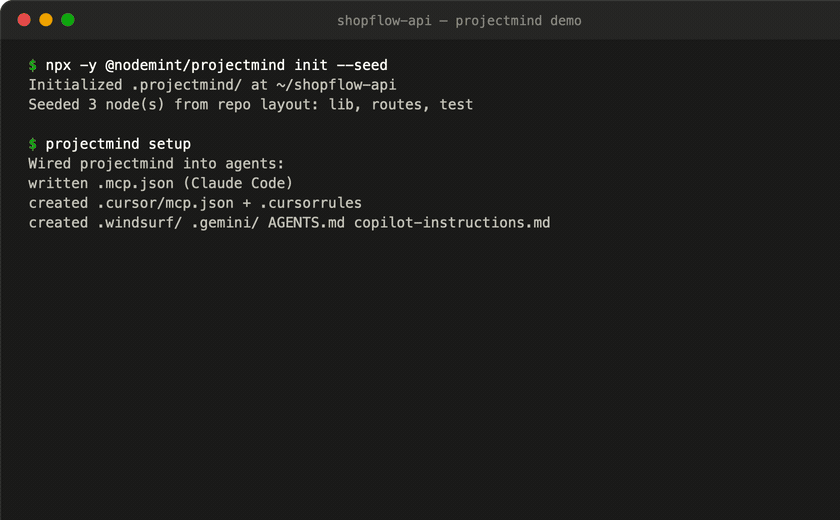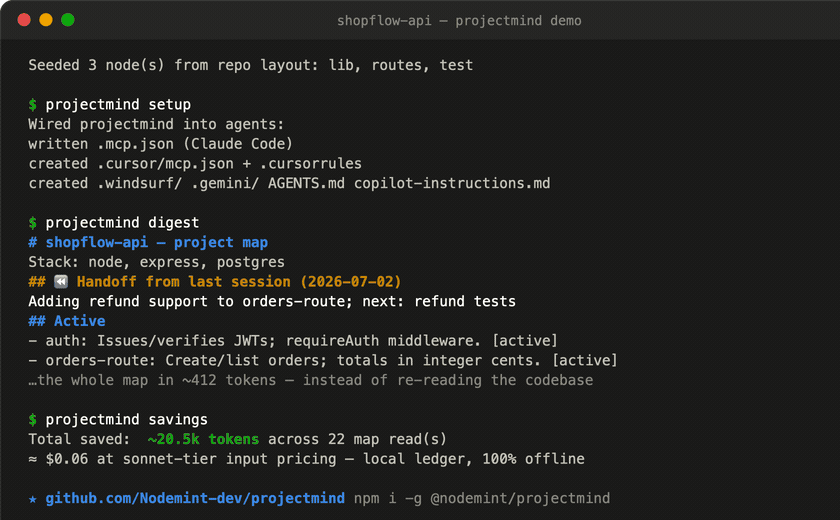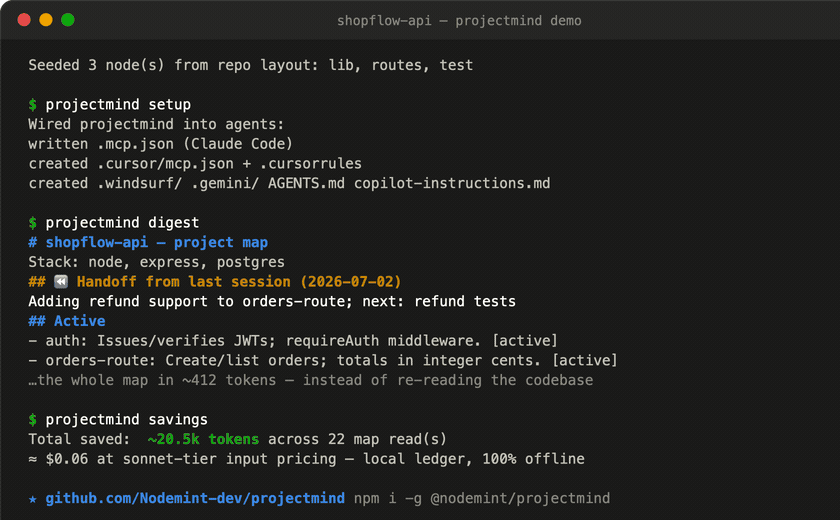

Every AI coding session starts the same way: the agent has no memory of your project, so it re-reads files, re-derives your architecture, or asks you to re-explain decisions you made months ago. You pay for that in tokens, time, and wrong guesses — every single session, on every machine, for every teammate.
projectmind fixes this with a structured, persistent project map
(.projectmind/map.json): your modules, their dependencies, your architectural
decisions, your conventions, your domain glossary. The agent reads a ~400-token
digest first, drills into single nodes only when needed, and writes back what it
learns — so the next session (yours, a teammate's, or a different AI tool's)
starts already knowing the project.
The digest scales with your project's conceptual size (modules, decisions), not its byte size — so the savings grow with the repo.
Quick start — one command
npm install -g @nodemint/projectmind
cd your-repo
projectmind init
That single init does everything: scaffolds the map, seeds it from your
repo layout, detects which AI agents are installed on your machine and
wires each one (MCP server + a rules file carrying the live map), adds
.projectmind/ to your .gitignore (the map stays local — nothing to push),
and installs the git hook that keeps the map fresh on every commit.
Then the one step no tool can do for you: restart your agent (or start a
new chat session). AI agents load their config and rules files at session
start — a chat that was already open keeps its old context, and every session
after that has the map automatically. Using the VS Code savings extension?
Cmd+Shift+P → "Developer: Reload Window" once.
Want it available in every future project without even running init?
projectmind setup --global # registers the MCP server once, user-wide
(projectmind init --bare scaffolds only, and projectmind setup re-wires
agents on demand, if you prefer the pieces separately.)
See what it saves you — measured, not promised
The MCP server keeps a local savings ledger: every time your agent reads the map instead of scanning files, it records the tokens actually served vs. the estimated tokens of the files the agent would have read instead.

Check it anytime:
$ projectmind savings
projectmind savings (estimated — local ledger, never leaves this machine)

  Total saved:   ~20.5k tokens across 22 map read(s)
  ≈ $0.0614 at sonnet-tier input pricing ($3/MTok, as of 2026-06)
  Today:         ~20.5k tokens (22 read(s))

  By tool:
    mind_digest      12 reads   ~18.5k saved
    mind_query        6 reads   ~1210 saved
    mind_context      4 reads   ~712 saved

  Methodology: tokens ≈ ceil(bytes/4); baseline = files the agent would have read instead.
The dollar figure needs zero configuration: it defaults to Sonnet-tier input
pricing from a built-in table of published rates (Haiku $1 / Sonnet $3 / Opus $5
/ Fable $10 per MTok input, as of June 2026), and says exactly which assumption
it used. If you run a different model, set savings.model (or an exact
savings.inputPricePerMTok) in .projectmind/config.json — but nobody has to.
(Real output from a scripted day of agent work on the sample project in
test/fixtures/ — 12 session starts, 6 module drill-ins, 4 task-context reads.
Reproduce the per-session number with npm run benchmark.)
VS Code status bar: the integrations/vscode extension
shows a live ✦ ~20.5k tokens saved counter that reads the same local ledger.
Zero dependencies, zero network.
The ledger is honest by design: every number is labelled an estimate
(ceil(bytes ÷ 4), the rough English+code average), savings are floored at zero,
and the file is gitignored — it's your private data, on your machine, deletable
at any time.
One deliberate gap, stated plainly: the ledger only counts tool calls
(mind_digest, mind_query, mind_context). The embedded digest described
below never requires a tool call — that's the whole point — so its savings
don't show up as a number here. projectmind savings names which rules files
carry it instead of inventing a token count we can't actually observe.
Session handoff — pick up exactly where you left off
The thing every agent session loses is working state: what you were in the middle of, what's next, the gotcha you just discovered. Code graphs can't capture it; chat history dies with the session. projectmind carries it over:
$ projectmind digest
# shopflow-api — project map
Order-management HTTP API with JWT auth, backed by PostgreSQL.
Stack: node, express, postgres

## ⏪ Handoff from last session (2026-07-02)
Adding refund support to orders-route; next: write the refund tests
Your agent calls mind_handoff before the session ends (or before its context
gets compacted); the note leads the very next digest, so the next session —
tonight on your laptop, tomorrow on your desktop, or a different AI tool
entirely — resumes in one read instead of re-deriving the task. Notes live in
your gitignored local overlay: personal working state, never committed, cleared
with mind_handoff({clear: true}) when done. Humans can use it too:
projectmind handoff "note".
Works everywhere your team works
No language assumptions, no platform assumptions: the full test suite (85 tests, including the git-hook end-to-end and offline-guarantee tests) runs in CI on Linux, macOS, and Windows × Node 18/20/22. Paths, globs, atomic renames, and the installed git hook are exercised on all three. The map format is plain JSON — nothing OS-specific is ever written to your repo.
Verified against real open-source repos (fresh clone → projectmind init --seed,
2026-07-02):
| Repo | Stack detected | Seeded nodes | Repo size (est.) | Digest |
|---|---|---|---|---|
| expressjs/express | node | examples, lib, test |
~175k tokens / 152 files | ~86 tokens |
| pallets/flask | python | examples, src, tests |
~153k tokens / 104 files | ~111 tokens |
| flutter/pinball | dart, flutter | lib, packages, test, web |
~513k tokens / 637 files | ~99 tokens |
That's the core scaling property in the wild: the digest tracks a project's conceptual size, staying ~100 tokens whether the repo is 150k or 500k tokens. (A freshly seeded digest is a starter skeleton — a curated map with decisions and conventions lands around 400 tokens, like the benchmark fixture. We quote the honest per-session savings number — 78.9% — from the benchmark, not from these whole-repo ratios.)
How it works
flowchart LR
    subgraph agents["Your AI agents"]
        A1[Claude Code]
        A2[Cursor]
        A3[Gemini / Codex / Copilot]
    end
    subgraph pm["projectmind"]
        MCP["MCP server\n(stdio, 6 tools)"]
        CORE["core\n(atomic writes, schema-validated)"]
        HOOK["git post-commit hook\n+ watch mode"]
    end
    subgraph repo["Your repo"]
        MAP[".projectmind/map.json\nnodes · edges · decisions\nconventions · glossary"]
        DIG[".projectmind/digest.md\n+ embedded in CLAUDE.md etc."]
    end
    LEDGER[".projectmind/ledger.json\nlocal savings ledger (gitignored)"]

    A1 <--> MCP
    A2 <--> MCP
    A3 <--> MCP
    MCP --> CORE
    HOOK --> CORE
    CORE <--> MAP
    CORE --> DIG
    MCP --> LEDGER
Two update paths keep the map current without burning tokens:
- Deterministic: the git hook (and optional
projectmind watch) map changed files to modules via globs and bump freshness. Pure local computation, zero LLM. - Agent-recorded: when the agent makes an architectural decision or learns a
convention, it calls
mind_update— a few tokens once, instead of re-discovery every session.
There is deliberately no background LLM summarization — that would burn the tokens this tool exists to save.
What the agent actually reads
# shopflow-api — project map
Order-management HTTP API with JWT auth, backed by PostgreSQL.
Stack: node, express, postgres

## Active
- **auth**: Issues/verifies JWT access tokens; exposes requireAuth Express middleware. [active]
- **orders-route**: Create and list orders for the authenticated user; totals in integer cents. [active]

## Modules
- **db**: PostgreSQL pool wrapper: query() helper and withTransaction().
…

## Key decisions
- Store money as integer cents, never floats. (2026-06-10)
- JWT for stateless auth instead of server sessions. (2026-06-15)

## Conventions
- Never read process.env outside src/config.js.
…
~412 tokens for the whole thing. The long fields (notes, rationale, file
lists) are excluded from the digest and only surface through mind_query —
cheap by default, detail on demand.
MCP tools
| Tool | Purpose |
|---|---|
mind_digest() |
Read first every session. The compact map. |
mind_context({files}) |
Task-scoped. Only the modules a task touches + their direct deps. The cheapest read when you know the files. |
mind_query(node) |
Full detail on one node: files, notes, edges. |
mind_search(term) |
Find nodes / decisions / glossary by keyword. |
mind_update(delta) |
Record a structural change, decision, or convention. |
mind_handoff(note) |
Leave a "resume here" note that leads the next session's digest. |
mind_stats() |
Map size, digest cost, and your savings ledger. |
One-command agent wiring — and it doesn't depend on the model choosing to read it
projectmind setup idempotently writes the MCP config and a workflow
rules block for each agent — merging into existing configs, never clobbering
(an unparseable config is backed up and skipped).
Here's the part that matters: MCP tools are a nudge — no server can force a
model to call one, so an agent can (and sometimes will) skip mind_digest on
a plain "explain this project" question, especially mid-task. But rules files
(CLAUDE.md, .cursorrules, .windsurfrules, GEMINI.md, AGENTS.md,
.github/copilot-instructions.md) are loaded into every agent's context
unconditionally, with zero model choice involved — that's the actual
mechanism, not a coincidence. So setup doesn't just write instructions to
call mind_digest; it embeds the live digest itself between
<!-- projectmind:digest:begin/end --> markers, and every subsequent
mind_update, CLI edit, git-commit hook run, or watch save re-syncs it
automatically. The project map is present in context from message one, on
every agent, with no tool call required at all — the same reliability
class as a context-injecting hook, without needing one.
(Only the repo-committed map is ever embedded — never your gitignored local overlay or handoff notes, so nothing personal leaks into a file you commit.)
| Agent | MCP config | Rules file |
|---|---|---|
| Claude Code | .mcp.json |
CLAUDE.md |
| Cursor | .cursor/mcp.json |
.cursorrules |
| Windsurf | .windsurf/mcp.json |
.windsurfrules |
| Gemini CLI | .gemini/settings.json |
GEMINI.md |
| Codex / generic | — | AGENTS.md |
| GitHub Copilot | — | .github/copilot-instructions.md |
Target one with projectmind setup --agent cursor. Manual wiring is one line
everywhere:
{ "mcpServers": { "projectmind": { "command": "npx", "args": ["-y", "@nodemint/projectmind", "mcp"] } } }
Install once, use everywhere — global setup
projectmind setup above is per-project. Run projectmind setup --global
instead to register the MCP server once, so it's available in every
project you open from then on — no per-repo .mcp.json, no re-running setup.
Supported: Claude Code, Cursor, Windsurf, Gemini CLI.
projectmind setup --global
For Claude Code this shells out to its own claude mcp add --scope user
(the same mechanism tools like codegraph use for global registration) rather
than hand-editing its internal config file. For the others it merges into
their global config (~/.cursor/mcp.json, ~/.codeium/windsurf/mcp_config.json,
~/.gemini/settings.json) the same idempotent way the per-project setup does.
Two things this can't do, by design:
- Rules files stay per-project.
CLAUDE.md/.cursorrules/ etc. are checked-in project conventions — there's no sane "global" version of them, so--globalonly registers the MCP server, not the nudge-text. Without a project's.projectmind/map,mind_digestjust returns an empty-but-valid digest — harmless, but the agent won't be as strongly reminded to call it. - A chat session already open won't see it. Every MCP client (Claude Code,
Cursor, etc.) loads its server list once at session start — that's an MCP
client behavior, not something any server can override. Global scope means
every new session in every future project has it automatically; it does
not retroactively add it to a conversation already in progress. Restart the
agent once after running
--global, and you're done for good.
Where projectmind fits (and what it deliberately isn't)
| Structural code graphs (e.g. codegraph) | Coding-policy plugins (e.g. ponytail) | projectmind | |
|---|---|---|---|
| Captures | symbols, call paths — the how | how agents should write code | intent, decisions, conventions — the why |
| Source | parsed from code | prompt policy | curated by you + your agent |
| Can it know why you chose JWT over sessions? | no | no | yes |
| Carries your working state across sessions | no | no | yes (handoff) |
| Shows you what it saved | no | no | yes (local ledger) |
| Works offline | varies | yes | always (CI-enforced) |
You can't parse "money is always integer cents" or "we chose JWT for horizontal scaling" out of source code. That's the layer projectmind owns.
So it complements structural tools instead of cloning them: if a
.codegraph/ index exists in your repo, mind_digest, mind_query, and
mind_context automatically point the agent to codegraph for symbol-level
detail. No dependency, no duplication — projectmind is the why, codegraph is
the how.
Keeping the map honest
$ projectmind doctor
Nodes pointing at files that no longer exist:
  - legacy-auth (globs: src/old-auth/**)
Nodes untouched for more than 90 days:
  - reports (last touched 2026-03-12, 112 days ago)
projectmind doctor— drift detection: dangling file globs, stale nodes.projectmind validate— schema integrity + drift warnings.projectmind watch— live freshness on save (fs.watch, debounced, local).- Corrupt
map.json? It's backed up tomap.json.corrupt-<ts>and the session continues with an empty valid map — the agent never crashes on a bad file. - Every write is schema-validated and atomic (temp file +
fsync+ rename), so a racing agent and git hook can't corrupt the map.
The benchmark (reproduce it yourself)
$ npm run benchmark
Project: sample-project
Baseline (files an agent would read):  ~1953 tokens  (8 files)
projectmind digest:                    ~412 tokens
Savings:                               78.9%  (~1541 tokens/session)
Methodology, stated plainly: the baseline is the concatenated content of the
files an agent would plausibly read to orient itself (README + package.json +
all src/ files of the committed fixture project); tokens are estimated at
ceil(chars ÷ 4). These are estimates, not exact counts — the fixture and
the script are in test/, so the number is auditable and reproducible. Savings
on a real repo are typically much larger, because real repos have far more than
8 files while the digest stays roughly constant-size.
CLI reference
projectmind init [--seed]                       # scaffold .projectmind/ (+ starter map from repo layout)
projectmind seed                                # propose starter nodes (never overwrites curated ones)
projectmind setup [--agent <name>]              # wire MCP + rules into agents (default: all)
projectmind digest                              # print the digest (what the agent sees)
projectmind context [--files a,b] [--node id] [--term t] [--depth 1]
projectmind query <id>                          # full node detail
projectmind search <term>
projectmind add-node <id> "summary" [status]    # active | stable | deprecated
projectmind add-edge <from> <to> <rel>
projectmind decide "text" ["rationale"]
projectmind convention "text"
projectmind handoff ["note"] [--clear]          # leave/show/clear the resume-here note
projectmind stats                               # sizes + estimated digest tokens
projectmind savings                             # your local savings ledger
projectmind validate                            # map integrity + drift warnings
projectmind doctor [--stale <days>]             # drift report
projectmind watch                               # live freshness updates on save
projectmind install-hook                        # git post-commit auto-updater

Options: --local (per-developer overlay), --root <dir>
The map, in 20 seconds
{
  "version": 1,
  "project": { "name": "shopflow-api", "stack": ["node", "express", "postgres"] },
  "nodes": {
    "auth": {
      "type": "service",                      // module | component | service | doc | concept
      "summary": "Issues/verifies JWTs; requireAuth middleware.",  // one line — the token budget
      "files": ["src/auth.js"],               // globs; the hook maps commits → nodes with these
      "status": "active",                     // active | stable | deprecated
      "notes": "Longer detail — never in the digest, only via mind_query."
    }
  },
  "edges": [{ "from": "auth", "to": "config", "rel": "depends-on" }],
  "decisions": [{ "id": "d3", "text": "JWT over sessions.", "rationale": "…", "date": "2026-06-15" }],
  "conventions": ["Money is integer cents."],
  "glossary": { "SKU": "Stock Keeping Unit." }
}
Local-first by default: init gitignores the whole .projectmind/
directory — the raw map, your personal overlay ("mid-refactor on X",
handoffs), and the savings ledger all stay on your machine. Nothing to push,
nothing to review. The shareable knowledge still travels with the repo,
because the digest is embedded in your committed rules files (CLAUDE.md
etc.) and auto-synced on every change.
Team mode (opt-in): want the full raw map in git so teammates and CI share
one source of truth? Delete the .projectmind/ line from .gitignore —
that's the whole switch. Every write is deterministic (sorted keys, atomic),
so map.json and digest.md produce clean, reviewable PR diffs. init never
overrides this choice once you've made it.
Trust FAQ
Does it send my code anywhere? No — and you don't have to take our word for
it. A CI test (test/offline.test.js) scans the entire source tree and fails if
any network API (http, net, fetch, sockets, …) appears. Two runtime
dependencies (@modelcontextprotocol/sdk, picomatch), no telemetry, no LLM
calls, no accounts.
What gets committed? By default, nothing under .projectmind/ — the map is
local-first and gitignored at init. What is committed: the digest embedded
in your rules files (CLAUDE.md, .cursorrules, …), which is exactly the
part meant to be shared — and it never includes your personal overlay or
handoff notes (regression-tested). Teams can opt into committing the full map
by removing one .gitignore line.
Are the savings numbers real? They're honest estimates, clearly labelled, with the methodology printed next to every number and a reproducible benchmark in the repo. We'd rather under-claim than exaggerate.
Does it work in a chat session that's already open? Partially, and we'd
rather tell you exactly where the line is: every MCP client loads servers and
rules files at session start, so a conversation that was open before init
ran keeps its old context — no tool (ours or anyone's) can inject into it.
From the very next session on, everything is automatic. If the MCP server was
already registered globally (setup --global), the mind_* tools work even
mid-session in a brand-new project — only the embedded rules-file digest
waits for the next session.
Can the map rot? The git hook (installed by init) and watch mode keep
file↔module freshness current for free; doctor flags dangling and stale
nodes; validate checks integrity; and the embedded digest re-syncs on every
map write, so what agents see never lags what's recorded.
Does it lock me into one AI tool? No. Any MCP-capable agent can use it, the rules files cover the rest, and the map itself is plain JSON any tool can read.
Development
npm install
npm test              # 85 tests: schema, atomicity, corruption self-heal, scopes,
                      # globs, MCP round-trip, ledger, handoff, offline guarantee
npm run benchmark     # prints the estimated savings number
MIT © contributors. See CHANGELOG.md.
projectmind MCP questions
How do I add projectmind MCP to Claude Code?
Run claude mcp add projectmind -- npx -y @nodemint/projectmind in your terminal. Add --scope user to make it available in every project.
How do I add projectmind MCP to Cursor?
Open ~/.cursor/mcp.json and add the server under mcpServers, using the Cursor config shown in the install section above.
Does the project map stay private?
Yes, the map is stored locally in your repository and is automatically added to your .gitignore so it is never pushed to remote servers.