
Provides a persistent local-first memory layer for AI applications using Postgres and pgvector with hybrid semantic and keyword search.
Also known as MihaiBuilds/memory-vault, memory-vault
- Stars
- 67
- Tools
- 6
- Downloads, 30 days
- —
- Latest version
- 1.6.1
- Last commit
- Nov 9, 2026
- License
- MIT
What is Memory Vault MCP?
Memory Vault provides a persistent local-first memory layer for AI applications using Postgres and pgvector with hybrid semantic and keyword search. It exposes 6 tools, such as recall, remember, forget.
Summary generated from the project's README
About Memory Vault MCP server
Memory Vault provides a persistent, local-first memory layer designed to give AI applications long-term recall. It uses a single PostgreSQL database equipped with the pgvector extension to manage vector embeddings, full-text indexes, and relational data in one place. This architecture allows for hybrid search, combining semantic similarity with keyword matching to find relevant information even when exact terms are forgotten. The system is built to run on standard hardware without requiring a GPU, utilizing sentence-transformers for embeddings and spaCy for entity extraction.
Developers can integrate this memory layer into their workflows through several interfaces. It functions as an MCP server for Claude Desktop and Claude Code, offering tools like recall, remember, forget, and memory_status. Beyond MCP, it provides a REST API for custom application integration and a web dashboard for manual searching, ingesting files, and exploring a knowledge graph. Users can deploy the entire stack quickly using Docker or set it up manually with Python and uv.
What you can do with it
- 1Enable Claude to retain project contextYou can instruct Claude to store specific technical decisions or project details so they are available in future sessions.
- 2Perform hybrid information retrievalA developer can search through stored notes using both semantic meaning and specific keywords to find precise data.
- 3Chat with private data locallyYou can use a local LLM to query your personal knowledge base without uploading sensitive information to the cloud.
- 4Visualize connections between entitiesUsers can explore how different pieces of information relate to one another through an automated knowledge graph.
Written from the project's README. Every use case is checked against a quote from it.
How to install Memory Vault MCP
Formats verified 10 Nov 2026Add to CursorAdd to GooseInstall Memory Vault MCP in Claude Code
$ claude mcp add --env 'DB_PASSWORD=<YOUR_DB_PASSWORD>' --env 'DB_HOST=<DB_HOST>' --env 'DB_NAME=<DB_NAME>' --env 'DB_PORT=<DB_PORT>' --env 'DB_USER=<DB_USER>' memory-vault -- docker run -i --rm ghcr.io/mihaibuilds/memory-vault-mcp:1.6.1Install Memory Vault MCP in Cursor
~/.cursor/mcp.json
{
  "mcpServers": {
    "memory-vault": {
      "command": "docker",
      "args": [
        "run",
        "-i",
        "--rm",
        "ghcr.io/mihaibuilds/memory-vault-mcp:1.6.1"
      ],
      "env": {
        "DB_PASSWORD": "<YOUR_DB_PASSWORD>",
        "DB_HOST": "<DB_HOST>",
        "DB_NAME": "<DB_NAME>",
        "DB_PORT": "<DB_PORT>",
        "DB_USER": "<DB_USER>"
      }
    }
  }
}Install Memory Vault MCP in VS Code
.vscode/mcp.json
{
  "servers": {
    "memory-vault": {
      "type": "stdio",
      "command": "docker",
      "args": [
        "run",
        "-i",
        "--rm",
        "ghcr.io/mihaibuilds/memory-vault-mcp:1.6.1"
      ],
      "env": {
        "DB_PASSWORD": "<YOUR_DB_PASSWORD>",
        "DB_HOST": "<DB_HOST>",
        "DB_NAME": "<DB_NAME>",
        "DB_PORT": "<DB_PORT>",
        "DB_USER": "<DB_USER>"
      }
    }
  }
}Install Memory Vault MCP in VS Code CLI
$ code --add-mcp '{"name":"memory-vault","type":"stdio","command":"docker","args":["run","-i","--rm","ghcr.io/mihaibuilds/memory-vault-mcp:1.6.1"],"env":{"DB_PASSWORD":"<YOUR_DB_PASSWORD>","DB_HOST":"<DB_HOST>","DB_NAME":"<DB_NAME>","DB_PORT":"<DB_PORT>","DB_USER":"<DB_USER>"}}'Install Memory Vault MCP in Claude Desktop
claude_desktop_config.json
{
  "mcpServers": {
    "memory-vault": {
      "command": "docker",
      "args": [
        "run",
        "-i",
        "--rm",
        "ghcr.io/mihaibuilds/memory-vault-mcp:1.6.1"
      ],
      "env": {
        "DB_PASSWORD": "<YOUR_DB_PASSWORD>",
        "DB_HOST": "<DB_HOST>",
        "DB_NAME": "<DB_NAME>",
        "DB_PORT": "<DB_PORT>",
        "DB_USER": "<DB_USER>"
      }
    }
  }
}Install Memory Vault MCP in Codex
$ codex mcp add memory-vault --env 'DB_PASSWORD=<YOUR_DB_PASSWORD>' --env 'DB_HOST=<DB_HOST>' --env 'DB_NAME=<DB_NAME>' --env 'DB_PORT=<DB_PORT>' --env 'DB_USER=<DB_USER>' -- docker run -i --rm ghcr.io/mihaibuilds/memory-vault-mcp:1.6.1Install Memory Vault MCP in Codex config.toml
~/.codex/config.toml
[mcp_servers.memory-vault]
command = "docker"
args = ["run", "-i", "--rm", "ghcr.io/mihaibuilds/memory-vault-mcp:1.6.1"]

[mcp_servers.memory-vault.env]
DB_PASSWORD = "<YOUR_DB_PASSWORD>"
DB_HOST = "<DB_HOST>"
DB_NAME = "<DB_NAME>"
DB_PORT = "<DB_PORT>"
DB_USER = "<DB_USER>"
Install Memory Vault MCP in Gemini CLI
$ gemini mcp add -s user -e 'DB_PASSWORD=<YOUR_DB_PASSWORD>' -e 'DB_HOST=<DB_HOST>' -e 'DB_NAME=<DB_NAME>' -e 'DB_PORT=<DB_PORT>' -e 'DB_USER=<DB_USER>' memory-vault docker -- run -i --rm ghcr.io/mihaibuilds/memory-vault-mcp:1.6.1Install Memory Vault MCP in Gemini settings.json
~/.gemini/settings.json
{
  "mcpServers": {
    "memory-vault": {
      "command": "docker",
      "args": [
        "run",
        "-i",
        "--rm",
        "ghcr.io/mihaibuilds/memory-vault-mcp:1.6.1"
      ],
      "env": {
        "DB_PASSWORD": "<YOUR_DB_PASSWORD>",
        "DB_HOST": "<DB_HOST>",
        "DB_NAME": "<DB_NAME>",
        "DB_PORT": "<DB_PORT>",
        "DB_USER": "<DB_USER>"
      }
    }
  }
}Started by HostedMCP on 16 Nov 2026
We ran this command for ghcr.io/mihaibuilds/memory-vault-mcp:1.6.1 1.6.1 in an isolated container with no network and no keys. It answered and listed 6 tools.
Memory Vault MCP tools 6
Read from the server with tools/listrecallSearch your memories for information relevant to a query. Returns chunks ranked by relevance using hybrid search (vector + full-text + RRF). Uses query enrichment (keyword extraction + variation) for better recall. Results are budgeted to fit within max_tokens to avoid flooding context. Args: query: The search query — a question, topic, or keyword phrase. spaces: Filter to specific memory spaces (e.g. ["default", "projects"]). If omitted, searches all spaces. since: Only return memories after this date (ISO format, e.g. "2025-01-01"). limit: Maximum number of results (default 10, max 50). max_tokens: Token budget for results (default 2000). ef_search: How much of the vector index to search, 1-1000. Omit to use the default (40). Raise it when a search should have found something and did not — better recall, slower query. Worth trying before concluding a memory is missing.
rememberStore a new memory in the system. The text is embedded and stored as a searchable chunk. Use this to save important information, decisions, or knowledge. Args: text: The text content to remember. space: Which memory space to store it in (default "default"). source: Where this memory comes from (default "mcp"). speaker: Who said/wrote this — "human" or "assistant" (default "human").
forgetSoft-delete a memory chunk by ID. The chunk is removed from search results but stays in the database for potential recovery. Sets importance to 0 and marks it in metadata. Args: chunk_id: The UUID of the chunk to forget.
purge_forgottenPermanently delete memories that were forgotten a while ago. `forget` is a soft delete: the memory stops appearing in search but the row stays, so it can be recovered. Nothing removed it afterwards, so a vault that is edited often accumulated one dead row per edit forever. This is the deliberate, irreversible half. It is never automatic — there is no timer that quietly deletes your memories — and it only touches memories already marked forgotten, never active ones. Args: older_than_days: Only purge memories forgotten at least this many days ago. The default keeps a month of recovery, so purging right after an accidental forget still spares it. Pass 0 to purge every forgotten memory regardless of age.
move_memoryMove a stored memory into a different space. The memory keeps its content and embedding; only the space it belongs to changes. Its knowledge-graph entries are rebuilt in the target space so the graph and search agree about where it lives. The target space must already exist — use the dashboard or the API to create one first. Args: chunk_id: The UUID of the chunk to move. target_space: Name of the space to move it into.
memory_statusGet the current status of the memory system. Returns database health, chunk counts per space, and embedding model info.
Configuration
DB_PASSWORDRequiredSecretPostgres password for DB_USER
DB_HOSTRequiredHostname of the Postgres+pgvector instance Memory Vault connects to (e.g. 'host.docker.internal' when Postgres runs on the host, 'localhost' when running natively, or the service name when both run in compose)
DB_NAMERequiredPostgres database name
DB_PORTRequiredPostgres port
DB_USERRequiredPostgres user with read/write access to the memory vault database
MCP_HTTP_ALLOWED_HOSTSMCP_HTTP_ENABLED
Automated checks
Ran Nov 16, 2026Full report →Not verified yet. A server needs a score of 80, no serious finding, and enough data for us to check. How checks work · What to fix for more points

- Source repository linked and reachablemihaibuilds/memory-vault is public and reachablegithub.com/mihaibuilds/memory-vault ↗Pass
- Package names this repository as its sourceNot checked
- Build provenance (Sigstore attestation)Not checked
- Open source license (OSI)MITspdx.org/licenses/MIT.html ↗Pass
- Commit or release in the last yearLast commit or release 2026-11-09github.com/mihaibuilds/memory-vault ↗Pass
- OpenSSF ScorecardNot checked
- Package name not close to a popular packageNot checked
- No critical advisory in the package or its dependenciesNot checked
- No hidden instructions to the model6 tool descriptions and the README read; no override phrases, credential paths or hidden charactersPass
- Destructive tools are labelledpurge_forgotten has no destructiveHintFinding
- Remote endpoint answers the MCP handshakeNot checked
README
View on GitHubMemory Vault



The memory database for AI applications. Self-hosted Postgres + pgvector with hybrid search, MCP-native, and a knowledge graph baked in.
Every conversation with Claude or ChatGPT starts from zero. No memory of what you built last week, what decisions you made last month, what problems you've already solved. You either re-explain everything from scratch, or paste in a wall of context and hope it fits in the window.
Memory Vault is the persistent layer underneath. It stores what you want your AI to remember — decisions, conversations, notes, project context — in a single Postgres database with hybrid semantic + keyword search. Claude can recall and store memories during any session via MCP, you can chat with your own memories through a local LLM, or you can build your own AI tool on top of the REST API.
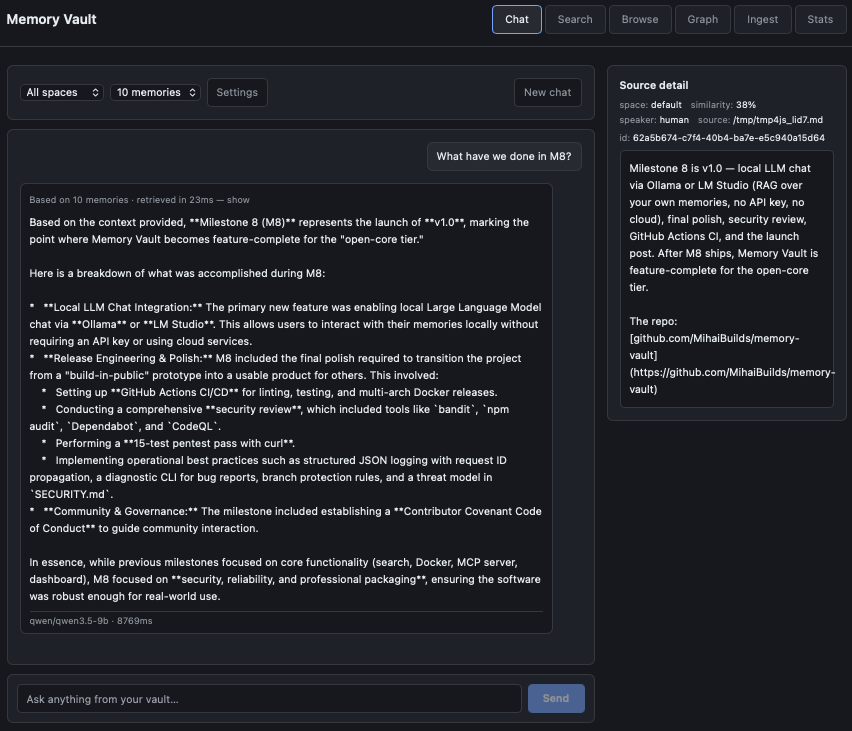
Chat with your vault using a local LLM. Every answer shows the exact memories it was grounded in — click any source to verify.
Status
v1.0 — released 2026-05-07. First stable release of Memory Vault. M1-M7 (hybrid search, Docker, MCP, REST API, dashboard, knowledge graph, local LLM chat) all shipped and stable.
See CHANGELOG.md for the full per-release history, or GitHub Releases for the platform-native view.
Semver from here forward — the public surface (REST API endpoints, MCP tool signatures, DB schema) is stable. Breaking changes only on a major version bump.
Quick Start (Docker)
git clone https://github.com/MihaiBuilds/memory-vault.git
cd memory-vault
docker compose up -d
That's it. PostgreSQL + pgvector + Memory Vault, running and ready. Migrations run automatically on first start.
# Check it's working
docker compose exec app memory-vault status

# Ingest a file
docker compose exec app memory-vault ingest /path/to/file.md --space default

# Search
docker compose exec app memory-vault search "your query here"
Data persists in a Docker volume — docker compose down and up again, your memories are still there.
Open http://localhost:8000 in your browser to use the dashboard (Chat, Search, Browse, Graph, Ingest, Stats).
Windows users: clone into WSL2, not a Windows path, and read docs/windows.md if you hit a line-ending error.
No-Docker quick start
If you prefer running without Docker:
Prerequisites
Setup with uv (recommended)
# Clone
git clone https://github.com/MihaiBuilds/memory-vault.git
cd memory-vault

# Create virtual environment and install dependencies
uv sync

# Install the spaCy language model
uv run python -m spacy download en_core_web_sm

# Configure
cp .env.example .env
# Edit .env with your PostgreSQL credentials

# Run migrations
uv run memory-vault migrate

# Verify
uv run memory-vault status
Setup with pip + venv (fallback)
If you don't want to install uv, plain pip + venv works too:
# Clone
git clone https://github.com/MihaiBuilds/memory-vault.git
cd memory-vault

# Create virtual environment
python -m venv .venv
source .venv/bin/activate

# Install dependencies
pip install -e .

# Install the spaCy language model
python -m spacy download en_core_web_sm

# Configure
cp .env.example .env
# Edit .env with your PostgreSQL credentials

# Run migrations
memory-vault migrate

# Verify
memory-vault status
Usage
If you set up with uv, prefix commands with uv run (e.g. uv run memory-vault search ...). If you used pip + venv, activate the venv first (source .venv/bin/activate) and run commands directly:
# Ingest a file
memory-vault ingest notes.md --space default

# Search memories
memory-vault search "hybrid search architecture" --limit 5

# Check status
memory-vault status
Features
- Hybrid search — semantic similarity + keyword matching combined, so you find the right memory even when you don't remember the exact words
- MCP integration — four tools (
recall,remember,forget,memory_status) that Claude can use natively during any session - Local LLM chat — query your own memories through LM Studio without sending anything to the cloud, with sources shown for every answer
- Knowledge graph — entities and relationships extracted automatically, connections between things emerge over time
- Memory spaces — separate namespaces for different projects or domains
- REST API — integrate AI memory into any application
- One-command setup —
docker compose upand it's running - Self-hosted — your data stays on your machine, always
Architecture
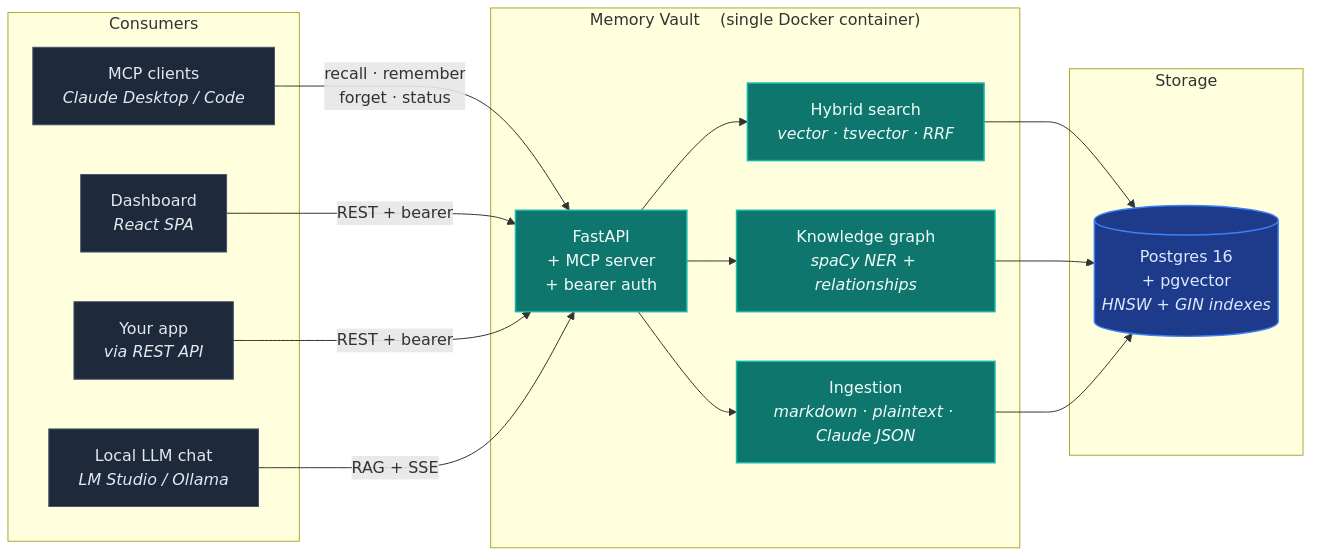
Postgres + pgvector at the core. The same memory layer is reachable from MCP (Claude), the dashboard chat page, the REST API, and any app you build on top.
Three things are deliberate about this stack:
- One database, not two. Vector embeddings, full-text indexes, and relational data all live in Postgres. No separate vector DB to keep in sync.
- Frontend-agnostic. The dashboard is one consumer of the API, not the API itself. MCP, REST, CLI, and your own apps are equal first-class clients.
- CPU-only by default. No GPU required. Embeddings (sentence-transformers) and entity extraction (spaCy) both run on a normal laptop.
Tech Stack
- PostgreSQL 16 + pgvector — vector storage and hybrid search in one database
- Python 3.11+ — async backend with psycopg 3
- sentence-transformers —
all-MiniLM-L6-v2embeddings (384-d, runs on CPU) - spaCy —
en_core_web_smfor entity extraction (CPU-only, no LLM calls) - FastAPI — REST API with bearer auth, rate limiting, and OpenAPI docs
- React 19 + Vite + TanStack Query — web dashboard, baked into the main Docker image
- Cytoscape.js + cose-bilkent — force-directed knowledge graph rendering on the dashboard
- Docker — one-command deployment with
docker compose up - MCP — Claude integration via FastMCP (stdio transport)
MCP Integration (Claude Desktop & Claude Code)
Memory Vault exposes six tools via the Model Context Protocol so Claude can read and write memories during any conversation.
Tools
| Tool | Description |
|---|---|
recall |
Search memories with hybrid search (vector + full-text + RRF) |
remember |
Store a new memory — auto-classified and embedded |
forget |
Soft-delete a memory by chunk ID |
purge_forgotten |
Permanently delete memories forgotten more than N days ago |
move_memory |
Move a memory to another space, rebuilding its graph entries |
memory_status |
Database health, chunk counts, embedding model info |
Resources
| Resource | Description |
|---|---|
memory://spaces |
List all memory spaces with chunk counts |
memory://stats |
Current system statistics |
Setup — Claude Code
Make sure you've completed the No-Docker quick start above (uv sync or pip install, plus the spaCy model download) so the memory_vault package is installed.
Project scope — add to your project's .mcp.json:
{
  "mcpServers": {
    "memory-vault": {
      "command": "/path/to/memory-vault/.venv/bin/python",
      "args": ["-m", "memory_vault.mcp"],
      "env": {
        "DB_HOST": "localhost",
        "DB_PORT": "5432",
        "DB_NAME": "memory_vault",
        "DB_USER": "memory_vault",
        "DB_PASSWORD": "memory_vault"
      }
    }
  }
}
Global scope — to make memory-vault available in every Claude Code session, add the same server block to ~/.claude/.mcp.json, then add memory-vault to enabledMcpjsonServers in ~/.claude/settings.json:
{
  "enabledMcpjsonServers": ["memory-vault"]
}
Verify with claude mcp list — memory-vault should show connected.
Setup — Claude Desktop
Add the same server block to Claude Desktop's config (Settings → Developer → Edit Config), then restart Claude Desktop.
Docker Users
If you're running Memory Vault via Docker, use DB_HOST: "127.0.0.1" and make sure port 5432 is exposed in your docker-compose.yml:
{
  "mcpServers": {
    "memory-vault": {
      "command": "/path/to/memory-vault/.venv/bin/python",
      "args": ["-m", "memory_vault.mcp"],
      "env": {
        "DB_HOST": "127.0.0.1",
        "DB_PORT": "5432",
        "DB_NAME": "memory_vault",
        "DB_USER": "memory_vault",
        "DB_PASSWORD": "memory_vault"
      }
    }
  }
}
The MCP server runs on the host (not inside Docker) and connects to the PostgreSQL container over the exposed port.
Verify It Works
Once configured, Claude will have access to the memory tools. Try:
"Use memory_status to check the memory system."
"Remember that we chose Redis for the session cache."
"Recall everything about hybrid search."
Troubleshooting
ModuleNotFoundErroron startup — the virtual environment isn't installed; re-runuv sync(orpip install -e .) in the repo directory.OSError: [E050]on startup — the spaCy language model isn't installed; re-runpython -m spacy download en_core_web_sm.- Server shows
failedin Claude Code — runclaude --debug mcpto see the server's error output. - Tools not available in Claude Code despite server connecting — confirm
memory-vaultis listed inenabledMcpjsonServersin~/.claude/settings.json. - Connection refused with Docker running — use
DB_HOST: "127.0.0.1"instead of"localhost".
Remote access over HTTP
Everything above runs MCP over stdio, which assumes the client and the server are on the same machine. If your client is somewhere else — Claude Desktop on another machine, an agent harness in a different container — Memory Vault can also serve MCP over HTTP using SSE.
It is off by default. A memory store is not something to start listening on a port without being asked:
MCP_HTTP_ENABLED=true
The transport then mounts at /api/mcp on the same port as the REST API, so a
client connects to http://<host>:8000/api/mcp/sse.
Every request needs a token, created the same way as for the REST API:
memory-vault token create my-remote-client
Clients differ in how they express a remote MCP server, but they all need the same three things — the SSE transport, the URL, and the token. In the shape most of them use:
{
  "mcpServers": {
    "memory-vault": {
      "type": "sse",
      "url": "http://192.168.1.50:8000/api/mcp/sse",
      "headers": { "Authorization": "Bearer mv_your-token-here" }
    }
  }
}
Say which hostnames are yours
Memory Vault answers only to hostnames you have declared, and refuses anything
else with HTTP 421. That check is what stops a page in a browser resolving
its own domain to 127.0.0.1 and reaching your memory store through your
machine.
The default covers a client on the same machine (localhost and 127.0.0.1,
on any port). Reaching it by any other name — a LAN address, a container name,
a hostname behind a reverse proxy — means saying so:
MCP_HTTP_ALLOWED_HOSTS=memory.internal:8000,192.168.1.50:8000
The list replaces the default rather than adding to it, so include
localhost:* if you still want local clients. A host:* entry matches that
host on any port.
If a client gets 421 Misdirected Request, this is why: the name it used is
not on the list.
Security
API_AUTH_ENABLED=false does not open the MCP transport. That setting is a
local-development convenience for the REST API, and it deliberately stops
there — an unauthenticated REST API on your own laptop is a convenience, while
an unauthenticated memory store on a listening port is how instances end up
public. With the flag off, /api/spaces answers without a token and
/api/mcp/sse still answers 401.
Two things worth knowing before you expose the port:
- Bind to somewhere sensible. Publishing the container port on
0.0.0.0reaches the whole network. Bind to a LAN address or keep it behind a reverse proxy or tunnel. - There is no transport encryption. Tokens travel in a header, so put TLS in front of it — a reverse proxy or a tunnel — for anything crossing a network you do not control.
Tokens behave exactly as they do for the REST API: revoke one with
memory-vault token revoke <prefix> and it stops working on both surfaces at
once, because both check the same table.
stdio keeps working unchanged. This is an additional way in, not a replacement, and enabling it changes nothing for existing clients.
Local LLM Chat
Memory Vault includes a chat page that lets you talk to your own memories using a local LLM — no cloud, no OpenAI key, no telemetry. The dashboard runs hybrid search against your vault, builds a context block from the top hits, and streams the answer back from a model running on your machine.
Sources are shown with every answer. Every response includes the exact chunks the LLM used, with similarity scores and content previews. Click any source to verify the answer is grounded in your data, not invented. This is the differentiator vs. opaque chat-over-docs tools — you always know what the model saw.
Setup
Memory Vault uses LM Studio as the local LLM provider in v1.0.
- Download and install LM Studio.
- Load a non-thinking model — Qwen2.5 (7B+), Llama 3 (8B+), or similar. Avoid Qwen3, DeepSeek-R1, and o1-style reasoning models — they emit chain-of-thought into the answer and break the RAG flow.
- Start the local server (LM Studio → Developer tab → Start Server). Default address:
http://localhost:1234. - Open the Memory Vault dashboard → Chat page → ⚙️ Settings → confirm the Local LLM URL points at your LM Studio instance. The model is auto-detected.
That's it. Ask a question; the dashboard retrieves relevant chunks, sends them with your question to LM Studio, and streams the answer back.
How it works
- Hybrid search retrieves the top chunks for your question (same engine as
/api/searchand MCPrecall) - Top hits are packed into a 6,000-token context budget — oldest history dropped first, then lowest-similarity chunks
- LM Studio generates an answer streamed token-by-token via Server-Sent Events
- Sources arrive first in the stream, so the UI shows "based on N memories" before tokens start flowing
Why LM Studio first
LM Studio's native API supports reasoning="off", which is the only reliable way to suppress chain-of-thought from thinking models in a RAG flow. Memory Vault uses the native API by default and falls back to OpenAI-compat (/v1/chat/completions) with <think>...</think> stripping if the native API isn't available.
REST API
Every MCP tool is also exposed as an HTTP endpoint so you can integrate Memory Vault into any app, script, or language. The API is served by FastAPI at http://localhost:8000 when you run docker compose up.
- Interactive docs: http://localhost:8000/docs
- OpenAPI schema: http://localhost:8000/openapi.json
The auto-generated /docs page is the canonical API reference — it stays in sync with the code. The summary below is for orientation.
Authentication
All endpoints except /api/health require a bearer token. Create one via the CLI:
docker compose exec app memory-vault token create my-app
The plaintext token is shown once — copy it immediately. Then send it as a header:
curl -H "Authorization: Bearer mv_..." http://localhost:8000/api/spaces
Manage tokens:
memory-vault token list
memory-vault token revoke mv_abc1234
To disable auth entirely (local dev only), set API_AUTH_ENABLED=false.
Endpoints
| Method | Path | Description |
|---|---|---|
GET |
/api/health |
Service + database health (no auth) |
GET |
/api/spaces |
List memory spaces with chunk counts |
POST |
/api/search |
Hybrid search (vector + full-text + RRF) |
GET |
/api/search/quality |
How well recent searches have been matching |
GET |
/api/chunks |
List chunks with pagination and filters |
GET |
/api/chunks/{id} |
Get a single chunk |
DELETE |
/api/chunks/{id} |
Soft-delete (forget) a chunk |
POST |
/api/ingest/text |
Ingest a text string as a chunk |
POST |
/api/ingest/file |
Upload a file through the ingestion pipeline |
POST |
/api/chat |
RAG chat over hybrid search (non-streaming) |
POST |
/api/chat/stream |
RAG chat with token-by-token SSE streaming |
Example — search
curl -X POST http://localhost:8000/api/search \
  -H "Authorization: Bearer $MV_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
    "query": "how does hybrid search work",
    "spaces": ["default"],
    "limit": 5
  }'
Example — search quality
curl http://localhost:8000/api/search/quality \
  -H "Authorization: Bearer $MV_TOKEN"
{
  "queries": 42,
  "window_hours": 24,
  "avg_top_similarity": 0.51,
  "weak_matches": 6,
  "empty_results": 0,
  "weak_threshold": 0.35
}
Aggregated from searches that already ran — asking costs nothing and runs no
query of its own. It reports each search's best hit rather than the mean of
its top-K, because a search returns as many rows as you asked for whatever the
vault holds; averaging down the ranks measures your limit as much as the
quality of the match.
weak_matches is the number worth watching. A search that finds nothing
relevant still returns its closest guesses, so empty_results stays near zero
even when nothing is being answered well. A high weak count usually means the
answers were never stored, rather than that search is failing to find them.
The Stats page in the web UI shows the same figures.
Example — ingest text
curl -X POST http://localhost:8000/api/ingest/text \
  -H "Authorization: Bearer $MV_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{"text": "Decided to use RRF for hybrid merging", "space": "default"}'
Example — upload a file
curl -X POST http://localhost:8000/api/ingest/file \
  -H "Authorization: Bearer $MV_TOKEN" \
  -F "file=@notes.md" \
  -F "space=default"
Configuration
| Variable | Default | Description |
|---|---|---|
API_HOST |
0.0.0.0 |
Bind address |
API_PORT |
8000 |
Port |
API_AUTH_ENABLED |
true |
Set false to disable bearer auth (local dev only) |
API_CORS_ORIGINS |
* |
Comma-separated allowed origins, or * |
API_RATE_LIMIT_PER_MIN |
120 |
Per-IP request limit per minute |
Dashboard
Memory Vault ships with a web UI baked into the same Docker image as the API — no separate deploy, no extra port. Open http://localhost:8000 in your browser after docker compose up.
Six pages:
- Chat — talk to your vault with a local LLM, sources shown for every answer (default landing page)
- Search — hybrid search with space filter, similarity scores, expandable hit content
- Browse — paginated chunk list with space + sort filters, two-step inline delete
- Graph — force-directed knowledge graph (Cytoscape.js), pan/zoom, click a node to see its mentions and related entities, filters for space / type / min-mentions / max-nodes
- Ingest — paste text or upload files (one at a time in v1.0), per-file status, batch summary
- Stats — system health, total chunks, spaces table with visual distribution, auto-refresh every 30s
Access
The dashboard uses the same bearer token as the API. Create one and paste it into the dashboard's token screen:
docker compose exec app memory-vault token create dashboard
The plaintext token is shown once — copy it immediately. Open http://localhost:8000, paste into the prompt, and the dashboard stores it in localStorage under memory-vault-token. You won't be asked again on that browser.
Rotating or revoking
# See which tokens exist
docker compose exec app memory-vault token list

# Revoke by prefix (shown in list output)
docker compose exec app memory-vault token revoke mv_abc1234

# Create a new one
docker compose exec app memory-vault token create dashboard
After revoking, the dashboard will hit a 401 on its next request and auto-clear the stored token, forcing you to paste the new one.
Troubleshooting
- Prompted for token every reload: your browser is blocking
localStorage(private mode, strict cookie settings). Use a normal window or allow storage forlocalhost. - 401 on every request: the token was revoked or
API_AUTH_ENABLEDchanged. Create a fresh token and paste it in. - Dashboard shows but API calls fail with CORS: you're hitting the API on a different origin than the dashboard. The baked-in build avoids this — use
http://localhost:8000, not the dev server, unless you know what you're doing. - Running the dev server:
cd web && npm install && npm run devserves the UI athttp://localhost:5173with API calls proxied to:8000. For development only. - Windows-specific issues: see docs/windows.md.
- Reporting a bug: run
docker compose exec app memory-vault diagnose(ormemory-vault diagnoseon the host for a fuller bundle includingdocker compose ps+ db logs). The command writes amemory-vault-diagnostic-YYYY-MM-DD-HHMMSS.zipcontaining app logs, status, OS info, and redacted env vars. Bearer tokens, passwords, andmv_tokens are auto-scrubbed — but please review the bundle before attaching it to a public GitHub issue. - Quoting a request ID: every API response carries an
X-Request-IDheader (UUID hex). Include it in bug reports — it lets the maintainer grep the same request across the structured JSON logs.
How It Works
Hybrid Search
Memory Vault combines two search methods and merges the results:
- Vector search — converts your query to an embedding, finds semantically similar chunks via HNSW index
- Full-text search — keyword matching via PostgreSQL tsvector + GIN index
- RRF merging — Reciprocal Rank Fusion combines both ranked lists so neither method dominates
This means you find the right memory whether you remember the exact words or just the concept.
Query Enrichment
Before searching, Memory Vault generates up to 3 query variations using the embedding model's WordPiece tokenizer to extract key technical terms. This improves recall without losing precision.
Memory Vault MCP questions
How do I add Memory Vault MCP to Claude Code?
Run claude mcp add --env 'DB_PASSWORD=<YOUR_DB_PASSWORD>' --env 'DB_HOST=<DB_HOST>' --env 'DB_NAME=<DB_NAME>' --env 'DB_PORT=<DB_PORT>' --env 'DB_USER=<DB_USER>' memory-vault -- docker run -i --rm ghcr.io/mihaibuilds/memory-vault-mcp:1.6.1 in your terminal. Add --scope user to make it available in every project.
How do I add Memory Vault MCP to Cursor?
Open ~/.cursor/mcp.json and add the server under mcpServers, using the Cursor config shown in the install section above.
What tools does Memory Vault MCP provide?
It exposes 6 tools, including recall, remember, forget, purge_forgotten, move_memory.
Does this require a GPU to run?
No, it is designed to be CPU-only by default, running embeddings and entity extraction on a normal laptop.
How can I run Memory Vault quickly?
The easiest way is using Docker Compose with a single command.