
Performs snapshot testing for AI agents by recording tool-calling trajectories and flagging behavioral regressions.
Also known as hidai25/eval-view, eval-view, evalview
- Stars
- 142
- Tools
- —
- Downloads, 30 days
- 2,297
- Latest version
- 0.6.0
- Last commit
- Oct 16, 2026
- License
- Apache-2.0
What is EvalView MCP?
EvalView performs snapshot testing for AI agents by recording tool-calling trajectories and flagging behavioral regressions.
Summary generated from the project's README
About EvalView MCP server
EvalView provides snapshot testing for AI agents to detect behavioral regressions. Instead of writing manual assertions, developers record a baseline of how an agent currently behaves, including the specific tools it calls, the order of those calls, and the resulting parameters. This approach allows teams to catch silent changes caused by model updates, prompt edits, or provider shifts that might otherwise pass standard tests.
The tool operates via a command line interface using the evalview package. Developers use the snapshot command to establish a golden baseline and the check command to compare new runs against it. While the tool can run offline for deterministic tool-sequence diffing without an API key, users can opt-in to an LLM judge for scoring output quality. It is compatible with various frameworks like LangGraph, CrewAI, and any HTTP API, making it a versatile regression gate for CI/CD pipelines.
What you can do with it
- 1Detect tool calling changesIdentify when an agent starts calling different tools or changes the sequence of its actions.
- 2Monitor output quality dropsFlag instances where the quality of the agent's response decreases even if the tool calls remain the same.
- 3Automate regression testing in CIIntegrate agent testing into pull requests to block code changes that cause behavioral drift.
- 4Establish behavior baselinesCapture the current successful behavior of an agent to use as a reference for future tests.
Written from the project's README. Every use case is checked against a quote from it.
How to install EvalView MCP
Formats verified 10 Nov 2026Add to CursorAdd to GooseInstall EvalView MCP in Claude Code
$ claude mcp add --env 'OPENAI_API_KEY=<YOUR_OPENAI_API_KEY>' eval-view -- uvx evalviewInstall EvalView MCP in Cursor
~/.cursor/mcp.json
{
  "mcpServers": {
    "eval-view": {
      "command": "uvx",
      "args": [
        "evalview"
      ],
      "env": {
        "OPENAI_API_KEY": "<YOUR_OPENAI_API_KEY>"
      }
    }
  }
}Install EvalView MCP in VS Code
.vscode/mcp.json
{
  "servers": {
    "eval-view": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "evalview"
      ],
      "env": {
        "OPENAI_API_KEY": "<YOUR_OPENAI_API_KEY>"
      }
    }
  }
}Install EvalView MCP in VS Code CLI
$ code --add-mcp '{"name":"eval-view","type":"stdio","command":"uvx","args":["evalview"],"env":{"OPENAI_API_KEY":"<YOUR_OPENAI_API_KEY>"}}'Install EvalView MCP in Claude Desktop
claude_desktop_config.json
{
  "mcpServers": {
    "eval-view": {
      "command": "uvx",
      "args": [
        "evalview"
      ],
      "env": {
        "OPENAI_API_KEY": "<YOUR_OPENAI_API_KEY>"
      }
    }
  }
}Install EvalView MCP in Codex
$ codex mcp add eval-view --env 'OPENAI_API_KEY=<YOUR_OPENAI_API_KEY>' -- uvx evalviewInstall EvalView MCP in Codex config.toml
~/.codex/config.toml
[mcp_servers.eval-view]
command = "uvx"
args = ["evalview"]

[mcp_servers.eval-view.env]
OPENAI_API_KEY = "<YOUR_OPENAI_API_KEY>"
Install EvalView MCP in Gemini CLI
$ gemini mcp add -s user -e 'OPENAI_API_KEY=<YOUR_OPENAI_API_KEY>' eval-view uvx -- evalviewInstall EvalView MCP in Gemini settings.json
~/.gemini/settings.json
{
  "mcpServers": {
    "eval-view": {
      "command": "uvx",
      "args": [
        "evalview"
      ],
      "env": {
        "OPENAI_API_KEY": "<YOUR_OPENAI_API_KEY>"
      }
    }
  }
}Configuration
OPENAI_API_KEYSecretOpenAI API key for LLM-as-judge output quality scoring. Optional — deterministic tool/sequence evaluation works without it.
| Name | Description | |
|---|---|---|
| OPENAI_API_KEY | OpenAI API key for LLM-as-judge output quality scoring. Optional — deterministic tool/sequence evaluation works without it. | Secret |
Automated checks
Ran Nov 12, 2026Full report →Passed our automated checks. That is not a security audit: read the code and give the server the narrowest access it needs. How checks work

- Source repository linked and reachablePass
- Open source license (OSI)Pass
- Commit or release in the last yearPass
- Package name not close to a popular packagePass
- Remote endpoint uses HTTPSNot checked
- Destructive tools are labelledNot checked
- No hidden instructions to the modelPass
- No critical advisory in the package or its dependenciesPass
README
View on GitHubYour agent returns 200 and looks fine. But a model update, a provider change, or a one-line prompt edit just made it skip a clarification, call the wrong tool, or quietly drop output quality. Your tests still pass. Your users notice before you do.
EvalView snapshots your agent's behavior — the tools it calls, in what order, with what output — and tells you the moment that behavior changes. Like Jest snapshots, but for tool-calling, multi-turn agents.
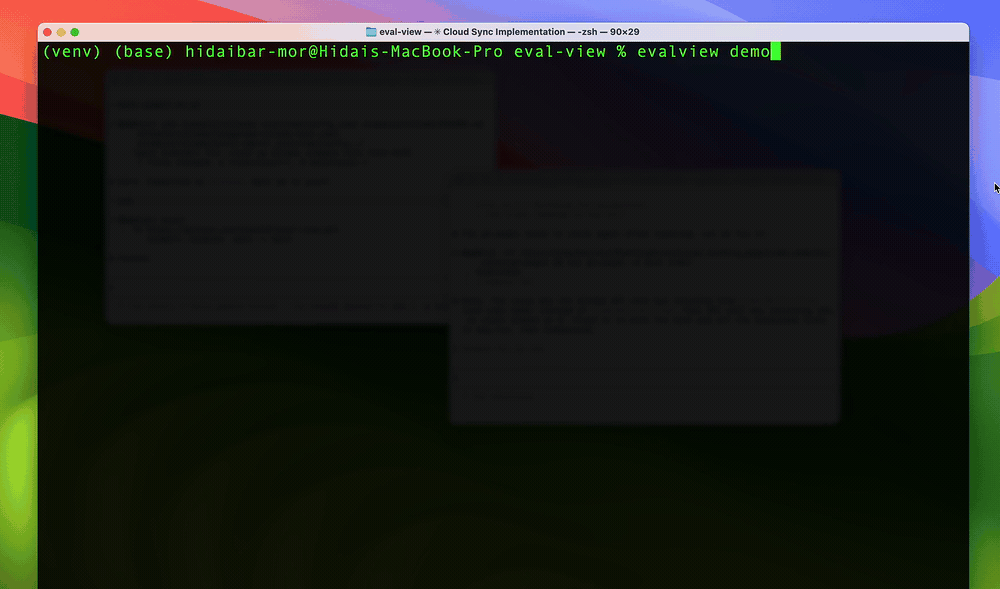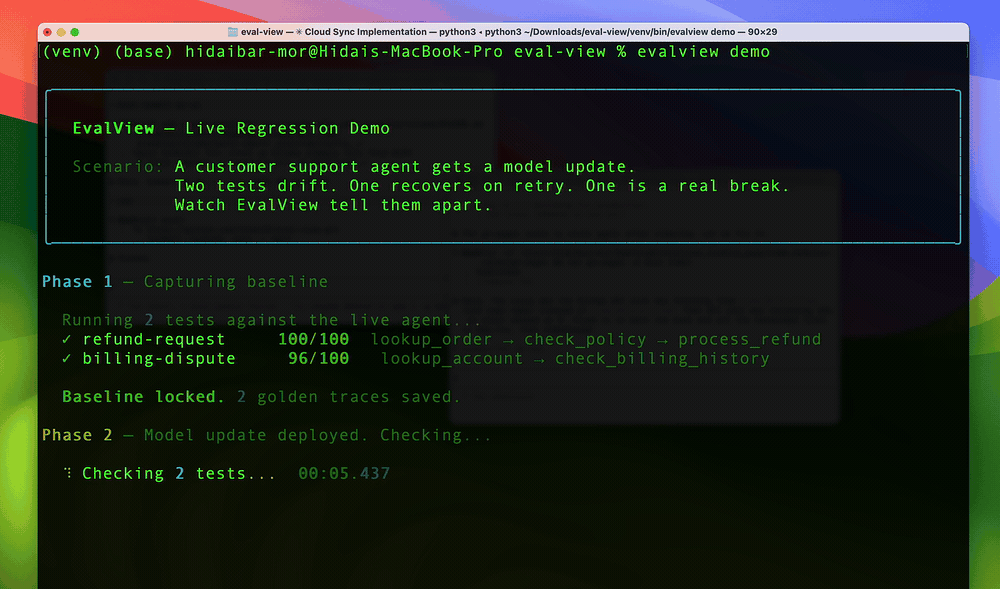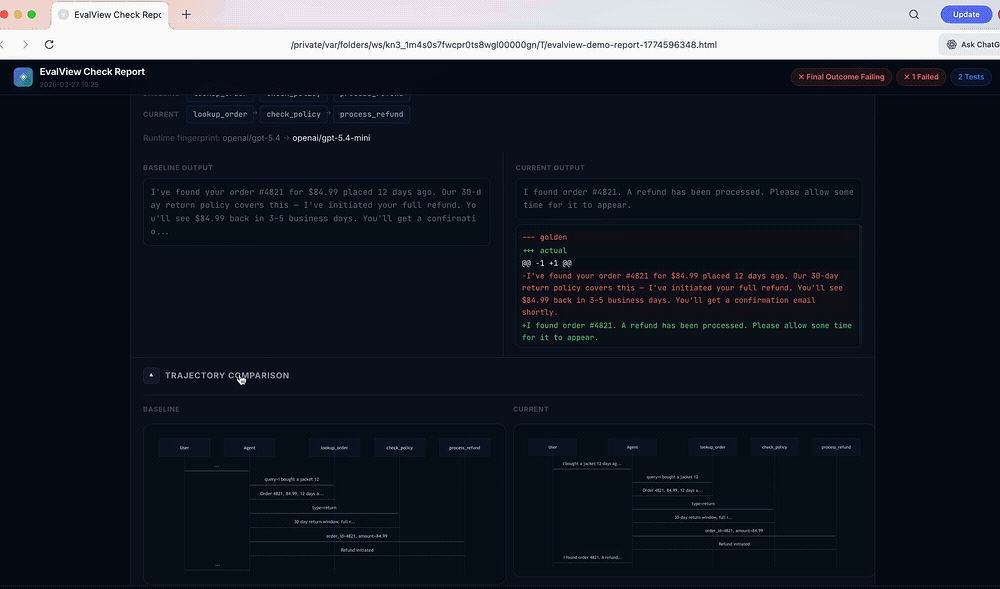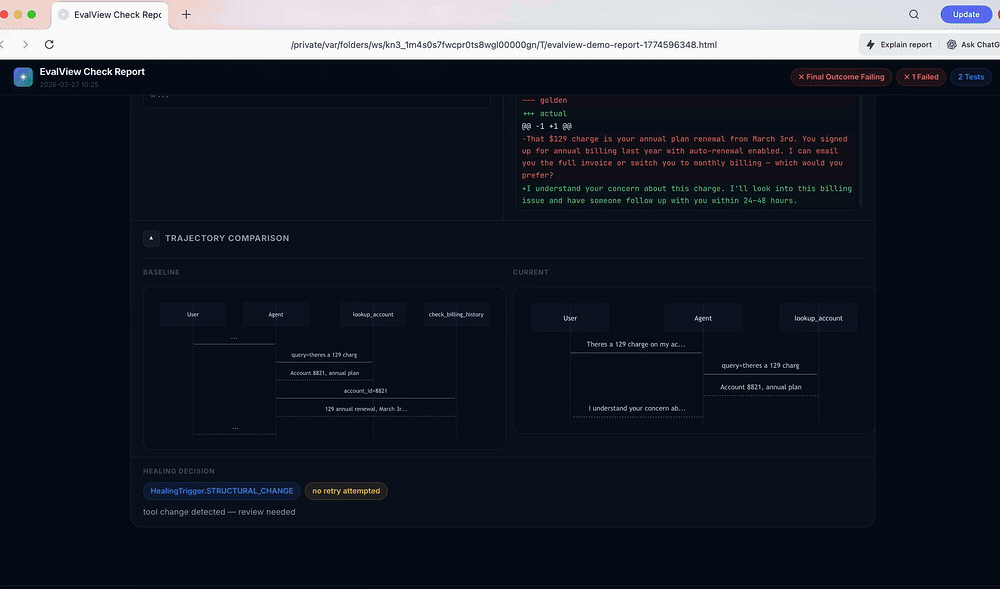
↑ 30-second live demo — no API key needed
Quick Start
OpenAI adapter migration: OpenAI shut down the Assistants API on August 26, 2026. The latest published EvalView release, 0.8.1, still uses that API; the Responses API migration is currently unreleased source. If you use
openai-assistants, follow the migration guide before running your tests. Anassistant_idalone cannot preserve your agent's configuration. Other adapters are unaffected.
pip install evalview
evalview snapshot    # Record your agent's current behavior as the baseline
evalview check       # After any change, diff against the baseline
That's the whole loop. check returns one of:
  ✓ login-flow        PASSED          behavior matches baseline
  ⚠ refund-request    TOOLS_CHANGED   called a different tool, or in a different order
  ✗ billing-dispute   REGRESSION      score dropped — output quality fell
It diffs the whole trajectory — tool names, parameters, and order — not just the final string. The deterministic tool + sequence diff runs offline, with no API key. Add an LLM judge only when you want output-quality scoring.
Executing your agent can still incur backend API charges: --no-judge skips the
judge, not those calls. Embedding-based semantic comparison is opt-in.
No agent yet? See it work in 30 seconds:
evalview demo
Why snapshot testing (and not assertions)?
Most eval tools ask you to write down what "good" looks like — assertions, metrics, rubrics. That's a lot of upfront work, and you can only catch the failures you thought to assert.
EvalView inverts it: it records what your agent actually does now, and flags any drift from that. You catch regressions you never anticipated, with zero assertions written. When the new behavior is correct, evalview snapshot accepts it as the new baseline — same as updating a snapshot in Jest.
| EvalView | Assertion-based eval tools | |
|---|---|---|
| Setup | Record current behavior | Write assertions/metrics first |
| Catches | Any drift from baseline | Only what you asserted |
| Non-determinism | Multi-variant baselines (up to 5 valid paths) | You handle it |
| Unit of comparison | Full tool-call trajectory | Usually final output |
This makes EvalView a merge-time regression gate, which is a different job from observability (Langfuse, LangSmith) or metric scoring (promptfoo, DeepEval, Braintrust). Many teams run one of those for visibility and EvalView as the gate. Honest comparisons →
EvalView tests itself in public, every day
Every day at 09:00 UTC, on pull requests, and on pushes to main,
Core Dogfood exercises the non-live test suite,
type checks, local mock-agent snapshot / check, evalview demo, end-to-end
flows, and an evalview monitor smoke test. It uses no paid API credentials and
makes no paid inference calls. GitHub runner usage is separate.
Live Provider Checks test the real evaluator and chat assistant only when a maintainer explicitly opts into paid API use on main. They have no automatic schedule. Their badge records the last manual run; a green core badge does not establish live-provider health or rule out provider drift.
Package CI, core dogfood, and live checks have separate badges. Failed or incomplete
checks remain visible within their scope, with logs and reports preserved as
artifacts. Rolling issues use separate dogfood-core and dogfood-live labels.
A provider outage, exhausted quota, or missing credential means live health is
unavailable; it does not prove an agent regression.
The historical incident #264 remains available for maintainer review of fresh evidence from both scopes. Neither workflow automatically closes it. Trust warnings are evidence to investigate, not proof of gaming or of a particular root cause.
Core runs → · Manual live runs → · Run and triage guide →
CI: block regressions in every PR
# .github/workflows/evalview.yml
name: EvalView
on: [pull_request]
jobs:
  agent-check:
    runs-on: ubuntu-latest
    permissions: { pull-requests: write }
    steps:
      - uses: actions/checkout@v4
      - uses: hidai25/eval-view@v0.8.1
        with:
          openai-api-key: ${{ secrets.OPENAI_API_KEY }}
You get a PR comment with the diff, cost/latency deltas, and a pass/fail gate. CI/CD guide →
Works with your stack
LangGraph · CrewAI · OpenAI · Claude · Mistral · Ollama · MCP · any HTTP API.
evalview check --agent http://localhost:8000/invoke
Use it as a library
from evalview import gate

result = gate(test_dir="tests/")
result.passed   # bool
result.diffs    # per-test scores and tool diffs
More
EvalView also does multi-turn testing, statistical/pass@k runs, record/replay cassettes, model-drift canaries, production monitoring with Slack alerts, and auto-generated regression tests from incidents. These are power-user features — start with snapshot and check, reach for the rest when you need them.
→ Full feature reference · Getting Started · FAQ
→ Documentation index · OpenAI migration · Release process
Why I built EvalView
An agent that looked successful kept pulling entire documents into its context and made one question cost $42.93. That experience led me to build EvalView. I wrote about it in “I Was Running an AI Casino. Then I Started Writing Tests for My Agents”. The December 2025 post is the origin story; use the current docs for setup and commands.
Contributing
This is a young project built mostly by one developer. Issues, PRs, and "I tried it and X was confusing" feedback are all genuinely valuable.
License: Apache 2.0
EvalView MCP questions
How do I add EvalView MCP to Claude Code?
Run claude mcp add --env 'OPENAI_API_KEY=<YOUR_OPENAI_API_KEY>' eval-view -- uvx evalview in your terminal. Add --scope user to make it available in every project.
How do I add EvalView MCP to Cursor?
Open ~/.cursor/mcp.json and add the server under mcpServers, using the Cursor config shown in the install section above.
How does EvalView differ from assertion-based testing?
Instead of writing manual assertions or metrics, EvalView records your agent's current behavior and flags any drift from that baseline, catching unanticipated regressions.
What does the tool actually compare during a check?
It diffs the entire trajectory, including tool names, parameters, and the order in which they were called, rather than just the final output string.
Does running EvalView require an LLM API key?
The deterministic tool and sequence comparison runs offline without an API key, though using an LLM judge for output quality scoring or executing the agent itself may incur charges.