
Maps and governs AI attack surfaces in application code by detecting LLM calls, agents, MCP servers, and RAG pipelines locally and offline.
Also known as apisec-inc/AI-Surface
- Stars
- 144
- Tools
- —
- Downloads, 30 days
- —
- Latest version
- —
- Last commit
- Oct 8, 2026
- License
- MIT
What is AI-Surface MCP?
AI-Surface maps and governs AI attack surfaces in application code by detecting LLM calls, agents, MCP servers, and RAG pipelines locally and offline.
Summary generated from the project's README
About AI-Surface MCP server
Securing application code against AI-related vulnerabilities is what AI-Surface enables for DevOps, AppSec, and platform engineering teams. It maps the AI attack surface by detecting LLM calls, agents, MCP servers, RAG pipelines, and vector stores. The tool operates as a local static analysis pass that executes no code and makes no network calls, ensuring your source code never leaves your host. Because it runs entirely offline without telemetry, it is suitable for sensitive environments.
Developers can use the tool via a CLI to scan directories, generate an AI-BOM, or integrate it into CI/CD pipelines using a single command. It provides a scorecard and categorizes findings as either confirmed risks or likely risks. The tool also offers an MCP server for use within AI coding assistants like Claude Code, Cursor, or Windsurf, and a Claude Code hook that automatically flags new surfaces after edits. Findings are mapped to established standards including the OWASP LLM Top 10, EU AI Act, NIST AI RMF, and ISO 42001.
What you can do with it
- 1Audit AI attack surfacesIdentify all LLM calls, agents, and RAG pipelines currently present in your codebase.
- 2Gate high-risk pull requestsPrevent new high-risk AI vulnerabilities from being merged into your main branch by failing CI builds.
- 3Monitor AI code editsReceive immediate feedback within your AI coding assistant when a change introduces a new AI surface.
- 4Generate governance evidenceCreate an AI-BOM that includes compliance mapping for regulatory requirements.
Written from the project's README. Every use case is checked against a quote from it.
Automated checks
Ran Nov 14, 2026Full report →Not verified yet. A server needs a score of 80, no serious finding, and enough data for us to check. How checks work · What to fix for more points

- Source repository linked and reachableapisec-inc/ai-surface is public and reachablegithub.com/apisec-inc/ai-surface ↗Pass
- Package names this repository as its sourceNot checked
- Build provenance (Sigstore attestation)Not checked
- Open source license (OSI)MITspdx.org/licenses/MIT.html ↗Pass
- Commit or release in the last yearLast commit or release 2026-10-08github.com/apisec-inc/ai-surface ↗Pass
- OpenSSF ScorecardNot checked
- Package name not close to a popular packageNot checked
- No critical advisory in the package or its dependenciesNot checked
- No hidden instructions to the model0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersPass
- Destructive tools are labelledNot checked
- Remote endpoint answers the MCP handshakeNot checked
README
View on GitHubai-surface
Find the AI attack surface your code is about to ship. Locally, offline, before the PR merges.


ai-surface maps the AI attack surface in your codebase: LLM calls, agents, MCP servers, RAG/vector stores, model gateways, self-hosted runtimes, provider keys, and the HTTP APIs that expose them. Run it locally, in CI, or inside your AI coding tool to see what AI surfaces a change introduces, generate an AI-BOM, and gate new high-risk findings before merge.
Most layers of a codebase already have a check that runs before merge: Trivy for container images, Gitleaks for committed secrets, an SCA for dependencies. The AI layer, the agents, MCP servers, RAG, and LLM calls, has not had one. ai-surface is that check.
Every risky finding carries a verdict: confirmed risk (an unambiguous fact of the code as written, like a financial-action tool with no approval step) or likely risk (inferred, wants a human look). Every scan ends on a scorecard with a posture grade. CI setup is one command: ai-surface init.
It runs as a local static analysis pass that executes no code, makes no network calls, sends no telemetry, and requires no credentials, so your source never leaves the host.
Try it without installing:
uvx --from apisec-ai-surface ai-surface scan .
If ai-surface is useful to you, star the repo so more engineers find it.
Findings map to the OWASP LLM Top 10 and the EU AI Act, NIST AI RMF, and ISO 42001, so the AI-BOM doubles as governance evidence (see Compliance). Runtime exploit validation is out of scope for this OSS scanner.
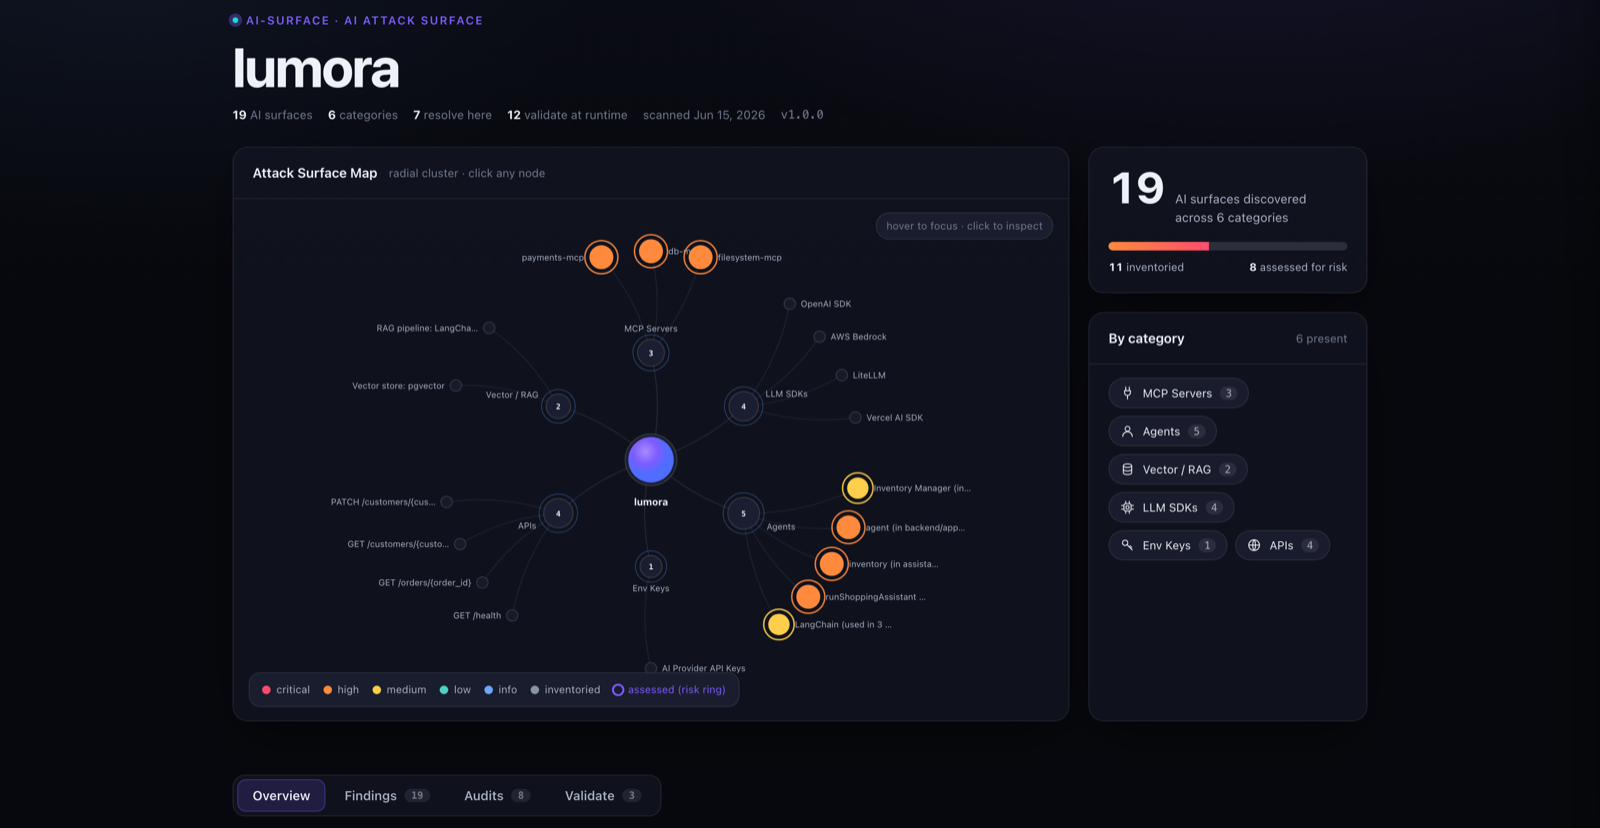
The optional --ui map shows detected AI surfaces as nodes grouped by category. It is served on loopback and runs locally.
Who is this for?
Use ai-surface if you are:
- adding agents, MCP servers, RAG, model gateways, or LLM calls to an application
- reviewing AI-related pull requests before they merge
- adding an AI risk gate to CI/CD
- building an AI-BOM or AI-governance inventory from source code
- trying to understand where AI risk enters your codebase
Built for DevOps, DevSecOps, platform engineering, AppSec, and security-minded engineering teams.
Table of Contents
- Who is this for?
- Quick start
- What the output looks like
- First run on a mature repo
- GitHub Action and CI gating
- Inside your AI coding tool: MCP server and Claude Code hook
- Open the local UI
- What it detects
- Proven on real code
- Output formats
- CLI reference
- Compliance and governance
- How it works
- Comparison with adjacent tools
- What it does not do
- Roadmap
- Runtime validation
- Development
- Project
- License
Quick start
Install once, then run ai-surface anywhere:
pipx install apisec-ai-surface
ai-surface scan .
# if the ai-surface command is not found after install, run: pipx ensurepath
# then open a new shell

# or run once with no install
uvx --from apisec-ai-surface ai-surface scan .

# or in a project venv
pip install apisec-ai-surface && ai-surface scan .

# explore the results visually
ai-surface scan . --ui
Requires Python 3.9+. The CLI runs locally; --ui serves on loopback only.
What the output looks like
Reproduce this yourself on the bundled demo app: ai-surface scan examples/demo-app --governance (add --ui for the interactive map). Each risky finding carries a verdict: CONFIRMED RISK when the risk is a fact of the code as written (a declared capability, a present secret, a financial tool with no approval step) or LIKELY RISK when it is inferred and wants a human look. The run ends on a scorecard. The block is shown with --governance so the per-finding EU AI Act / NIST / ISO clauses are visible; by default those collapse to a single summary line (Governance: evidence for EU AI Act, NIST AI RMF, ISO/IEC 42001, OWASP LLM Top 10). Add --ai-only to drop the plain API-endpoint section. Output below is trimmed for length.
AI Attack Surface Report
────────────────────────────────────────────────────────────────
Project:    demo-app
19 production AI surfaces · 25 risk indicators · across 8 detector(s)
Severity: 3 high · 1 medium

AGENT FRAMEWORKS
  • AWS Strands Agent: triage_agent (in src/support_workflow.py)
      Tools/perms: fetch_customer_profile, search_knowledge_base, escalate_to_human
  • LangChain Agent: support_agent (in src/chat_agent.py)  CONFIRMED RISK  [HIGH]
      Tools/perms: lookup_order, refund_payment, cancel_subscription
      ⚠ financial action exposed   ⚠ high blast-radius combination
      ⚑ [HIGH] financial-action
        Agent can invoke financial tools (refund_payment)
        OWASP: LLM06    Governance: EU AI Act Art. 9
        Fix: Gate financial tools behind human approval; least-privilege the agent.
      ⚑ [HIGH] no-human-oversight
        High-risk action runs with no human approval / in-the-loop gate detected
        OWASP: LLM06, LLM09    Governance: EU AI Act Art. 14

MCP SERVERS
  • MCP Server: stripe-mcp  CONFIRMED RISK  [HIGH]   Trust: verified (90/100)
      Tools/perms: read_charges, refund, customer:read
      ⚑ [HIGH] financial-action
        MCP exposes financial tools (refund, charge, payout) to the model.
        OWASP: LLM06    Governance: EU AI Act Art. 9
      ⚑ [MEDIUM] unverified-source
        MCP is not from a known/verified publisher; its posture is unknown.
        OWASP: LLM03    Governance: ISO 42001 A.10
  • MCP Server: github-mcp  CONFIRMED RISK  [MEDIUM]
      ⚑ [MEDIUM] remote-mcp        MCP connects to a remote server via URL
      ⚑ [MEDIUM] broad-permissions MCP is granted broad (admin/write) scopes

LLM SDK CALL SITES
  • Anthropic SDK  LIKELY RISK · claude-3-5-sonnet · src/llm_service.py
      ⚠ non-literal data flows into LLM call
  • AWS Bedrock · us.anthropic.claude-sonnet-4 · src/support_workflow.py

VECTOR-STORE
  • Vector store: pgvector  LIKELY RISK        ⚠ retrieved content reaches the model (RAG)
  • RAG pipeline: LangChain  LIKELY RISK       ⚠ ingests external content (RAG poisoning surface)

API ENDPOINTS
  • REST API: GET   /orders/{order_id}         LIKELY RISK   ⚠ object-id in path (BOLA candidate)
  • REST API: PATCH /customers/{customer_id}   LIKELY RISK   ⚠ object-id in path (BOLA candidate)

Governance: evidence for EU AI Act, NIST AI RMF, ISO/IEC 42001, OWASP LLM Top 10
────────────────────────────────────────────────────────────────
AI Surface Scorecard   D
  19 surfaces · 4 confirmed risk · 11 likely risk
  Worst finding: MCP Server: stripe-mcp: MCP exposes financial tools (refund, charge, payout) to the model.
First run on a mature repo
The first run maps the AI surfaces already present in the codebase. The pattern that scales is to baseline existing surfaces, then gate only new high-risk findings in pull requests:
ai-surface scan . --update-baseline           # 1. snapshot today's inventory
ai-surface scan . --baseline                  # 2. show only what changed
ai-surface scan . --baseline --fail-on high   # 3. in CI, fail only on NEW high+ risk
--baseline --fail-on high is the recommended PR gate: low-noise, non-blocking on pre-existing debt, and actionable.
GitHub Action and CI gating
The fastest path is one command from your repo root:
ai-surface init
It writes the recommended workflow below into .github/workflows/ai-surface.yml and prints a pre-commit snippet for local scans (the repo ships .pre-commit-hooks.yaml).
Or drop this into .github/workflows/ai-surface.yml yourself:
name: AI Surface Check
on: [pull_request]

permissions:
  contents: read
  pull-requests: write   # required when comment-on-pr is true

jobs:
  ai-surface:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
        with:
          fetch-depth: 0   # required for base-vs-head diff
      - uses: apisec-inc/AI-Surface@v1
        with:
          path: '.'
          comment-on-pr: 'true'
          fail-on: 'high'  # fail only on NEW high-or-critical findings
Every PR gets a sticky comment showing what changed in the PR, not just the current repo state. fail-on gates on assessed severity, so inventory-only findings do not fail the build. With fail-on: high, the build fails only when the PR introduces a new high-or-critical finding.
No API keys are required. The action uses the built-in GITHUB_TOKEN to post or update the PR comment.
For non-GitHub CI, the gate is just an exit code:
ai-surface scan . --fail-on high
See docs/CI_INTEGRATION.md for permissions, fork PR behavior, baseline options, SARIF upload, policy files, and multi-repo rollups.
Inside your AI coding tool: MCP server and Claude Code hook
AI assistants now write a growing share of application code, and AI-written code is exactly where new AI attack surface appears: a new agent tool, a new MCP server, a new LLM call, usually added by someone who cannot see what they just exposed. ai-surface can sit inside that loop and flag the surface at the moment it is created.
Two pieces, both local, offline, and read-only:
- An MCP server.
ai-surface mcpexposes two tools to any MCP client (Claude Code, Cursor, Windsurf, Cline):scan_ai_surfaceinventories a path, andcheck_new_ai_surfacereports only what changed since the last check, with the OWASP LLM Top 10 ids and EU AI Act, NIST AI RMF, and ISO 42001 clauses for each finding. - A Claude Code hook.
ai-surface hook claude-coderuns automatically after every edit. When a change introduces or expands AI surface, the finding is injected into the session so Claude tells you and can offer a guard, for example a human approval step in front of a refund tool. When a later edit puts that guard in place, the hook says so. This is fix confirmation: a flagged risk cleared gets its own all-clear line, so the loop is flag, fix, confirm. It is silent on ordinary edits, never fails a tool call, and keeps its rolling baseline outside your repository.
Set both up for a repo with one command:
pip install "apisec-ai-surface[mcp]"   # the MCP server needs Python 3.10+; the hook has no extra needs
ai-surface init --claude-code
This writes the hook into .claude/settings.json and the server into .mcp.json, merging with anything already there. Start claude in the repo and approve both when prompted.
For Cursor and other MCP clients, register the server as a stdio command:
{ "mcpServers": { "ai-surface": { "command": "ai-surface", "args": ["mcp"] } } }
The pre-commit hook and the GitHub Action remain the editor-agnostic guarantees: they catch the same surface regardless of which tool wrote the code. See docs/INTEGRATIONS.md for the tool reference, the hook contract, where state is kept, and troubleshooting.
Open the local UI
After installing ai-surface, you can open the interactive AI attack-surface map from any repo:
ai-surface scan . --ui
The UI shows detected AI surfaces as nodes grouped by category, with risk indicators, governance badges, evidence, and AI-BOM download where available.
The UI is served locally over 127.0.0.1 from a temporary directory.
The analysis never runs in the browser, your source code never leaves your machine, and no telemetry is collected.
To stop the local UI server, press Ctrl-C in the terminal.
What it detects
ai-surface looks for eight categories of AI surface. Configuration files, provider keys, manifests, and specs are detected across stacks; deeper code-level detection is strongest today for Python and TypeScript/JavaScript. See docs/LANGUAGE_SUPPORT.md for the full matrix.
| Category | Coverage | What it finds |
|---|---|---|
| Agent frameworks | 11 Python + 7 JS/TS frameworks | LangChain, LangGraph, CrewAI, LlamaIndex, AutoGen, Haystack, Semantic Kernel, Pydantic AI, AWS Strands, the OpenAI Agents SDK and the Claude Agent SDK (Python); LangChain.js, LangGraph.js, Vercel AI SDK, Mastra, OpenAI Agents SDK, LlamaIndex.ts, and the Claude Agent SDK (TS/JS). Extracts agent tool inventories and flags financial, destructive, and high-blast-radius authority. |
| MCP servers | Discovery + deep-dive audit | Configured MCP servers such as .mcp.json entries and in-house source servers. Audited findings include risk flags, remediation, detected secrets by name/type only, and registry/trust signals. |
| Vector stores / RAG | 13 stores + 2 frameworks | Pinecone, Weaviate, Chroma, Qdrant, Milvus, FAISS, LanceDB, pgvector, Elasticsearch/OpenSearch/Vespa/Redis in vector mode, plus LangChain and LlamaIndex retrieval pipelines. Flags managed-store egress, RAG data flow, embeddings, and external ingestion. |
| LLM SDK call sites | 13 providers | Anthropic, OpenAI, Azure OpenAI, AWS Bedrock, Google Generative AI, Vertex AI, Together, Mistral, Cohere, Replicate, Groq, LiteLLM, and Vercel AI SDK. Extracts models where visible and flags non-literal prompt/message flow. |
| API endpoints | HTTP/REST + OpenAPI | OpenAPI/Swagger specs and framework routes including FastAPI, Starlette, Flask, Express, Spring, and Django. Captures method, path, framework, auth style, and object-id path segments that may need BOLA review. |
| Model gateways | Configs + source | LiteLLM proxy, Portkey, Helicone, Cloudflare AI Gateway, and OpenRouter. Captures routed-model inventories where visible. |
| AI infrastructure | Manifests + IaC | Kubernetes, Helm, Docker Compose, Dockerfiles, and Terraform for AI runtimes and managed AI services such as Ollama, vLLM, TGI, SGLang, Triton, llama.cpp, Bedrock, SageMaker, and Vertex endpoints. |
| AI provider keys | Names only | Common provider key names such as OPENAI_API_KEY, ANTHROPIC_API_KEY, and AZURE_OPENAI_* across environment files and config. Values are never read or printed. |
Inventory categories do not get severity by default. Severity is assigned only when the deep-dive audit has enough evidence, currently in MCP, agent, and RAG findings. See docs/DETECTORS.md for every pattern matched.
Proven on real code
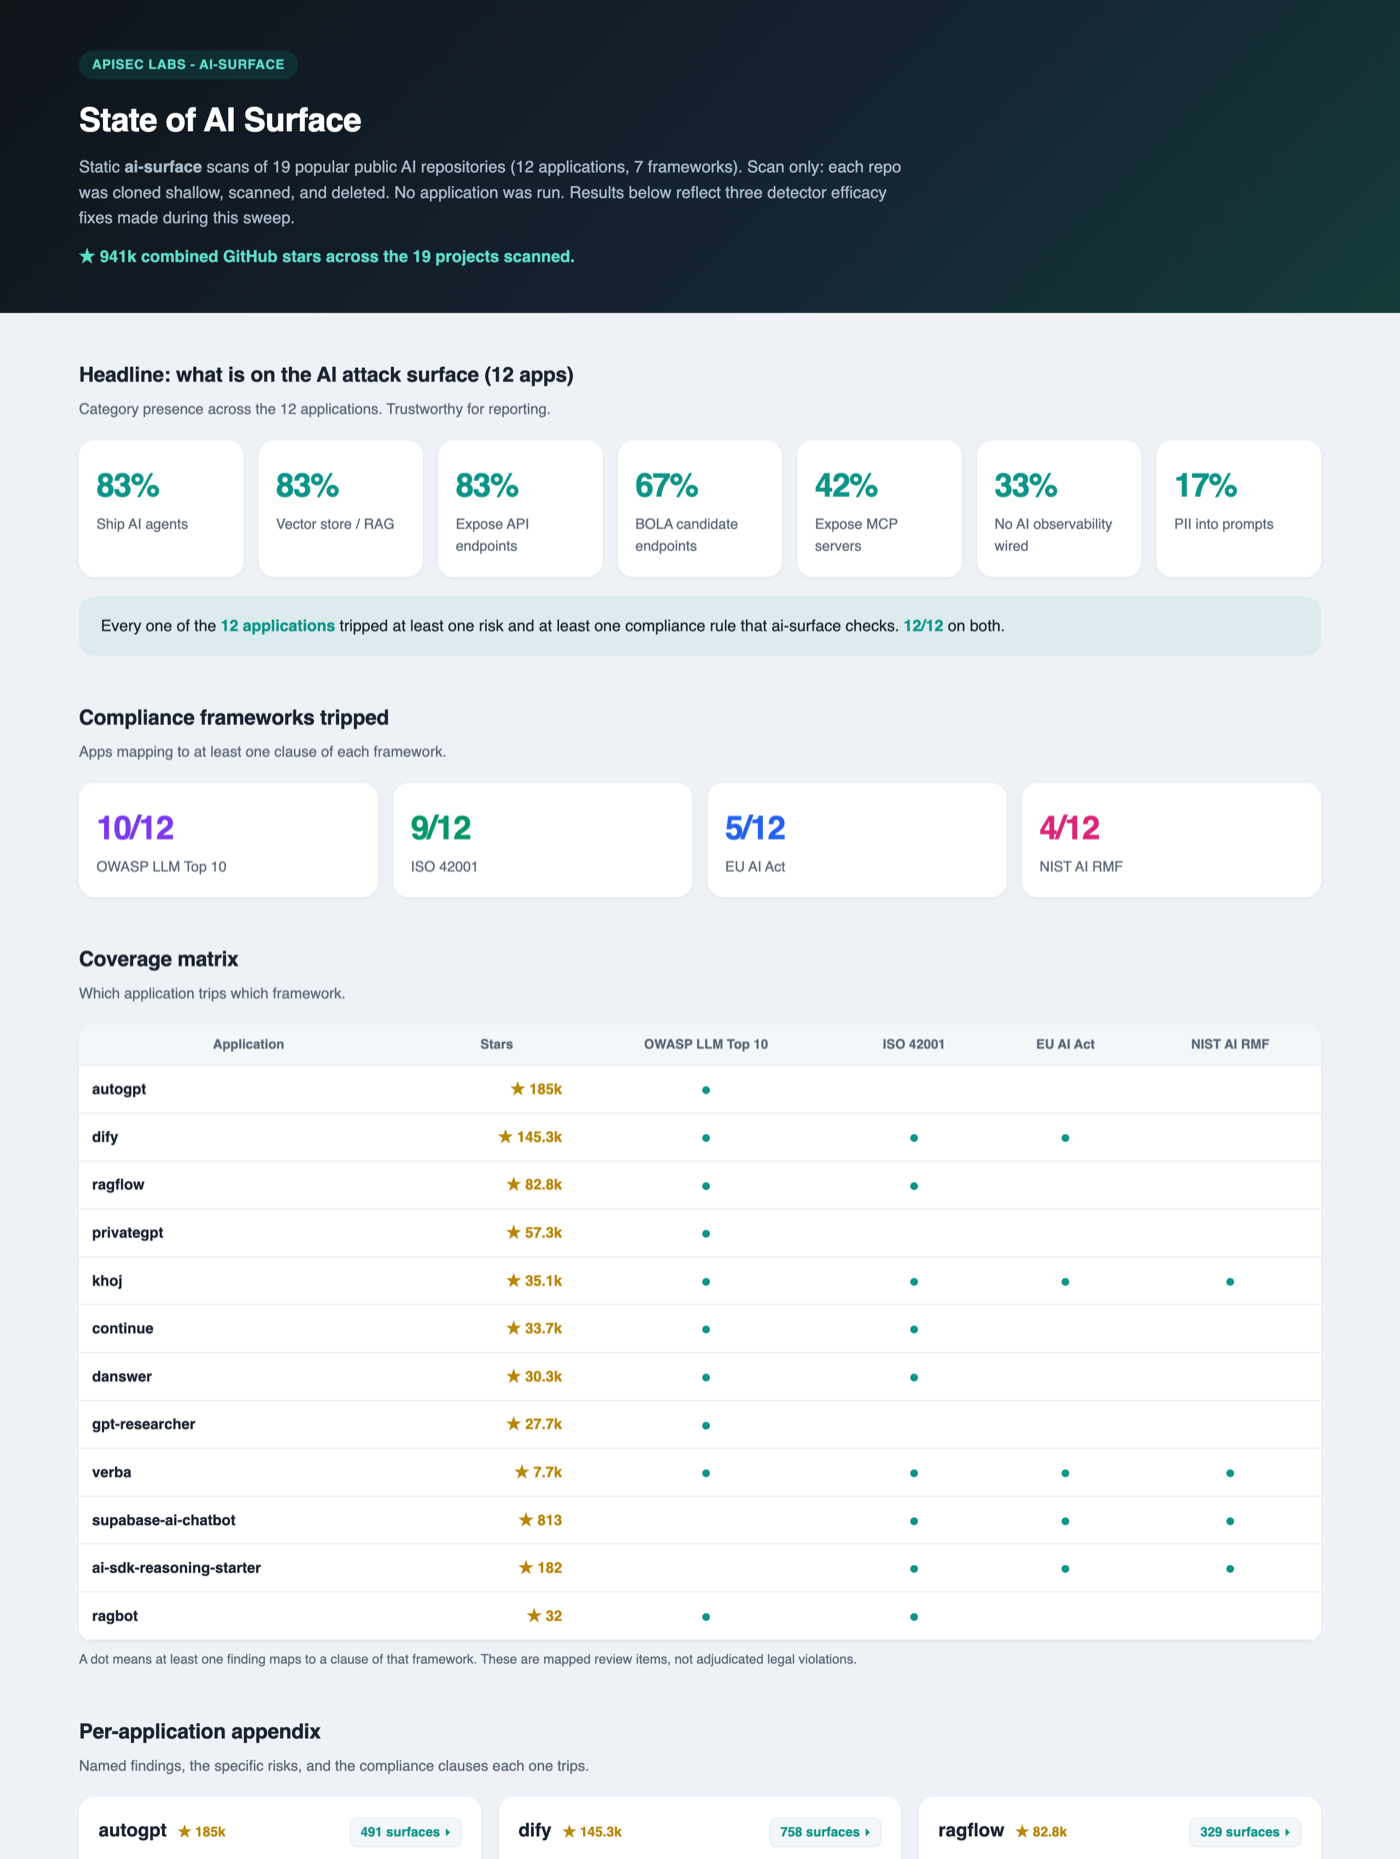
We tested ai-surface against 19 popular open-source AI projects on GitHub, representing about 941k combined stars at the time of analysis. The set included AutoGPT, Dify, RAGFlow, AutoGen, CrewAI, LlamaIndex, Continue, Danswer, and others.
This was a static, offline analysis only: each repo was shallow-cloned, analyzed locally, and deleted. No application was run. No code left the host.
The set split into 12 applications and 7 framework/library repos. Frameworks and libraries are reported separately because they often include many integrations as code paths, so their raw component counts are not comparable to applications.
Across the 12 application repos, ai-surface found:
| Signal | Apps |
|---|---|
| Ship AI agents | 83% |
| Have a vector store / RAG layer | 83% |
| Expose API endpoints | 83% |
| Have API endpoints that may need BOLA review | 67% |
| Expose MCP servers | 42% |
| Run an agent/MCP surface with no observability wired | 33% |
| Interpolate PII into prompts | 17% |
| Trip at least one risk and one governance rule | 100% |
These are category-presence signals, not exploitability claims. The numbers are a floor, not a ceiling: tool resolution is regex/AST-light today, so some agent/tool risks can under-fire on larger platforms. Raw per-component counts are useful for investigation but can vary by framework, coding style, and detector coverage.
Full methodology, per-app appendix, framework/library appendix, and caveats are in the State of AI Surface report.
Output formats
ai-surface scan .                      # terminal report
ai-surface scan . --ui                 # interactive map in a local browser
ai-surface scan . --output json        # machine-readable JSON (schema 1.0)
ai-surface scan . --output markdown    # human-readable Markdown report
ai-surface scan . --output cyclonedx   # CycloneDX AI-BOM
ai-surface scan . --output sarif       # SARIF 2.1.0 for GitHub code scanning
ai-surface scan . --write-inventory    # write .ai-inventory.md to the project root
ai-surface scan . --quiet              # one-line CI summary
CycloneDX output is the AI-BOM: an inventory artifact generated in CI the way teams already generate SBOMs, with AI governance mappings attached.
SARIF output can be uploaded to GitHub code scanning for Security tab visibility and inline PR annotations.
The --ui viewer serves over 127.0.0.1 from a throwaway temp directory; the analysis never runs in the browser, nothing is sent off your machine, and there is no telemetry.
CLI reference
# Map the current project
ai-surface scan .

# Open the local interactive map
ai-surface scan . --ui

# Produce machine-readable or human-readable output
ai-surface scan . --output json
ai-surface scan . --output markdown
ai-surface scan . --output cyclonedx
ai-surface scan . --output sarif

# Filter to specific categories
# aliases: mcp, agents, llm, gateway, infra, keys, api, vector
ai-surface scan . --categories mcp,agents
ai-surface scan . --categories vector

# Focus on AI-specific surface (drop plain, non-AI API endpoints)
ai-surface scan . --ai-only

# Show per-finding governance clauses (EU AI Act / NIST / ISO)
# Off by default; a one-line governance summary always shows.
ai-surface scan . --governance

# Gate CI by assessed severity
ai-surface scan . --fail-on high       # fail on high or critical findings
ai-surface scan . --fail-on critical   # fail only on critical findings

# Severity floor the baseline cannot suppress (closes baseline-acceptance gap)
# New high+ blocks the PR; any critical always blocks, even if pre-existing.
ai-surface scan . --baseline --fail-on high --always-fail-on critical

# Aggressive gate: fail on any risk indicator
ai-surface scan . --fail-on-risk

# Baseline existing AI surfaces, then show only what changed
ai-surface scan . --update-baseline
ai-surface scan . --baseline
ai-surface scan . --baseline --fail-on high

# Compare two reports
ai-surface compare base.json head.json
Editor and agent integrations:
| Command | What it does |
|---|---|
ai-surface init --claude-code |
Wire the hook and the MCP server into this repo's Claude Code config |
ai-surface mcp |
Run the MCP server over stdio (needs the [mcp] extra, Python 3.10+) |
ai-surface hook claude-code |
The Claude Code PostToolUse / SessionStart hook; reads the payload on stdin |
ai-surface hook claude-code --reset |
Forget the hook's rolling baseline for the current repo |
Compliance and governance
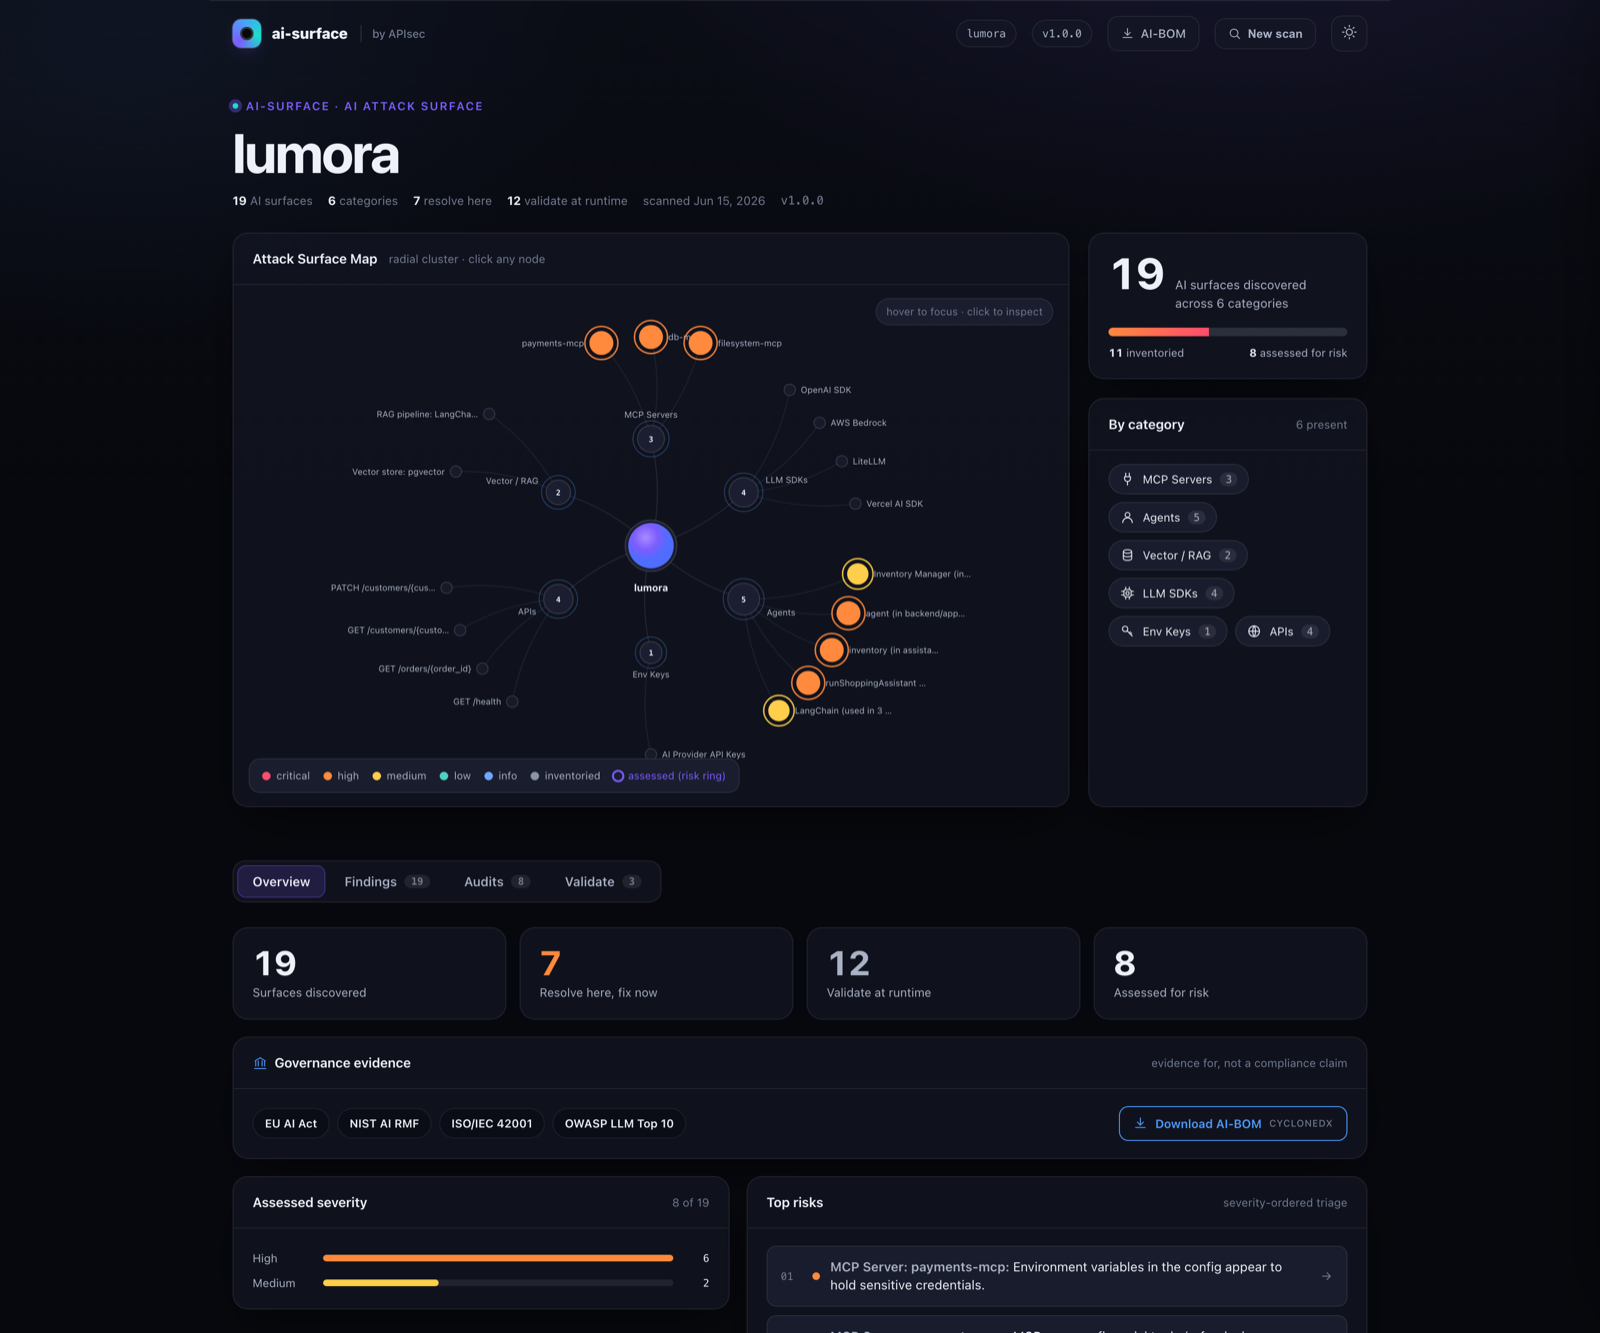
ai-surface maps audited findings to the OWASP LLM Top 10 and to evidence-relevant clauses in the EU AI Act, NIST AI RMF, and ISO/IEC 42001.
In terminal and markdown output, the per-finding clauses are off by default and a single governance summary line is shown instead; pass --governance to print the clause under each risk flag. The UI shows these mappings as badges. JSON output always carries them as structured standards fields. CycloneDX output carries them as component properties, making it your AI-BOM artifact.
ai-surface produces evidence; it does not certify, attest, or assert compliance. A framework requirement is reported only when the analysis produced that kind of evidence.
What the mappings cover
| Evidence kind | Examples | Framework use |
|---|---|---|
| Inventory | agents, MCP servers, RAG/vector stores, LLM calls, gateways, AI infra | AI-BOM, system documentation, governance inventory |
| Risk | financial tools, destructive tools, high-blast-radius agents, secret-bearing MCP config | risk review and assessment evidence |
| Human oversight | high-risk action with no detected approval gate | EU AI Act Art. 14 review signal |
| Logging / monitoring | agent or MCP execution surface with no detected tracing | EU AI Act Art. 12, NIST MEASURE 3, ISO A.6.2.6 evidence |
| Data governance | RAG/vector layer, PII interpolated into prompts | EU AI Act Art. 10, ISO A.7 evidence |
Example risk-flag mappings
| Risk flag | OWASP | EU AI Act | NIST AI RMF | ISO/IEC 42001 |
|---|---|---|---|---|
secrets-in-env |
LLM02 | Art. 15 | - | - |
financial-action / destructive-action / high-blast-radius |
LLM06 | Art. 9 | - | - |
no-human-oversight |
LLM06 / LLM09 | Art. 14 | - | - |
no-observability |
- | Art. 12 | MEASURE 3 | A.6.2.6 |
pii-to-llm |
LLM02 | Art. 10 | - | A.7 |
unverified-source / remote-mcp / local-binary |
LLM03 | - | - | A.10 |
| vector store / RAG present | LLM08 | Art. 10 | data | A.7 |
The reported footprint is a floor, not a ceiling: static analysis can miss risks in code that builds tools dynamically or through factory functions.
Full mapping details, caveats, and AI-BOM generation guidance are in docs/COMPLIANCE.md.
AI-Surface MCP questions
Does ai-surface require internet access or API keys?
No, it runs as a local static analysis pass that makes no network calls, sends no telemetry, and requires no credentials.
Can I use ai-surface with my AI coding tools like Claude Code or Cursor?
Yes, it provides an MCP server and a Claude Code hook to flag AI surfaces at the moment they are created within your coding session.
How does the tool handle existing security debt in a repository?
You can baseline existing surfaces and then configure the tool to only fail CI/CD on new high-risk findings.
What compliance frameworks does the tool support?
Findings map to the OWASP LLM Top 10, the EU AI Act, NIST AI RMF, and ISO 42001.