
Enables AI agents to perform associative recall over markdown notes by combining vector search with wikilink graph traversal in SQLite.
Also known as tonydzi/sqlite-graph-memory
- Stars
- 15
- Tools
- —
- Downloads, 30 days
- —
- Latest version
- 0.3.9
- Last commit
- Nov 12, 2026
- License
- MIT
What is sqlite-graph-memory MCP?
sqlite-graph-memory enables AI agents to perform associative recall over markdown notes by combining vector search with wikilink graph traversal in SQLite.
Summary generated from the project's README
About sqlite-graph-memory MCP server
Developers using Claude Code, Cursor, Codex, or Windsurf can provide their coding agents with associative memory by connecting them to their existing markdown notes. This MCP server functions as a read-only search layer that combines vector search with graph traversal. Instead of relying on flat chunk retrieval, it uses the wikilinks you have already written in your Obsidian vaults or markdown files to navigate between related topics.
Setup involves installing the package via pip and running the indexing command to build a local SQLite database from your notes folder. The system uses vector search to find entry points and then performs a one-hop graph traversal through your manual links to find relevant information that a standard search might miss. It is designed to be lightweight, requiring only a single SQLite file without the need for a dedicated graph database or complex ETL pipelines. Users can choose between a standard installation or a lite version using ONNX Runtime for faster performance on specific hardware.
What you can do with it
- 1Retrieve information via link hopsAsk an agent to find details about a tool that is only mentioned in a note linked to your current topic.
- 2Maintain persistent memory across sessionsGive your AI agent access to a long-term knowledge base so it does not forget your project context between chats.
Written from the project's README. Every use case is checked against a quote from it.
How to install sqlite-graph-memory MCP
Formats verified 10 Nov 2026Install sqlite-graph-memory MCP in Claude Code
$ claude mcp add --env BRAIN_INDEX_DIR=<BRAIN_INDEX_DIR> sqlite-graph-memory -- uvx sqlite-graph-memoryInstall sqlite-graph-memory MCP in Cursor
~/.cursor/mcp.json
{
  "mcpServers": {
    "sqlite-graph-memory": {
      "command": "uvx",
      "args": [
        "sqlite-graph-memory"
      ],
      "env": {
        "BRAIN_INDEX_DIR": "<BRAIN_INDEX_DIR>"
      }
    }
  }
}Install sqlite-graph-memory MCP in VS Code
.vscode/mcp.json
{
  "servers": {
    "sqlite-graph-memory": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "sqlite-graph-memory"
      ],
      "env": {
        "BRAIN_INDEX_DIR": "<BRAIN_INDEX_DIR>"
      }
    }
  }
}Install sqlite-graph-memory MCP in Claude Desktop
claude_desktop_config.json
{
  "mcpServers": {
    "sqlite-graph-memory": {
      "command": "uvx",
      "args": [
        "sqlite-graph-memory"
      ],
      "env": {
        "BRAIN_INDEX_DIR": "<BRAIN_INDEX_DIR>"
      }
    }
  }
}Install sqlite-graph-memory MCP in Codex
~/.codex/config.toml
[mcp_servers.sqlite-graph-memory]
command = "uvx"
args = ["sqlite-graph-memory"]

[mcp_servers.sqlite-graph-memory.env]
BRAIN_INDEX_DIR = "<BRAIN_INDEX_DIR>"
Install sqlite-graph-memory MCP in Gemini CLI
~/.gemini/settings.json
{
  "mcpServers": {
    "sqlite-graph-memory": {
      "command": "uvx",
      "args": [
        "sqlite-graph-memory"
      ],
      "env": {
        "BRAIN_INDEX_DIR": "<BRAIN_INDEX_DIR>"
      }
    }
  }
}Configuration
BRAIN_INDEX_DIRRequiredDirectory holding the index. Build it once with `sgm-index /path/to/notes`.
TURNSTATE_DBSQLite file for recall telemetry.
| Name | Description | |
|---|---|---|
| BRAIN_INDEX_DIR | Directory holding the index. Build it once with `sgm-index /path/to/notes`. | Required |
| TURNSTATE_DB | SQLite file for recall telemetry. |
Automated checks
Ran Nov 12, 2026Full report →Passed our automated checks. That is not a security audit: read the code and give the server the narrowest access it needs. How checks work

- Source repository linked and reachablePass
- Open source license (OSI)Pass
- Commit or release in the last yearPass
- Package name not close to a popular packagePass
- Remote endpoint uses HTTPSNot checked
- Destructive tools are labelledNot checked
- No hidden instructions to the modelPass
- No critical advisory in the package or its dependenciesPass
README
View on GitHubsqlite-graph-memory: persistent memory for Claude Code, Cursor and Codex over your own markdown notes
Your coding agent remembers what you already wrote down, and reaches the note a plain search
misses by following the links between your notes. It is an MCP server and a CLI over any
folder of markdown, Obsidian vaults included: pip install, point it at the folder, and
Claude Code, Cursor, Codex or any other MCP client can recall from it.
It fits Andrej Karpathy's LLM Wiki pattern (April 2026), where an agent maintains an interlinked markdown wiki and a search tool over the pages is the first helper he suggests adding: sgm is that search layer, read-only, and it follows your [[wikilinks]] as a graph. Independent project, not affiliated with or endorsed by him.
Your agent forgets everything between sessions, and plain vector search gives it back
flat, unrelated chunks. This gives it associative recall over your own markdown notes:
vector search finds the entry points, the [[wikilinks]] you already wrote are the graph.
One SQLite file, no graph database, no ETL pass, no server.




Install in your client
Already using your own agent rules and projects? The Russian existing-setup guide combines this memory backend with the optional starter-kit method, preserves existing settings, and checks recall in a fresh chat. Install one memory connection per client; the starter-kit memory plugin and manual registration are alternatives.
Build the index once (any folder of markdown; uv gives you uvx):
BRAIN_INDEX_DIR=$HOME/.sgm-index uvx --python 3.12 --from 'sqlite-graph-memory[lite]' sgm-index ~/notes
--python 3.12 is deliberate. onnxruntime has no wheels for Python 3.14 on an Intel Mac, or on
Apple Silicon below macOS 14. On such a machine an unpinned uvx falls back to release 0.3.5,
which has no [lite], and sgm-index then stops and asks for [embeddings].
Then point your client at the server. Use the absolute path of that index folder.
Cold-start timeout (0.3.5 and later). The MCP server starts recall in a separate process with a default deadline of 180 seconds; a first call on a clean Windows install took 89 s, which the old fixed 60 s always cut off. Override with BRAIN_RECALL_TIMEOUT (integer seconds, 1 to 600; invalid values return an error). Your MCP client's own tool timeout must also allow the longer call. On 0.3.3 and earlier the deadline is a fixed 60 s: upgrade, or use sgm-ask --ask directly, and do not report MCP recall as verified merely because the CLI works.
Claude Code
claude mcp add sqlite-graph-memory -e BRAIN_INDEX_DIR=$HOME/.sgm-index -- uvx --python 3.12 --with 'sqlite-graph-memory[lite]' sqlite-graph-memory
Cursor (~/.cursor/mcp.json; Claude Desktop, Zed and Windsurf take the same mcpServers block)
{
  "mcpServers": {
    "sqlite-graph-memory": {
      "command": "uvx",
      "args": ["--python", "3.12", "--with", "sqlite-graph-memory[lite]", "sqlite-graph-memory"],
      "env": { "BRAIN_INDEX_DIR": "/absolute/path/to/.sgm-index" }
    }
  }
}
VS Code (.vscode/mcp.json in the workspace)
{
  "servers": {
    "sqlite-graph-memory": {
      "type": "stdio",
      "command": "uvx",
      "args": ["--python", "3.12", "--with", "sqlite-graph-memory[lite]", "sqlite-graph-memory"],
      "env": { "BRAIN_INDEX_DIR": "/absolute/path/to/.sgm-index" }
    }
  }
}
Codex (~/.codex/config.toml)
[mcp_servers.sqlite-graph-memory]
command = "uvx"
args = ["--python", "3.12", "--with", "sqlite-graph-memory[lite]", "sqlite-graph-memory"]
env = { BRAIN_INDEX_DIR = "/absolute/path/to/.sgm-index" }
Size, du -sh of a fresh Python 3.12 venv on an x86_64 Mac (1 Nov 2026): the base install is
26 MB and has no torch (numpy only, enough for the graph half and the SQLite ledger);
with [embeddings] (torch) it is 879 MB, 540 MB of that torch 2.2.2 CPU. With [lite],
the same two models on ONNX Runtime and no torch, it is 155 MB (Windows, Python 3.12,
3 Nov 2026), installs in 12 s, and one MCP recall on the 202-note bench vault took 7.0 s
against 33.8 s through torch on the same machine, with the same top hits and scores.
[lite] is picked automatically when installed; SGM_BACKEND=torch forces torch (for a GPU).
An index built by either backend is searched correctly by the other.
Already installed with pip? Replace uvx --python 3.12 --with ... sqlite-graph-memory by sgm-mcp
(examples/mcp-config.json). Agents that read files first:
llms.txt.
Three commands
pip install 'sqlite-graph-memory[lite]'
sgm-index ./notes
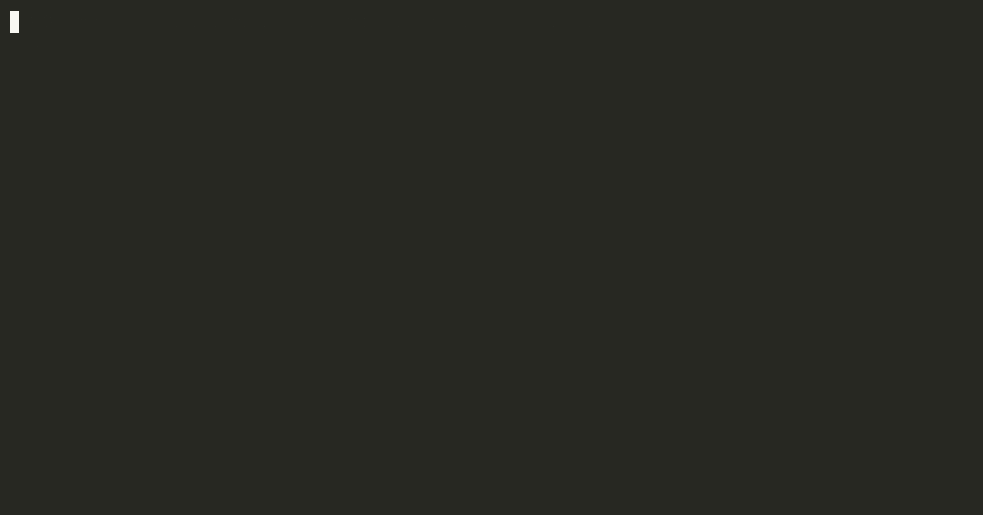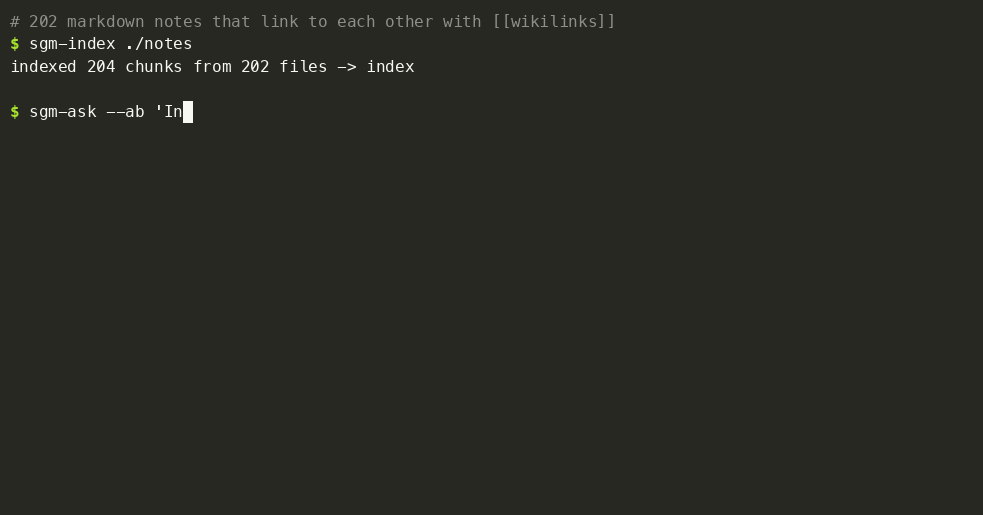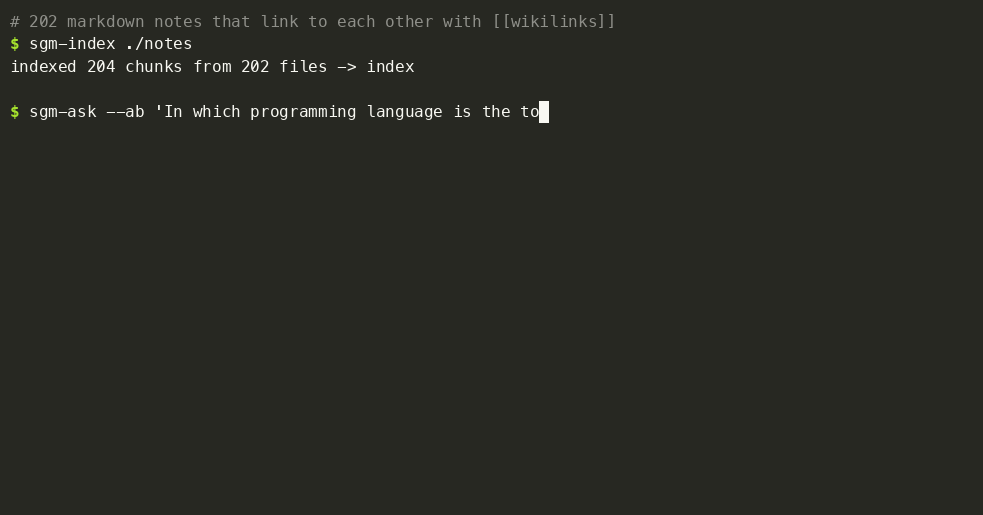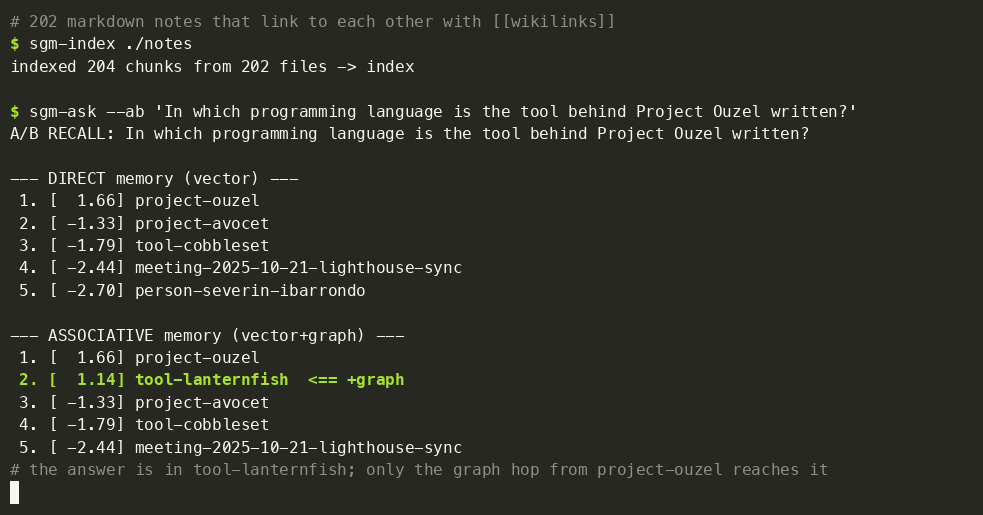
sgm-ask --ab "In which programming language is the tool behind Project Ouzel written?"
On an Intel Mac, use Python 3.12 with pip install. On a newer Python it can quietly install 0.3.5, which has no [lite].
./notes is any folder of markdown notes. Re-running sgm-index only re-embeds notes
that are new or changed since the last run (tracked by a manifest next to the index);
pass --full to force a complete rebuild.
To get exactly the output below, use the 202-note synthetic vault from this repo (it is not inside the pip package):
git clone --depth 1 https://github.com/tonydzi/sqlite-graph-memory && cp -R sqlite-graph-memory/bench/vault ./notes
Real output, top 5 of 12:
--- DIRECT memory (vector) ---
 1. [  1.66] project-ouzel
 2. [ -1.33] project-avocet
 3. [ -1.79] tool-cobbleset
 4. [ -2.44] meeting-2025-10-21-lighthouse-sync
 5. [ -2.70] person-severin-ibarrondo

--- ASSOCIATIVE memory (vector+graph) ---
 1. [  1.66] project-ouzel
 2. [  1.14] tool-lanternfish  <== +graph
 3. [ -1.33] project-avocet
 4. [ -1.79] tool-cobbleset
 5. [ -2.44] meeting-2025-10-21-lighthouse-sync
The answer lives in tool-lanternfish ("Lanternfish is written in Elixir"). The question
never names Lanternfish, so the vector pass does not find it in the top 12 at all.
project-ouzel links to it, so one graph hop puts it second.
If that hop found something your vector search missed, a
star is how other people with a notes
folder find this repo. sgm-ask --ab asks the same once per machine, in a terminal only;
SGM_NO_STAR_PROMPT=1 turns it off.
That is the idea in one query, and it is not a blanket win. On this same vault vector-only
ranks ahead of graph mode overall; the numbers are in bench/. --ab
exists so you can measure which one wins on your own notes.
What it is
Graph RAG on SQLite for AI agents — a working pilot, not a framework. It is the extracted
memory layer of a personal "second brain" agent setup: vector search finds the entry
points, the [[wikilinks]] you already wrote by hand are the graph, and dense similarity
orders what the hop dragged in (a cross-encoder rerank is opt-in with --rerank; see below
for why it is no longer the default).
SQLite is the only database (schema.sql).
Status: pilot, and the word is load-bearing: it runs daily in one real setup (an index of ~28k curated notes, ~93k chunks, rebuilt nightly from a ~270k-file
Obsidian vault driven by Claude Code), but it is deliberately minimal and makes no attempt
to be general — see What's intentionally missing, which is
where the uneven test coverage is described.
Published as the companion code for an upcoming write-up on lightweight Graph RAG for agents;
the one design note that is already written is docs/bitemporal.md.
Why
Most Graph RAG stacks assume a graph database, an ETL pipeline, and an entity-extraction pass — HippoRAG (arXiv:2405.14831) derives its KG that way, and Graphiti/Zep maintain a temporal one. For a single-user agent over a markdown knowledge base, all three are overkill:
- The graph already exists — Obsidian/Logseq/plain-markdown users hand-curate their
edges as
[[wikilinks]], andbrain_ask.pyjust parses them. No extraction pass, and edge quality beats anything a model would mine. - SQLite is enough — the only things worth persisting are derived state (a per-turn
ledger) and telemetry, and both are defined in
schema.sql. One file, stdlib driver, zero ops. The ledger is telemetry, not memory: recall never reads it, so past turns do not change whatbrain_ask.pyor the MCP server return. - Measure before adding a stage. The pilot shipped a cross-encoder reranker from day one;
measured later, it lowered recall on long queries (our 184-question gold set: body nDCG@12
0.640 reranked vs 0.815 dense; DolphinBench Riley slice, 1000 sessions: R@5 0.48 vs 0.61).
Since 0.3.7 it is off by default and stays available as
--rerank/SGM_RERANK=1.
So the pilot's bet: vector retrieval for entry points, hand-curated wikilinks for
association, SQLite for everything that must persist. All steps live in one file,
brain_ask.py, in that order.
Architecture
Three layers, three failure-isolated components:
markdown notes (with [[wikilinks]])
        │
        ├── index_notes.py      chunk + embed (e5-base) → .npy/.pkl index
        │
        ├── brain_ask.py        recall pipeline:
        │       1. dense retrieve  top-60 chunks, dedup by file
        │       2. --graph         +1-hop wikilink neighbours of top-15 hits (max 40)
        │       3. order           dense similarity → top-12
        │                          (--rerank: cross-encoder instead, opt-in)
        │       4. --ab            run vector-only AND vector+graph, diff,
        │                          log the delta to SQLite (ab_recall)
        │
        └── turnstate_hook.py   agent Stop-hook: after every assistant turn,
                                parse the transcript tail and append one row
                                (ask, summary, files, tools, commands, decisions)
                                to SQLite (turns). 0 LLM tokens, pure stdlib.
                                turnstate_show.py = read-only viewer.
                                Off the recall path: nothing in recall
                                reads this table.
schema.sql documents both tables. The graph is not materialized in SQL:
brain_ask.py parses edges from the notes at query time, bounded to 1 hop / 40 neighbours.
That keeps the graph permanently in sync with the notes at zero maintenance cost; materialize
an edge table only when hop depth or corpus size demands it.
Design choices that survived contact with reality
- Graph expansion is candidate generation, not ranking (
brain_ask.py). Neighbours go into the same ranking pool as vector hits, so an irrelevant linked note gets buried. That is what makes 1-hop expansion safe to leave on. - Entity gate (
looks_like_entityinbrain_ask.py). A/B telemetry showed graph expansion helps theme queries ("approaches to agent memory") but hurts name/tool lookups ("NotebookLM"): a name's card links to everything, so the hop pulls in noise. The heuristic inbrain_ask.pyis deliberately conservative, and switches the graph off only for name-shaped queries. - Crash-safety as a policy. The graph hop (
brain_ask.py) is wrapped, so a failure degrades recall to vector-only. The Stop-hook (turnstate_hook.py) is wrapped too, but it sits off the recall path: a failure costs one ledger row and nothing else. A memory layer must never make the agent worse than having no memory layer. - Measure, don't believe.
--abruns both pipelines on every real query and logs how many notes the graph promoted into the top-N, toab_recallinschema.sql. Whether "associative memory" earns its keep is a weekly SQL query, not a vibe.
What's intentionally missing
- No entity lane. The production setup has an extra retrieval lane over people/project cards; it is too entangled with personal data to publish.
- Packaging exists since v0.3.0 (
pip install sqlite-graph-memory). There IS an eval suite now — see Measure before you swap — but it scores retrieval on wikilink-derived gold, which is weak supervision and says so out loud. Test coverage is uneven:index_notes.py,brain_ask.pyandmcp_server.pyhave unit tests, andturnstate_hook.pyhas write-path coverage. Runpytest -qfor the current count rather than trusting a number written in prose here — that is how this file ended up claiming "no tests" while seven were passing. The status line above says pilot on purpose.
Quickstart
# Indexing and reranking need an embedding stack; the base install leaves it out.
# [lite] runs the models on ONNX Runtime without torch (~155 MB); [embeddings]
# brings torch (~2 GB) if you want a GPU. Ask for one explicitly:
pip install 'sqlite-graph-memory[lite]'

# 1. index a folder of markdown notes
sgm-index /path/to/notes

# 2. ask, three ways
sgm-ask "how do I think about agent memory"
sgm-ask --graph "how do I think about agent memory"
sgm-ask --ab    "how do I think about agent memory"   # logs the diff to SQLite

# 3. inspect the A/B telemetry
sqlite3 turnstate.db "select ts, query, new_in_top, promoted_via_graph from ab_recall order by id desc limit 10"
Run any of them on a base install and they tell you which extra is missing rather than
raising ModuleNotFoundError — that path is covered by tests/test_optional_extra.py.
To enable the per-turn ledger in Claude Code, register the Stop hook (the exact block is
examples/claude-code-stop-hook.json, which calls sgm-turnstate-hook), then read it back with
sgm-turnstate-show. The ledger records what each turn did; recall never reads it.
sgm-turnstate-show --stats
Working from a clone instead of an install? pip install -e '.[lite]' gives you the
same four commands, and the modules stay importable as
from sqlite_graph_memory import brain_ask.
Configuration is env-only and every variable is listed in .env.example; everything
defaults to the current directory. GPU is used automatically if a CUDA torch build is
present, and CPU works fine for small corpora.
What --ab looks like
Output of brain_ask.py with --ab, on a toy 4-note corpus (real runs use an index of ~28k notes / ~93k chunks):
A/B RECALL: how should agent memory work
(Direct=4 vector / Associative=+0 graph; Associative promoted 0 new notes into top-12, 0 of them via graph)

--- DIRECT memory (vector) ---
 1. [  4.11] agent-memory
 2. [ -6.50] graph-rag
 3. [ -8.66] sqlite-ledger
 4. [ -9.73] cooking

--- ASSOCIATIVE memory (vector+graph) ---
 1. [  4.11] agent-memory
 2. [ -6.50] graph-rag
 3. [ -8.66] sqlite-ledger
 4. [ -9.73] cooking
On a corpus this small the graph adds nothing — every note is already in the candidate
pool. The interesting deltas appear at scale, and that is exactly what the ab_recall
table in schema.sql accumulates evidence for.
Public benchmark — bench/
Every number in the next section comes from our private vault, so nobody outside the lab can
check it. bench/ is the reproducible half: a generated 202-note vault
about a fictional lab, 91 questions in seven classes (including 22 whose answer is not in
the vault), and three metrics that matter for agent memory: recall@k on the support notes,
verbatim citation, and abstaining when the fact is missing.
python bench/run.py --system bm25          # one command, stdlib only
python bench/validate.py                   # what CI runs on every result file
Our own baseline is on the leaderboard with its weak spots written out: on "what is the current deadline" questions it retrieves both decisions (R@5 1.00) and cites the superseded one 6 times out of 6; vector-only ranks ahead of graph mode on this vault (R@5 0.88 vs 0.85). Other memory systems (mem0, Letta, Khoj, plain RAG) can join the board with one adapter file and a pull request: bench/CONTRIBUTING.md. CI recomputes every submitted number from the per-question outputs, so a typed-in number cannot get onto the board.
Health check — sgm-stats
Four numbers about the link graph itself, no model and no index needed. It reads the notes with
the same filter and the same [[wikilink]] parser as recall, so it measures the graph --graph
actually walks. Thresholds follow second-brain-os metrics;
each is a --threshold-* flag. Exit code 0 ok, 1 warn, 2 fail, so it can sit in cron.
$ sgm-stats bench/vault --today 2026-10-20
202 pages in bench/vault

FAIL  orphan_rate       26.2%   53 of 202 pages have no inbound link
OK    avg_degree         4.65   940 resolved links over 202 pages
OK    main_component   100.0%   202 of 202 pages; 1 component
WARN  stale_concepts   100.0%   12 of 12 concept pages older than 90 days (as of 2026-10-20)
The synthetic bench vault fails the orphan check for a plain reason: its 40 meeting and 12 decision notes link out and nothing
links back to them. --json gives the same report with the first orphan and stale page names.
Measure before you swap — eval/
Every "obvious" upgrade to a RAG pipeline — a newer embedder, a stronger reranker, hybrid
BM25, a different chunker — is a hypothesis. Without a number on your corpus, swapping one
in is superstition with a changelog entry. eval/ is the smallest honest ruler we could
build, and it needs no labelling budget and no LLM calls: the wikilinks you already wrote
are the relevance labels.
python eval/run_eval.py --selftest                       # metrics only: no model, no index
python eval/build_gold.py /path/to/notes --n-per-class 60   # -> eval/gold-<today>.jsonl (freeze it)
python eval/run_eval.py --gold eval/gold-<today>.jsonl --sqlite
Four question classes, each probing a different part of the pipeline: title (a note's own
title should find it), body (its first paragraph should find it), bridge (its first
paragraph should surface the notes it [[links]] to — this is what the graph is for), and
temporal (an outdated note's title should surface its replacement, via a
superseded_by: "[[newer-note]]" frontmatter field). Every question is scored in both modes,
vector-only and vector+graph, so "does the graph help?" stops being a matter of taste.
run_eval.py imports brain_ask.py and calls the same functions the agent calls —
load_index, retrieve_candidates, expand_1hop, rerank_candidates — so what you measure
is what runs. An eval that re-implements the pipeline measures the re-implementation.
--sqlite appends one row per class and mode to a gold_eval table, which is how a run six
weeks from now can be diffed against today's.
Sweeping the graph-expansion knobs — eval/run_ablation.py
run_eval.py scores one configuration at a time (vector vs graph). run_ablation.py
sweeps a grid of pipeline parameters — whether the 1-hop graph expansion runs at all
(hops), how many top hits seed it (ghops), how many neighbours it admits (gmax), the
dense-retrieve pool size (topk), and whether entity/name-shaped queries skip the hop
(entity_gate) — against the same gold file, in one run, reusing brain_ask.py and
run_eval.py's own metrics so the sweep can't drift from what sgm-ask actually does:
python eval/run_ablation.py --list-grid                        # cells only, no model/index load
python eval/run_ablation.py --gold eval/gold-<today>.jsonl      # the built-in 10-cell default grid
Each dense embedding is computed once per question and reused across every cell (a cell's
candidate pool is a slice of the widest pool asked for, not a re-retrieve); only the
cross-encoder rerank runs per (question, cell), since the candidate set changes per cell.
The report — printed as a Markdown table and written as both <prefix>.md and <prefix>.csv
(--out <prefix>, or --csv/--md directly) — breaks down n, Recall@12, MRR, nDCG@12
and delta_nDCG@12 (vs the grid's 0-hop baseline) per (cell, class) and overall, and
warns explicitly whenever a class has fewer than 20 questions. The built-in default
10-cell grid varies one axis at a time against 1-hop (ghops=15, gmax=40, topk=60, entity_gate=on) rather than a full Cartesian product; --grid takes default, a
';'-separated key=val cell list (e.g. --grid "hops=0;hops=1,ghops=30,gmax=80" to test
multi-axis interactions), or a JSON array of cell dicts.
Sample run (intfloat/multilingual-e5-base + cross-encoder/mmarco-mMiniLMv2-L12-H384-v1 on CPU) over a 5-note synthetic mini-vault (12 questions: 5 title, 5 body, 1 bridge, 1 temporal) with --grid "hops=0,topk=3;hops=1,ghops=2,gmax=5,topk=3,entity_gate=on;hops=1,ghops=2,gmax=5,topk=3,entity_gate=off":
| cell | class | n | Recall@12 | MRR | nDCG@12 | delta_nDCG@12 |
|---|---|---|---|---|---|---|
cell-0 (hops=0, topk=3) |
bridge | 1 | 0.500 | 0.500 | 0.387 | +0.000 |
cell-0 (hops=0, topk=3) |
overall | 12 | 0.958 | 0.903 | 0.907 | +0.000 |
cell-1 (hops=1, ghops=2, gmax=5, topk=3, gate=on) |
bridge | 1 | 1.000 | 0.500 | 0.693 | +0.307 |
cell-1 (hops=1, ghops=2, gmax=5, topk=3, gate=on) |
overall | 12 | 1.000 | 0.903 | 0.933 | +0.026 |
cell-2 (hops=1, ghops=2, gmax=5, topk=3, gate=off) |
bridge | 1 | 1.000 | 0.500 | 0.693 | +0.307 |
cell-2 (hops=1, ghops=2, gmax=5, topk=3, gate=off) |
overall | 12 | 1.000 | 0.903 | 0.933 | +0.026 |
When topk is smaller than the vault (topk=3 < 5 notes), 1-hop [[wikilink]] expansion (cell-1, cell-2) lifts bridge Recall@12 from 0.500 to 1.000 (+0.307 nDCG@12, +0.026 overall) without regressing title, body, or temporal. On the default 10-cell grid (topk=20..80 > 5 notes), every cell scores identically (overall Recall@12 1.000, nDCG@12 0.929, delta_nDCG@12 = +0.000) because dense retrieval already admits the entire mini-vault before the graph hop runs.
sqlite-graph-memory MCP questions
How do I add sqlite-graph-memory MCP to Claude Code?
Run claude mcp add --env BRAIN_INDEX_DIR=<BRAIN_INDEX_DIR> sqlite-graph-memory -- uvx sqlite-graph-memory in your terminal. Add --scope user to make it available in every project.
How do I add sqlite-graph-memory MCP to Cursor?
Open ~/.cursor/mcp.json and add the server under mcpServers, using the Cursor config shown in the install section above.
How does it handle graph connections?
It uses existing [[wikilinks]] in your markdown notes as the graph edges, performing a 1-hop expansion to find related notes.
Does it require a separate graph database?
No, it uses a single SQLite file for persistence and parses edges from your notes at query time.
Can I use it with Obsidian?
Yes, it works with any folder of markdown files, including Obsidian vaults.
What is the difference between the lite and full versions?
The lite version uses ONNX Runtime and is significantly smaller (approx 155 MB) compared to the version using torch (approx 879 MB).