
Memstem MCP server
Commit Oct 29, 2026Provides a unified memory and skill infrastructure for AI agents by pulling knowledge from connected filesystems into a searchable hybrid index.
Also known as Memstem/memstem
- Stars
- 5
- Tools
- —
- Downloads, 30 days
- —
- Latest version
- —
- Last commit
- Oct 29, 2026
- License
- MIT
What is Memstem MCP?
Memstem provides a unified memory and skill infrastructure for AI agents by pulling knowledge from connected filesystems into a searchable hybrid index.
Summary generated from the project's README
About Memstem MCP server
Memstem provides a centralized memory and skill infrastructure designed for AI agents to share knowledge across different environments. Instead of requiring agents to push data to a central store, this service uses a pull-based approach by watching the filesystems of connected clients like Claude Code, OpenClaw, and Codex. This method ensures that memory remains intact even when the host AI tools undergo version updates or upgrades.
The system maintains a markdown-canonical vault and builds a searchable index using a hybrid search strategy that combines BM25 and cosine similarity. Developers can use it locally via stdio or through a local HTTP API. It supports various embedding providers including Ollama for local setups, or cloud options like OpenAI, Gemini, and Voyage. The server includes a hygiene loop that automatically distills sessions and builds project records to improve retrieval quality.
Users interact with the service through five specific MCP tools: memstem_search, _get, _list_skills, _get_skill, and _upsert. The architecture is built to be resilient, featuring an always-on embed queue and optional cross-encoder reranking to ensure high-quality results.
What you can do with it
- 1Sync knowledge across multiple AI agentsA developer can use Memstem to ensure that information learned in Claude Code is immediately available to an OpenClaw session.
- 2Perform advanced hybrid searchesAn AI client can query the memory using both keyword matching and vector similarity to find specific technical details.
- 3Automate memory organization and distillationThe system can automatically summarize long chat sessions into concise records to make them easier to retrieve later.
- 4Maintain a local private memory stackDevelopers can run a completely self-hosted setup using Ollama to avoid sending data to cloud providers.
Written from the project's README. Every use case is checked against a quote from it.
README
View on GitHubMemstem


Unified memory and skill infrastructure for AI agents. One canonical knowledge store. Many AI clients. No version-fragility.
A central memory with stems reaching out to other systems, drawing their memories in.
If memstem helps you, please ⭐ the repo — there's no telemetry here, so stars are the only signal I have for whether to keep building this in the open.
What it is
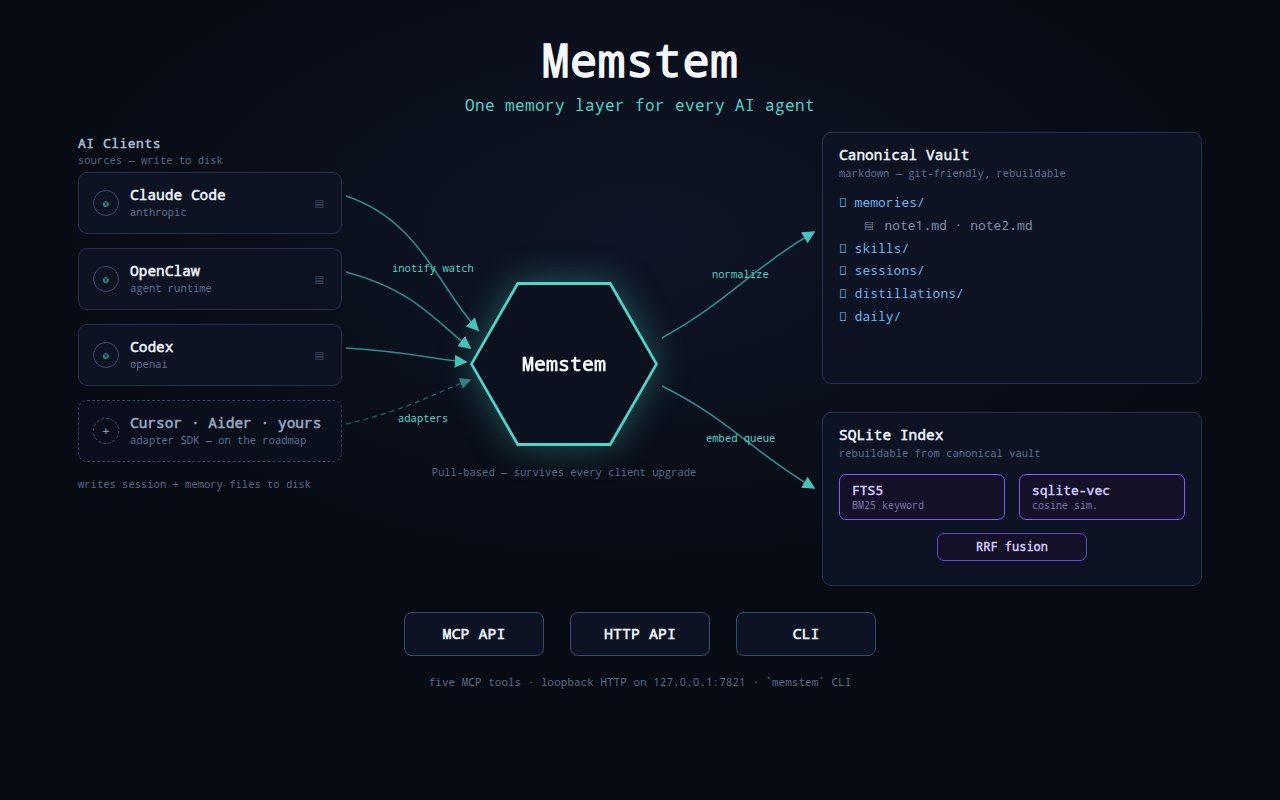
Memstem is a standalone memory service that acts as the single source of truth for memories and skills shared across multiple AI environments. Unlike traditional memory layers that you push to from each AI, Memstem pulls from the filesystem of each connected AI — so it's immune to upgrade churn in any of them.
Connect Claude Code, OpenClaw, Codex, and OpenCode (including Pocket OpenRouter sessions) — adapters for Cursor, Aider, and more are on the roadmap. Memstem watches each system's session and memory files, ingests new content within seconds, and exposes one unified search API via MCP.
Why
Existing AI memory systems break when their host upgrades. Push-based hooks fail silently across version changes. Each AI has its own memory format, and there's no clean way to share knowledge across them.
Memstem solves this by:
- Pull-based ingestion via
inotify/ FSEvents filesystem watchers — no hooks, no push APIs to break - Markdown-canonical storage — files are the truth, the index is rebuildable
- Hybrid search — BM25 (FTS5) + cosine similarity (sqlite-vec) + reciprocal rank fusion
- Multi-AI adapters — pluggable per-system ingestion (Claude Code, OpenClaw, Codex, etc.)
- MCP-native API — every modern AI agent can call it
Architecture (one paragraph)
Markdown files in a structured tree are the canonical store. A SQLite database with FTS5 and sqlite-vec is the rebuildable index. A daemon watches each connected AI's filesystem and ingests deltas. An MCP server exposes search, get, and skill retrieval to clients. A hygiene loop runs inside the daemon — distilling sessions (and re-distilling them as they grow), scoring importance, building project records, and compacting the vector table on configurable intervals.
See ARCHITECTURE.md for the full design and ROADMAP.md for the phase plan.
Status
v0.20.0 — actively developed, running in production.
Live on the maintainer's infrastructure, ingesting from multi-agent
OpenClaw, Claude Code, and Codex in real time. The 0.13 line added the
recall-quality stack (cross-encoder reranking + MMR, multimodal
embeddings, a validated fully self-hosted Qwen3 recall setup); 0.14
through 0.16 were three reliability batches from a full-codebase
review — durability, concurrency, failure visibility, embed-queue
claim/lease, and dedup-judge correctness. 0.17 added security hardening
(request-edge clamps, reserved _-path rejection, optional HTTP
bearer-token auth) and the first publication to PyPI; 0.18 adds
source-deletion tombstones — deleting an authored source file in a
connected agent's workspace removes its memory from search (ADR 0026).
0.19 is an embedder-resilience line — query timeouts + circuit breaker
(ADR 0030), cold-path key self-heal (ADR 0031), surfaced search
degradation (ADR 0032), correct daily-log vault paths (ADR 0033) — and
removes the LLM-judge dedup service (ADR 0028); 0.19.1 pins mcp<2
(0.19.0 installs broken with the MCP SDK's 2.0 release); 0.20 completes
the move to MCP SDK v2 (MCPServer) — same tools, both protocol eras
served over stdio, hardened against stray-stdout corruption.
See CHANGELOG.md for the release-by-release history.
Shipping:
- Hybrid search (FTS5 BM25 + sqlite-vec cosine, merged with RRF) over a markdown-canonical vault. Index is rebuildable from the files.
- Five MCP tools (
memstem_search,_get,_list_skills,_get_skill,_upsert) plus a co-hosted local HTTP API on127.0.0.1:7821for first-party clients (CLI tools, future editor extensions), with optional bearer-token auth for non-loopback deployments. - Pluggable embedders — Ollama (local default), OpenAI, Gemini, Voyage, or
any OpenAI-compatible server — selectable via
_meta/config.yaml. For a self-hosted, no-cloud setup the recommended embedder is Qwen3-Embedding-8B (4096-dim, instruction-tuned); see Embedding provider. Always-on embed queue with retry/backoff and idle-timeout self-exit. - Cross-encoder reranking + MMR — opt-in recall-quality
pass that re-orders hybrid-search candidates with an LLM reranker and
diversifies near-duplicates with MMR, wired into config, the daemon, MCP, and
CLI (
--rerank,--mmr,--rerank-top-n). Off by default; pair it with a self-hosted Gemma/Qwen reranker for zero per-query cloud cost. See Search & reranking. - Derived records —
memstem hygiene distill-sessionsproducestype: distillationcompanion records for meaningful sessions, andmemstem hygiene project-recordsaggregates per-project-tag sessions intotype: projectrollups. Both are CLI-driven, idempotent, opt-in (NoOp default; pluggable OpenAI / Ollama summarizer). Direct fix for "the project where we did X" queries that today fail to surface project work that exists in the vault. See docs/distillation-verification.md. - In-daemon hygiene loop —
memstem daemonruns the three hygiene stages (distill-sessions, importance, project-records) as background tasks alongside the watchers and embed workers, each on its own configurable interval with per-stage locking and failure isolation.GET /healthexposes per-stagelast_runtimestamps for fleet monitoring; setloop_enabled: falseon multi-tenant hosts where the customer hasn't authorized LLM spend. See ADR 0023. - OpenAI-compatible LLM backends for hygiene — the
summarizer speaks the OpenAI chat-completions protocol,
so distillation and project-records can run against a
self-hosted vLLM / TGI / LM Studio / LiteLLM endpoint via a
base_urloverride — no per-customer cloud billing. The audit log and provenance honestly label which service produced each verdict (openai:gpt-…for OpenAI Inc.,openai-compat:gemma-…for a self-hosted endpoint). - Codex adapter — third filesystem adapter (after
Claude Code and OpenClaw), watching
~/.codex/sessions|skills|memories; enabled by default and no-ops silently on hosts without Codex. Codex sessions group by project tag alongside Claude Code's. See ADR 0022. - Source-deletion tombstones — deleting an authored source file
(
memory,skill, ordailylog) in a connected agent's workspace removes the corresponding memory from search. A reconcile-time source-liveness sweep sets adeleted_atmarker (filtered from search likevalid_to/deprecated_by, and recoverable viainclude_deleted), cleared automatically if the source is restored. Session logs and generated records (distillations, project rollups) are never affected, and a vanished workspace mount is skipped rather than mass-tombstoned. See ADR 0026. - Security hardening — request-edge size/value clamps, rejection of
reserved
_-prefixed vault paths, optional HTTP bearer-token auth for non-loopback deployments, and Gemini API keys sent via request header rather than query string. - Post-cleanup operator workflow —
memstem hygiene verifyis a single read-only command that summarizes vault state after a cleanup + backfill sweep: per-type counts, distillation coverage, undistilled-eligible sessions remaining, dedup / noise findings cleanup-retro would still flag, open skill review tickets, and parser/validation skips. Optional--json-outemits a machine-readable payload for CI / monitoring. Replaces ad-hoc SQLite inspection. See the post-cleanup playbook in docs/operations.md. - Explicit ranking policy —
SearchConfig.type_biasmultiplies each result's score by a small per-type weight so default search clearly prefers curated/derived records (distillation 1.10, memory/skill/project 1.05) over raw conversational sessions (0.85). Bounds are intentionally tight ([0.85, 1.10]) — the bias breaks ties without overriding relevance. Tunable per-vault in_meta/config.yaml; an empty mapping recovers pre-0.10 behaviour. - Quality pipeline — write-time noise filter, exact-body hash dedup (Layer 1), TTL tagging for transient kinds, boot-echo hash filter — keeps the vault from being polluted by AI-session firehose.
memstem authfor persistent embedder API keys (~/.config/memstem/secrets.yaml, mode 0600), so cron, PM2, systemd, and headless servers don't need per-shell exports.- Secret handling (architecture and policy locked, implementation
in phases). Memstem is being extended with a
SecretBackendinterface, agent-sidevault.put/vault.gettools, system-prompt guidance, and an ingest-time regex pack that redacts known-format secrets to vault placeholders before they enter the index. Scope and limits are documented up front so customers know what Memstem will and will not commit to — it is not a guaranteed secret scanner. See docs/secrets.md for the full responsibility boundary and shipping-status table. - Operational tooling —
memstem init,doctor,connect-clients(idempotent wiring into~/.claude.jsonand each OpenClaw agent'sopenclaw.json),migrate(FlipClaw → Memstem one-shot), a one-lineinstall.sh, and a 15-second e2e smoke test (scripts/e2e-smoke.sh).
CI runs on Linux — the supported platform. macOS installs work with a Homebrew or pyenv Python (see docs/install.md) but aren't CI-gated; native Windows is not supported (use WSL2). 1,400+ tests passing. See ROADMAP.md for what's next.
Quickstart
The full one-liner. Installs everything (memstem, Ollama, embedding model), scaffolds the vault, imports your existing Claude Code + OpenClaw memory, wires Memstem into Claude Code, and starts the daemon under PM2:
curl -fsSL https://raw.githubusercontent.com/Memstem/memstem/main/scripts/install.sh | bash -s -- \
  --yes --connect-clients --migrate --migrate-no-embed --start-daemon
The default uses Ollama (local, no API key, no network call). To install with a cloud embedder in one go:
# OpenAI (text-embedding-3-large at 3072 dimensions)
curl -fsSL https://raw.githubusercontent.com/Memstem/memstem/main/scripts/install.sh | bash -s -- \
  --yes --embedder openai --openai-key "$OPENAI_API_KEY" \
  --connect-clients --migrate --start-daemon

# Or Voyage / Gemini — same shape:
#   --embedder voyage --voyage-key "$VOYAGE_API_KEY"
#   --embedder gemini --gemini-key "$GEMINI_API_KEY"
Picking --embedder openai|gemini|voyage implies --no-ollama (cloud doesn't need a local daemon). The key gets stored via memstem auth set <provider>, so cron, PM2, and fresh shells all pick it up afterward without per-shell exports.
The --migrate-no-embed flag is the practical default on a CPU-only Ollama box: it imports records to vault + FTS5 in minutes instead of hours. After it returns:
memstem search "what did we decide about pricing"   # FTS5 hits work immediately
pm2 logs memstem --lines 20                          # watch ingestion + embed worker
memstem doctor                                       # `Embed queue: N pending` shows backfill progress
Embedding is always queued rather than inline (see ADR 0009): the migrate finishes in seconds and the daemon's embed worker drains the queue at its own pace. On CPU-only Ollama that means semantic search becomes "good" over an hour or two; on the API providers above it's done in seconds.
Manual install if you'd rather not pipe a script:
pipx install memstem                         # or: pip install memstem
ollama pull nomic-embed-text                 # 768-dim local embedder
memstem init ~/memstem-vault                 # interactive wizard
memstem migrate --apply                      # one-shot history import
memstem connect-clients                      # patch settings + CLAUDE.md
memstem doctor                               # verify
memstem daemon                               # ingest + watch
On macOS, use a Homebrew or pyenv Python — the system Python ships a SQLite that can't load the sqlite-vec extension.
The full install reference — every installer flag, API-key handling, the macOS detail, and exactly what connect-clients edits — is in docs/install.md.
Querying from an agent
Once memstem connect-clients has run, an MCP-aware client (Claude Code, etc.) sees five tools:
| Tool | Purpose |
|---|---|
memstem_search |
Hybrid (FTS5 + vector) search across the vault |
memstem_get |
Fetch a memory by id or vault path |
memstem_list_skills |
List skills, optionally filtered by scope |
memstem_get_skill |
Fetch a skill by title |
memstem_upsert |
Create or update a memory record |
See docs/mcp-api.md for the full schema.
Read-only mode. memstem mcp --read-only serves the first four tools only: memstem_upsert is not registered, the index is opened read-only, and the server writes nothing (no query log, no importance signal, no caches). It is safe beside a running daemon, and meant for letting another person's or agent's MCP client search a vault it must never change, for example command="memstem mcp --read-only" as an SSH forced command. See Read-only mode.
Every search runs in parallel down two paths and is merged with Reciprocal Rank Fusion, so exact-keyword hits and semantic neighbours both surface in one ranked list:
Configuration
~/memstem-vault/_meta/config.yaml controls embedding, search, and adapters. The wizard writes a sensible default; common edits:
Embedding provider — pick one
Memstem ships several providers. Default is local Ollama (zero-config, no API key). For a high-quality self-hosted setup with no cloud API, the recommended embedder is Qwen3-Embedding-8B (see the self-hosted block below). Switch by editing the embedding: block (then memstem reindex so existing vectors get redone against the new provider).
# Default — local, no API key
embedding:
  provider: ollama
  model: nomic-embed-text
  dimensions: 768
# Google Gemini — Matryoshka shortening lets you keep any dim you want
# (768 = same as Ollama, no reindex when switching from Ollama default).
embedding:
  provider: gemini
  model: gemini-embedding-2-preview     # default; ~20% recall over -001, 8k context
  api_key_env: GOOGLE_API_KEY
  dimensions: 768            # 768 / 1536 / 3072 — Matryoshka truncates the native 3072d
Pin model: gemini-embedding-001 if you'd rather have the production-stable predecessor (the "preview" label means Google may change behavior; new-RAG quality vs API stability is your call).
# OpenAI — or any OpenAI-compatible endpoint (Together, Mistral, Groq, vLLM, LM Studio)
embedding:
  provider: openai
  model: text-embedding-3-small
  api_key_env: OPENAI_API_KEY
  dimensions: 1536
  # base_url: https://api.together.xyz/v1   # for OpenAI-compatible providers
# Voyage — Anthropic's recommended embedding partner; tops retrieval benchmarks
embedding:
  provider: voyage
  model: voyage-3
  api_key_env: VOYAGE_API_KEY
  dimensions: 1024
# Recommended self-hosted (no cloud API) — Qwen3-Embedding-8B on vLLM.
# Instruction-tuned 4096-dim retriever, served over the OpenAI-compatible path
# (point base_url at your own server). Pair with the query_instruction below and
# a self-hosted reranker (see "Search & reranking") for the full no-cloud stack.
embedding:
  provider: openai                       # OpenAI-compatible client
  model: qwen3-text-embed                # the name your vLLM serves
  base_url: http://your-vllm-host:8000/v1
  api_key_env: OPENAI_API_KEY            # any non-empty token; vLLM ignores it
  dimensions: 4096
  query_instruction: "Given a search query, retrieve relevant memories, notes, and documents that answer it"
API keys are read from environment variables named in api_key_env — they never land in the vault. embedding.workers (default 2) and embedding.batch_size (default 8) tune the queue throughput; CPU Ollama is happiest at 1 worker, API providers tolerate 4+.
Search & reranking (recall quality)
Hybrid search (BM25 + vector, merged with RRF) works out of the box. For higher precision, enable the reranker + MMR pass: it re-orders the top candidates with an LLM and diversifies near-duplicates. Off by default — opt in per vault:
search:
  mmr_lambda: 0.5            # 0 = max diversity, 1 = pure relevance
  rerank_top_n: 15           # candidate pool the reranker re-scores
  reranker:
    enabled: true
    provider: openai         # OpenAI-compatible — also works against a self-hosted vLLM box
    model: gemma-4-e4b-it    # or gpt-4o-mini, qwen2.5:7b, ...
    base_url: http://your-vllm-host:8000/v1
    api_key_env: OPENAI_API_KEY
Per-query overrides: memstem search "q" --rerank --mmr 0.5 --rerank-top-n 15
(and --no-rerank to skip). Together with the Qwen3 embedder + query_instruction
above, this is the validated fully self-hosted recall stack — no per-query cloud
cost. For picking the reranker LLM, see
recall-quality model recommendations.
Adapters
embedding:
  provider: ollama
  model: nomic-embed-text
  base_url: http://localhost:11434
  dimensions: 768

adapters:
  openclaw:
    agent_workspaces:
      - { path: ~/assistant, tag: assistant }
      - { path: ~/support-agent, tag: support }
    shared_files:
      - ~/assistant/RULES.md
  claude_code:
    project_roots:
      - ~/.claude/projects
    extra_files:
      - ~/.claude/CLAUDE.md
    # skills_root: ~/.claude/skills   # default; user skills are indexed (ADR 0051)
    # ingest_skills: true
Run memstem doctor after edits to verify every configured target exists and the embedder is reachable.
What a session record holds (and what it does not)
A type: session record is the conversation, not the transcript. Each
adapter keeps the user and assistant text and reduces everything else to a
marker or drops it:
| Source | Kept | Reduced to a marker | Dropped |
|---|---|---|---|
| Claude Code | user + assistant text | [tool_use: <name>], [tool_result] |
tool arguments, command output, file contents, diffs, images |
| Codex | user + assistant text | [function_call: <name>], [function_call_output] |
reasoning, developer/permissions boilerplate, environment stubs |
| OpenClaw | text blocks | — | tool_use, tool_result, thinking blocks (no marker) |
Uploaded or pasted images leave no trace unless the assistant described them in its reply. Distillations and project records are derived from these session records, so they cannot recover tool output either.
The practical consequence: Memstem is not a transcript archive. It keeps a session record even after its source file is deleted (the record is tombstoned, not removed — see ADR 0026), but it can never re-derive the commands, results, or pictures that were only in the raw transcript. If you want the full record, archive the transcripts rather than deleting them; if you only want the conversation to be searchable, Memstem already has it.
Distillation + project records
Two hygiene commands turn raw session transcripts and per-project session sets into retrieval-shaped derived records. Both are CLI-driven, idempotent, and opt-in — NoOp is the install-time default, you opt into a real summarizer explicitly.
# One-shot backfill at cutover (or any time you want to refresh):
memstem auth set openai sk-...
memstem hygiene distill-sessions --backfill --provider openai --apply
memstem hygiene project-records --provider openai --apply

# Routine refresh (post-backfill):
memstem hygiene distill-sessions --provider openai --apply
memstem hygiene project-records --provider openai --apply
What you get:
- Session distillations at
vault/distillations/<source>/<session_id>.md— one paragraph + structured Key entities / Deliverables / Decisions / Status sections per session. Provenance always points back to the source transcript, and records a snapshot of its size — when a session later outgrows that snapshot by 500+ words or 10+ turns (a long-running or reopened session), the default scan re-distills it in place so the summary follows the transcript (ADR 0037;--no-refresh-staledisables,--min-new-words/--min-new-turnstune the gate). - Project records at
vault/memories/projects/<slug>.md— one per Claude Code project tag with ≥2 sessions. Canonical project name extracted from the work itself, accumulated decisions, link map.
Both can also run with Ollama (--provider ollama, default model
qwen2.5:7b) for local-only setups. See
docs/distillation-verification.md
for the full operator workflow (dry-run, quality spot-check, eval
diff, manual override) and
docs/recall-models.md for the model
recommendations + cost expectations.
Memstem MCP questions
How does Memstem ingest data from AI clients?
It uses pull-based ingestion via filesystem watchers like inotify and FSEvents, making it immune to version changes in the host AI.
What kind of search capabilities does it offer?
It features hybrid search combining BM25 (FTS5) and cosine similarity (sqlite-vec) with reciprocal rank fusion.
Can I run Memstem without using cloud services?
Yes, you can use a self-hosted setup with Ollama as the default local embedder.