
すべての数値を特定のデータベースのソース行まで追跡することで、財務およびERPデータにおけるAIのハルシネーションを防ぎます。
別名 brick-byte/footnote, @brick-byte/footnote
- スター
- 0
- ツール
- —
- ダウンロード数(30日間)
- 819
- 最新バージョン
- 0.2.0
- 最終コミット
- 2026年11月4日
- ライセンス
- MIT
footnote MCPとは
すべての数値を特定のデータベースのソース行まで追跡することで、財務およびERPデータにおけるAIのハルシネーションを防ぎます。
プロジェクトのREADMEから生成された概要
footnote MCP server について
ERPデータを扱う財務アナリストや開発者は、footnoteを使用することで、すべての数値を特定のデータベース行まで追跡し、AIのハルシネーションを防ぐことができます。言語モデルに数値を生成させるのではなく、このサーバーは決定論的なコアを使用します。モデルは型定義された操作カタログから選択を行い、集計はすべてSQLが担当します。これにより、モデルが数値を捏造するのではなく、信頼できるシステムから値がそのままコピーされることが保証されます。
このサーバーはMCP serverとプロベナンスストアの両方の機能を備えており、ERPデータベースへの読み取り専用接続と、監査証跡用の別個の追記専用データベースを必要とします。Claude Desktop、Cursor、LangChainなどのクライアントと互換性があります。データの整合性を維持するため、サーバー側で書き込まれる改ざん防止用のハッシュチェーン構造を持つプロベナンスログを強制します。これにより、モデルが監査証跡に影響を与えることはできません。この構成により、クリック可能な引用とエクスポート可能な証拠を監査人に提供できるため、高い正確性が求められる調達や在庫管理の環境に適しています。
できること
- 1財務情報の検証監査人はAIの回答に含まれる金額をクリックして、その合計を算出した正確な請求書レコードを確認できます。
- 2顧客データの捏造防止モデルが存在しないクライアントを照会しようとした場合、サーバーはモデルに話を捏造させるのではなく、実在する代替案を含む復旧可能なエラーを返します。
- 3AIの推論の監査AIがリスクに関する判断を下した際、サーバーはその結論を個別に引用された検証可能な事実へと分解します。
- 4データ整合性の確保開発者は検証コマンドを実行して、過去の監査ログが改ざんされていないことを確認できます。
プロジェクトの README から作成されています。すべてのユースケースは、その引用と照らし合わせて確認されています。
footnote MCPのインストール方法
フォーマット検証日 2026年11月10日Cursor に追加Gooseに追加Claude Codeにfootnote MCPをインストール
$ claude mcp add --env 'DATABASE_URL=<YOUR_DATABASE_URL>' footnote -- npx -y @brick-byte/footnoteCursorにfootnote MCPをインストール
~/.cursor/mcp.json
{
  "mcpServers": {
    "footnote": {
      "command": "npx",
      "args": [
        "-y",
        "@brick-byte/footnote"
      ],
      "env": {
        "DATABASE_URL": "<YOUR_DATABASE_URL>"
      }
    }
  }
}VS Codeにfootnote MCPをインストール
.vscode/mcp.json
{
  "servers": {
    "footnote": {
      "type": "stdio",
      "command": "npx",
      "args": [
        "-y",
        "@brick-byte/footnote"
      ],
      "env": {
        "DATABASE_URL": "<YOUR_DATABASE_URL>"
      }
    }
  }
}VS Code CLIにfootnote MCPをインストール
$ code --add-mcp '{"name":"footnote","type":"stdio","command":"npx","args":["-y","@brick-byte/footnote"],"env":{"DATABASE_URL":"<YOUR_DATABASE_URL>"}}'Claude Desktopにfootnote MCPをインストール
claude_desktop_config.json
{
  "mcpServers": {
    "footnote": {
      "command": "npx",
      "args": [
        "-y",
        "@brick-byte/footnote"
      ],
      "env": {
        "DATABASE_URL": "<YOUR_DATABASE_URL>"
      }
    }
  }
}Codexにfootnote MCPをインストール
$ codex mcp add footnote --env 'DATABASE_URL=<YOUR_DATABASE_URL>' -- npx -y @brick-byte/footnoteCodex config.tomlにfootnote MCPをインストール
~/.codex/config.toml
[mcp_servers.footnote]
command = "npx"
args = ["-y", "@brick-byte/footnote"]

[mcp_servers.footnote.env]
DATABASE_URL = "<YOUR_DATABASE_URL>"
Gemini CLIにfootnote MCPをインストール
$ gemini mcp add -s user -e 'DATABASE_URL=<YOUR_DATABASE_URL>' footnote npx -- -y @brick-byte/footnoteGemini settings.jsonにfootnote MCPをインストール
~/.gemini/settings.json
{
  "mcpServers": {
    "footnote": {
      "command": "npx",
      "args": [
        "-y",
        "@brick-byte/footnote"
      ],
      "env": {
        "DATABASE_URL": "<YOUR_DATABASE_URL>"
      }
    }
  }
}設定
DATABASE_URLシークレットPostgres connection string. Omit to use the built-in SQLite sample database.
PROVENANCE_ACTORIdentity recorded against each provenance record. In production this comes from the request's auth.
PROVENANCE_DBPath to the SQLite provenance log. Defaults to in-memory, which discards the trail on exit.
| 名前 | 説明 | 種類 |
|---|---|---|
| DATABASE_URL | Postgres connection string. Omit to use the built-in SQLite sample database. | シークレット |
| PROVENANCE_ACTOR | Identity recorded against each provenance record. In production this comes from the request's auth. | |
| PROVENANCE_DB | Path to the SQLite provenance log. Defaults to in-memory, which discards the trail on exit. |
自動チェック
実行日 2026年11月14日完全なレポート →自動チェックに合格しました。これはセキュリティ監査ではありません。コードを読み、サーバーに必要最小限のアクセス権を与えてください。 チェックの仕組み

- ソースリポジトリがリンクされており、アクセス可能brick-byte/footnote is public and reachablegithub.com/brick-byte/footnote ↗合格
- パッケージがこのリポジトリをソースとして指定@brick-byte/footnote names brick-byte/footnote as sourcenpmjs.com/package/@brick-byte/footnote ↗合格
- ビルドの来歴 (Sigstore 証明)No build attestation published for this release未チェック
- オープンソースライセンス (OSI)MITspdx.org/licenses/MIT.html ↗合格
- 過去1年以内にコミットまたはリリースありLast commit or release 2026-11-05github.com/brick-byte/footnote ↗合格
- OpenSSF Scorecard未チェック
- パッケージ名が有名なパッケージに酷似していないNo popular package one edit away from @brick-byte/footnote合格
- パッケージおよびその依存関係に重大な勧告なし113 resolved dependencies checked; no critical advisoryosv.dev ↗合格
- モデルへの隠れた指示がない0 tool descriptions and the README read; no override phrases, credential paths or hidden characters合格
- 破壊的なツールがラベル付けされている未チェック
- リモートエンドポイントが MCP ハンドシェイクに応答未チェック
README
GitHubで見るFootnote

An MCP server that prevents hallucinated numbers when AI answers questions over ERP and finance data. Every figure in an answer traces back to the database rows that produced it: clickable at read time, exportable for an auditor, and tamper-evident.
Works with any MCP client: Claude Desktop, Cursor, Microsoft Agent Framework, Semantic Kernel (.NET), LangChain, or your own loop.
An MCP server, a provenance store, and a demo UI showing what the combination looks like.
The quickest way to try it:
// claude_desktop_config.json — sample data, nothing to install
{ "mcpServers": {
    "footnote": {
      "command": "npx",
      "args": ["-y", "@brick-byte/footnote"],
      "env": { "PROVENANCE_ACTOR": "your-name" }
    } } }
Against your own database it reads from two, never one — the ERP read-only, the audit trail somewhere you own. Run footnote check first; see Connecting to an existing database.
{ "mcpServers": {
    "footnote": {
      "command": "npx",
      "args": ["-y", "@brick-byte/footnote"],
      "env": {
        // Read-only role. Footnote never writes here and never migrates it.
        "DATABASE_URL": "postgres://footnote_ro:pass@host:5432/erp",
        // The append-only provenance log, deliberately a separate database.
        "PROVENANCE_DB": "/path/to/footnote-provenance.db",
        "PROVENANCE_ACTOR": "your-name"
      }
    } } }
Or run the demo UI locally:
npm install
npm run demo      # http://localhost:4711
npm test          # 30 tests, including the invariants below
Node 22.5+ required (uses the built-in node:sqlite, so there is no database to install).
Postgres is opt-in. The same schema, seed and query set run against it, and the same suite has to pass on both:
npm run db:up     # Postgres 17 in Docker, seeded from migrations/001_init.sql
npm run test:pg   # the same suite + 2 Postgres-only checks (32)
npm run demo:pg   # the demo, against Postgres
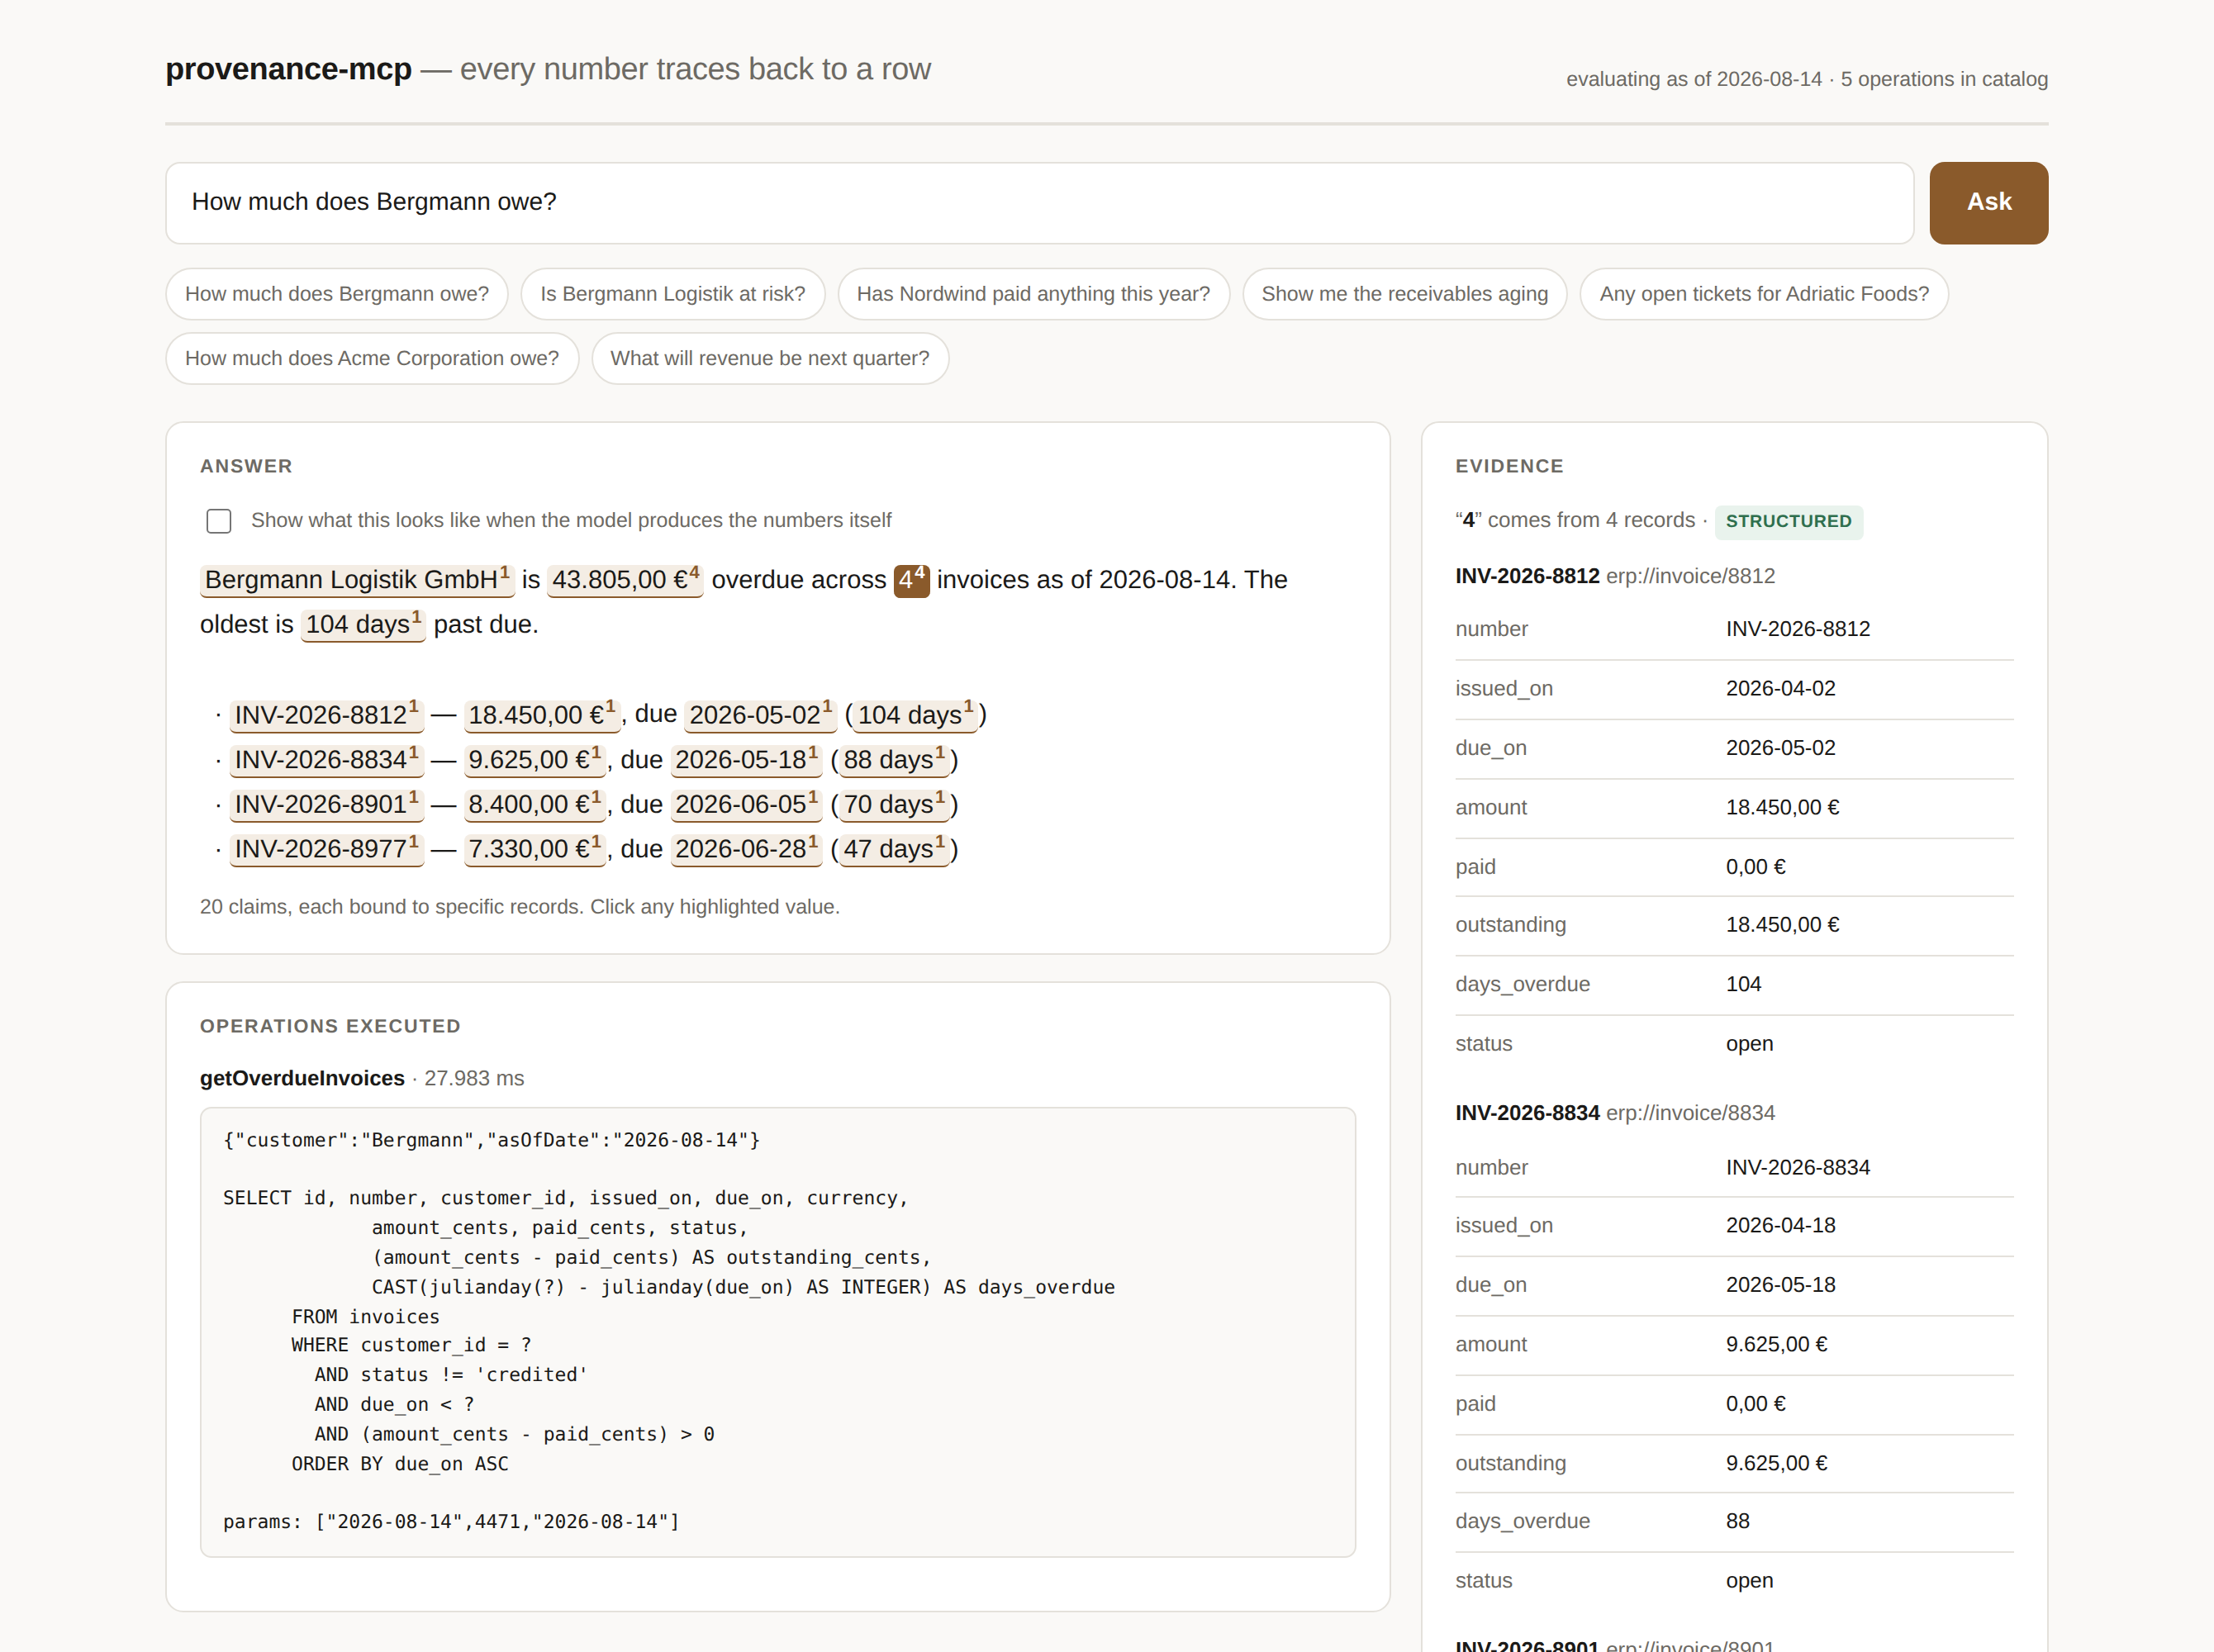
The problem
Language models produce plausible continuations, not true ones. Point one at a business database and it will confidently report a number that no query produced — and the fabricated figure is indistinguishable from the real one, because both come out of the same machinery.
The usual answers don't hold up here. Uncertainty signals catch the fuzzy cases, not the fluent ones. A verifier built from the same model can confirm a fabrication as easily as catch it. And in finance, inventory or procurement, "the model said so" is not an answer anyone can act on.
What does work is structural: never let the model produce the number.
The architecture
  question
     │
     ▼
  model ──────────► picks an operation from a catalog and supplies typed args
     │                (it cannot write SQL, cannot invent an operation)
     ▼
  contract layer ─► validates params, resolves entities against the database,
     │                rejects anything that does not exist
     ▼
  deterministic ──► executes the query; SQL does all aggregation
  core                returns values + the evidence behind each one
     │
     ▼
  provenance ─────► appends a hash-chained record, server-side,
  store               where the model cannot influence it
     │
     ▼
  host UI ────────► fills slots from structured output and renders each
                      claim as a clickable citation
The model handles translation and phrasing — the two things it is reliable at. Numbers come from the system of record.
What it enforces
These are tests, not guidelines. npm test fails if any of them breaks.
No number is generated. Values are copied verbatim from an operation's structured output into template slots. A test asserts every monetary figure in an answer is covered by a claim with evidence behind it, and that the stated total equals the sum of the records it cites.
Entities are validated before any query runs. A fabricated customer produces a recoverable error listing real alternatives — not a silent empty result the model narrates around.
Aggregation happens in SQL. The model chooses which aggregation to run, never what it equals.
Empty results are handled in code. This is the single biggest fabrication trigger: hand a model an empty result set mid-sentence and it invents something to finish the sentence. Operations set an explicit emptyReason instead.
Unroutable questions are refused. "What will revenue be next quarter?" maps to no operation, so no answer is produced. Refusal is a first-class outcome, not a failure.
Provenance is written server-side. The model never reports its own provenance. Provenance that depends on the model choosing to cite is worthless.
The log is tamper-evident. Each record carries the hash of its predecessor. npm run verify walks the chain and reports the first record that was modified after it was written.
Query ordering is a tested contract. listCustomers must return record order, because entity extraction takes the first match. Sorting it by name instead produces the failure this project exists to prevent: a fluent sentence, a real figure, correctly cited to real rows, about the wrong company. There is a test for exactly that.
Interpretations, not just figures
The harder case is judgement. "Bergmann is at risk" is a conclusion with no row to check it against — and an ungrounded interpretation is more dangerous than an ungrounded number, because it reads as insight and survives review.
The answer here states the conclusion and then lays out each premise as a separately cited fact:
Bergmann Logistik GmbH shows two independent risk signals.
This is an interpretation — the underlying facts are:

  · 43.805,00 € overdue across 4 invoices, oldest 104 days past due
  · 2 open support tickets, 1 high severity
  · agreed payment terms of 30 days, account owned by Ana Kovač

The conclusion is the model's. Every fact above is a record you can open.
A human can disagree with the reasoning while trusting the inputs.
Provenance record format
{
  "id": "…", "sequence": 1, "timestamp": "2026-08-14T09:12:04.000Z",
  "actor": { "id": "zoran", "role": "controller" },
  "question": "How much does Bergmann owe?",
  "answer": "Bergmann Logistik GmbH is 43.805,00 € overdue across 4 invoices…",

  // Each claim indexes a span of the answer and names its evidence.
  "claims": [
    {
      "text": "43.805,00 €",
      "span": { "start": 25, "end": 36 },
      "evidenceIds": ["invoice:8812", "invoice:8834", "invoice:8901", "invoice:8977"],
      "origin": "structured"        // never "generated" for a value
    }
  ],

  // The query, so the result is reproducible.
  "operations": [
    { "name": "getOverdueInvoices",
      "arguments": { "customer": "Bergmann", "asOfDate": "2026-08-14" },
      "query": { "sql": "SELECT …", "params": ["2026-08-14", 4471, "2026-08-14"] },
      "durationMs": 0.42 }
  ],

  // Field values, not just IDs — the export stands alone if the source moves on.
  "evidence": [
    { "id": "invoice:8812", "type": "invoice", "recordId": "8812",
      "uri": "erp://invoice/8812",
      "fields": { "number": "INV-2026-8812", "due_on": "2026-05-02",
                  "outstanding": "18.450,00 €", "days_overdue": 104 } }
  ],

  "previousHash": "0000…", "hash": "9aa2ba…"
}
origin is the field that matters. structured means the value was copied from an operation's output. generated means a model produced it — which for a number is exactly what this project exists to prevent.
MCP details
The server uses the parts of the protocol that carry this work:
| Feature | Use |
|---|---|
inputSchema |
The model gets a typed catalog, not a query language |
structuredContent |
Values return as validated JSON beside the prose, so figures never have to survive a round trip through generated tokens |
resource_link |
Every record touched comes back as an erp:// URI — the deep-link primitive behind a clickable citation |
annotations.audience |
Record links are marked user-facing |
_meta |
Carries the provenance record ID and hash so a host can fetch the full trace |
isError |
A fabricated entity is a recoverable tool error the model can correct, not a protocol failure |
What MCP does not give you, and what this repo adds: nothing in the protocol binds this claim to that evidence. The protocol hands you links; the claim-to-evidence mapping and its rendering live in the host. That binding is the actual product.
Run standalone over stdio:
npm run mcp
The claude_desktop_config.json entry is at the top of this README.
Running from source (for development)
{ "mcpServers": {
    "footnote": {
      "command": "npx",
      "args": ["tsx", "--experimental-sqlite", "/path/to/footnote/src/mcp-server.ts"],
      "env": { "PROVENANCE_DB": "/path/to/provenance.db", "PROVENANCE_ACTOR": "your-name" }
    } } }
Connecting to an existing database
By default Footnote runs against its own throwaway sample database. Set DATABASE_URL and it switches to external mode, meant for a database it did not create — a customer's ERP.
External mode changes three things, all of them about not damaging a system that isn't ours:
- The migration never runs. In demo mode Footnote creates and seeds
customers,invoices,paymentsandtickets. Against a real database that would either crash on a read-only role or, worse, succeed — inserting fabricated invoices into a live finance system.FOOTNOTE_SEED=1is the only way to opt back in, and exists for our own Docker Postgres. - The ERP connection is read-only at the session level. Every pool connection starts with
default_transaction_read_only=onand astatement_timeout. The catalog only ever emitsSELECT, but that is a property of code someone can change; this is enforced by the server. - The provenance log goes somewhere else. It is append-only and needs write access, so it never shares the ERP connection. Writing an audit trail into the database being audited would mean asking for write access to the very system under audit.
Create a read-only role
CREATE ROLE footnote_ro LOGIN PASSWORD '…';
GRANT CONNECT ON DATABASE your_erp TO footnote_ro;
GRANT USAGE  ON SCHEMA public      TO footnote_ro;
GRANT SELECT ON ALL TABLES IN SCHEMA public TO footnote_ro;

-- Postgres 15+ already revokes this from PUBLIC; older versions do not.
REVOKE CREATE ON SCHEMA public FROM footnote_ro, PUBLIC;

-- So tables added later are readable too, without re-granting by hand.
ALTER DEFAULT PRIVILEGES IN SCHEMA public GRANT SELECT ON TABLES TO footnote_ro;
Environment variables
| Variable | Default | Purpose |
|---|---|---|
DATABASE_URL |
unset | The ERP. Setting it enables external mode. Unset means demo mode. |
PROVENANCE_DATABASE_URL |
unset | Postgres for the provenance log. Never falls back to DATABASE_URL. |
PROVENANCE_DB |
./footnote-provenance.db in external mode, :memory: in demo |
SQLite path for the provenance log, when PROVENANCE_DATABASE_URL is unset. |
FOOTNOTE_SEED |
unset | 1 applies the demo schema and seed. Never set this against a customer database. It also makes the ERP connection writable, because seeding writes. |
FOOTNOTE_STATEMENT_TIMEOUT_MS |
5000 |
Statement timeout on the ERP connection. |
PROVENANCE_ACTOR / PROVENANCE_ROLE |
mcp-client / unknown |
Identity recorded against each provenance record. |
Check before you connect
DATABASE_URL=postgres://footnote_ro:…@host:5432/erp npm run check
or, from the installed package, footnote check. It reports the server version, whether those credentials can write, what they can read, which catalog tables and columns are missing, and whether the provenance store opens with an intact chain. It exits non-zero on a finding, so it works as a deployment gate.
The write probe deliberately connects without the read-only session flag — probing through our own default_transaction_read_only=on would have the server reject the write every time and report a pass against a role with full write access. It creates a table inside a transaction that is always rolled back, then verifies nothing was left behind.
Expose your data as views
The catalog reads fixed table and column names and never guesses at mappings. If your schema differs — and it will — create views rather than renaming anything:
CREATE VIEW invoices AS
  SELECT ar_doc_id        AS id,
         doc_number       AS number,
         bp_id            AS customer_id,
         doc_date::text   AS issued_on,
         net_due_date::text AS due_on,
         curr             AS currency,
         ROUND(gross_amt * 100)::bigint AS amount_cents,
         ROUND(paid_amt  * 100)::bigint AS paid_cents,
         CASE WHEN clearing_date IS NOT NULL THEN 'paid' ELSE 'open' END AS status
    FROM fi_open_items;
Two things that will bite otherwise: dates must come back as text in YYYY-MM-DD, because a driver-returned Date object renders as Tue May 02 2026 … inside claim text and breaks the span offsets that make citations clickable; and money must be integer cents, never floats. npm run check lists exactly which columns are missing.
What you get over plain MCP, and what needs host integration
Any MCP client — Claude Desktop, Microsoft Agent Framework, Semantic Kernel, LangChain, your own loop — can call this server today. What that gives you:
- a fixed catalog of typed operations; the model cannot write SQL or invent one
- entity validation, so a fabricated customer is an error rather than an empty result
- aggregation in SQL, never in the model
- refusals instead of improvisation when a question maps to no operation
resource_linkentries identifying every record touched- a hash-chained, server-side provenance log of every call
What it does NOT give you: clickable claim-level citations. Over plain MCP the framework receives structuredContent and resource links, and then its own model composes the answer — at which point the binding between a specific claim and its evidence is gone, and the numbers pass back through generated tokens.
Preserving that binding is host-side work, because nothing in the protocol carries it. src/web.ts and src/public/index.html are the reference implementation: claim spans, citation chips, record resolution. Roughly 200 lines. Port that to your host and you get the other half.
Try these in the demo
| Question | What it shows |
|---|---|
| How much does Bergmann owe? | Every figure clickable to the invoice behind it |
| Is Bergmann Logistik at risk? | An interpretation with separately cited premises |
| Show me the receivables aging | Portfolio aggregation, computed in SQL |
| How much does Acme Corporation owe? | Fabricated entity → refusal with real alternatives |
| What will revenue be next quarter? | Unroutable → refusal rather than improvisation |
Toggle "show what this looks like when the model produces the numbers itself" for the contrast: identical formatting, fluent prose, every figure wrong, nothing in the output marking which.
Layout
migrations/001_init.sql  schema + seed, shared by both backends and Docker
src/database.ts     the Db seam — SqliteDb and PostgresDb behind one interface
src/db.ts           opens the ERP database, applies the migration
src/operations.ts   the catalog — the model's entire callable surface
src/compose.ts      slot-filling; claims and spans are emitted here
src/provenance.ts   append-only hash-chained store, export, verification
src/mcp-server.ts   MCP server over stdio
src/web.ts          demo host application
src/verify.ts       npm run verify / npm run export
src/check.ts        npm run check — pre-flight against a customer database
test/run.ts         30 tests covering the invariants above (32 on Postgres)
docker-compose.yml  Postgres 17, seeded from the same migration
Only operations.ts writes ERP SQL, in one dialect, with ? placeholders.
PostgresDb rewrites those to $1..$n, and the single expression that genuinely
differs between the engines — whole days between two dates, julianday() on
SQLite, date subtraction on Postgres — is named daysBetween on the Db
interface rather than inlined. That is the one place a port can silently change
a number, so it is isolated and the suite asserts the same day counts on both.
Status and limits
v0, and honest about scope.
- You cannot add provenance to someone else's AI. If the answer comes from SAP Joule or Dynamics Copilot, you have no access to their retrieval pipeline or rendering. This approach applies to AI layers you build yourself over business data.
- Vendor citations exist but stop short. As of August 2026, SAP, Microsoft, NetSuite and Salesforce all ship citations that resolve to knowledge content — help articles, PDFs, documentation. None ships a general mechanism binding a figure to the transaction behind it. Numeric answers are the weakest link everywhere.
- The demo's intent routing is deliberately naive keyword matching, so the project runs with no API key. In a real deployment the model emits the tool call and this code still fills the slots. The architecture is the point, not the routing.
- Writes are out of scope. In an ERP a fabricated read is embarrassing; a fabricated write corrupts a ledger. Writes belong behind a proposal → validation → confirmation flow.
- Retention, access control, and a real deep-link resolver for a specific ERP are the last mile — and the last mile is where the actual product lives.
Prior art worth knowing
- OpenTelemetry GenAI semantic conventions — spans for GenAI clients and MCP. Early; stops well above record-level provenance.
- OpenLineage — dataset and job lineage. Same idea one layer down, for tables rather than claims.
- LLM observability — Langfuse, LangSmith, Arize, Datadog. Tracing for engineers debugging apps, not provenance for the person reading the answer.
License
MIT.
footnote MCPのよくある質問
footnote MCPをClaude Codeに追加するには
ターミナルでclaude mcp add --env 'DATABASE_URL=<YOUR_DATABASE_URL>' footnote -- npx -y @brick-byte/footnoteを実行します。すべてのプロジェクトで利用するには--scope userを追加します。
footnote MCPをCursorに追加するには
~/.cursor/mcp.jsonを開き、上記のインストールセクションに示すCursor設定を使ってmcpServersの下にサーバーを追加します。
footnoteはどのようにしてハルシネーションを防ぐのですか?
モデルが数値を生成することを禁止し、構造化されたデータベースの出力からテンプレートのスロットへ値をそのままコピーすることで実現します。
このMCP serverは既存のERPデータベースを書き換えることはありますか?
いいえ。このサーバーはセッションレベルで読み取り専用ロールを使用し、ステートメントタイムアウトを強制するため、システムへの書き込みや損傷は発生しません。
監査証跡はどこに保存されますか?
プロベナンスログは、監査対象のシステムから切り離された、追記専用の別データベースに保存されます。
プロベナンスログのセキュリティは確保されていますか?
はい。各レコードには前のレコードのハッシュが含まれているため、ログの改ざんを検知できます。