
Second Brain MCP server
Commit 12. Nov. 2026Ermöglicht es einem AI-Client, mittels Hybrid Search Kontext aus einer lokalen Wissensdatenbank mit Notizen, Transkripten, Slack-Threads und Gmail abzurufen.
Auch bekannt als mshtawythug/second-brain
- Stars
- 17
- Tools
- —
- Downloads, 30 Tage
- —
- Neueste Version
- —
- Letzter Commit
- 12. Nov. 2026
- Lizenz
- MIT
Was ist Second Brain MCP?
Second Brain ist ein MCP server. Ermöglicht es einem AI-Client, mittels Hybrid Search Kontext aus einer lokalen Wissensdatenbank mit Notizen, Transkripten, Slack-Threads und Gmail abzurufen.
Zusammenfassung generiert aus dem README des Projekts
Über Second Brain MCP server
Second Brain bietet eine lokale, abfragbare Wissensdatenbank, die als Langzeitgedächtnis für AI Coding Agents und Assistenten dient. Es zentralisiert verschiedene Informationsquellen wie Markdown-Notizen, Slack-Threads, Gmail, Krisp-Transkripte und diverse Dokumentenformate wie PDF oder DOCX in einer einzigen Postgres-Datenbank unter Verwendung von pgvector. Nutzer können über ein CLI oder ein lokales Web-UI mit ihren Daten interagieren, wodurch sichergestellt wird, dass persönliche Informationen auf dem eigenen Rechner bleiben.
Entwickler können ihre AI-Clients über den enthaltenen brain-mcp server mit dieser Wissensdatenbank verbinden. Dieses Setup erlaubt es einem Agent, Hybrid Searches durchzuführen – also eine Kombination aus Full-Text- und Vektor-Retrieval –, um spezifischen Kontext zu finden, ohne ganze Dateien einlesen zu müssen. Das System ist durch verschiedene Installationsprofile hochgradig anpassbar: von einem minimalen Setup, das nur Full-Text-Search nutzt, bis hin zu einer vollständigen GraphRAG-Konfiguration inklusive Apache AGE und Concept Extraction. Dieser Ansatz reduziert den Token-Verbrauch erheblich, da statt massiver Rohdateien sortierte Snippets zurückgegeben werden.
Was du damit machen kannst
- 1Spezifischen Gesprächskontext abrufenEin AI Agent kann Slack-Threads und Gmail durchsuchen, um Antworten zu finden, ohne dass der Nutzer den Verlauf manuell kopieren muss.
- 2AI Token-Kosten senkenEin Entwickler kann das Search Tool nutzen, um einem Agenten kleine, relevante Snippets statt ganzer langer Dokumente bereitzustellen.
- 3Automatisierte WissenssyntheseDas System kann proaktiv aktuelle Notizen zusammenfassen oder Verbindungen zwischen verschiedenen Informationen finden.
- 4Multi-hop Research QueriesNutzer können komplexe Fragen stellen, die von der AI erfordern, mehrere Suchen über den gesamten Korpus hinweg zu planen und auszuführen.
Geschrieben aus dem README des Projekts. Jeder Use Case wurde gegen ein Zitat daraus geprüft.
Konfiguration
BRAIN_EMBEDDERDATABASE_URL
| Name | Beschreibung | Typ |
|---|---|---|
| BRAIN_EMBEDDER | — | |
| DATABASE_URL | — |
Automatisierte Checks
Geluften am 14. Nov. 2026Vollständiger Bericht →Noch nicht verifiziert. Ein Server benötigt einen Score von 80, keine kritischen Befunde und genug Daten für unsere Prüfung. Wie die Checks funktionieren · Was du für mehr Punkte verbessern kannst

- Source Repository verknüpft und erreichbarmshtawythug/second-brain is public and reachablegithub.com/mshtawythug/second-brain ↗Bestanden
- Paket nennt dieses Repository als QuelleNicht geprüft
- Build-Provenienz (Sigstore-Attestierung)Nicht geprüft
- Open Source Lizenz (OSI)MITspdx.org/licenses/MIT.html ↗Bestanden
- Commit oder Release im letzten JahrLast commit or release 2026-11-12github.com/mshtawythug/second-brain ↗Bestanden
- OpenSSF ScorecardNicht geprüft
- Package-Name ähnelt keinem populären PackageNicht geprüft
- Keine kritischen Advisories im Paket oder seinen AbhängigkeitenNicht geprüft
- Keine versteckten Anweisungen an das Modell0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersBestanden
- Destruktive Tools sind markiertNicht geprüft
- Remote-Endpoint beantwortet den MCP-HandshakeNicht geprüft
README
Auf GitHub ansehenSecond Brain
Local, queryable knowledge base and note vault with hybrid search and an entity-graph layer — searchable by any AI coding agent or assistant from any conversation.



Stores career docs, interview prep, Krisp transcripts, Slack threads, Gmail, and authored Markdown notes in Postgres + pgvector. Any agent reaches all of it through the brain CLI or the bundled brain-mcp MCP server — no re-pasting context into every chat. You read it through the CLI or the local web UI, and the vault is plain Markdown you can open in any editor.
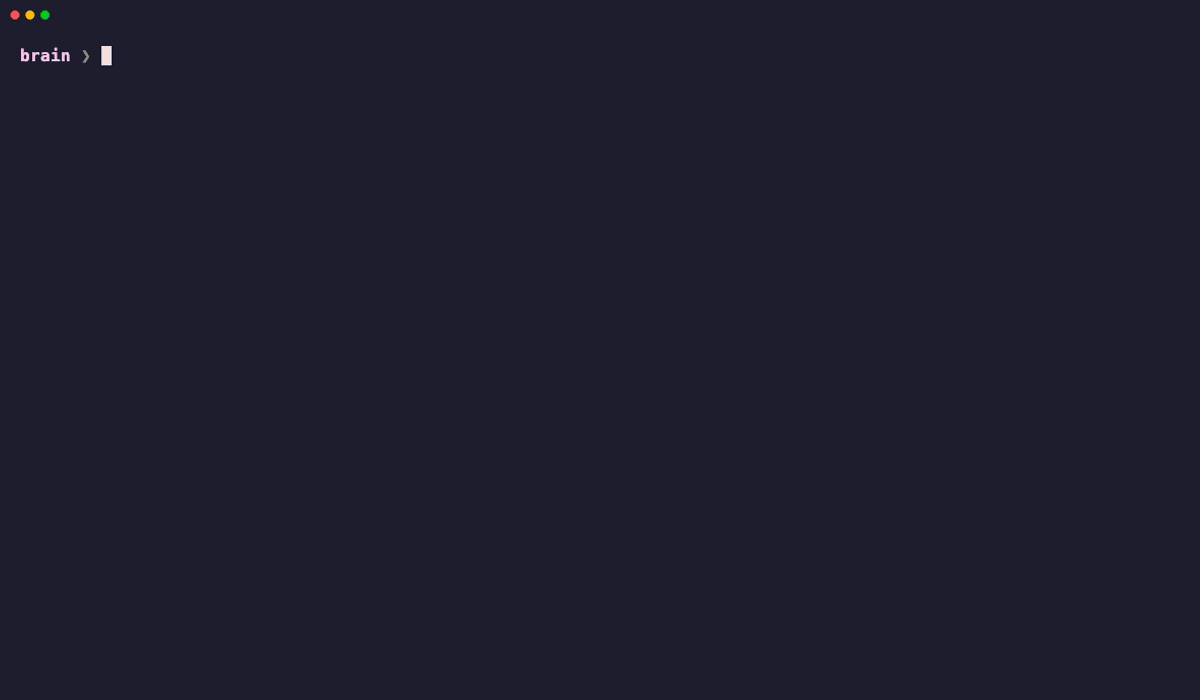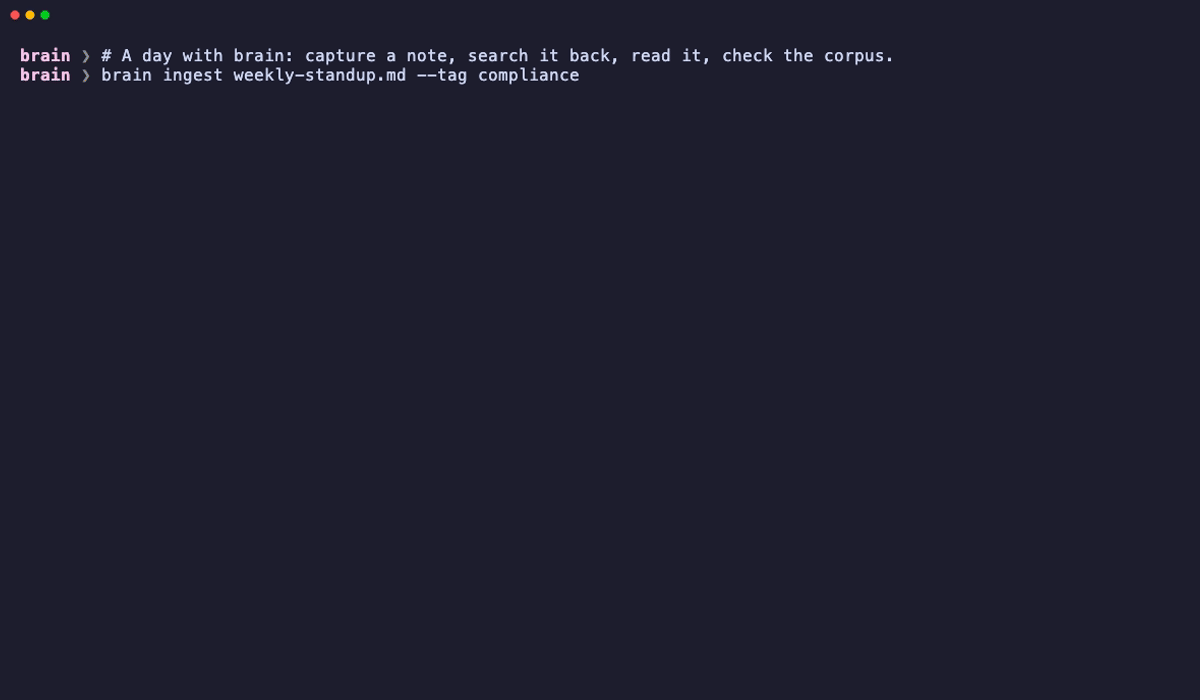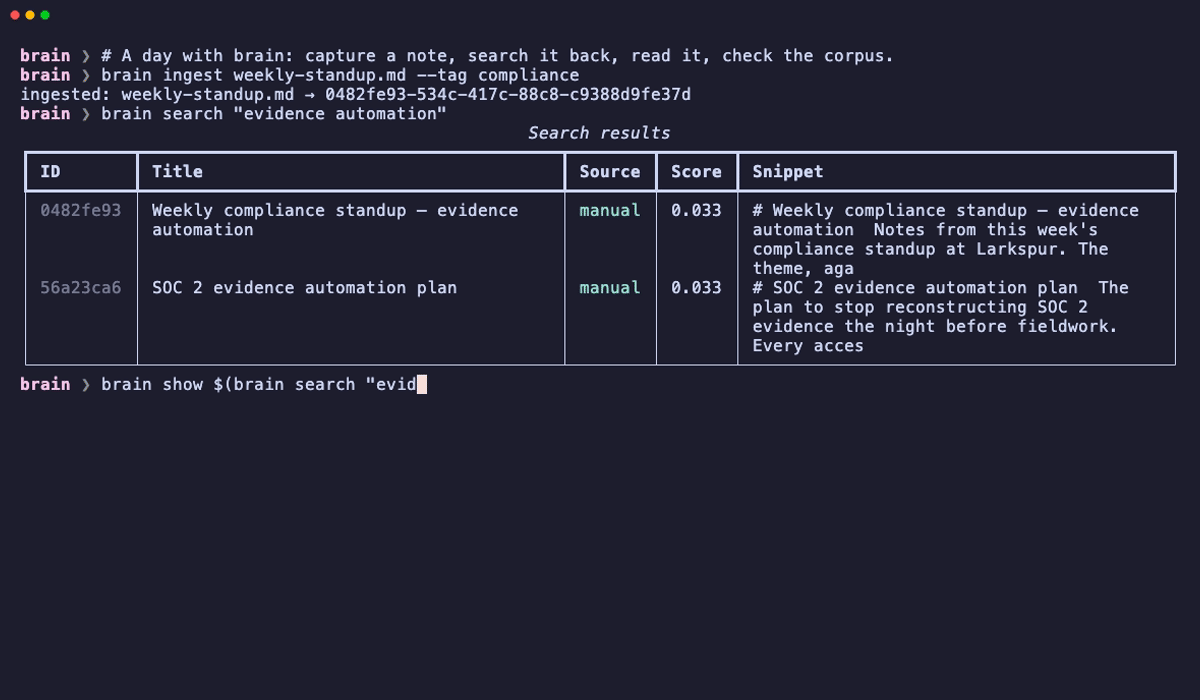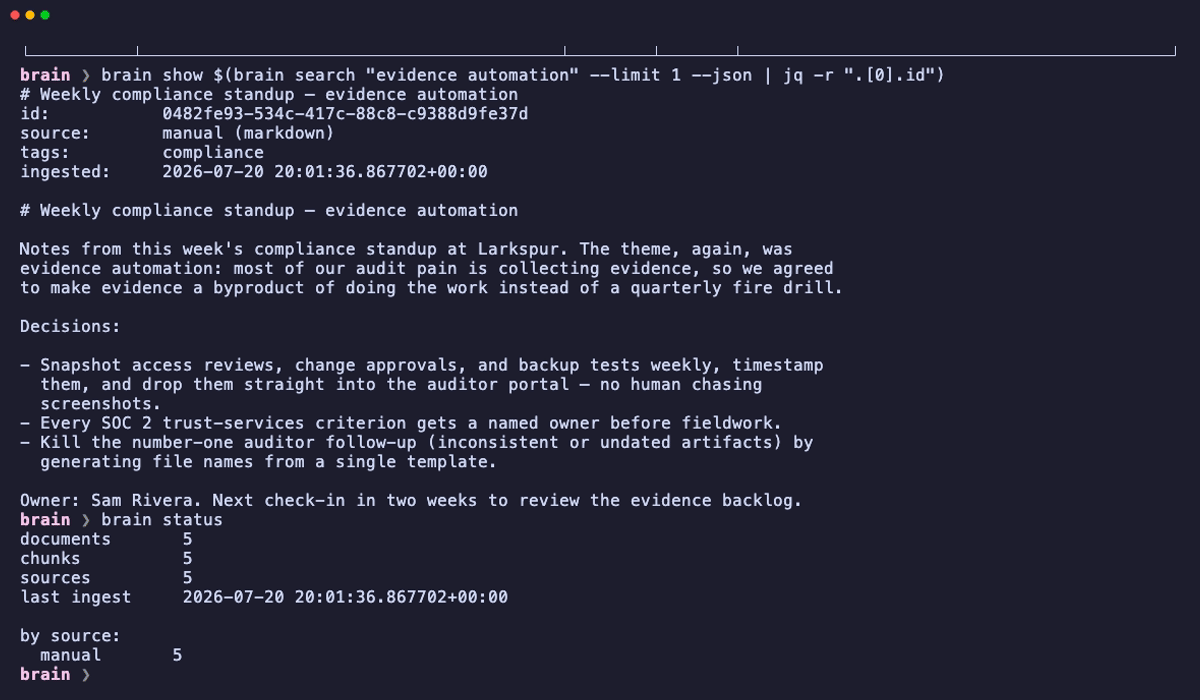
The everyday loop — capture a note, search it back, read the top hit, check the corpus:
Token savings
Querying brain returns a ranked snippet instead of dumping whole threads and files into an agent's context, so a lookup costs a fraction of the tokens a direct MCP or file read would:
| Source | Direct read (MCP / Read tool) |
Via brain (search + optional show) |
Savings |
|---|---|---|---|
| Gmail thread | 15–50k (metadata + full threads with quoted replies / headers) | ~2–4k (snippets + one targeted brain show) |
~5–15× |
| Krisp transcript | 25–75k (search + full transcripts across candidates) | ~6–16k (search + one relevant transcript) | ~4–10× |
| Long PDF / DOCX (30+ pages) | 15–25k (read the whole file) | ~1–9k (one snippet + targeted show) |
~5–15× |
Brain stores pre-extracted, quote-stripped bodies and hybrid-ranks before fetching, so only the passage that matched enters context. See the full per-source breakdown.
brain search --brief trims that payload further. With --json, each result carries whichever is cheaper — the document's ingest-time summary or its query-conditioned chunk snippet — plus a snippet_source key naming which one won, so brief output is 8 keys instead of 7. Ranking is untouched; only the projection changes. Measured over an 11-query sample: −57.4% (25,528 → 10,884 tokens, before / after).
brain search "platform migration" --json --brief
The tradeoff is stated rather than hidden: a result substituted to "summary" no longer says why it matched, so re-run without --brief to get the query-conditioned passage back. It is a no-op without --json. Full matrix in the CLI reference.
When the reader is an agent rather than a person, brain recall goes one step further. Instead of a ranked list someone has to open, it returns the passages themselves — packed to an explicit token budget, one per document to keep sources diverse, with the same inline [N] citations brain ask uses:
brain recall "platform migration runway" --budget 800
See it in 60 seconds
Install the CLI, then run the offline demo — a throwaway Postgres seeded with a synthetic Larkspur compliance corpus. No Ollama, no personal data, no model downloads:
pipx install secondbrain-py
# or, with uv:
uv tool install secondbrain-py
# or, pin the git tag (no PyPI needed):
pipx install git+https://github.com/mshtawythug/second-brain.git@v0.2.1

brain demo        # spins up a sandbox Postgres, seeds 22 docs, runs a hero query
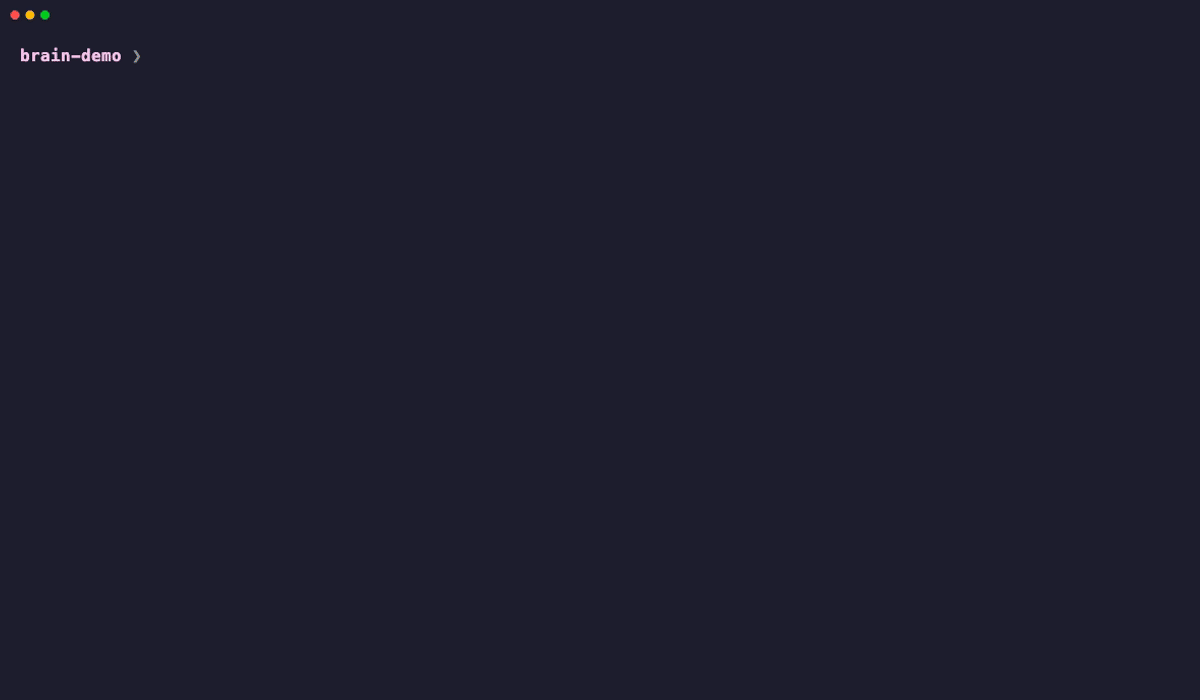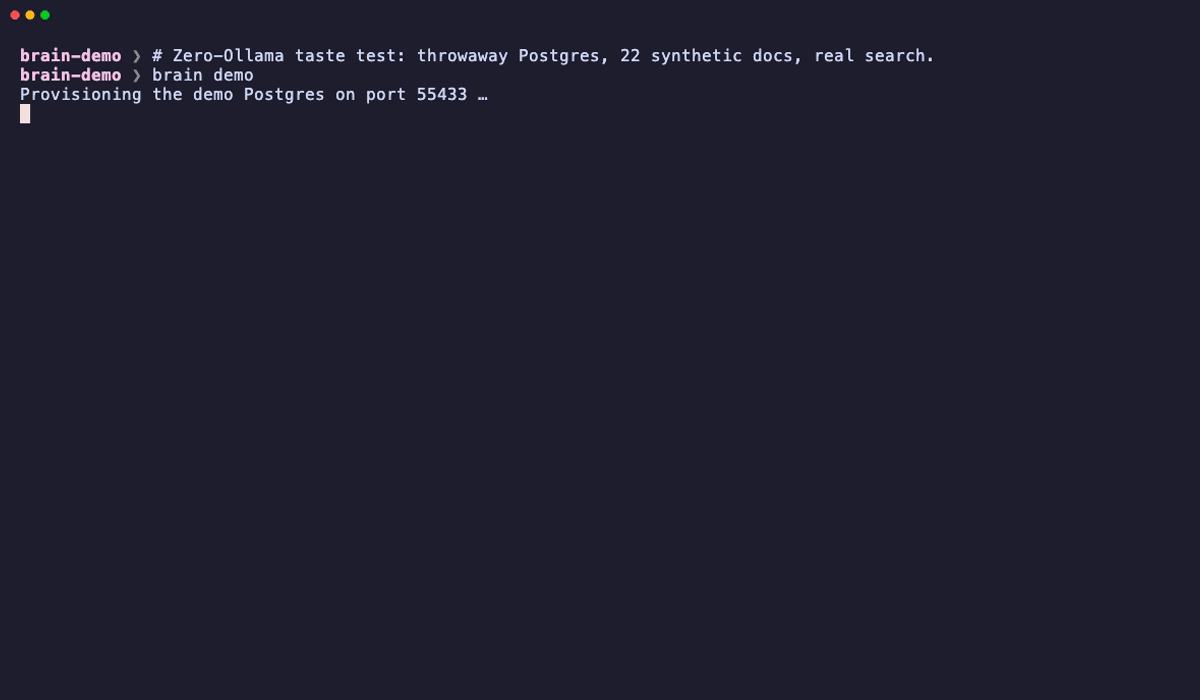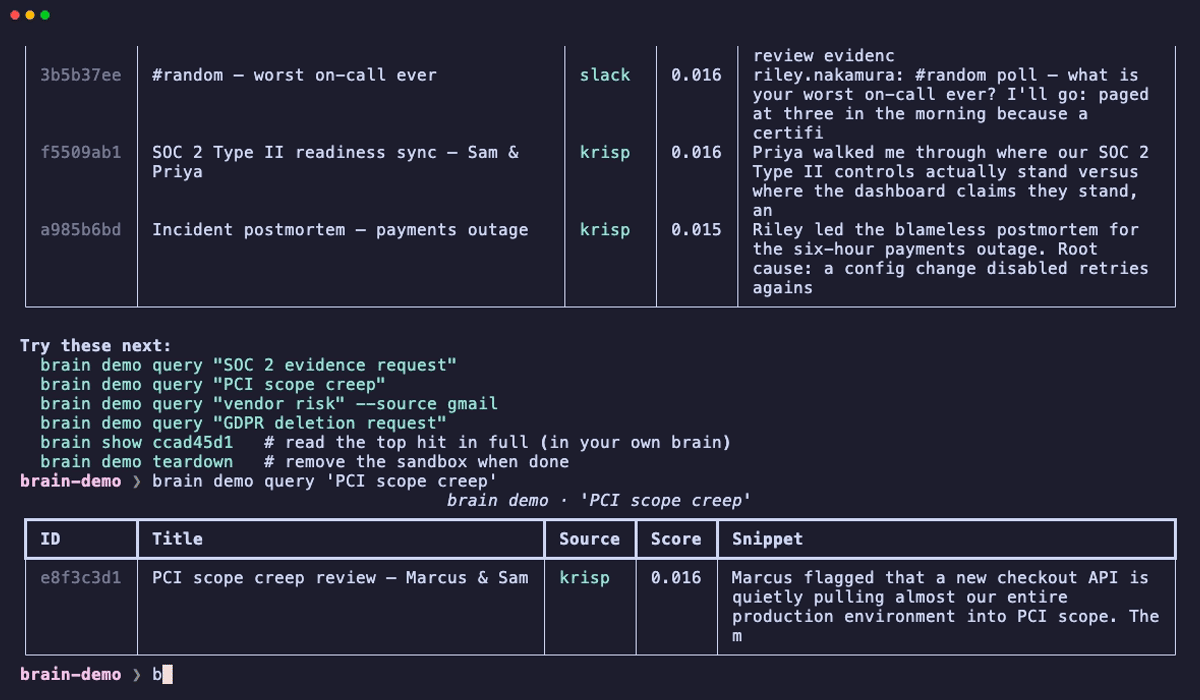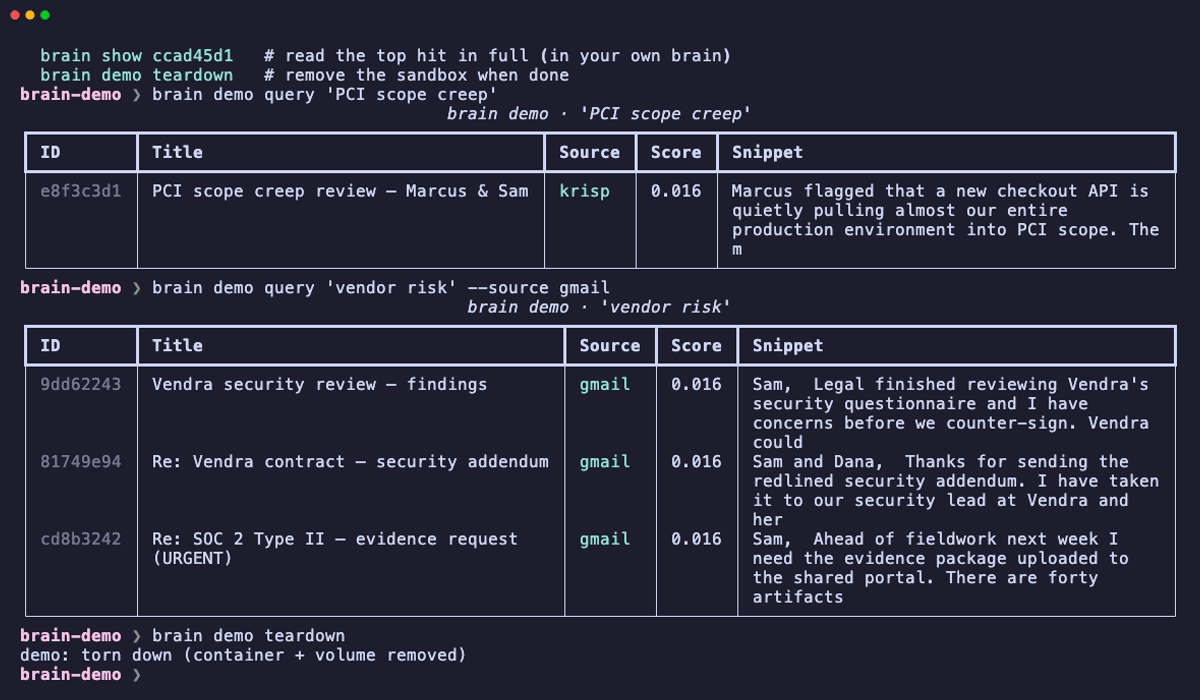
(IDs and scores are per-run; the seeded corpus and its ranking are deterministic — the top hit is always the "Compliance Horror Stories" note.)
Try these next:
brain demo query "SOC 2 evidence request"      # a targeted follow-up query
brain demo query "vendor risk" --source gmail  # narrow by source
brain show <id>                                # read the top hit in full (in your own brain)
brain demo teardown                            # remove the sandbox when done
brain demo needs only Docker; brain demo teardown destroys the sandbox.
Already ran the demo? You have brain installed — jump straight to brain setup --profile … below.
Quick start
Full install — the brain CLI plus the runtime (Postgres, and optionally Ollama / graph):
curl -fsSL https://raw.githubusercontent.com/mshtawythug/second-brain/v0.2.1/install.sh | bash
The installer pipx-installs brain from the v0.2.1 tag, then runs brain setup to provision $BRAIN_HOME, start the Postgres container, and (optionally) install the Claude Code skill. Choose how much to stand up with --profile:
| Profile | Search | Extra dependencies beyond the core |
|---|---|---|
minimal |
FTS-only (BRAIN_EMBEDDER=none) |
None — core only (no Ollama, no models). |
standard (default) |
Hybrid (FTS + vector) | + Ollama + one ~1 GB embedding model (snowflake-arctic-embed2). |
full |
Hybrid + GraphRAG | + Apache AGE image, concept-extraction LLM, and (opt-in) launchd daemons via --daemons. |
brain setup --profile minimal    # Docker-only, FTS search — fastest to stand up
brain setup --profile standard   # default: local hybrid search
brain setup --profile full --daemons
Prerequisites (core): Git, Python 3.11+, and a running Docker (Desktop or Engine) — the Postgres + pgvector database runs in a container on port 55432.
Optional extras (only if you want more than FTS-only search):
- Ollama — local, free embeddings + LLM enrichment. To upgrade a
minimal(FTS-only) brain to hybrid search: install Ollama, thenollama pull snowflake-arctic-embed2, setBRAIN_EMBEDDER=arcticin.env, and runbrain init && brain reembed. gwsCLI — only for Gmail ingest and Google-backed directory linking.
Prefer to drive every step yourself, or hacking on the code? See Installing from source.
Core usage
brain ingest ~/Documents/resume.pdf --tag career          # ingest a file (TXT / MD / PDF / DOCX)
brain ingest-dir ~/Documents/career                       # recursive, idempotent by content hash
brain search "what did I tell my manager about the migration"   # hybrid FTS + vector search
brain show <id-prefix>                                    # full document body (6+ hex prefix)
brain list --source gmail --limit 20                      # browse by source
brain tag <id-prefix> +interview +career -old-tag         # add (+name) / remove (-name) tags
brain capture --text "follow up on the migration cutover" # zero-friction inbox, tagged `inbox`
Add --json to search / show / list for machine-readable output, and --fts-only to search to skip the embedding call. The full command surface — Gmail ingest, the quick-capture inbox, enrichment, tacit-knowledge elicitation, GraphRAG, ranking diagnostics (brain explain) and relevance feedback (brain rate), the proactivity/synthesis commands, and vault authoring — lives in the CLI reference.
Proactive side
Search is reactive — you ask, the brain answers. The other half runs unprompted: brain brief digests what just landed, brain resurface ranks older notes for another look, brain review weekly synthesizes an ISO week into a vault page, brain timeline shows how a theme moved over time, brain connect proposes links between notes that share entities but aren't linked yet, and brain gaps mines the queries your brain failed to answer.
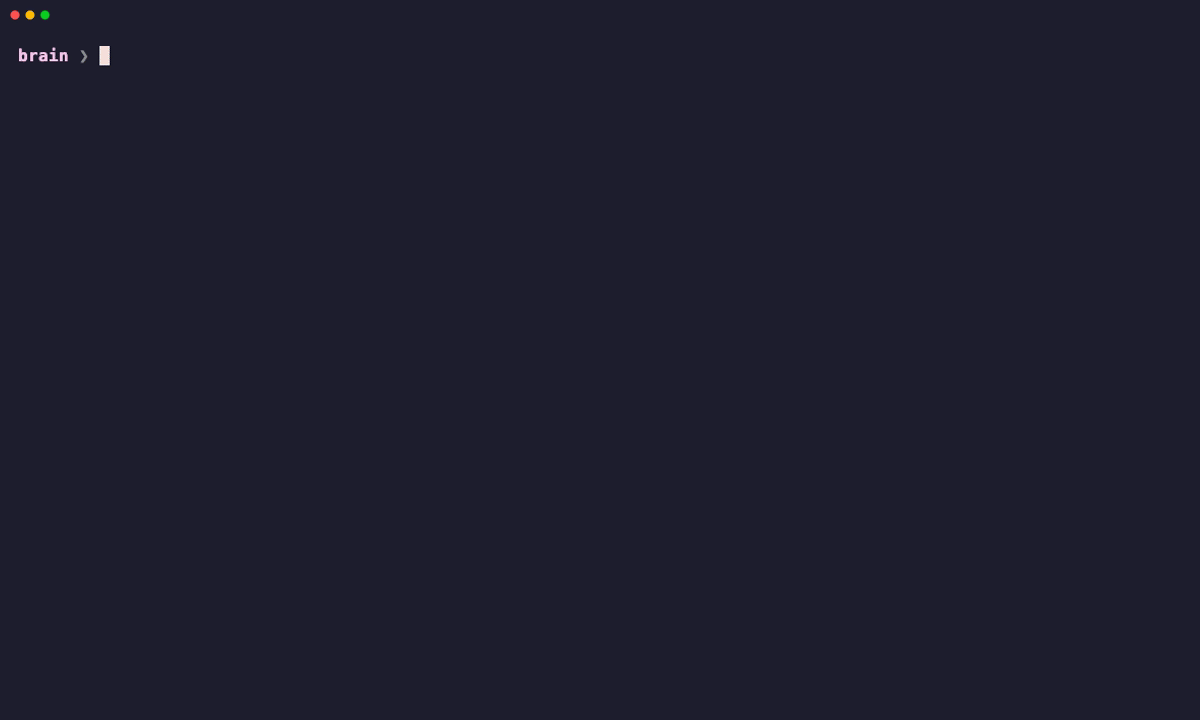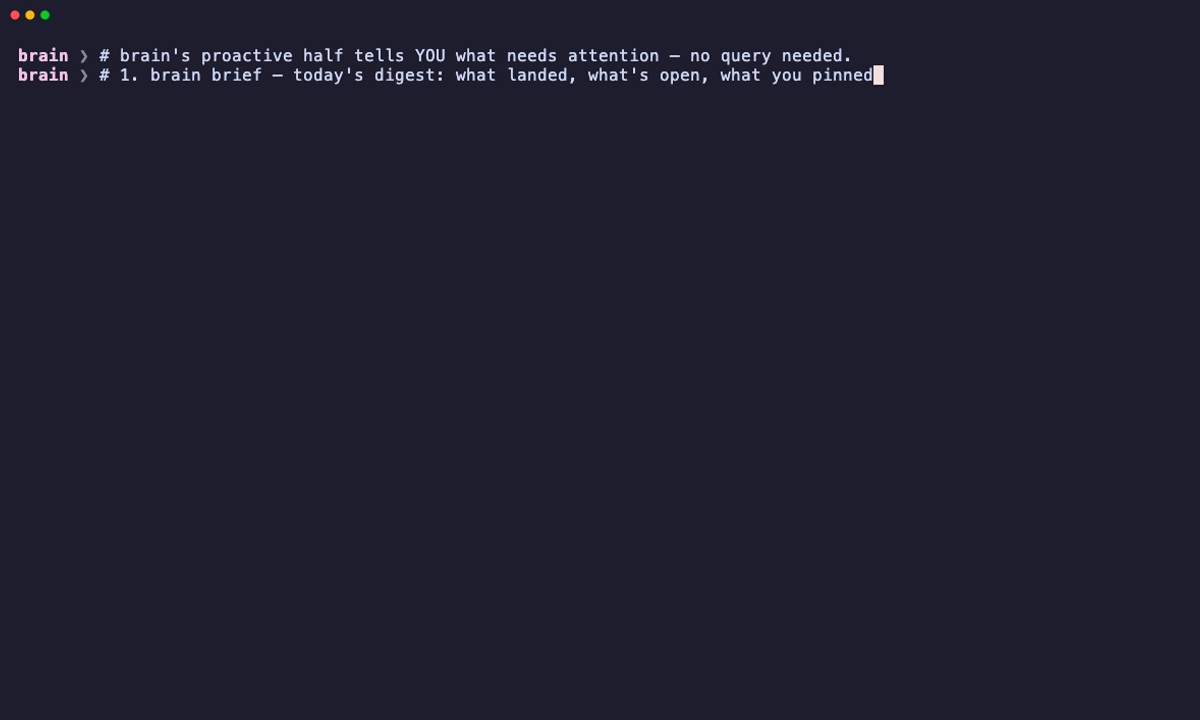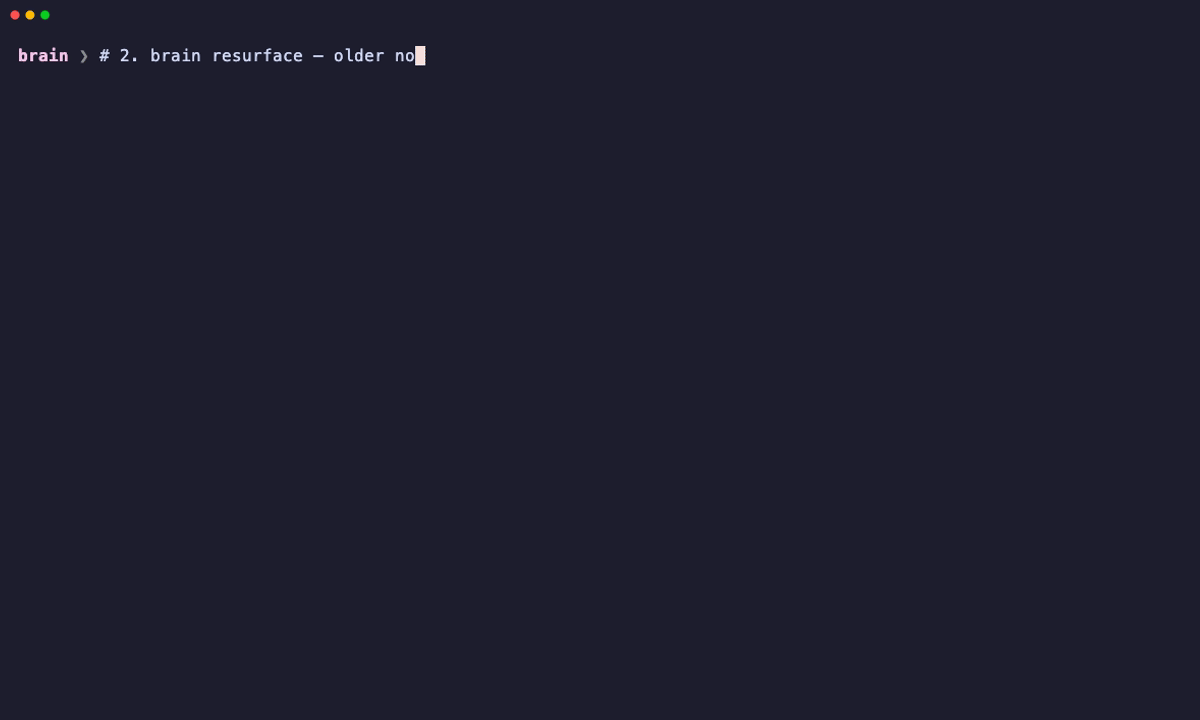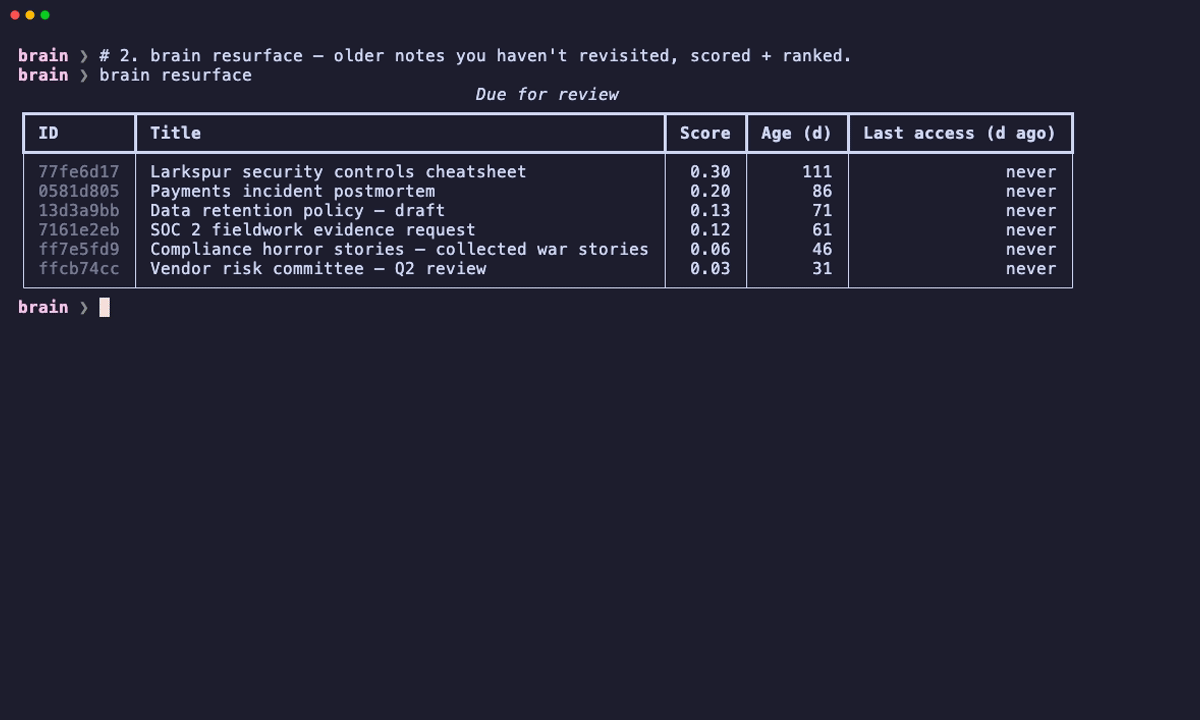
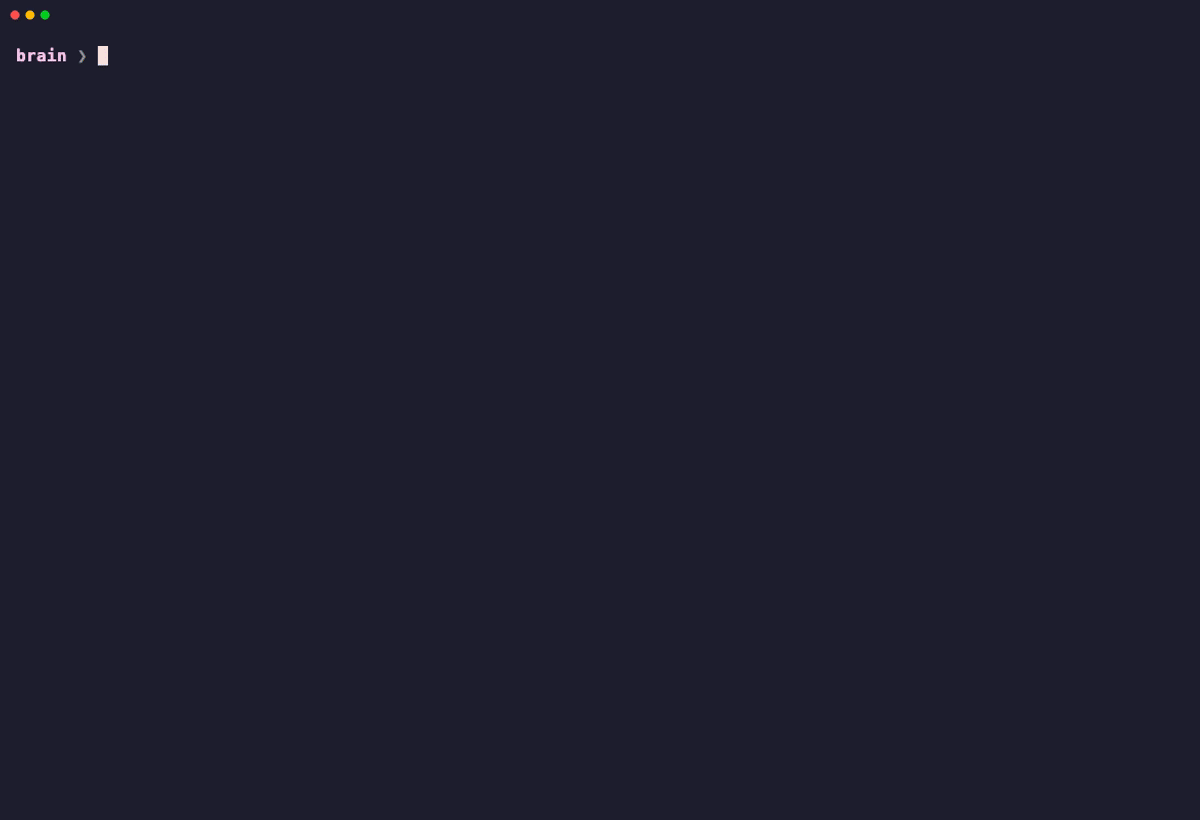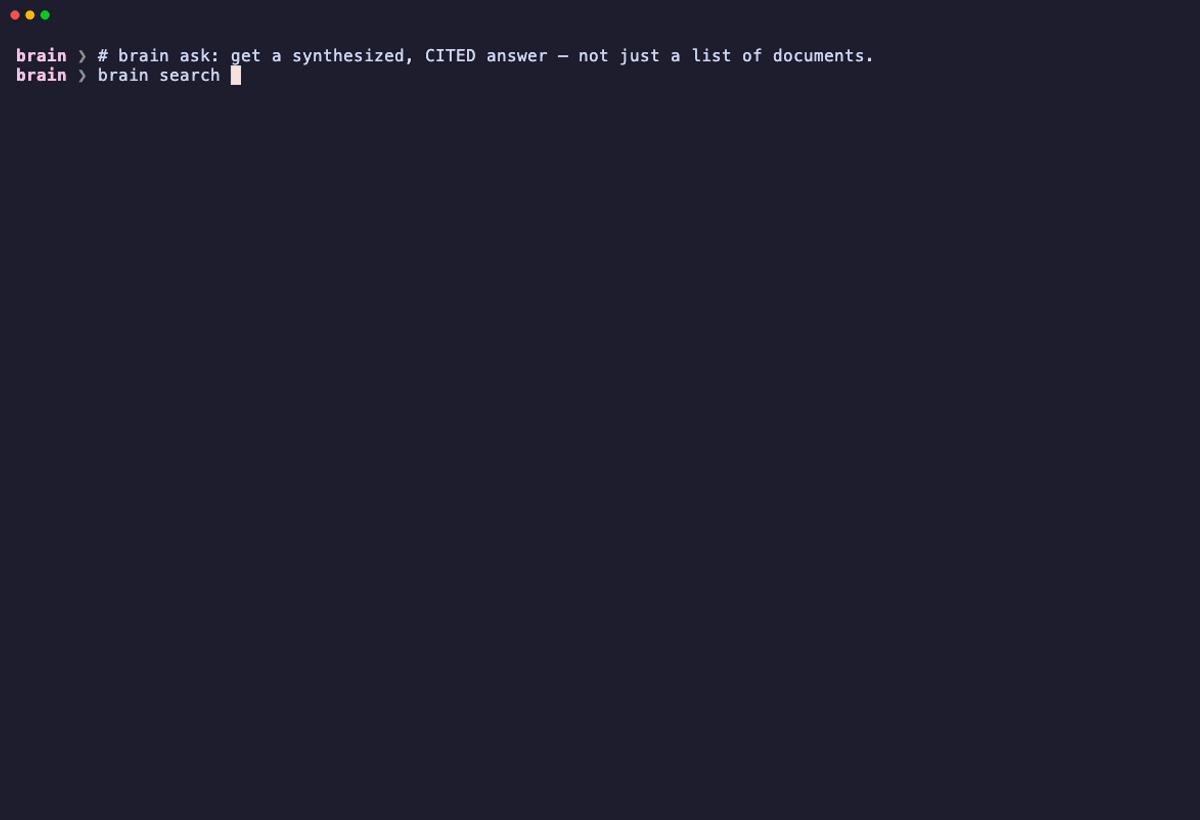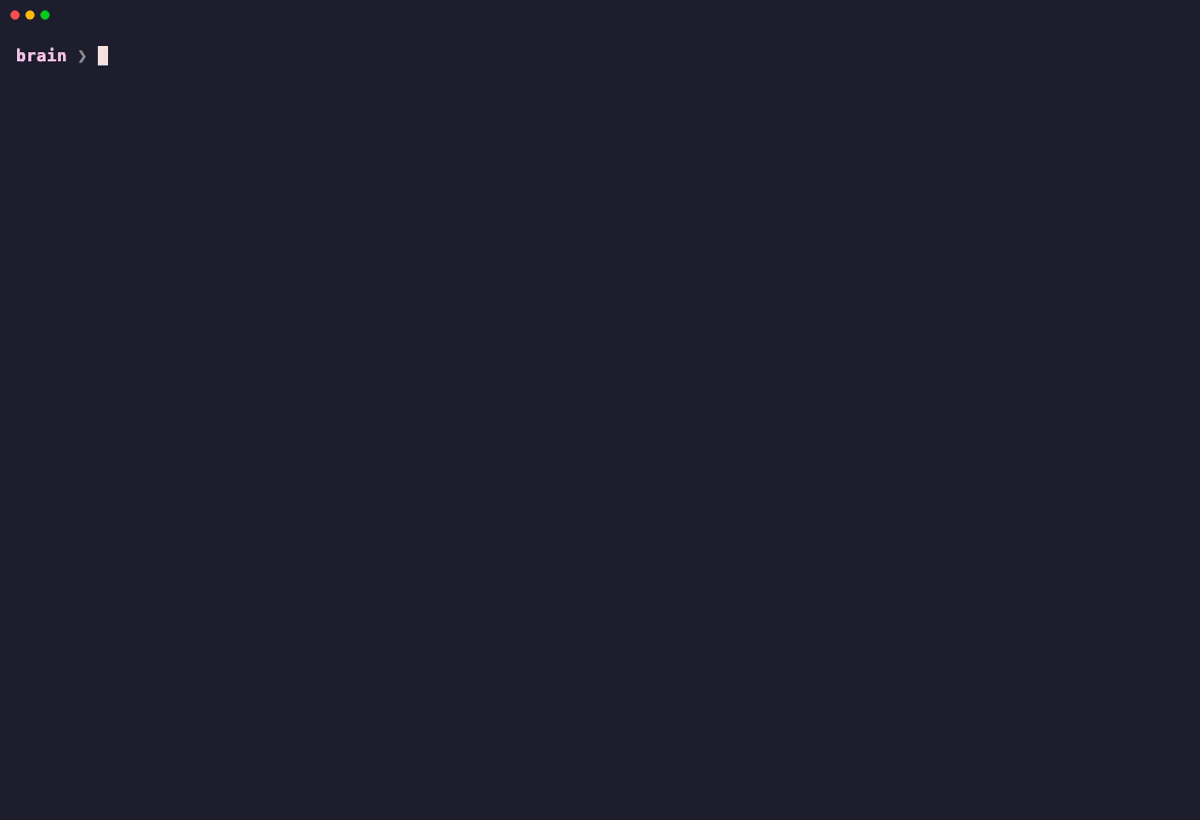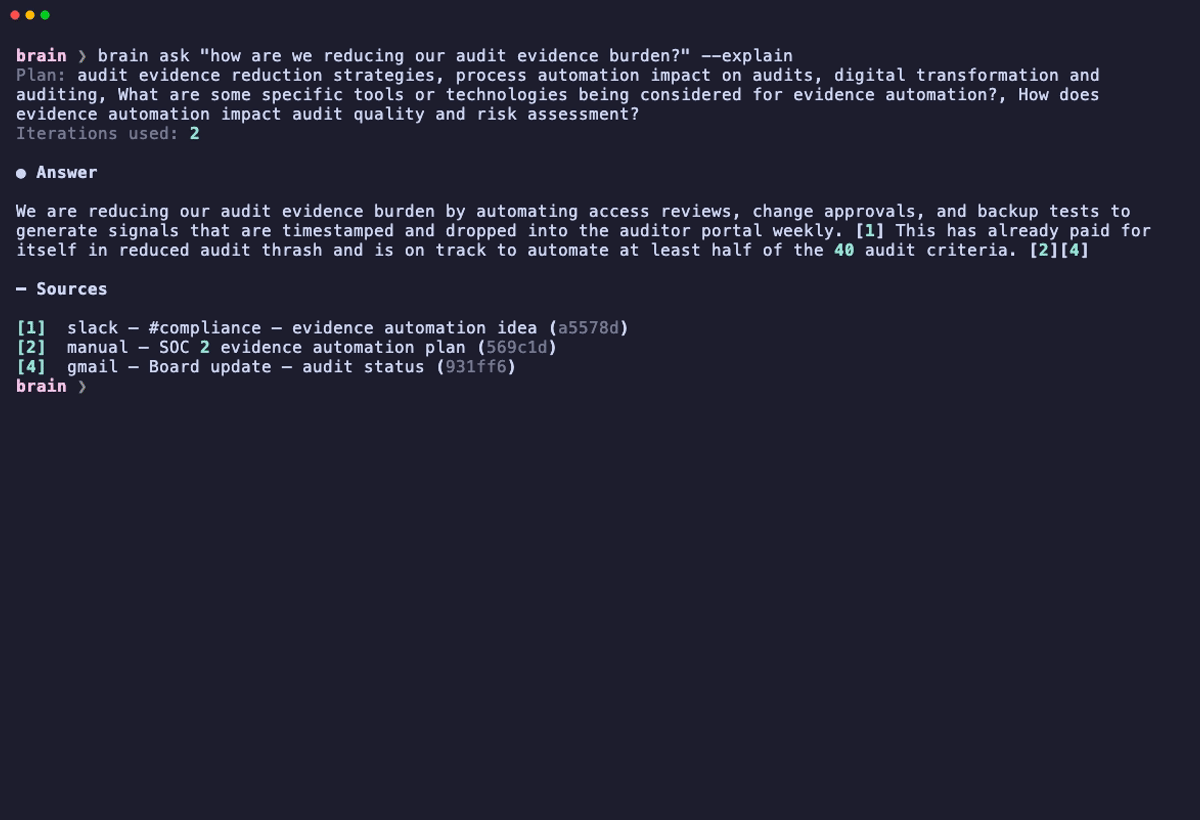
brain ask closes the loop. Instead of a ranked list you read yourself, it plans sub-queries, retrieves across iterations, and composes one answer with inline [N] citations back into your own documents:
brain brief                                             # today's digest
brain resurface                                         # older notes due for review
brain ask "what did we decide about the data pipeline?" # cited multi-hop answer
Full flags and examples for these and brain audio are in the CLI reference.
Local web UI
brain ui is the primary reading surface: a single-user web app over the same corpus. You can browse the tree, search with facets, read a document, and create, edit, move, or delete vault notes. Its Ingest tab pastes text or markdown, uploads one .md, .txt, .pdf or .docx file, or picks one by name from an inbox drop folder, into the brain as an ingested document, with live progress, cancel, and a link to the result. Its Agent tab asks a question as brain ask does, shows each step as it runs, and answers in plain text whose [n] citations open the cited notes. Both tabs work on a loopback, writable server only:
brain ui                                  # binds 127.0.0.1:8765 and opens a browser
brain ui --read-only                      # serve the corpus, block every mutation
brain ui --lan --read-only                # read from your phone: LAN address + a token
Reading from another device always needs a token. --lan binds this machine's LAN address and mints a token, then prints the URL to open. See Reading your brain from a phone for the manual --host <LAN address> --token <secret> form and the caveats.
Upgrading from a release that had the rendered Quartz wiki? It was retired in favour of brain ui, and upgrading does not remove its leftovers or stop a Caddy still serving it. The vault docs list what to delete by hand.
It adds no runtime dependency — starlette and uvicorn already ship as transitive deps of the MCP SDK — and the front end is hand-written static assets with no bundler and no CDN, so it works fully offline.
If the vault-sync watcher is not running, the top bar says so — "Watcher not running — external edits will not appear in search" — because edits made outside brain ui only reach search once brain vault sync --watch (or a manual brain vault sync) picks them up.
Beside each note, the inspector shows its local link graph — the note and its direct neighbours, click a node to open it — and a rail of related notes ranked by the same hybrid scoring and cosine floor brain search uses. Both are read-only: they read what is already in the database and never trigger a build.
Claude integrations
brain and the bundled brain-mcp server are harness-agnostic — any agent that runs a shell command or speaks MCP can query the corpus.
Register the MCP server once, then just ask — the agent searches the brain and answers from it, no context pasted in:
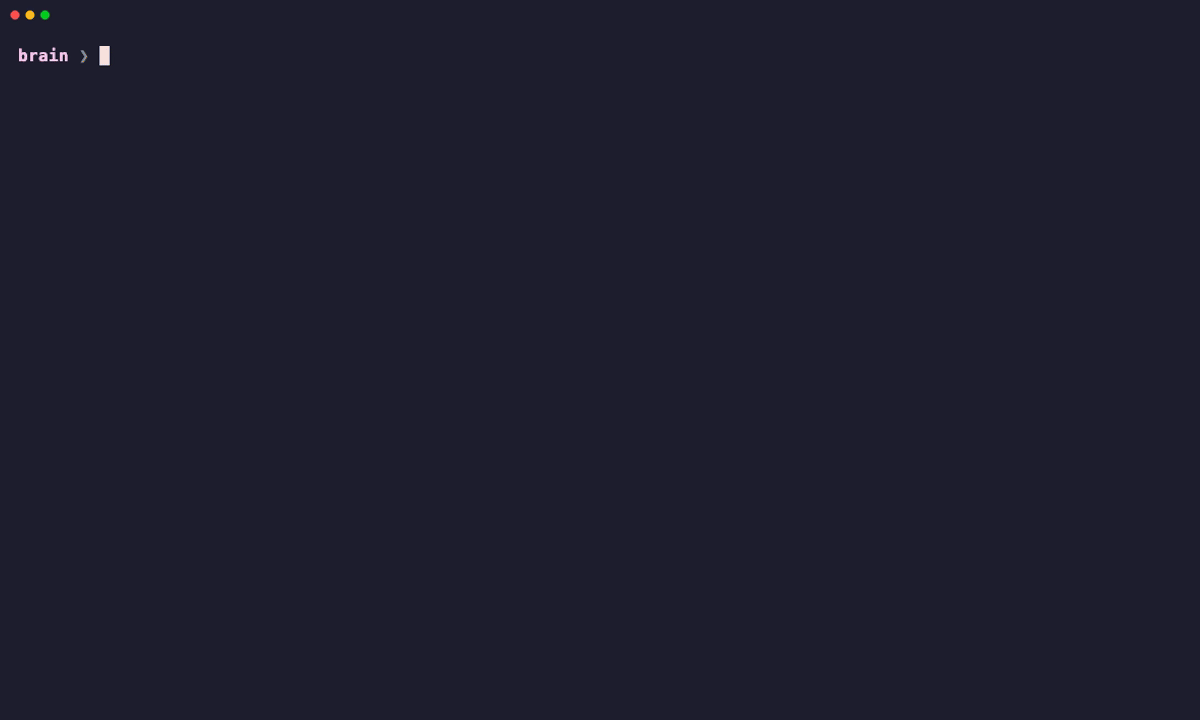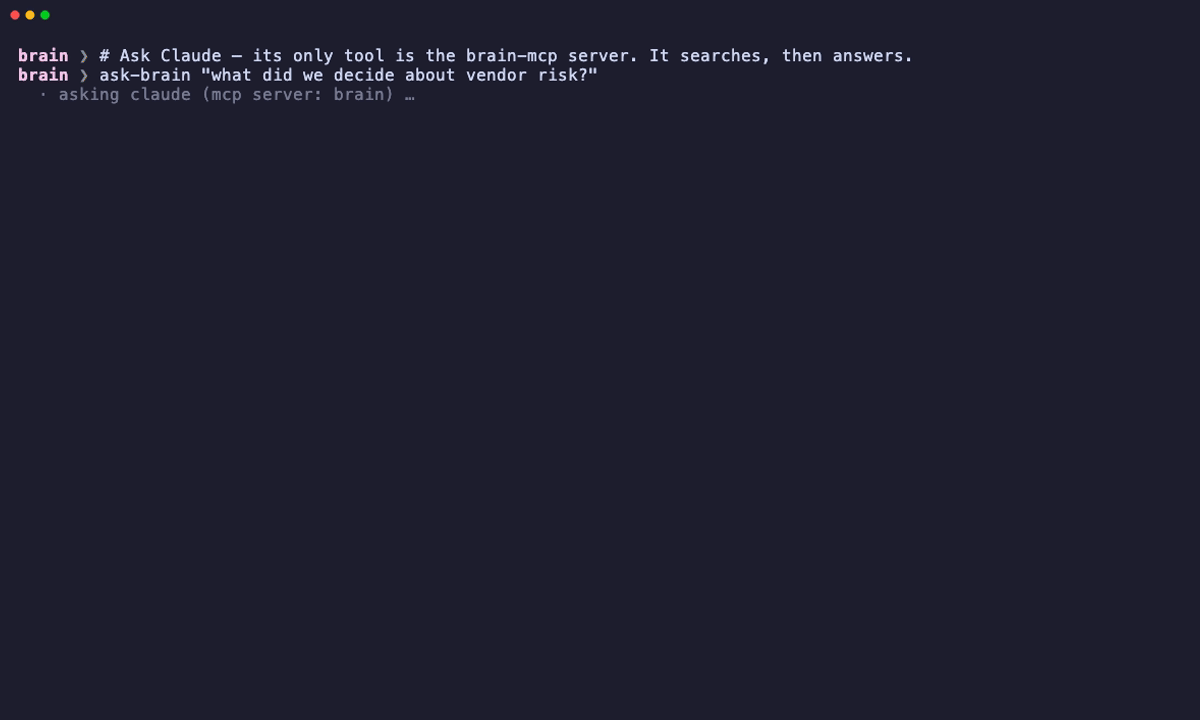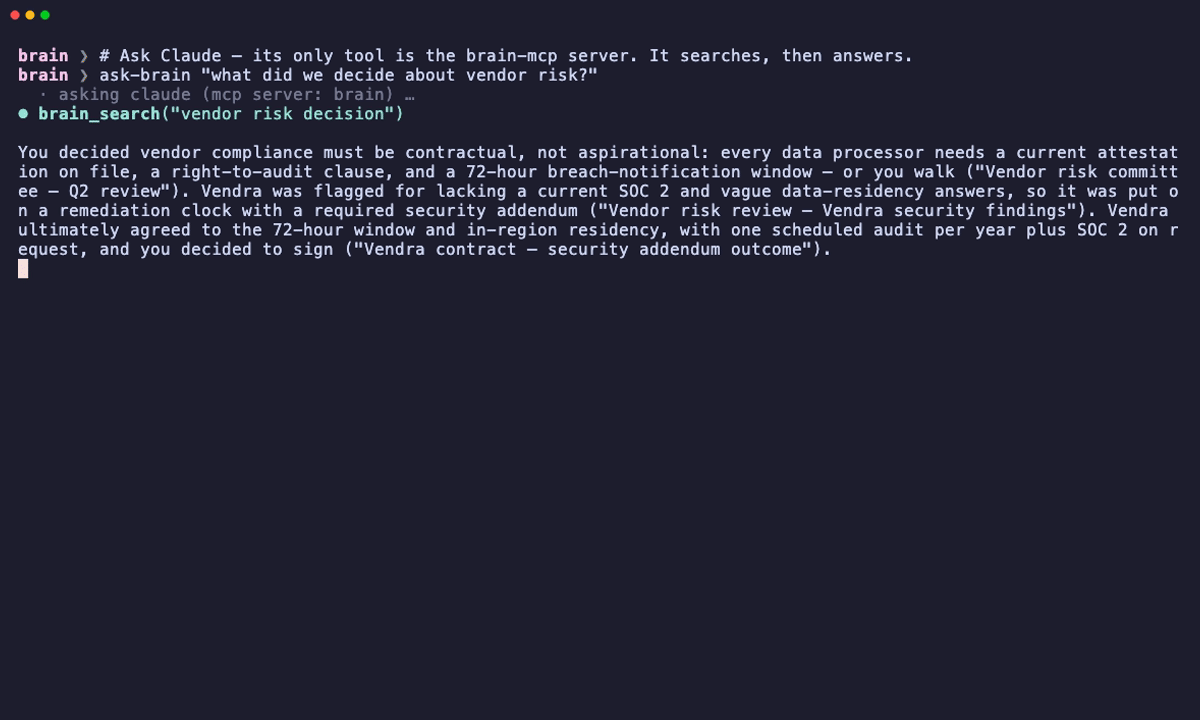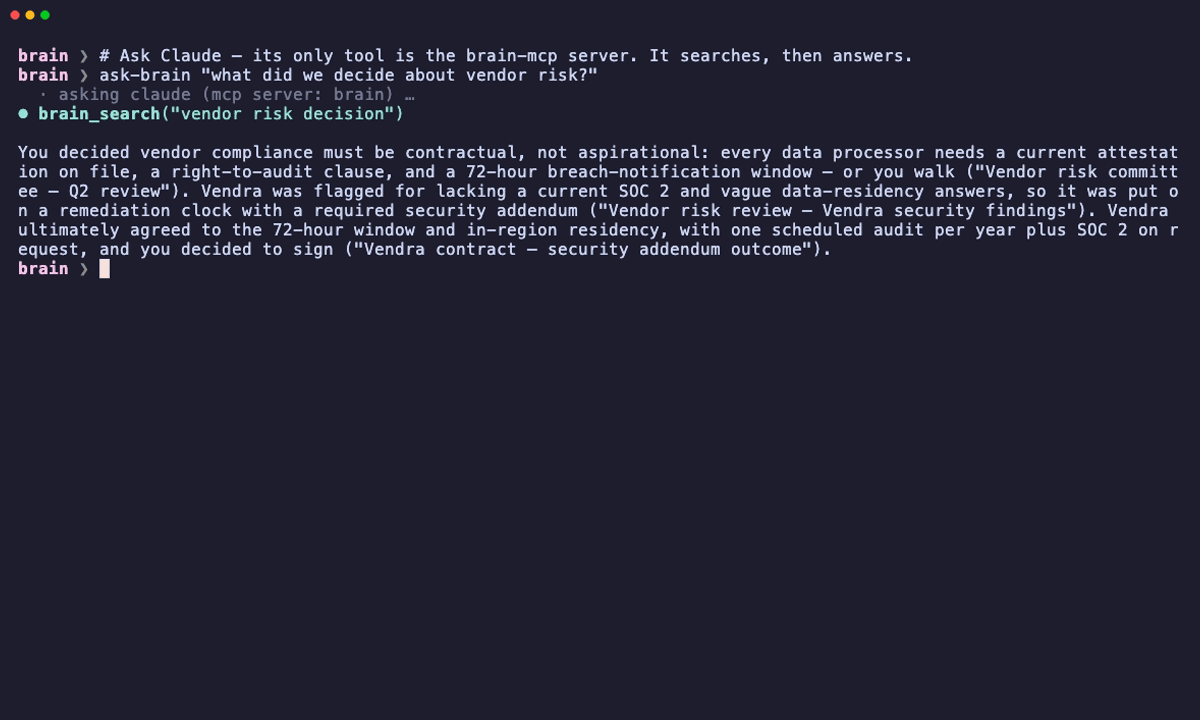
Claude Code — register the MCP server (or install the bundled agent skills with bin/brain-skills-sync):
claude mcp add brain -- brain-mcp
Claude Desktop — add to ~/Library/Application Support/Claude/claude_desktop_config.json (replace /Users/you with your home directory):
{
  "mcpServers": {
    "brain": {
      "command": "/Users/you/workspace/second-brain/.venv/bin/brain-mcp",
      "env": {
        "DATABASE_URL": "postgresql://brain:brain@localhost:55432/second_brain",
        "BRAIN_EMBEDDER": "arctic"
      }
    }
  }
}
uvx secondbrain-py also launches the MCP server. Full walkthrough (symlink, smoke-test, troubleshooting): docs/guides/claude-desktop-setup.md.
To reach the tools from another machine on a private network, brain mcp serve serves them over streamable HTTP: loopback by default, bearer-authenticated, read-only, with confidential documents refused. See docs/guides/mcp-http-transport.md.
search, recall, rate and ingest-stdin accept --agent <id> (or an ambient BRAIN_AGENT_ID), so when several agents share one brain, brain usage can report which of them has been reading what.
Payload ceilings. So no single tool call can eat an agent's context window, six env vars bound what the MCP server returns: BRAIN_SHOW_MAX_CONTENT_TOKENS (25000 — the only one where 0 means unlimited, and it bounds the body and the summary, each separately), BRAIN_SEARCH_MAX_LIMIT (50), BRAIN_RECALL_MAX_BUDGET_TOKENS (13000), BRAIN_GRAPH_ENTITIES_MAX_LIMIT (500), BRAIN_MCP_ROWS_MAX_LIMIT (200) and BRAIN_GRAPH_COMMUNITIES_LIST_LIMIT (25). An over-ceiling request is refused naming the ceiling that stopped it, and a trimmed body or list flags itself — never a silent cut. BRAIN_SNIPPET_MAX_CHARS (1600) caps a stitched search snippet on both the CLI and MCP paths. Every default is sized off live-corpus percentiles rather than picked, which is why every one is a knob: the table and the reasoning behind each number.
Confidential documents
Not everything in a personal corpus should leave the machine:
brain ingest board-deck.pdf --sensitivity confidential
brain mark-confidential <id-prefix>       # brain mark-normal downgrades it again
brain list --sensitivity confidential
confidential is an egress control, not an access control. The document stays fully readable from the local CLI — that is inside the trust boundary. What changes is what leaves the machine: the body is kept off a hosted embedder, withheld from the MCP brain_show / brain_search / brain_recall / brain_resurface responses unless the caller passes include_confidential=true, kept out of the pages brain generates into the vault, and withheld from brain ui on a LAN bind unless it is started with --include-confidential. Re-ingest is escalate-only — it can raise a document's tier but never lower it — so a background vault sync --watch pass cannot quietly reset what you marked.
Backups and health
brain backup --label pre-upgrade    # checksummed DB + vault archive, with a manifest
brain restore <archive> --db-only   # y/N confirmed; the pre-flight checks are not skippable
brain usage --days 30               # searches, opens, ingests, and search latency p50/p95
brain usage --engagement            # opens and ratings, and whether the ranking gate is met
brain doctor                        # environment, database, embedder, daemons, mirror drift
pg_dump runs inside the container by default: the server is 16.x while a typical host Homebrew pg_dump is 14.x, and that mismatch aborts the dump outright. The archive is a logical dump holding the corpus in plaintext, not a copy of the data/postgres bind mount.
How it works
Hybrid search. Every document is chunked, embedded, and indexed for Postgres full-text search. A query runs both legs — lexical tsvector ranking and vector cosine similarity — and fuses them with Reciprocal Rank Fusion (k=60), then applies a recency boost and metadata filters. Lexical alone misses paraphrases ("what did I say about X"); vector alone misses exact names (a coworker, a former employer); RRF gets both in one ranked list without tuning weights. Set BRAIN_EMBEDDER=none for an FTS-only brain with no embedding dependency at all.
GraphRAG. Alongside search, brain builds an entity graph of the people and concepts that co-occur across the corpus (Apache AGE inside the same Postgres) and retrieves over that structure — answering "what themes come up in my conversations with X" or "which clusters of people and topics dominate my notes" by traversing relationships instead of matching text. It runs alongside plain search, not instead of it. See docs/graphrag.md.
Documentation
- docs/ — full documentation index
- CLI reference — every command beyond the core five
- GraphRAG — entity-graph retrieval (themes, patterns, connections)
- Vault — the two-tier note vault, its maintenance commands, and the
bin/scripts - Configuration — tech stack, tuning knobs, integrations, embedder backends, uninstall
- Agent skills — the Claude Code skills bundled with the repo, and how to install them
- CONTRIBUTING.md — dev setup, codebase layout, running the tests
- SECURITY.md — security model and how to report a vulnerability
- CHANGELOG.md — release history
- LICENSE — MIT
Second Brain MCP Fragen
Wie kann ich das mit Claude nutzen?
Du kannst den enthaltenen brain-mcp server bei Claude Code registrieren oder ihn deiner Claude Desktop Config hinzufügen.
Welche Dateitypen kann ich importieren?
Das System unterstützt TXT, MD, PDF und DOCX sowie Slack-Threads und Gmail-Inhalte.