
Gitにインスパイアされたコンテンツ・アドレッシング・ストアを使用し、マシンやツール間で同期可能な、バージョン管理と検索に対応したAIメモリを提供します。
別名 code4161/memgit, memgit-mcp
- スター
- 4
- ツール
- —
- ダウンロード数(30日間)
- 925
- 最新バージョン
- 0.16.0
- 最終コミット
- 2026年11月12日
- ライセンス
- MIT
memgit MCPとは
memgitはMCPサーバーです。 Gitにインスパイアされたコンテンツ・アドレッシング・ストアを使用し、マシンやツール間で同期可能な、バージョン管理と検索に対応したAIメモリを提供します。.
プロジェクトのREADMEから生成された概要
memgit MCP server について
memgitは、異なるマシンやツール間で同期可能な、AIコーディングエージェント向けのバージョン管理・検索対応メモリレイヤーを提供します。SHA-256に基づいたコンテンツ・アドレッシング・オブジェクトストアを使用することで、すべてのメモリの安定性と復元性を保証します。このシステムにより、開発者はノートPC、デスクトップ、リモートサーバーなどの環境を切り替える際も一貫したコンテキストを維持でき、同期中のデータはエンドツーエンドの暗号化によって保護されます。
ユーザーは、MCPまたは直接インストールを通じて、Claude Code、Cursor、Windsurf、Gemini CLIなどのさまざまなAIクライアントにこのメモリを統合できます。サーバーは、変更内容のdiffや誤ったエントリのロールバックといった高度なバージョン管理機能をサポートしています。また、既存のリポジトリからプロジェクトの事実を抽出するonboardと呼ばれるシーディングメカニズムも備えています。チーム利用の場合、メモリをgitリポジトリのように扱い、GitHubなどのプラットフォームにプッシュすることで、学習されたルールや規約をグループ内で共有できます。
できること
- 1デバイス間でのメモリ同期クラウド同期機能を使用することで、AIエージェントが学習したルールを、ローカルのノートPCとリモートサーバーの両方で利用できるようにできます。
- 2誤ったAIメモリ更新の取り消しAIエージェントが重要なプロジェクトルールを誤った情報で上書きしてしまった場合、rollbackコマンドを使用して以前の状態に復元できます。
- 3既存のコードベースからのメモリ投入新しいプロジェクトを開始する際、アーキテクチャや規約を自動的に抽出して、AIに即座にコンテキストを与えることができます。
- 4チーム内でのAIコンテキストの共有標準的なgitコマンドを使用して、AIが学習した知識を共有リポジトリにプッシュし、チーム全員で利用できます。
プロジェクトの README から作成されています。すべてのユースケースは、その引用と照らし合わせて確認されています。
memgit MCPのインストール方法
フォーマット検証日 2026年11月10日Claude Codeにmemgit MCPをインストール
$ claude mcp add memgit -- npx -y memgit-mcpCursorにmemgit MCPをインストール
~/.cursor/mcp.json
{
  "mcpServers": {
    "memgit": {
      "command": "npx",
      "args": [
        "-y",
        "memgit-mcp"
      ]
    }
  }
}VS Codeにmemgit MCPをインストール
.vscode/mcp.json
{
  "servers": {
    "memgit": {
      "type": "stdio",
      "command": "npx",
      "args": [
        "-y",
        "memgit-mcp"
      ]
    }
  }
}Claude Desktopにmemgit MCPをインストール
claude_desktop_config.json
{
  "mcpServers": {
    "memgit": {
      "command": "npx",
      "args": [
        "-y",
        "memgit-mcp"
      ]
    }
  }
}Codexにmemgit MCPをインストール
~/.codex/config.toml
[mcp_servers.memgit]
command = "npx"
args = ["-y", "memgit-mcp"]
Gemini CLIにmemgit MCPをインストール
~/.gemini/settings.json
{
  "mcpServers": {
    "memgit": {
      "command": "npx",
      "args": [
        "-y",
        "memgit-mcp"
      ]
    }
  }
}自動チェック
実行日 2026年11月14日詳細レポート →自動チェックに合格しました。これはセキュリティ監査ではありません。コードを読み、サーバーに必要最小限のアクセス権を与えてください。 チェックの仕組み
- ソースリポジトリがリンクされており、アクセス可能code4161/memgit is public and reachablegithub.com/code4161/memgit ↗合格
- パッケージがこのリポジトリをソースとして示しているmemgit-mcp, memgit name code4161/memgit as sourcenpmjs.com/package/memgit-mcp ↗合格
- ビルドの来歴(Sigstore 証明)No build attestation published for this release未チェック
- オープンソースライセンス (OSI)MITspdx.org/licenses/MIT.html ↗合格
- 過去1年以内にコミットまたはリリースありLast commit or release 2026-11-12github.com/code4161/memgit ↗合格
- OpenSSF Scorecard未チェック
- パッケージ名が有名なパッケージに酷似していないNo popular package one edit away from memgit-mcp, memgit合格
- パッケージと依存関係に重大なアドバイザリがないthe package checked; no critical advisoryosv.dev ↗合格
- モデルへの隠れた指示がない0 tool descriptions and the README read; no override phrases, credential paths or hidden characters合格
- 破壊的なツールがラベル付けされている未チェック
- リモート endpoint が MCP ハンドシェイクに応答する未チェック
README
GitHubで見るmemgit — one memory for your AI coding agents
The same memory in every session, on every machine, in every tool. Versioned, so a wrong memory is one command to undo.
Claude Code now remembers things on its own, on one machine. Its docs are plain about the limit: auto memory is machine-local and is not shared across machines or cloud environments. memgit is the layer on top. It imports what Claude Code already keeps and adds the three things built-in memory does not do:
- Every machine. Your laptop, your desktop and a server hold the same memory, synced end-to-end encrypted.
- Every tool. Claude Code, Cursor, Codex, Windsurf, Gemini CLI and any MCP host read and write one store.
- History. Every change is a checkpoint.
memgit diffshows what an agent changed andmemgit rollbackputs it back.
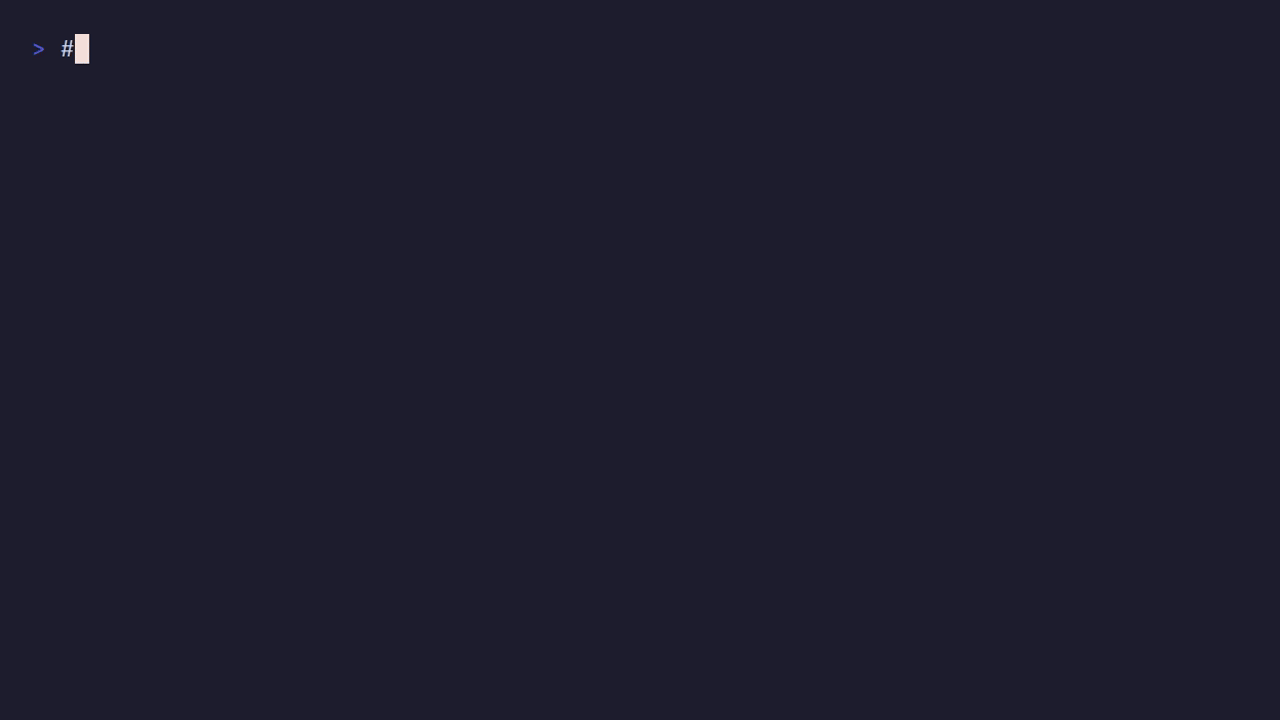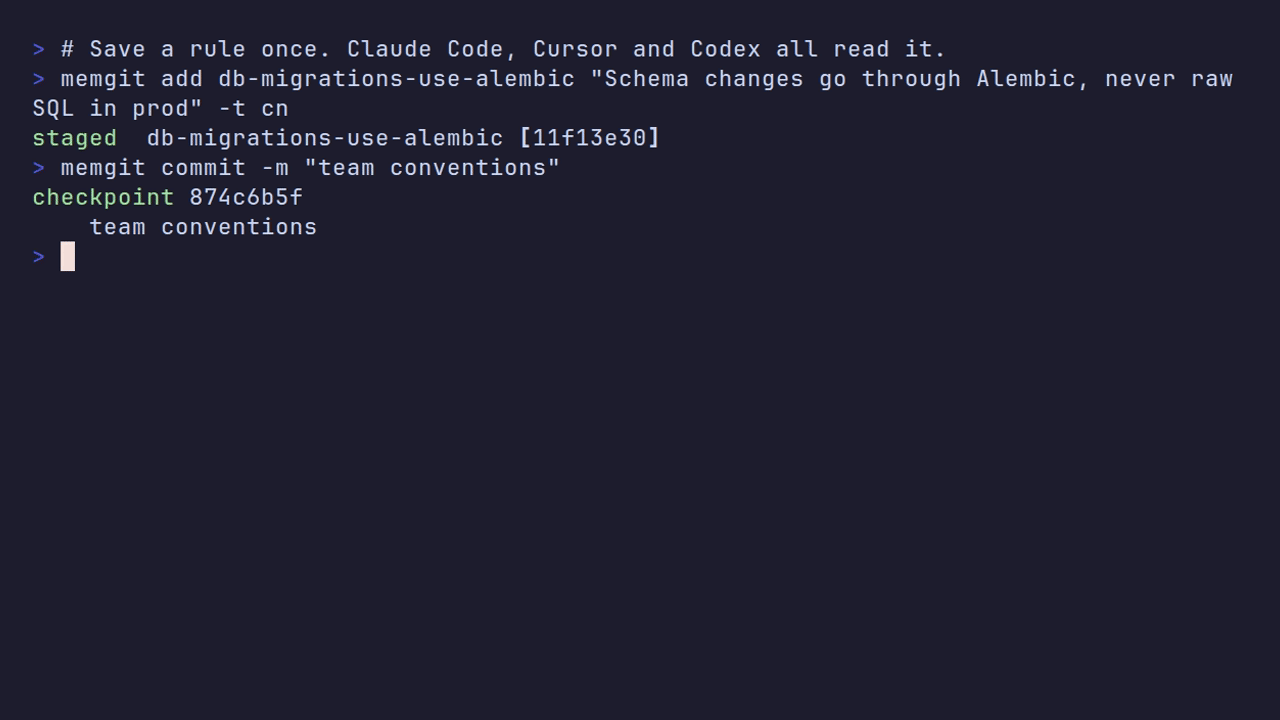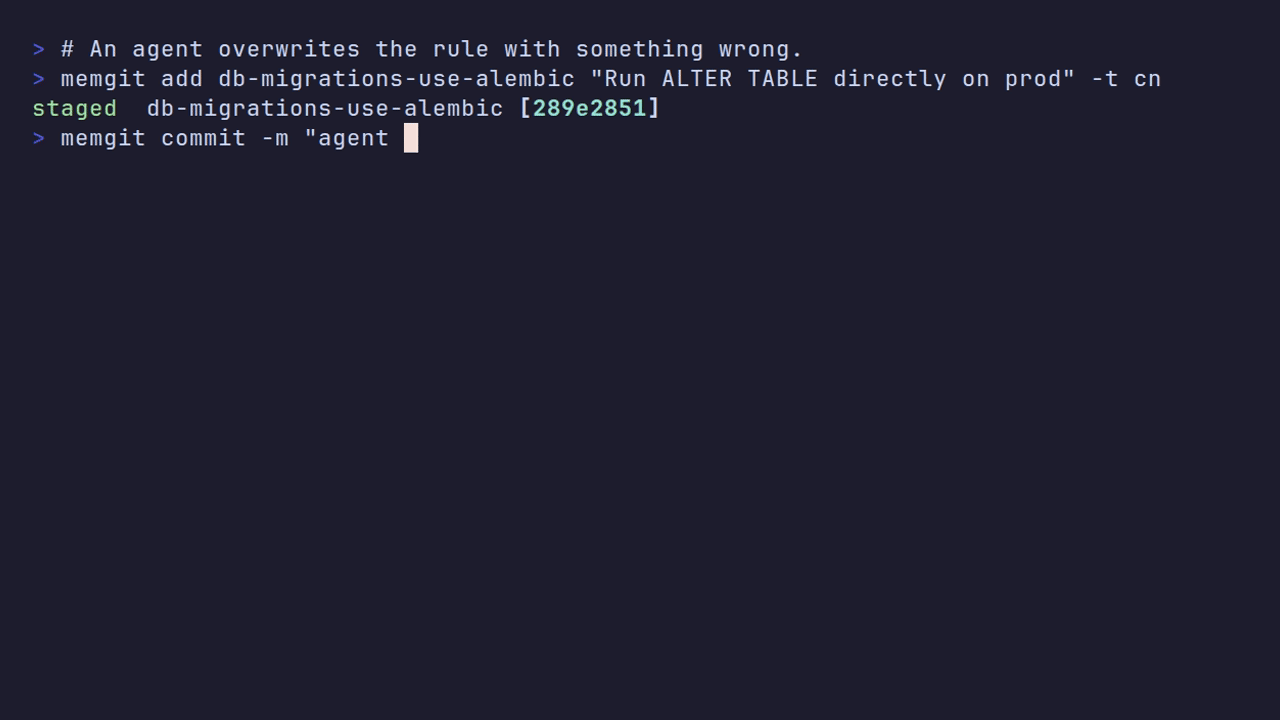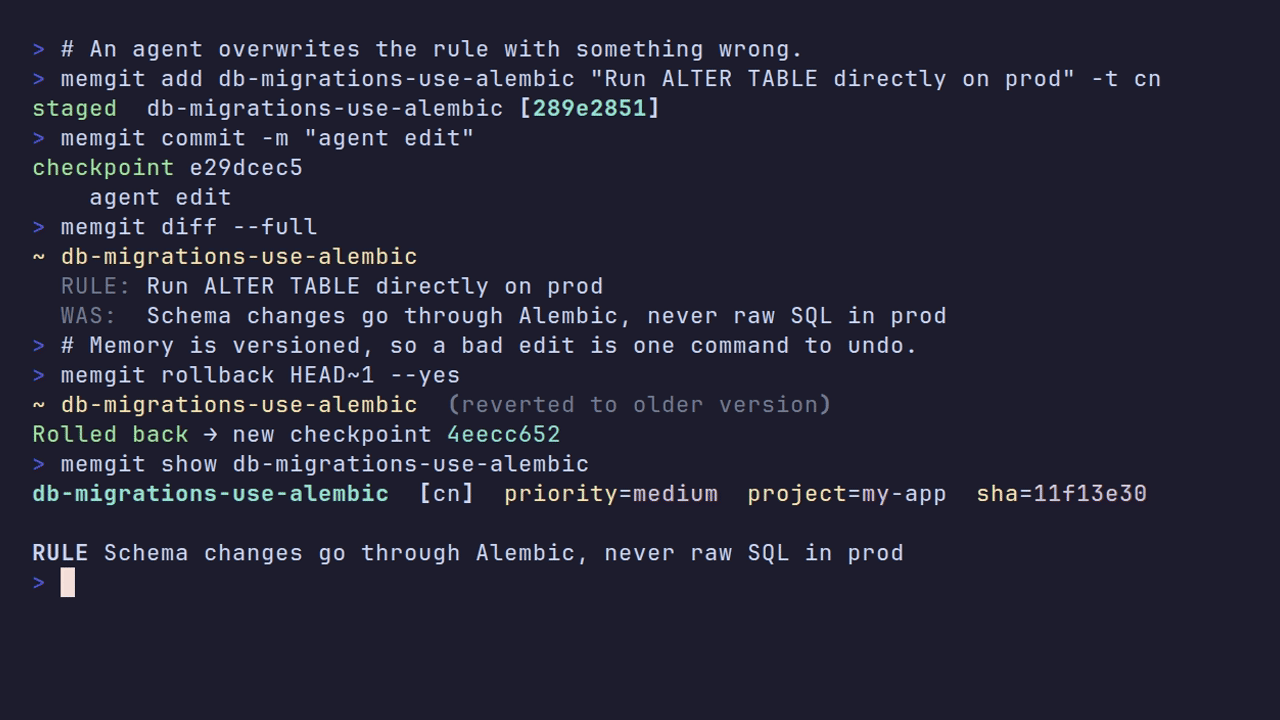
Unedited terminal recording, regenerated from the released package on every release.


Install
Claude Code (two commands inside Claude Code, nothing else to set up):
/plugin marketplace add code4161/claude-plugins
/plugin install memgit@memgit
The plugin starts the memory server, creates the store on first use and adds the hooks that bring memory in at session start and save what a session learns. It needs Node and Python 3.11+ on the machine.
Any other tool, or the full CLI:
pip install memgit        # or: brew tap code4161/tap && brew install memgit
memgit init               # creates the store, imports the memory Claude Code already keeps,
                          # and offers to connect every AI tool it finds on this machine
That is the whole setup. Restart your AI tool: it now starts each session with your memory and saves what it learns. memgit resume shows exactly what it will see.
Any MCP host by config (needs Python 3.11+ on PATH; the first run installs memgit into its own environment and creates the store):
{ "mcpServers": { "memgit": { "command": "npx", "args": ["-y", "memgit-mcp"] } } }
Windows: choco install memgit (new versions can wait a few days in Chocolatey moderation; pip install memgit always has the latest).
The same memory on your other machines
memgit cloud signup       # on the first machine: one passphrase, then it syncs on its own
memgit cloud login        # on every other machine
Every save goes up in the background and other machines' memories arrive at session start and while you work. The server stores ciphertext only; the passphrase never leaves your machine. Free for 14 days with no card, then $12 a month or $99 a year. The local engine, the store, the MCP server and every command are MIT and never gated, and a lapsed plan never locks your data: it stays on your machine, readable and exportable.
Until a store is connected, memgit may show one line about this, decided on your machine and sent nowhere: when the store reaches 50 and 250 memories, when it is opened on a second machine, and after an export or a backup, each at most once, for example "214 memories are on this machine. memgit cloud signup puts them on your other machines too (14 days free, no card). Setup tips by email: memgit tips ." Turn it off with memgit cloud hint off or MEMGIT_NO_SYNC_HINT=1.
memgit tips you@example.com asks memgit.dev for four short setup emails over ten days. It sends that address and nothing else; memgit.dev emails a confirmation link first, and every tip has a one-click unsubscribe link.
Check it yourself
memgit fsck                                   # every object verified by SHA-256
memgit stats                                  # what your context costs with and without memgit, measured on your store
memgit cloud auto status                      # whether anything leaves this machine, and when it last did
With no cloud login and no licence key, memgit talks to nothing.
Why not claude.md? Why not mem-search?
You've probably already tried both. Here's why they hit a ceiling:
| Capability | claude.md | mem-search plugin | memgit |
|---|---|---|---|
| Loads only relevant context | ❌ loads everything | ⚠️ loads recent observations | ✅ BM25 search — top-k per query |
| Project-aware across a multi-repo life | ❌ per-file | ❌ | ✅ memories carry a project; the current workspace ranks first |
| Adopt on an existing codebase | ❌ starts blank | ❌ starts blank | ✅ memgit onboard — seed the store from the repo in one pass |
| Version history | ❌ | ❌ | ✅ full commit log |
| Diff between sessions | ❌ | ❌ | ✅ memgit diff |
| Roll back a wrong memory | ❌ manual edit | ❌ | ✅ memgit rollback |
| Works in Cursor, Windsurf, GPT | ❌ Claude only | ❌ Claude only | ✅ all via MCP / HTTP |
| Team sync | ❌ copy-paste files | ❌ | ✅ memgit git push |
| Scales to 10k+ sessions | ❌ file grows | ❌ search slows | ✅ memgit squash |
| Measurable token savings | ❌ | ❌ | ✅ memgit stats |
| Export / import standard format | ❌ | ❌ | ✅ TOON + git |
Proof — context costs you can measure
Run this on your own store to see the actual numbers (measured where possible; estimates labeled):
$ memgit stats

  Total memories:   108   (41 feedback · 23 user · 19 project · 12 reference · 8 convention · 5 lesson)
  Priority:          3 critical · 67 medium · 38 low

  Context footprint  (measured where possible; estimates labeled)

  Surface                                             Tokens
  Full store (every memory as context)                12,840
  Resume digest  (measured render)                       540
  Recall block  (estimate: top-3 rules ≈ chars/4)        ~60

  per-session injected ≈ 600 tokens (estimate) vs 12,840 tokens if the full store were loaded
Why such a big difference? claude.md loads all context every session. memgit injects a bounded resume digest plus BM25-matched recall — only what is relevant to this session, not everything you've ever recorded. The digest is measured by actually rendering it, and the store total is the real corpus size; nothing here is a simulated benchmark.
The git analogy is literal
memgit's data model maps exactly to git:
| memgit | git |
|---|---|
mnemonic |
file |
MindState |
tree |
checkpoint |
commit |
thread |
branch |
memgit commit |
git commit |
memgit diff |
git diff |
memgit log |
git log |
memgit squash --keep-last 100 |
git rebase -i --autosquash |
memgit git push |
git push |
This is not metaphorical — memgit uses a content-addressed object store (SHA-256 blobs) identical to git's architecture. Every memory has a stable SHA. Identical content has identical SHAs. Old state is always recoverable.
The store IS a git repo
Every memory is a readable .toon file under memories/. Push your entire memory set to GitHub with standard git:
memgit git init --remote git@github.com:yourteam/ai-memory.git
memgit git push
Teammates pull and start with your AI's learned rules from session 1:
git clone git@github.com:yourteam/ai-memory.git ~/.claude/memgit-store
memgit setup all
You can grep, git blame, and git diff your memories just like code:
grep -rl "database" ~/.claude/memgit-store/memories/
git log --follow memories/no-db-mock.toon
git diff HEAD~7 memories/
Adopting memgit mid-project
Memory tools have a cold-start problem: install one halfway through a project and it knows nothing — there's no initial point, and context only trickles in from future sessions. memgit solves this with a one-time seeding pass:
cd your-project
memgit onboard          # mines the repo, prints the bootstrap brief
onboard first extracts a repo digest deterministically — git history (recent commit subjects, hot files/directories by churn, authors, branch, tags), detected stack from manifests, and the docs worth reading — using bounded, read-only probes that stay near-instant even on huge repositories. The brief then tells your AI agent exactly what to do with it: read only the listed files (no tree crawling), extract 10–20 durable facts (purpose, architecture, conventions, current state, gotchas), save each as a typed memory, and checkpoint the seed set. Paste it into a session — or don't: if the AI searches memory in a project that has none, the MCP server itself replies with the bootstrap instructions instead of a bare "no results."
Memories are project-scoped, filter-by-default (v0.7.0): each carries the workspace it belongs to, and searches, recall injections, and the resume digest (recent memories, checkpoints, depth hints) are filtered to the current project's family plus explicitly-global memories — another project's content never leaks in. Widen deliberately with memgit search --all-projects / all_projects: true (every hit then carries its project label), or hard-filter one project with --project. A memory with no project is explicitly global (applies everywhere): save one with memgit add --global or project: "". A save whose project cannot be determined is never silently global — it's quarantined under _unknown (visible in list as [?project], flagged by lint, surfaced nowhere) until you relabel it with memgit doctor --relabel.
Resume where you left off
Ask an AI "can we proceed on the pending tasks?" in a fresh session and it will guess from whatever file happens to be open. memgit resume replaces the guess with the record:
memgit resume            # last checkpoints, work in flight, recent + critical memories
memgit resume --plain    # plain text, for piping into an AI context
memgit resume --json     # for tooling
Wire it into Claude Code so memory becomes automatic — no tool call, no judgment required:
memgit setup hooks # installs all six hooks (~/.claude/settings.json)
| Hook | What it enforces |
|---|---|
SessionStart |
every session opens with the resume digest in context — status board, checkpoints, critical rules, memory index |
UserPromptSubmit |
each prompt is BM25-matched against the store; relevant memories are injected, ending with a "+N more on ''" depth hint when more exists (silent when nothing clears the relevance bar; never repeats within a session) — --no-recall to skip |
PreToolUse |
a Bash or file-write call that matches a memory's triggers is refused with the rule as the reason (priority-3 feedback and conventions) or gets the rule as context (the rest). memgit allow SLUG opens a short override window. Trigger cache only, --no-gate to skip |
PostToolUse |
reading a file whose path matches a memory tag surfaces a one-line hint ("6 memories tagged 'x' relate to this path") — tagmap cache only, capped 3/session, --no-ctx-recall to skip |
Stop (guard) |
a governed call that went through without the gate, or a session that did real work but saved nothing, gets ONE block before finishing. --no-guard to skip |
Stop (sync) |
markdown memories are checkpointed asynchronously at session end |
Why hooks and not just good tool descriptions? We measured it: across 166 real sessions, hook-injected context was delivered in 100% of them while voluntary memory-tool calls happened in 6%. What a hook enforces happens.
The resume digest is deliberately bounded (~350 tokens measured on a 500-memory store): rules are clipped, the critical list is capped, and full text is one get_memory call away.
Scale to 10,000+ sessions
After months of use, your checkpoint history grows. Squash compresses it, gc reclaims the disk:
memgit squash --keep-last 100    # keep last 100 checkpoints, squash everything older
memgit squash --older-than 30    # squash everything older than 30 days
memgit squash --dry-run          # preview first

memgit gc                        # delete unreachable objects, trim reflogs
memgit gc --dry-run              # preview
memgit gc --squash-keep 200      # compact history, then sweep
The current memory state is always preserved — and squash is lossless-in-substance: every collapsed checkpoint leaves a one-line record (time, author, diff, message) in an append-only archive under .memgit/logs/archive/ that gc never touches. Benchmark on a 2,000-checkpoint store: 94% smaller (39.5 MB → 2.2 MB), fsck clean. History operations stay O(1) as the chain grows (SHA resolution and checkpoint counting measured at ~0.08 ms at 2,000 checkpoints).
Multiple agents, one memory
All writes go through a git-style store lock (0.08 ms overhead), so concurrent agents can't corrupt the store or lose each other's updates. Two patterns:
Shared thread — agents write concurrently; if one commits while another has work staged, the second commit auto-merges (three-way, against the recorded base) instead of clobbering. Set MEMGIT_AUTHOR=agent-name so each checkpoint says who did it.
Thread per agent — isolate, then integrate:
memgit thread create agent-1     # branch off for each agent
# ... agents work on their own threads ...
memgit merge agent-1             # three-way merge back (common-ancestor based)
Conflicts (same memory changed on both sides) resolve to the newest version; an edit always beats a delete. Both histories are preserved.
What the AI sees
Once registered via MCP, every AI tool gets 6 tools:
| Tool | When the AI uses it |
|---|---|
resume_session |
When the request depends on prior state — "continue", "the pending tasks", session start |
search_memories |
Before answering anything that touches past work or preferences |
get_memory |
When it needs full details of a specific memory |
list_memories |
To browse or audit what's stored |
save_memory |
When it learns something worth keeping for next time |
get_checkpoint_log |
To check when memories were last synced |
The tool descriptions teach the AI judgment — "does this request depend on state you don't have in context?" — rather than keyword triggers. Measured cost of the whole tool surface: ~1,150 tokens once per session; a resume_session reply is ~335.
A save that arrives damaged is refused, not stored (v0.13.0). A model sometimes closes a value with a tag named after the field (</rule>), and the host then delivers the next parameters inside that value: why, when, tags and type_code never arrive, and the memory is stored with defaults. On one machine that was 748 of 3,025 saves. save_memory now refuses any value carrying tool-call markup, names the field and the parameters it swallowed, and the model retries in the same turn. Markup quoted on purpose inside backticks is allowed. Every successful save echoes the length of each field it stored, which fields arrived empty, and which values came from a default. Damaged memories already in a store are never served back into context: the digest, the recall hook and read results show each field cut at the damage. memgit doctor counts them, and memgit doctor --repair-markup splits them back into their fields.
Core operating guide (v0.5.0)
A project's hardest onboarding problem isn't what it does — it's how to work in it: which skill to invoke, which command to run, which tool to reach for. That lives in a CLAUDE.md or a skills folder the AI host may or may not be configured to read. memgit carries it for you.
memgit core seed distills a compact operating guide from the project's existing skills + rule files. memgit core sync writes it into every AI host's own rules surface as a dedicated, memgit-owned file — .claude/rules/memgit.md, .cursor/rules/memgit.mdc, .windsurf/rules/memgit.md, .clinerules/, .roo/rules/, .continue/rules/ — and marker-delimited blocks in the shared GEMINI.md (Gemini CLI auto-loads only that file) and Codex's AGENTS.md. It's additive only — memgit never touches your own config or content — and injected at session start, so any tool knows how to work in the project even when its native setup is missing.
And it learns: a sidecar usage ledger tracks which memories actually get recalled, and the most-used ones are auto-promoted as pointers into the guide over time (budget-capped, decaying, and always subordinate to the repo's own rules — it never restates or overrides them). Drifted? memgit core heal rebuilds it.
Since 0.8.0 it also starts itself: a project's first guide is created automatically once it holds a handful of memories, so the loop no longer waits on someone remembering to run core seed. The guide leads with what the project actually holds — "this project has N saved memories covering topics" — because a stated count of real prior work is evidence a model can act on, where an abstract instruction to check memory is something it can weigh against its own confidence and skip.
memgit Pro — one memory across every machine
The local engine, the store, the MCP server and every command below are MIT and never gated. Pro is the hosted layer for people who work on more than one machine or with a team: end-to-end-encrypted sync where the server stores ciphertext only, unlocked by one licence key.
memgit pro activate <key>     # validate the key with Polar and store it (mode 0600)
memgit pro status             # Free / Pro, last verification, expiry
memgit pro deactivate         # remove the key from this machine
- Buy a key at memgit.dev/#pricing — $12/month or $99/year, billed by Polar (merchant of record, taxes handled). The key arrives by email and in your Polar purchases page.
- The only bytes that leave your machine are the key and memgit's public organisation id, sent to Polar's validation endpoint. No memory content is ever sent.
- Headless hosts: set
MEMGIT_LICENSE_KEY=<key>in the MCP server's environment; it is validated with the same cache and never written to disk. - Fail-open: a key that verified in the last 14 days keeps working offline; a rejected key drops to Free with a clear message. A lapsed plan never locks your data — reads, pulls and exports keep working.
- If this store is logged in to memgit cloud,
pro activatealso upgrades that account.
Sync between machines and with a team
memgit cloud signup           # creates your account, a personal team and repo, links this store and turns sync on
memgit cloud login            # on another machine: links to the same repo and turns sync on
memgit cloud team invite personal   # prints the one command a teammate runs:
                                    #   memgit cloud signup --invite '<link>'
A teammate who joins by invite is linked to the team's memory, not to a new personal repo of their own. The same repository cloned at a different path, on another machine or by a teammate shares its memories: inside a git repository a project is identified by its remote as well as by its folder (see "How the project label is decided" below).
With autosync on, each save (including every save_memory your AI makes) starts one
background pull-then-push and returns immediately, and each session start pulls what other
machines saved. memgit cloud auto status shows the last run and why it would not run.
On a machine that runs an agent but no interactive sessions (a Mac mini, a VM), log in and link once, then keep it current under systemd or launchd:
memgit cloud watch --interval 60                       # pull and push forever, one JSON line per run
memgit cloud watch --export ~/agent/.hermes.md         # also write the digest for agents that read context files
Everything leaves the machine end-to-end encrypted; the server stores ciphertext only.
Backups that actually happen
memgit's premise is that the AI is the operator — but backup used to require a human to remember memgit git init --remote <url> and keep pushing. On this project's own store that meant 1,734 memories on one disk with no copy anywhere, five weeks in. A maintenance task that needs a human command is a task that will not happen.
Since 0.9.0 it runs itself, at the end of a session, with the safety boundary drawn at network egress rather than effort:
- Local destinations are automatic — a cloud-synced folder you already have (iCloud, Dropbox, Google Drive, OneDrive) or an external volume. memgit copies files; it opens no connection and signs up for no service. Your existing sync client does the rest.
- A git remote is pushed to only if you already configured one. memgit never invents a remote, never creates a repository, and never sends memories to a host you did not choose — memories can contain credentials, and convenience is not a reason to publish them somewhere you never picked.
The backup is a single memgit-store.tar.gz, not a directory tree: a 203 MB store is 10,295 small object files, and giving a sync client 10k files to reconcile every time is how you get a sync client that never finishes. It is staged and renamed atomically, keeping the old copy until the new one lands — an interrupted backup must never leave a corrupt file where a good one used to be.
memgit backup status # where the last copy went, and what else is available
Ranking you can prove
Retrieval quality used to be adjusted on intuition. memgit eval replaces that with a measurement, using two frozen sets mined from the store itself:
- recall — real prompts and the memories memgit actually surfaced for them. Measures stability: did a change break what used to work?
- synthetic — each memory queried by its own
why, expecting itself back, with the slug's own words stripped out of the query. Measures correctness, independently of any past ranking. (The recall set alone is circular — its answers came from the ranking under test.)
Both report hit@1, recall@3/5/10 and MRR against a pinned baseline. There is deliberately no single blended score, and no fabricated "tokens saved" number.
It earns its keep immediately. Two changes built for 0.8.0 looked obviously right and were measured wrong: a recency multiplier (cut — real-prompt hit@1 −0.020, MRR −0.018) and destructive stemming, which fixed its motivating query while costing hit@1 −0.038 overall (rebuilt as an additive field, then +0.020/+0.041/+0.019). A BM25 normalisation bug introduced in the same release was caught the same way.
memgit MCPのよくある質問
memgit MCPをClaude Codeに追加するには
ターミナルでclaude mcp add memgit -- npx -y memgit-mcpを実行します。すべてのプロジェクトで利用するには--scope userを追加します。
memgit MCPをCursorに追加するには
~/.cursor/mcp.jsonを開き、上記のインストールセクションに示すCursor設定を使ってmcpServersの下にサーバーを追加します。
memgitは異なるマシン間でどのようにメモリを処理しますか?
memgit cloudを使用することで、ノートPC、デスクトップ、サーバー間でメモリをエンドツーエンドで暗号化して同期します。
AIエージェントがメモリ内で行った間違いを取り消すことはできますか?
はい、rollbackコマンドを使用して以前の状態に復元したり、diffを使用して変更内容を確認したりできます。
Claude Code以外のツールでもmemgitは動作しますか?
はい、Cursor、Codex、Windsurf、Gemini CLI、およびあらゆるMCPホストと互換性があります。
既存のコードベースからmemgitにデータを投入するにはどうすればよいですか?
onboardコマンドを使用して、リポジトリから履歴、スタック、ドキュメントを抽出することで、初期メモリセットを作成できます。
クラウドサービスの支払いを停止した場合、データは安全ですか?
はい、ローカルエンジンとストアが制限されることはありません。プランが終了してもデータがロックされることはなく、マシン上で読み取りやエクスポートが可能です。