
Ermöglicht es AI Agents, Web Scraping, semantische Suche und Deep Research mittels SearXNG, Tavily und Crawl4AI durchzuführen.
Auch bekannt als waiky-github/CrawlEyes, crawleyes
- Stars
- 2
- Tools
- 4
- Downloads, 30 Tage
- 126
- Neueste Version
- 0.2.0
- Letzter Commit
- 22. Okt. 2026
- Lizenz
- MIT
Was ist CrawlEyes MCP?
Ermöglicht es AI Agents, Web Scraping, semantische Suche und Deep Research mittels SearXNG, Tavily und Crawl4AI durchzuführen. Er stellt 4 Tools bereit, etwa search, extract, sitemap.
Zusammenfassung generiert aus dem README des Projekts
Über CrawlEyes MCP server
CrawlEyes gibt AI Agents die Fähigkeit, das Web zu sehen und zu lesen, indem es ein einheitliches Toolkit für Scraping und Suche bereitstellt. Es fungiert als standardmäßiger MCP server, der über stdio oder Remote-Verbindungen via streamable-http mit Clients wie Claude Desktop oder Cursor verbunden werden kann. Das System integriert SearXNG für eine datenschutzorientierte Suche mit einem schlüssellosen Tavily-Fallback, um Zuverlässigkeit zu gewährleisten, ohne dass externe Accounts oder API-Keys erforderlich sind.
Entwickler können den Server nutzen, um Deep Research zu betreiben, Seitenstrukturen über Sitemap-Tools zu entdecken oder sauberes Markdown aus dynamischen Webseiten zu extrahieren. Die Extraction Engine nutzt Crawl4AI, um etwa 89% des Page-Noise wie Werbung und Navigationselemente zu entfernen, wodurch der Content direkt für RAG-Workflows bereitsteht. Zudem bietet es lokales semantisches Reranking mittels fastembed, um die relevantesten Suchergebnisse zu priorisieren, ohne schwere Abhängigkeiten wie torch zu benötigen.
Was du damit machen kannst
- 1Sauberen Content für RAG extrahierenKonvertiere unübersichtliche Webseiten in bereinigtes, LLM-ready Markdown, indem Werbung und Navigation entfernt werden.
- 2Suchen ohne API-KeysFühre Web-Suchen über eine selbst gehostete SearXNG-Instanz mit einem automatischen Fallback auf Tavily aus.
Geschrieben aus dem README des Projekts. Jeder Use Case wurde gegen ein Zitat daraus geprüft.
So installierst du CrawlEyes MCP
Formate geprüft am 10. Nov. 2026Zu Cursor hinzufügenZu Goose hinzufügenCrawlEyes MCP in Claude Code installieren
$ claude mcp add --env 'TAVILY_API_KEY=<YOUR_TAVILY_API_KEY>' crawleyes -- uvx --from crawleyes crawleyes-mcpCrawlEyes MCP in Cursor installieren
~/.cursor/mcp.json
{
  "mcpServers": {
    "crawleyes": {
      "command": "uvx",
      "args": [
        "--from",
        "crawleyes",
        "crawleyes-mcp"
      ],
      "env": {
        "TAVILY_API_KEY": "<YOUR_TAVILY_API_KEY>"
      }
    }
  }
}CrawlEyes MCP in VS Code installieren
.vscode/mcp.json
{
  "servers": {
    "crawleyes": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "--from",
        "crawleyes",
        "crawleyes-mcp"
      ],
      "env": {
        "TAVILY_API_KEY": "<YOUR_TAVILY_API_KEY>"
      }
    }
  }
}CrawlEyes MCP in VS Code CLI installieren
$ code --add-mcp '{"name":"crawleyes","type":"stdio","command":"uvx","args":["--from","crawleyes","crawleyes-mcp"],"env":{"TAVILY_API_KEY":"<YOUR_TAVILY_API_KEY>"}}'CrawlEyes MCP in Claude Desktop installieren
claude_desktop_config.json
{
  "mcpServers": {
    "crawleyes": {
      "command": "uvx",
      "args": [
        "--from",
        "crawleyes",
        "crawleyes-mcp"
      ],
      "env": {
        "TAVILY_API_KEY": "<YOUR_TAVILY_API_KEY>"
      }
    }
  }
}CrawlEyes MCP in Codex installieren
$ codex mcp add crawleyes --env 'TAVILY_API_KEY=<YOUR_TAVILY_API_KEY>' -- uvx --from crawleyes crawleyes-mcpCrawlEyes MCP in Codex config.toml installieren
~/.codex/config.toml
[mcp_servers.crawleyes]
command = "uvx"
args = ["--from", "crawleyes", "crawleyes-mcp"]

[mcp_servers.crawleyes.env]
TAVILY_API_KEY = "<YOUR_TAVILY_API_KEY>"
CrawlEyes MCP in Gemini CLI installieren
$ gemini mcp add -s user -e 'TAVILY_API_KEY=<YOUR_TAVILY_API_KEY>' crawleyes uvx -- --from crawleyes crawleyes-mcpCrawlEyes MCP in Gemini settings.json installieren
~/.gemini/settings.json
{
  "mcpServers": {
    "crawleyes": {
      "command": "uvx",
      "args": [
        "--from",
        "crawleyes",
        "crawleyes-mcp"
      ],
      "env": {
        "TAVILY_API_KEY": "<YOUR_TAVILY_API_KEY>"
      }
    }
  }
}Von HostedMCP gestartet am 16. Nov. 2026
Wir haben diesen Befehl für crawleyes 0.2.0 in einem isolierten Container ohne Netzwerk und ohne Schlüssel ausgeführt. Er hat geantwortet und 4 Tools gelistet.
CrawlEyes MCP tools 4
Vom Server mit tools/list gelesensearch搜索网页。SearXNG 优先,失败自动 fallback Tavily keyless(无需 API key)。 带统一限流 + 指数退避重试(最多 3 次)。 limit 会被 clamp 到 [1, 20],防止传超大值打爆下游。 Returns JSON with title/url/description for each result.
extract抓取网页正文为 Markdown。自动去噪(过滤导航/广告),失败自动重试。 返回前会剥离隐藏文字 + 标记可疑注入,防止 prompt-injection 劫持 Agent。 respect_robots=True 时先检查目标站 robots.txt (RFC 9309),被 Disallow 则拒绝。 format: markdown(默认) | fit | raw | markdown_with_citations。 Returns JSON with title/markdown/length.
sitemap发现站点 URL 地图。解析 {origin}/sitemap.xml(支持 index/gzip), 缺失时回退 robots.txt 的 Sitemap 声明。返回去重后的 URL 列表 JSON。 用于整站抓取 / deep_research 扩 URL 源。带统一限流。
deep_research深度调研:把主题拆成子问题→搜索→抓取→合成带引用的报告。 Uses SearXNG → Tavily keyless (no API key). Optional LLM synthesis via CRAWLEYES_LLM_* env vars; without them returns an evidence-aggregate report. Returns JSON with report (Markdown) + sources.
| search | 搜索网页。SearXNG 优先,失败自动 fallback Tavily keyless(无需 API key)。 带统一限流 + 指数退避重试(最多 3 次)。 limit 会被 clamp 到 [1, 20],防止传超大值打爆下游。 Returns JSON with title/url/description for each result. | |
| extract | 抓取网页正文为 Markdown。自动去噪(过滤导航/广告),失败自动重试。 返回前会剥离隐藏文字 + 标记可疑注入,防止 prompt-injection 劫持 Agent。 respect_robots=True 时先检查目标站 robots.txt (RFC 9309),被 Disallow 则拒绝。 format: markdown(默认) | fit | raw | markdown_with_citations。 Returns JSON with title/markdown/length. | |
| sitemap | 发现站点 URL 地图。解析 {origin}/sitemap.xml(支持 index/gzip), 缺失时回退 robots.txt 的 Sitemap 声明。返回去重后的 URL 列表 JSON。 用于整站抓取 / deep_research 扩 URL 源。带统一限流。 | |
| deep_research | 深度调研:把主题拆成子问题→搜索→抓取→合成带引用的报告。 Uses SearXNG → Tavily keyless (no API key). Optional LLM synthesis via CRAWLEYES_LLM_* env vars; without them returns an evidence-aggregate report. Returns JSON with report (Markdown) + sources. |
Konfiguration
TAVILY_API_KEYSecretOptional. Tavily API key for higher-rate search fallback. If unset, uses Tavily keyless (rate-limited).
PLAYWRIGHT_DOWNLOAD_HOSTSEARXNG_URLOptional. Base URL of a SearXNG instance (e.g. http://localhost:8080). If unset, falls back to Tavily keyless.
| Name | Beschreibung | Typ |
|---|---|---|
| TAVILY_API_KEY | Optional. Tavily API key for higher-rate search fallback. If unset, uses Tavily keyless (rate-limited). | Secret |
| PLAYWRIGHT_DOWNLOAD_HOST | — | |
| SEARXNG_URL | Optional. Base URL of a SearXNG instance (e.g. http://localhost:8080). If unset, falls back to Tavily keyless. |
Automatisierte Checks
Geluften am 13. Nov. 2026Vollständiger Bericht →Unsere automatisierten Checks bestanden. Das ist kein Security-Audit: Lies den Code und gib dem Server nur den minimal notwendigen Zugriff. Wie die Checks funktionieren

- Source Repository verknüpft und erreichbarBestanden
- Open Source Lizenz (OSI)Bestanden
- Commit oder Release im letzten JahrBestanden
- Package-Name ähnelt keinem populären PackageBestanden
- Remote Endpoint nutzt HTTPSNicht geprüft
- Destruktive Tools sind markiertNicht geprüft
- Keine versteckten Anweisungen an das ModellBestanden
- Keine kritischen Advisories im Paket oder seinen AbhängigkeitenBestanden
README
Auf GitHub ansehenCrawlEyes — Web Scraping & Search Toolkit for AI Agents
English | 中文


CrawlEyes gives AI agents reliable full-text extraction (web_extract) and robust search (web_search) backends — the "eyes" that let agents see and read the web. Built and tested against Hermes Agent.
Also ships as a standard MCP server, so any MCP client (Claude Desktop, Cursor, other agents) can reuse the same search + extraction capabilities.
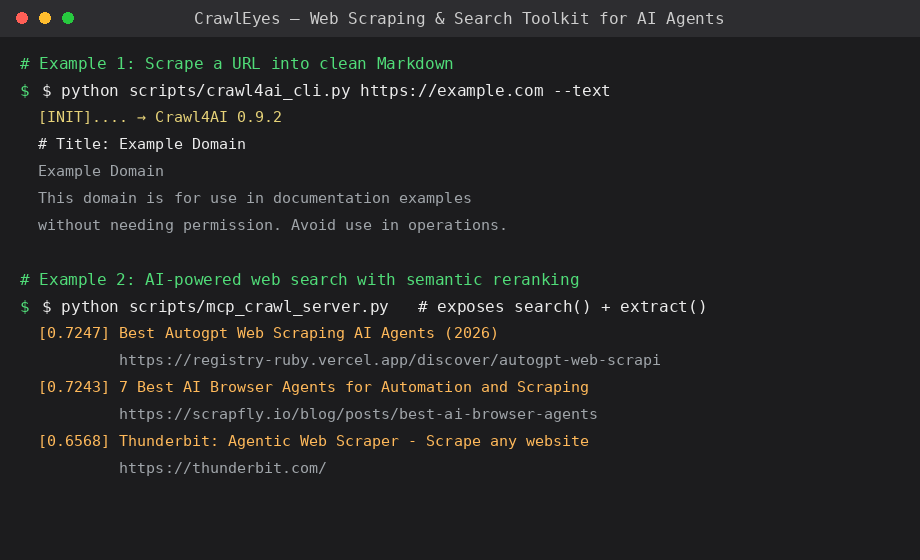
Why CrawlEyes?
Most agent toolkits cover one slice of the pipeline. CrawlEyes is the rare all-in-one that you can actually run behind the Great Firewall without external accounts.
| Typical agent toolkit | CrawlEyes | |
|---|---|---|
| 🔍 Search | API key required, often blocked in CN | ✅ SearXNG (self-hosted) + Tavily keyless fallback — zero config, zero key |
| 📄 Extraction | Separate scraper, or Firecrawl SaaS | ✅ Built-in Crawl4AI full-text extract, ~89% noise removal |
| 🧠 Semantic rerank | Rarely included | ✅ Local fastembed rerank — no torch, ~50MB model |
| 🔌 MCP server | Often missing | ✅ Standard MCP tools (search + extract + deep_research + sitemap), any client |
| 🌐 China-friendly | Mostly English/GFW-blocked | ✅ Tested on a real mainland China server (baidu + yandex) |
Zero API keys. Zero external accounts. One command. CrawlEyes is the only toolkit in this space that combines search + extraction + semantic reranking + MCP in a single, China-friendly, self-hosted package.
Features
| Capability | Where | Why it matters |
|---|---|---|
| Full-text extraction | scripts/crawl4ai_cli.py |
Headless-browser scraping → clean Markdown; handles ~80% of JS/dynamic/UA-blocked pages |
| Content denoising (P1) | crawl4ai_cli.py --noise-filter |
Prunes nav/ads/comments via Crawl4AI's PruningContentFilter — measured 24.6k→2.8k chars (~89% noise removed) on a typical article |
| Retry with backoff (P3) | crawl4ai_cli.py --retry N |
Exponential backoff (1s/2s/4s) on transient failures |
| Browser session reuse (P4) | crawl4ai_cli.py --session NAME |
Reuses the browser context across scrapes in one process — no cold-start per URL |
| Keyword-focused extraction | crawl4ai_cli.py --bm25 KEYWORD |
Keeps only paragraphs relevant to a keyword (experimental — BM25 is English-centric; works best on English docs) |
| Search (primary) | SearXNG (self-hosted meta-search) | Privacy-friendly search aggregator |
| Search (fallback) | Tavily keyless API | Zero-config, no-key fallback when SearXNG is down/empty |
| Search orchestration | plugins/searxng-tavily/ |
Hermes plugin provider: SearXNG first → auto-fallback to Tavily keyless; three-state circuit breaker (3 fails → 60s cooldown → half-open) + shared SQLite cache (TTL 3600s) |
| Semantic reranking (P2) | scripts/crawl_search_standalone.py |
Local embedding rerank of search results with fastembed + BAAI/bge-small-zh-v1.5 (512-dim, no torch dependency, ~50MB, cached) — puts relevant results first. Measured: crawler-relevant items 0.817/0.732 float to top, irrelevant 0.302/0.139 sink |
| MCP server (P5) | scripts/mcp_crawl_server.py |
Exposes search + extract + deep_research + sitemap as standard MCP tools (stdio default, or streamable-http for remote clients). Works in any MCP client, no Hermes dependency. Extracted content is sanitized against prompt-injection (strips invisible chars + prompt-hijack lines). Unified rate limiting + exponential backoff guard every tool (sliding window, per-tool cost) so concurrent agent calls can't hammer downstream services |
| Sitemap discovery (P1) | crawleyes/sitemap.py |
sitemap(origin) → parses sitemap.xml (plain / gzip / index-recursion) with robots.txt fallback, returns a deduped URL map. Zero-key way to discover a site's URL surface for whole-site fetch or deep-research seeding |
| Multi-format extract (P0) | extract(..., format=) |
markdown (default) / fit (denoised) / raw (unfiltered) / markdown_with_citations — pick the level of cleanup you need |
| RAG-ready interfaces | crawleyes/rag.py |
One-liners markdown(url) / search_markdown(query) → clean, sanitized, LLM-ready Markdown for RAG corpora |
| Deep research | crawleyes/deep_research.py |
deep_research(topic) → decomposes topic into sub-questions → searches → extracts → synthesizes a cited Markdown report. Optional LLM (any OpenAI-compatible endpoint); degrades to evidence-aggregate mode without one |
| Verification | scripts/ |
Clean subprocess scripts to verify each backend end-to-end per Hermes profile |
Project layout
plugins/searxng-tavily/   Hermes web-search provider plugin (SearXNG → Tavily keyless fallback)
                          + three-state circuit breaker + shared SQLite cache
scripts/
  crawl4ai_cli.py          Universal scraping CLI (URL → Markdown), with denoise/retry/session/BM25
  crawl_search_standalone.py  Standalone search (SearXNG → Tavily) + optional semantic rerank.
                             No Hermes dependency — usable anywhere, powers the MCP server.
  mcp_crawl_server.py      Standard MCP server exposing search + extract + deep_research + sitemap (stdio)
  single_env_check.py      Verify crawl4ai provider registered+available+extracts (one profile)
  verify_searxng_tavily.py Verify searxng-tavily provider: normal path + forced fallback
  agent_link_check.py      Verify full agent tool chain: web_search_tool dispatch + logs
Quick start
1. Install Crawl4AI (China-friendly mirrors)
python3 -m venv .venv
# Use Tsinghua PyPI mirror for speed (or any mirror you prefer)
.venv/bin/pip install -i https://pypi.tuna.tsinghua.edu.cn/simple crawl4ai
# Playwright browser kernel — use npmmirror binary mirror if cdn.playwright.dev is blocked
PLAYWRIGHT_DOWNLOAD_HOST=https://registry.npmmirror.com/-/binary/playwright \
  .venv/bin/python -m playwright install chromium
.venv/bin/crawl4ai-setup
2. Scrape a page
.venv/bin/python scripts/crawl4ai_cli.py https://example.com          # stdout Markdown
.venv/bin/python scripts/crawl4ai_cli.py https://example.com -o out.md  # to file
.venv/bin/python scripts/crawl4ai_cli.py URL --text --max-words 5000   # plain text, truncated

# Multi-format extraction (markdown|fit|raw|markdown_with_citations)
.venv/bin/python scripts/crawl4ai_cli.py URL --format raw              # unfiltered source markdown
.venv/bin/python scripts/crawl4ai_cli.py URL --format markdown_with_citations  # + source URLs

# Respect robots.txt (opt-in, default off)
.venv/bin/python scripts/crawl4ai_cli.py URL --respect-robots

# Denoise nav/ads + retry 3x + reuse session across scrapes
.venv/bin/python scripts/crawl4ai_cli.py URL --noise-filter --retry 3 --session s1
3. Use the search + rerank (standalone, no Hermes)
# Optional: local semantic rerank of results (fastembed + bge-small-zh, auto-downloaded)
.venv/bin/pip install -i https://pypi.tuna.tsinghua.edu.cn/simple fastembed

# SearXNG first, Tavily keyless fallback, then rerank
SEARXNG_URL=https://your-searxng .venv/bin/python -c "
import sys; sys.path.insert(0, 'scripts')
from crawl_search_standalone import CrawlSearch
r = CrawlSearch(rerank=True).search('your query')
print(r['data']['web'])"
China-network note: the embedding model downloads from HuggingFace, which is blocked on mainland networks. Set
HF_ENDPOINT=https://hf-mirror.comandHF_HUB_DISABLE_XET=1(hf-mirror doesn't support the xet protocol and returns 401 without this).
4. Run as an MCP server (any client)
# Any MCP client can connect via stdio (default):
.venv/bin/python scripts/mcp_crawl_server.py
# Exposes tools:
#   search(query, limit)                 - SearXNG → Tavily keyless, rerank, retry+rate-limit
#   extract(url, max_words, format)      - markdown|fit|raw|markdown_with_citations
#   deep_research(topic, num_questions)  - multi-round cited report
#   sitemap(origin, max_urls)            - URL map from sitemap.xml / robots.txt

# Or serve over HTTP (streamable-http) for remote clients:
.venv/bin/python -m crawleyes.mcp_crawl_server --transport http --port 8765 --host 127.0.0.1
#   → clients connect to http://127.0.0.1:8765/mcp
#   (host/port configurable; default 127.0.0.1:8765)
For Hermes specifically, add to config.yaml:
mcp_servers:
  crawl:
    command: "/path/to/crawl/.venv/bin/python"
    args: ["/path/to/crawl/scripts/mcp_crawl_server.py"]
    timeout: 90
    connect_timeout: 60
4b. Firecrawl-compatible /scrape endpoint
Already using Firecrawl's Python SDK? Point it at CrawlEyes and keep your code:
.venv/bin/python -m crawleyes.firecrawl_api --port 8899 --host 127.0.0.1
#   POST /v2/scrape  →  { success, data: { markdown, metadata } }
#   GET  /healthz    →  health check
from firecrawl import Firecrawl
fc = Firecrawl(api_url="http://127.0.0.1:8899", api_key="ignored")
doc = fc.scrape(url="https://example.com")   # → { markdown, metadata }
This is a pragmatic subset of the Firecrawl API — the core /scrape contract
(success + data.markdown + data.metadata), backed by CrawlEyes' own
extraction engine. It does not implement Firecrawl's async /crawl queue,
/search, or /map — see the design notes for the rationale.
5. Install the search plugin (Hermes)
Copy plugins/searxng-tavily/ into a Hermes plugins dir, then:
hermes plugins enable web/searxng-tavily
hermes config set web.search_backend searxng-tavily
Set SEARXNG_URL in your Hermes profile .env to point at your SearXNG instance. If unset or unreachable, the provider automatically falls back to the Tavily keyless API (no API key required).
Note: the plugin only takes effect for newly started agent sessions.
6. Verify
# Requires the Hermes source tree + its venv
venv/bin/python scripts/verify_searxng_tavily.py $HERMES_HOME
venv/bin/python scripts/agent_link_check.py $HERMES_HOME
Design notes
- Layered composition: no single tool covers everything. Crawl4AI handles extraction; SearXNG + Tavily cover search; each layer has a tested fallback.
- Tavily keyless works with zero configuration and no account — a cheap resilience net for the whole search path.
- Circuit breaker is SearXNG-only: a Tavily fallback success does not reset the breaker (otherwise it would never trip).
record_success()is only called when SearXNG itself succeeds. - Shared SQLite cache lives in the real user home (via
pwd.getpwuid, not$HOME— which Hermes profiles override), so all profiles share one cache. WAL + 5s timeout + try/except degrade-to-no-cache under concurrency. - Semantic rerank is cheap: fastembed (ONNX) avoids the ~2GB torch dependency; model loads in ~0.6s once cached, embeddings in ~50ms.
- MCP server is standalone: it does not import Hermes internals, so it runs on any Python 3.12 env and serves any MCP client.
- MCP transport is dual: stdio (default, standard MCP clients) or
streamable-http(--transport http), so a single codebase serves both local process and remote HTTP clients. - Unified rate limiting is layered: MCP tools and deep-research's internal search/extract all share one sliding-window limiter (per-tool cost), so concurrent agent fan-out can't hammer SearXNG/Tavily/Crawl4AI even through multi-round deep research.
Credits & inspiration
This project builds on a set of excellent open-source tools. All code here is an independent implementation (no copied code), but the ideas and interfaces are drawn from the following projects — full credit to their authors:
| Feature in this repo | Inspired by | License |
|---|---|---|
| Extraction engine (Crawl4AI wrapper) | Crawl4AI — direct dependency | Apache-2.0 |
| Content denoising (P1) | Readability, GeneralNewsExtractor (idea) | Apache-2.0 / MIT |
| Semantic reranking (P2) | Vane, Perplexica (idea) | MIT / MIT |
| Retry with backoff (P3) | Crawlee (idea) | Apache-2.0 |
| Browser session reuse (P4) | camoufox (idea) | MIT |
| MCP server (P5) | playwright-mcp, exa-mcp-server (idea) | Apache-2.0 / MIT |
| Search orchestration / fallback | SearXNG — self-hosted (official Docker image, no source modification), accessed via HTTP API only · Tavily keyless | AGPL-3.0 (server software, not linked/embedded) / proprietary API |
Design independence: the implementations here are written from scratch — we studied the above projects' approaches (denoising thresholds, rerank pipelines, backoff strategies, MCP tool patterns) but did not copy their source code. Dependencies are declared in
requirements.txt. If you believe any attribution is missing or incorrect, please open an issue.
Compliance
CrawlEyes is a general-purpose fetch toolkit for legitimate research and personal use. It deliberately does not include proxy pools, fingerprint rotation, or CAPTCHA-solving (anti-scraping evasion) — those are out of scope.
Robots.txt is opt-in (default off): pass respect_robots=True to extract / markdown (or --respect-robots on the CLI) to check each target's robots.txt (RFC 9309) and refuse URLs it explicitly disallows. It's default-off so legitimate scraping isn't silently blocked by aggressive or broken robots rules — compliance is the caller's informed choice per use case. Always review each site's terms of service before scraping at scale.
License
MIT — see LICENSE.
📮 关注我们
公众号:AI Aperture —— 分享 AI 工程实践、多 Agent 系统与开源项目经验。
扫码关注,获取项目更新与更多技术内容。
CrawlEyes MCP Fragen
Wie füge ich CrawlEyes MCP zu Claude Code hinzu?
Führe claude mcp add --env 'TAVILY_API_KEY=<YOUR_TAVILY_API_KEY>' crawleyes -- uvx --from crawleyes crawleyes-mcp in deinem Terminal aus. Füge --scope user hinzu, damit der Server in jedem Projekt verfügbar ist.
Wie füge ich CrawlEyes MCP zu Cursor hinzu?
Öffne ~/.cursor/mcp.json und füge den Server unter mcpServers hinzu, mit der Cursor-Config aus dem Installationsabschnitt oben.
Welche Tools bietet CrawlEyes MCP?
Er stellt 4 Tools bereit, darunter search, extract, sitemap, deep_research.
Benötigt CrawlEyes einen API-Key?
Nein, es ist so konzipiert, dass es ohne externe Accounts oder API-Keys funktioniert, indem es SearXNG und einen schlüssellosen Tavily-Fallback nutzt.
Welche Tools stellt der MCP server bereit?
Der MCP server stellt die Tools search, extract, deep_research und sitemap bereit.
Kann ich CrawlEyes für Deep Research nutzen?
Ja, das deep_research Tool zerlegt ein Thema in Unterfragen, führt Suchen und Extraktionen durch und erstellt einen zitierten Markdown-Bericht.
Wie geht der Server mit Fehlern bei der Suche um?
Er nutzt SearXNG als primäre Suche mit einem automatischen Fallback auf die schlüssellose Tavily API, gesteuert durch einen Three-State Circuit Breaker.