
live-memory MCP server
✓ 인증됨Claude Code의 토큰 비용과 파일 재읽기 횟수를 줄이기 위해 지속 가능한 읽기 전용 코드베이스 메모리를 제공합니다.
다른 이름 shofer-dev/claude-code-live-memory, claude-code-live-memory, shofer-live-memory
- 스타
- 7
- Tools
- 2
- 다운로드, 30일
- 74
- 최신 버전
- 0.6.0
- 마지막 커밋
- 2026년 8월 1일
- 라이선스
- Apache-2.0
live-memory MCP란?
live-memory은(는) MCP server입니다. Claude Code의 토큰 비용과 파일 재읽기 횟수를 줄이기 위해 지속 가능한 읽기 전용 코드베이스 메모리를 제공합니다. 2개 도구를 제공합니다. 예: ask_live_memory_submit, ask_live_memory_result.
프로젝트 README에서 생성된 요약
live-memory MCP server 정보
Live Memory는 Claude Code를 위해 설계된 MCP server로, 지속 가능한 읽기 전용 코드베이스 메모리를 제공합니다. 이 서버는 여러 세션에 걸쳐 저장소에 대한 지식을 축적하는 장기 실행 싱글톤(singleton)으로 작동하며, AI 에이전트가 파일을 반복해서 읽는 대신 질문을 통해 정보를 얻을 수 있도록 합니다. 이러한 방식은 토큰 비용을 절감하고 개발 작업의 이해 단계를 가속화합니다.
서버는 독립적인 HTTP 서비스로 실행되며 로컬 모델 또는 모든 OpenAI 호환 엔드포인트를 사용하도록 설정할 수 있습니다. Claude 구독 사용자의 경우 OAuth를 통해 Haiku를 사용하는 제로 컨피그(zero-config) 설정을 지원합니다. 에이전트의 일반적인 읽기 및 수정 작업 중에 파일 내용을 캡처하는 훅을 사용하여 수동적으로 학습하므로, 코드베이스가 변경되어도 메모리가 최신 상태를 유지합니다. 시스템은 경로 제한 및 읽기 전용으로 작동하므로 워크스페이스의 어떤 파일도 수정하거나 실행할 수 없습니다.
활용 사례
- 1코드베이스 이해 비용 절감AI 에이전트가 저장소의 모든 파일을 읽는 대신 메모리 서버를 사용하여 광범위한 아키텍처 질문에 답변할 수 있습니다.
- 2코드베이스 학습 자동화에이전트가 상호작용하는 파일을 관찰함으로써 시스템이 프로젝트에 대한 이해도를 자동으로 구축합니다.
프로젝트의 README를 바탕으로 작성되었습니다. 모든 활용 사례는 해당 내용의 인용문과 대조하여 확인합니다.
live-memory MCP 설치 방법
형식 확인: 2026년 11월 10일Cursor에 추가Goose에 추가Claude Code에 live-memory MCP 설치
$ claude mcp add claude-code-live-memory -- uvx shofer-live-memoryCursor에 live-memory MCP 설치
~/.cursor/mcp.json
{
  "mcpServers": {
    "claude-code-live-memory": {
      "command": "uvx",
      "args": [
        "shofer-live-memory"
      ]
    }
  }
}VS Code에 live-memory MCP 설치
.vscode/mcp.json
{
  "servers": {
    "claude-code-live-memory": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "shofer-live-memory"
      ]
    }
  }
}VS Code CLI에 live-memory MCP 설치
$ code --add-mcp '{"name":"claude-code-live-memory","type":"stdio","command":"uvx","args":["shofer-live-memory"]}'Claude Desktop에 live-memory MCP 설치
claude_desktop_config.json
{
  "mcpServers": {
    "claude-code-live-memory": {
      "command": "uvx",
      "args": [
        "shofer-live-memory"
      ]
    }
  }
}Codex에 live-memory MCP 설치
$ codex mcp add claude-code-live-memory -- uvx shofer-live-memoryCodex config.toml에 live-memory MCP 설치
~/.codex/config.toml
[mcp_servers.claude-code-live-memory]
command = "uvx"
args = ["shofer-live-memory"]
Gemini CLI에 live-memory MCP 설치
$ gemini mcp add -s user claude-code-live-memory uvx -- shofer-live-memoryGemini settings.json에 live-memory MCP 설치
~/.gemini/settings.json
{
  "mcpServers": {
    "claude-code-live-memory": {
      "command": "uvx",
      "args": [
        "shofer-live-memory"
      ]
    }
  }
}live-memory MCP 도구 2
README에서 감지됨ask_live_memory_submitask_live_memory_result
| ask_live_memory_submit | — | |
| ask_live_memory_result | — |
구성
LIVE_MEMORY_API_KEYLIVE_MEMORY_PRELOAD_GLOBSLIVE_MEMORY_PROVIDER
| 이름 | 설명 | 유형 |
|---|---|---|
| LIVE_MEMORY_API_KEY | — | |
| LIVE_MEMORY_PRELOAD_GLOBS | — | |
| LIVE_MEMORY_PROVIDER | — |
자동 검사
2026년 11월 14일에 실행됨전체 보고서 →자동 검사를 통과했습니다. 이는 보안 감사가 아닙니다. 코드를 직접 읽고 서버에 필요한 최소한의 권한만 부여하십시오. 검사 방식

- 소스 저장소 연결 및 접근 가능shofer-dev/claude-code-live-memory is public and reachablegithub.com/shofer-dev/claude-code-live-memory ↗통과
- 패키지가 이 저장소를 소스로 명시shofer-live-memory names shofer-dev/claude-code-live-memory as sourcepypi.org/project/shofer-live-memory/ ↗통과
- 빌드 출처(Sigstore 증명)No build attestation published for this release검사되지 않음
- 오픈 소스 라이선스 (OSI)Apache-2.0spdx.org/licenses/Apache-2.0.html ↗통과
- 최근 1년 내 커밋 또는 릴리스Last commit or release 2026-08-01github.com/shofer-dev/claude-code-live-memory ↗통과
- OpenSSF Scorecard검사되지 않음
- 패키지 이름이 인기 패키지와 유사하지 않음No popular package one edit away from shofer-live-memory통과
- 패키지 및 해당 종속성에 중요한 보안 권고 없음34 resolved dependencies checked; no critical advisoryosv.dev ↗통과
- 모델에 대한 숨겨진 지침 없음2 tool descriptions and the README read; no override phrases, credential paths or hidden characters통과
- 파괴적인 도구에 라벨 표시됨No tool named like delete, drop or exec통과
- 원격 엔드포인트가 MCP 핸드셰이크에 응답검사되지 않음
README
GitHub에서 보기██╗ ██╗██╗ ██╗███████╗
██║ ██║██║ ██║██╔════╝
██║ ██║██║ ██║█████╗
██║ ██║╚██╗ ██╔╝██╔══╝
███████╗██║ ╚████╔╝ ███████╗
╚══════╝╚═╝ ╚═══╝ ╚══════╝
███╗ ███╗███████╗███╗ ███╗ ██████╗ ██████╗ ██╗ ██╗
████╗ ████║██╔════╝████╗ ████║██╔═══██╗██╔══██╗╚██╗ ██╔╝
██╔████╔██║█████╗ ██╔████╔██║██║ ██║██████╔╝ ╚████╔╝
██║╚██╔╝██║██╔══╝ ██║╚██╔╝██║██║ ██║██╔══██╗ ╚██╔╝
██║ ╚═╝ ██║███████╗██║ ╚═╝ ██║╚██████╔╝██║ ██║ ██║
╚═╝ ╚═╝╚══════╝╚═╝ ╚═╝ ╚═════╝ ╚═╝ ╚═╝ ╚═╝
always-up-to-date codebase memory for Claude Code · ask, don't re-read
Live Memory — Claude Code plugin
A cheap, always-on model that learns your repo — so your agent stops re-reading it.
Live Memory runs a separate, cheap large-context model as a long-lived MCP server that accumulates
knowledge of your codebase across sessions. Instead of re-reading the same files every session, your
agent asks one read-only tool, ask_live_memory, the broad-understanding questions — "where is X,
how does Y work, what calls Z" — and Live Memory answers in a way that bootstraps the primary agent to
start doing productive work (e.g., edits). It learns passively from your agent's own reads and edits
(teed via hooks — no extra reading) and stays current as the repo changes (modifications and deletions).
Read-only and path-jailed (it can never edit, create, or run anything); zero-config on a Claude
subscription (Haiku, no API key); the memory model is pluggable — point it at a local model or any
OpenAI-compatible endpoint.
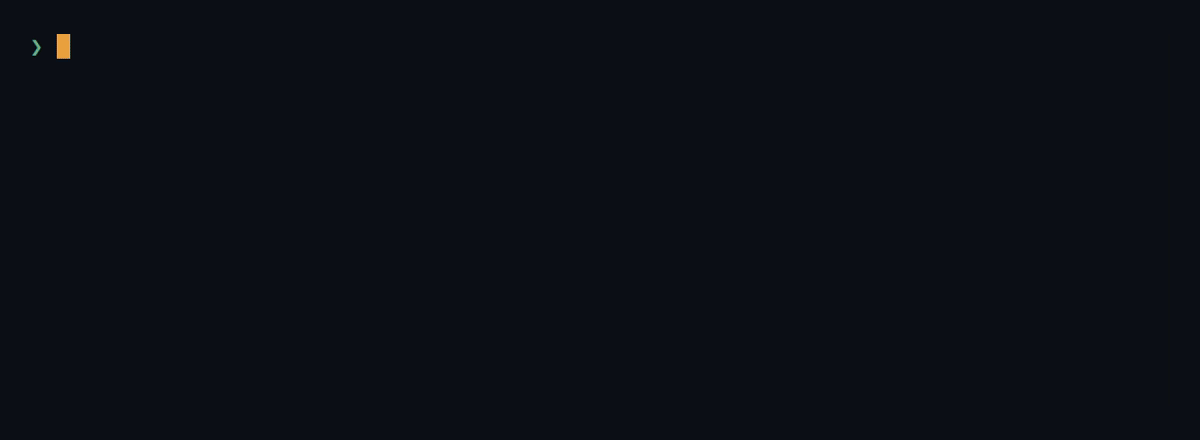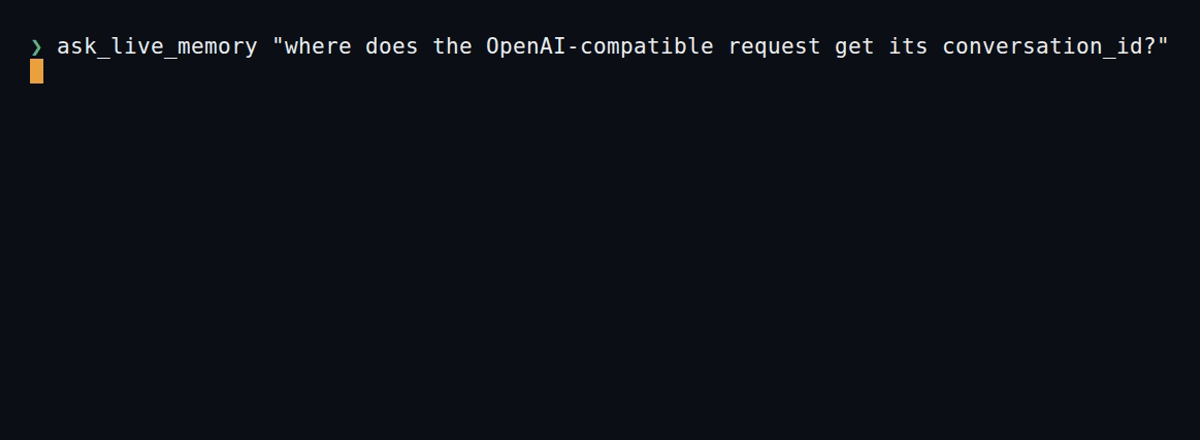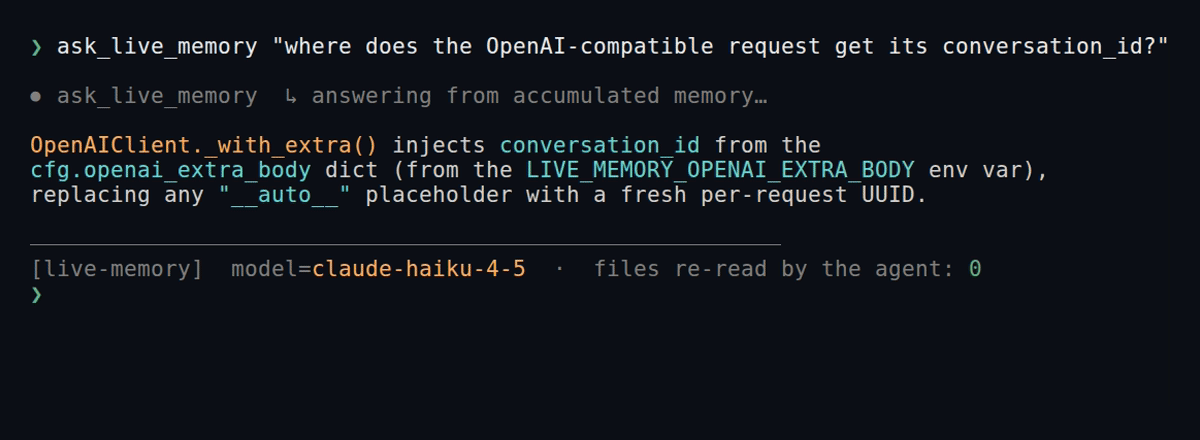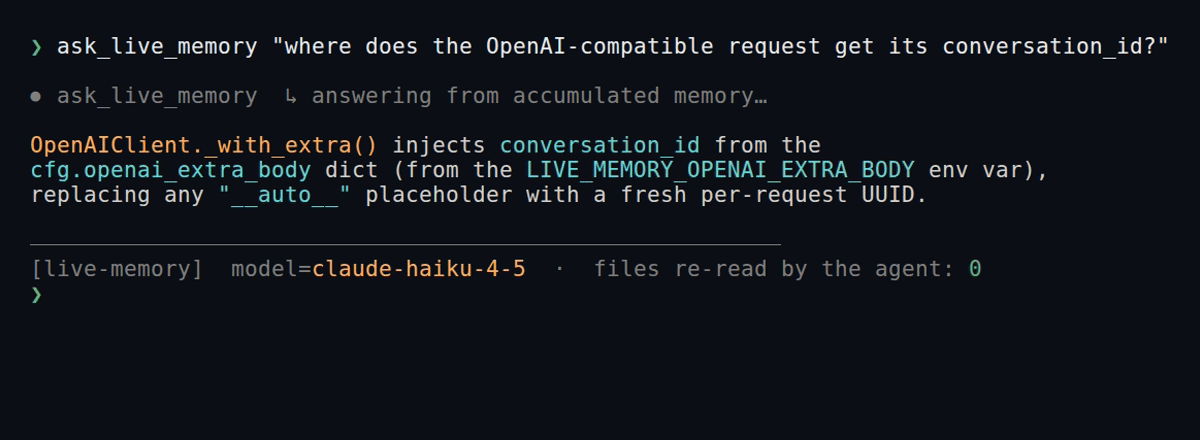
How it works
flowchart LR
  repo[("Your repo")]
  subgraph sessions["Claude Code sessions — premium model (many, over time)"]
    agent["Agent"]
  end
  agent -->|"reads / edits files"| repo
  agent -. "PostToolUse / FileChanged hooks<br/>tee file content — passive learning (free)" .-> lm
  agent ==>|"ask_live_memory(question, cwd)<br/>one read-only MCP tool"| lm
  lm ==>|"grounded answer — no file re-reading"| agent
  subgraph server["Live Memory — one MCP server per workspace (singleton)"]
    lm["Cheap / local large-context model<br/>+ accumulating context window<br/>append-only · neutral compaction to a ledger"]
    lm --> snap[("Local JSON snapshot<br/>persists across sessions")]
  end
Your agent reads or edits files as usual; hooks quietly tee that content to the server so it learns
for free. When the agent needs to understand something, it asks ask_live_memory instead of
re-reading — the server answers from its accumulated, per-workspace memory (or reads the code itself,
read-only, if it hasn't seen it yet). One server serves every session and persists across sessions.
Benchmarks
A/B on a real repo, cost per task, run to completion. Cost is shown three ways: the premium (building) model's bill — what your expensive model spends, since the companion runs on a cheap or local model — and all-in, also counting the companion's own cost on DeepSeek-v4-flash or Haiku:
| per task | premium-model bill | all-in · DeepSeek-flash† | all-in · Haiku | faster |
|---|---|---|---|---|
| Understanding-heavy (trace / comprehend) | −61% | −57% | −25% | ~22% |
| Hybrid (understand-then-edit: bug fixes + features) | −28% | −26% | −11% | ~11% |
| Pure edit / execution | ~break-even | ~break-even | ~break-even | ~0 |
Understanding-heavy work also offloads ~93% of the premium model's codebase-reading tokens (with lower
cost variance), and correctness never regressed on the hybrid tasks (12/12 passed with and without
it). DeepSeek-v4-flash matched Haiku's answer accuracy (98% vs 91% over 3 reps) at ~8× lower token
price; a local companion is ≈ free, so all-in ≈ the premium-model bill. Fully reproducible + audited
(human + Fable). Full numbers + methodology: benchmark/results/RESULTS.md.
† companion re-priced at DeepSeek-v4-flash rates (~8× cheaper than Haiku); exact for the understanding case, derived from the measured cost ratio for the hybrid case.
Lineage: Live Memory began as a feature of shofer.dev (Arkware's
parallel multi-agent coding platform), where sessions share an in-sync codebase memory. This is that
idea as a standalone Claude Code plugin — a fresh implementation, self-contained, with no
dependency on shofer. Part of the shofer Claude Code plugin family (with
slang-workflows).
Design: DESIGN.md · How it compares to Copilot/Cursor: COMPARISON.md · Testing: TESTING.md · Privacy: PRIVACY.md.
Quickstart
live-memory is an HTTP MCP server you run once (a singleton that serves every Claude Code session)
plus a plugin that registers ask_live_memory, the hooks, and the slash commands. Start the server
first — Claude Code only connects to it (it never spawns it), so if it isn't running you'll get a
connection error.
1 — Start the server (zero-config on a Claude subscription → Haiku; no API key needed):
git clone https://github.com/shofer-dev/claude-code-live-memory
cd claude-code-live-memory/deploy && ./install-service.sh   # venv + user systemd service, auto-starts on boot
# …or just run it in a terminal:
#   cd claude-code-live-memory/server && pip install -e . && python -m live_memory
2 — Install the plugin (inside a Claude Code session):
/plugin marketplace add shofer-dev/claude-code-live-memory
/plugin install live-memory@shofer-live-memory
Ask your agent a whole-repo question — it'll call ask_live_memory instead of reading files.
/live-memory-stats shows accumulated knowledge + cost · /live-memory-config switches
model/provider · /live-memory-empty wipes memory · /live-memory-reset starts a workspace
over with its configured preload docs re-loaded. Providers, systemd, workspaces, and concurrency
are detailed below.
Shape
live-memory/
├── .claude-plugin/plugin.json     # plugin manifest
├── .mcp.json                      # registers the server (type:http, explicit timeout)
├── hooks/                         # PostToolUse(Read|Write|Edit|…) + FileChanged → TEE file content (passive learning)
│   ├── hooks.json
│   └── notify.py
├── skills/live-memory/SKILL.md    # tells the agent when/why to call ask_live_memory
├── commands/                      # USER-facing slash commands (not agent tools)
│   ├── live-memory-stats.md       # /live-memory-stats  → GET /stats
│   ├── live-memory-config.md      # /live-memory-config → set model/provider, hot-reload
│   ├── live-memory-empty.md       # /live-memory-empty  → wipe memory (this workspace or `all`)
│   ├── live-memory-reset.md       # /live-memory-reset  → drop history + re-preload configured docs
│   ├── stats.py · config.py · empty.py · reset.py
├── settings.json
├── deploy/                        # systemd unit + env example + install-service.sh
└── server/                        # the long-running MCP server (Python, asyncio)
    ├── pyproject.toml             # deps + mypy(strict) + pytest config
    ├── tests/                     # pytest unit suite (mocked; no network)
    └── live_memory/
        ├── __main__.py            # entrypoint: python -m live_memory
        ├── server.py              # MCP (HTTP) ask_live_memory + /health + /stats + /notify + /clear + /reset + /reload
        ├── workspace.py           # per-cwd state registry (window + queue + store); fork/commit
        ├── manager.py             # the agent loop (process one question); compaction
        ├── context_window.py      # budget; file-context evict, Q&A summarize; fork/clone
        ├── summarizer.py          # NEUTRAL, query-agnostic knowledge-ledger summarization
        ├── question_queue.py      # per-workspace admission (serial/parallel) + per-entry timeout
        ├── async_jobs.py          # opt-in fire-and-forget job registry (submit/poll)
        ├── keep_warm.py           # background KV/prompt-cache keep-warm loop
        ├── conversation_store.py  # versioned JSON snapshot (SHA-256 file validation)
        ├── llm_client.py          # provider-pluggable: Anthropic Messages | OpenAI-compatible
        ├── oauth.py               # subscription OAuth credential + auto-refresh (zero-config)
        ├── config.py              # layered config (env > config.json > defaults) + provider knowledge
        ├── constants.py           # ALL tunable magic numbers + defaults, centralized (config sources its defaults here)
        ├── models.py              # core dataclasses (ChatMessage, FileContext, QuestionResult, …)
        ├── tool_executor.py       # read-only tools (Read/Grep/Glob/find_paths/git/…), path-jailed
        ├── preload.py             # configured preload globs → verbatim docs on workspace load
        ├── directory_tree.py      # workspace scan, ~10% context cap
        ├── pricing.py             # per-model USD cost (+ env overrides)
        ├── logging_setup.py       # stderr→journald + optional rotating file
        └── prompts.py             # system prompt + neutral-summary prompt
Architecture (see DESIGN.md for the full rationale)
- One externally-supervised, idempotent HTTP MCP server (singleton) serves all
Claude Code sessions; state is keyed per workspace (
cwd). - Model = independent + provider-pluggable: the server runs its own cheap
model (not the session's). Two adapters cover ~everything — Anthropic Messages
(with
cache_control) and OpenAI-compatible (DeepSeek/OpenAI/gateways). Zero-config: with no key but a Claude subscription, it uses the subscription OAuth token (auto-refreshed) on Haiku. - Passive (organic) learning: PostToolUse/FileChanged hooks tee the content
of the files your agent reads/edits into the memory, so it warms up for free from
real work;
ask_live_memoryis the active fallback for anything unseen. - Preload globs (opt-in):
preload_globs(e.g.docs/*.md) names reference docs loaded verbatim into the system prompt whenever a workspace is (re)loaded — the memory starts out knowing them. They behave like observations: compaction later distills them into the knowledge ledger under pressure./live-memory-resetdrops a workspace's history trail and re-preloads them fresh. - Append-only window between compactions; compaction = batched neutral summarization with a high/low-watermark (rare, batched) — observed files + Q&A distilled into a query-agnostic knowledge ledger — never front-truncation.
- Frozen volatile block + observation deltas (KV-cache preservation): the volatile system block (ledger + preloaded/observed content + manifest) is frozen between compactions and re-sent byte-identical; changes that arrive in between (a teed file, a staleness notice) are appended to the history as delta messages instead of mutating the block — so the provider's prefix cache keeps matching instead of truncating at the first changed byte.
- Two-tier timeout:
ask_live_memory(question, cwd, max_answer_tokens?)blocks up to the server-configured soft budget (default_timeout_s, default 60s — no longer a tool argument) and returns a best-effort answer before the hard.mcp.jsonMCP timeout. - Disclosed answer-length budget: the answer is hard-capped (default
LIVE_MEMORY_MAX_ANSWER_TOKENS) and the model is told the cap, so it self-regulates instead of being truncated mid-sentence; the optionalmax_answer_tokensarg overrides it per question. - Human status via the
/live-memory-statsslash command (→/stats), kept off the agent's tool surface.
Installation
Prerequisites: Python ≥ 3.10; ripgrep (rg) recommended (powers
Grep); git optional (powers git_search / get_changed_files).
1. Install the server:
cd server
pip install -e .          # runtime deps (mcp, anthropic, starlette, uvicorn, watchdog, httpx)
# for development/tests:  pip install -e ".[dev]"   # adds mypy, pytest, pytest-asyncio
2. Install the plugin into Claude Code so it reads .mcp.json, the hooks, the
skill, and the slash commands. The repo root doubles as a single-plugin
marketplace (.claude-plugin/marketplace.json); /plugin install only
installs from a marketplace, never a bare directory — so add the marketplace
first, then install from it. Inside a Claude Code session:
/plugin marketplace add https://github.com/shofer-dev/claude-code-live-memory
/plugin install live-memory@shofer-live-memory
shofer is the marketplace name; live-memory is the plugin name. To install
from a local clone instead, point add at the checkout directory:
/plugin marketplace add /ABSOLUTE/PATH/TO/claude-code-live-memory
/plugin install live-memory@shofer-live-memory
After editing plugin files later, run /plugin marketplace update shofer then
/reload-plugins (installed plugins are cached under ~/.claude/plugins/, so
source edits aren't picked up live).
For local development, skip the marketplace entirely and launch Claude Code
with the plugin loaded directly — this does pick up edits via /reload-plugins:
claude --plugin-dir /ABSOLUTE/PATH/TO/claude-code-live-memory
(The server in step 3 must be running before Claude Code connects — .mcp.json
points at a type:http endpoint Claude Code only connects to, never spawns; if
the server is down you'll see a connection error in /plugin's Errors tab.)
3. Run the server (next section). 4. Dev checks: mypy live_memory/ && pytest.
Running the server
The HTTP transport requires the server to be already running before Claude
Code connects (Claude Code does not start type:http servers) — run it under an
external supervisor (systemd/container/etc.).
Zero-config (no API key): if you're logged into a Claude subscription, it just works — the server reuses that credential (auto-refreshed) on Haiku.
cd server && pip install -e .
python -m live_memory
# serves MCP at http://127.0.0.1:7711/mcp  (+ /health, /stats, /notify, /reload)
The subscription path draws on your subscription's rate-limit budget (not $-metered) — a documented ToS gray area. For an always-on service prefer a key.
Pick any model/provider — env vars or the /live-memory-config slash
command (writes config.json, hot-reloads, no restart):
# DeepSeek (cheap, recommended), via env:
LIVE_MEMORY_PROVIDER=openai LIVE_MEMORY_BASE_URL=https://api.deepseek.com \
  LIVE_MEMORY_API_KEY=sk-... LIVE_MEMORY_MODEL=deepseek-chat  python -m live_memory

# …or at runtime, from inside Claude Code:
/live-memory-config set provider=openai base_url=https://api.deepseek.com model=deepseek-chat api_key=sk-...
/live-memory-config show
Supported providers: anthropic (Messages API + Bedrock/Vertex/gateways, API key
or subscription OAuth) and openai (any OpenAI-compatible endpoint: OpenAI,
DeepSeek, local models, gateways). Then enable the plugin so Claude Code reads
.mcp.json and connects.
Run as a systemd service
deploy/ has the boilerplate. One command registers and starts it:
cd deploy
./install-service.sh            # user service (recommended — see below)
./install-service.sh --system   # system-wide (best for API-key setups)
It creates a venv + installs the server, writes a config at
~/.config/live-memory/live-memory.env (from live-memory.env.example — edit it
for provider/model/key), installs live-memory.service, enables lingering, and
starts it. Config is supplied to the process by systemd via EnvironmentFile=.
- Persistence survives restarts automatically: per-workspace snapshots live
in
LIVE_MEMORY_DATA_DIR(default~/.claude/plugins/data/live-memory), so a restart reloads each workspace's memory on its next query. - Subscription (zero-config) auth needs a user service (the default): it
runs as you, so it can read
~/.claude/.credentials.jsonand reuse your Claude login (auto-refreshed). A--systemservice can also do this, but the unit must setUser=+Environment=HOME=…(the installer does this for you).
systemctl --user status live-memory
journalctl --user -u live-memory -f
systemctl --user restart live-memory     # after editing the env file
Logs
By default the server logs to stderr, which systemd captures into the journal — the idiomatic place, with rotation and unit/PID metadata:
journalctl --user -u live-memory -f          # user service
sudo journalctl -u live-memory -f            # system service
Two caveats and the escape hatch:
- A user service's journal only persists across reboots if journald has
persistent storage (
/var/log/journalexists). If yours is volatile, those logs vanish on reboot. - For a durable, greppable plain-text log regardless, set
LIVE_MEMORY_LOG_FILE(e.g./var/log/live-memory/live-memory.logfor a system service, or an absolute path under~/.local/state/live-memory/for a user one). It's a rotating handler (LIVE_MEMORY_LOG_MAX_BYTES×LIVE_MEMORY_LOG_BACKUPS) and writes in addition to journald.LIVE_MEMORY_LOG_LEVEL(defaultINFO) tunes verbosity.
Workspaces & cwd
Memory is keyed per workspace, from the cwd passed to ask_live_memory.
cwd must be an absolute path (a relative path is rejected — the shared
server can't resolve it against your session). By default the server snaps each
cwd to its enclosing git repo root, so a subdirectory and the repo root
share one memory:
| Env var | Default | Effect |
|---|---|---|
LIVE_MEMORY_CANONICALIZE_WORKSPACE |
true |
Snap cwd to its git repo root. Set false for a distinct memory per exact directory. |
LIVE_MEMORY_REPO_ROOT_MODE |
nearest |
Inside a submodule/worktree: nearest = the submodule's own root (git's default); outermost = the superproject root (fold submodule questions into the parent's memory). |
Preload globs — start out knowing your docs
preload_globs names glob patterns (relative to each workspace root) whose
matching files are read from disk and loaded verbatim into the system prompt
every time a workspace is (re)loaded — reference material the memory knows
before its first question. Preloaded content is treated like an observation:
rendered inline under its own heading until compaction distills it into the
knowledge ledger and sheds the raw bytes under budget pressure.
/live-memory-config set preload_globs=docs/*.md,README.md      # or:
LIVE_MEMORY_PRELOAD_GLOBS="docs/*.md,README.md"
| Env var | Default | Effect |
|---|---|---|
LIVE_MEMORY_PRELOAD_GLOBS |
(empty) | Comma-separated globs (relative to the workspace root, ** supported) preloaded verbatim on workspace load. Absolute patterns and matches escaping the workspace (symlinks) are skipped, as are binary files. |
LIVE_MEMORY_PRELOAD_MAX_TOTAL_BYTES |
2097152 |
Total cap across all preloaded files per workspace (per-file cap is LIVE_MEMORY_PASSIVE_MAX_FILE_BYTES). The effective cap is additionally clamped to the window budget (compaction_floor × LIVE_MEMORY_MAX_CONTEXT_TOKENS) — preloading past the floor would just make the first question distill + shed the docs immediately. To preload a corpus bigger than ~300 KB, raise LIVE_MEMORY_MAX_CONTEXT_TOKENS too. |
Notes:
- Preload runs when a workspace is loaded — its first query after a server
start,
/live-memory-empty, or a config change. A glob change via/live-memory-configapplies to already-loaded workspaces on their next reset/restart, not retroactively. /live-memory-resetstarts a workspace over in one step: it drops the current history trail (Q&A history, knowledge ledger, file manifest — memory and on-disk snapshot) and immediately re-preloads the configured globs fresh from disk. Use it when the accumulated trail has gone stale but you want the verbose reference docs back. (/live-memory-emptyis the same wipe without the eager re-preload — the docs still load lazily on the next question.)
Monitoring scope (file_globs) and the question timeout
| Env var / config key | Default | Effect |
|---|---|---|
LIVE_MEMORY_FILE_GLOBS / file_globs |
(empty — monitor everything) | Comma-separated fnmatch patterns (workspace-relative; * also crosses /). When set, the file-change feed — passive ingestion, stale/deleted tracking, modified hints — applies only to matching paths; everything else is dropped at the workspace boundary. Pair it with preload_globs for a docs-only memory: /live-memory-config set preload_globs=docs/*.md file_globs=docs/*.md. |
LIVE_MEMORY_DEFAULT_TIMEOUT_S / default_timeout_s |
60 |
The soft per-question time budget. ask_live_memory no longer takes a timeout argument — callers get this configured budget; the model is told it and returns a best-effort answer at the deadline. Keep it below the hard .mcp.json MCP timeout. |
Scoping matters for cache stability too: an unscoped feed tees every file your agents touch, and each new observation is a delta the next question must carry. A docs-only scope keeps the memory focused and its prompt small.
Concurrency
Questions to the same workspace are admitted by one of two models:
| Env var | Default | Effect |
|---|---|---|
LIVE_MEMORY_CONCURRENCY |
parallel |
parallel (default) = no queue delay — each question forks the window, up to MAX_PARALLEL_QUERIES run at once, and the fork that explored the most codebase commits back (others still return their answer but don't update shared memory). serial = one question at a time per workspace (shared window grows in place; strongest cache locality, concurrent callers wait). |
LIVE_MEMORY_MAX_PARALLEL_QUERIES |
4 |
Max concurrent questions per workspace in parallel mode. |
(Questions to different workspaces always run concurrently, regardless of this setting.)
Async (fire-and-forget) tools — opt-in
MCP tool calls block the caller's turn until they return. If you want the agent
to submit a slow query, keep working, and collect the answer later, set
LIVE_MEMORY_ASYNC_TOOLS=true to additionally expose:
ask_live_memory_submit(question, cwd)→ returns ajob_idimmediately.ask_live_memory_result(job_id)→ the answer when ready, or[running]to poll again.
The agent drives the polling (Claude Code can't push completion into a running
turn). Off by default; ask_live_memory (synchronous) is always available.
Cache keep-warm
Off by default — opt in with LIVE_MEMORY_KEEP_WARM=true, or via the slash
command: /live-memory-config set keep_warm=true. A background loop pings each
recently-active workspace's prefix (max_tokens=1, output discarded) so the
provider's KV/prompt cache doesn't go cold between questions — keeping the next
real query on cache-hit pricing instead of a full cold re-read. The heartbeat
interval is provider knowledge: 4 minutes (240s) for Anthropic/OpenAI (just
under their minute-scale cache TTLs), and auto-set very long for DeepSeek
(its disk cache lasts hours/days, so even enabled it self-disables there).
Override with LIVE_MEMORY_KEEP_WARM_INTERVAL_S /
/live-memory-config set keep_warm_interval_s=…, or stop warming idle
workspaces sooner with LIVE_MEMORY_KEEP_WARM_MAX_IDLE_S.
/live-memory-stats shows when the cache was last refreshed.
live-memory MCP 질문
live-memory MCP를 Claude Code에 추가하려면 어떻게 하나요?
터미널에서 claude mcp add claude-code-live-memory -- uvx shofer-live-memory를 실행합니다. 모든 프로젝트에서 사용할 수 있게 하려면 --scope user를 추가합니다.
live-memory MCP를 Cursor에 추가하려면 어떻게 하나요?
~/.cursor/mcp.json를 열고 mcpServers 아래에 서버를 추가합니다. 위 설치 섹션에 표시된 Cursor 구성을 사용합니다.
live-memory MCP는 어떤 도구를 제공하나요?
2개 도구를 제공합니다. 예: ask_live_memory_submit, ask_live_memory_result.
Live Memory는 제 코드베이스를 어떻게 학습하나요?
에이전트가 파일을 읽거나 수정할 때 파일 내용을 복제하는 훅(hook)을 통한 수동적 학습과, 'ask_live_memory' 도구를 통한 능동적 학습을 병행합니다.
메모리 도구를 제 파일에 사용해도 안전한가요?
네, 이 도구는 읽기 전용이며 경로 제한(path-jailed)이 적용되어 있어 저장소 내의 파일을 수정, 생성 또는 실행할 수 없습니다.
Claude와 함께 사용하려면 API 키가 필요한가요?
Claude 구독 중이라면 OAuth를 통해 Haiku 모델을 사용하여 별도 설정 없이 바로 사용할 수 있습니다.