
webfetch MCP server
✓ 인증됨멀티 엔진 퓨전, 시맨틱 캐싱, 문장 단위 압축 기능을 갖춘 LLM 에이전트용 셀프 호스팅 웹 검색 및 추출 파이프라인을 제공합니다.
다른 이름 firish/webfetch, webfetch-llm
- 스타
- 60
- Tools
- —
- 다운로드, 30일
- 203
- 최신 버전
- 0.1.3
- 마지막 커밋
- 2026년 7월 23일
- 라이선스
- MIT
webfetch MCP란?
webfetch은(는) MCP server입니다. 멀티 엔진 퓨전, 시맨틱 캐싱, 문장 단위 압축 기능을 갖춘 LLM 에이전트용 셀프 호스팅 웹 검색 및 추출 파이프라인을 제공합니다.
프로젝트 README에서 생성된 요약
webfetch MCP server 정보
webfetch는 LLM 에이전트를 위해 설계된 셀프 호스팅 웹 검색 및 추출 파이프라인을 제공합니다. Reciprocal-rank fusion을 통해 여러 검색 엔진을 결합함으로써, 비용이 많이 드는 호스팅 검색 도구의 로컬 대안 역할을 합니다. 사용자는 API 키를 사용하여 DuckDuckGo, Brave, Serper, Tavily와 같은 엔진을 연결할 수 있으며, DuckDuckGo를 사용하면 별도 비용 없이 즉시 작동합니다. 시스템은 페이지 페칭, Playwright를 통한 JavaScript 렌더링 및 콘텐츠 추출을 로컬에서 처리합니다.
비용과 컨텍스트 윈도우 사용량을 줄이기 위해, 이 서버는 문장 단위 압축과 로컬 SQLite 데이터베이스에 저장되는 이중 레이어 시맨틱 캐시를 채택했습니다. 이 캐시를 통해 에이전트는 반복되거나 유사하게 표현된 쿼리에 대한 결과를 무료로 가져올 수 있습니다. 개발자는 이를 Claude Desktop 또는 Claude Code에 통합하거나 Python 라이브러리로 사용할 수 있습니다. 서버에는 쿼리를 관리하고 호스팅 서비스 대비 로컬 파이프라인 사용 시의 경제적 이점을 모니터링할 수 있는 web_search, fetch_url, savings_report와 같은 특화된 도구가 포함되어 있습니다.
활용 사례
- 1LLM 컨텍스트 비용 절감에이전트가 문장 단위 압축을 사용하여 훨씬 적은 입력 토큰으로 검색 결과를 처리할 수 있습니다.
- 2중복 검색 비용 방지개발자가 로컬 시맨틱 캐시에서 유사한 쿼리를 제공함으로써 새로운 검색에 대한 비용 지불을 피할 수 있습니다.
- 3복잡한 페이지에서 데이터 추출파이프라인이 JavaScript 비중이 높은 웹사이트를 렌더링하고 PDF 또는 HTML 테이블에서 콘텐츠를 추출할 수 있습니다.
- 4검색 경제성 모니터링사용자는 호스팅 검색 가격과 비교하여 얼마나 많은 비용을 절감했는지 추적할 수 있습니다.
프로젝트의 README를 바탕으로 작성되었습니다. 모든 활용 사례는 해당 내용의 인용문과 대조하여 확인합니다.
webfetch MCP 설치 방법
형식 확인: 2026년 11월 10일Cursor에 추가Goose에 추가Claude Code에 webfetch MCP 설치
$ claude mcp add --env 'BRAVE_API_KEY=<YOUR_BRAVE_API_KEY>' --env 'SERPER_API_KEY=<YOUR_SERPER_API_KEY>' --env 'TAVILY_API_KEY=<YOUR_TAVILY_API_KEY>' webfetch -- uvx webfetch-llmCursor에 webfetch MCP 설치
~/.cursor/mcp.json
{
  "mcpServers": {
    "webfetch": {
      "command": "uvx",
      "args": [
        "webfetch-llm"
      ],
      "env": {
        "BRAVE_API_KEY": "<YOUR_BRAVE_API_KEY>",
        "SERPER_API_KEY": "<YOUR_SERPER_API_KEY>",
        "TAVILY_API_KEY": "<YOUR_TAVILY_API_KEY>"
      }
    }
  }
}VS Code에 webfetch MCP 설치
.vscode/mcp.json
{
  "servers": {
    "webfetch": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "webfetch-llm"
      ],
      "env": {
        "BRAVE_API_KEY": "<YOUR_BRAVE_API_KEY>",
        "SERPER_API_KEY": "<YOUR_SERPER_API_KEY>",
        "TAVILY_API_KEY": "<YOUR_TAVILY_API_KEY>"
      }
    }
  }
}VS Code CLI에 webfetch MCP 설치
$ code --add-mcp '{"name":"webfetch","type":"stdio","command":"uvx","args":["webfetch-llm"],"env":{"BRAVE_API_KEY":"<YOUR_BRAVE_API_KEY>","SERPER_API_KEY":"<YOUR_SERPER_API_KEY>","TAVILY_API_KEY":"<YOUR_TAVILY_API_KEY>"}}'Claude Desktop에 webfetch MCP 설치
claude_desktop_config.json
{
  "mcpServers": {
    "webfetch": {
      "command": "uvx",
      "args": [
        "webfetch-llm"
      ],
      "env": {
        "BRAVE_API_KEY": "<YOUR_BRAVE_API_KEY>",
        "SERPER_API_KEY": "<YOUR_SERPER_API_KEY>",
        "TAVILY_API_KEY": "<YOUR_TAVILY_API_KEY>"
      }
    }
  }
}Codex에 webfetch MCP 설치
$ codex mcp add webfetch --env 'BRAVE_API_KEY=<YOUR_BRAVE_API_KEY>' --env 'SERPER_API_KEY=<YOUR_SERPER_API_KEY>' --env 'TAVILY_API_KEY=<YOUR_TAVILY_API_KEY>' -- uvx webfetch-llmCodex config.toml에 webfetch MCP 설치
~/.codex/config.toml
[mcp_servers.webfetch]
command = "uvx"
args = ["webfetch-llm"]

[mcp_servers.webfetch.env]
BRAVE_API_KEY = "<YOUR_BRAVE_API_KEY>"
SERPER_API_KEY = "<YOUR_SERPER_API_KEY>"
TAVILY_API_KEY = "<YOUR_TAVILY_API_KEY>"
Gemini CLI에 webfetch MCP 설치
$ gemini mcp add -s user -e 'BRAVE_API_KEY=<YOUR_BRAVE_API_KEY>' -e 'SERPER_API_KEY=<YOUR_SERPER_API_KEY>' -e 'TAVILY_API_KEY=<YOUR_TAVILY_API_KEY>' webfetch uvx -- webfetch-llmGemini settings.json에 webfetch MCP 설치
~/.gemini/settings.json
{
  "mcpServers": {
    "webfetch": {
      "command": "uvx",
      "args": [
        "webfetch-llm"
      ],
      "env": {
        "BRAVE_API_KEY": "<YOUR_BRAVE_API_KEY>",
        "SERPER_API_KEY": "<YOUR_SERPER_API_KEY>",
        "TAVILY_API_KEY": "<YOUR_TAVILY_API_KEY>"
      }
    }
  }
}구성
BRAVE_API_KEY비밀Optional - adds Brave to the multi-engine fusion. DDG works with no keys at all.
SERPER_API_KEY비밀Optional - adds Serper (Google results) to the multi-engine fusion.
TAVILY_API_KEY비밀Optional - adds Tavily to the multi-engine fusion.
WEBFETCH_PROVIDEROptional - search strategy: multi (RRF fusion of available engines, default), fallback (priority failover), or a single engine name like ddg.
| 이름 | 설명 | 유형 |
|---|---|---|
| BRAVE_API_KEY | Optional - adds Brave to the multi-engine fusion. DDG works with no keys at all. | 비밀 |
| SERPER_API_KEY | Optional - adds Serper (Google results) to the multi-engine fusion. | 비밀 |
| TAVILY_API_KEY | Optional - adds Tavily to the multi-engine fusion. | 비밀 |
| WEBFETCH_PROVIDER | Optional - search strategy: multi (RRF fusion of available engines, default), fallback (priority failover), or a single engine name like ddg. |
자동 검사
2026년 11월 14일에 실행됨전체 보고서 →자동 검사를 통과했습니다. 이는 보안 감사가 아닙니다. 코드를 직접 읽고 서버에 필요한 최소한의 권한만 부여하십시오. 검사 방식

- 소스 저장소 연결 및 접근 가능firish/webfetch is public and reachablegithub.com/firish/webfetch ↗통과
- 패키지가 이 저장소를 소스로 명시webfetch-llm names firish/webfetch as sourcepypi.org/project/webfetch-llm/ ↗통과
- 빌드 출처(Sigstore 증명)No build attestation published for this release검사되지 않음
- 오픈 소스 라이선스 (OSI)MITspdx.org/licenses/MIT.html ↗통과
- 최근 1년 내 커밋 또는 릴리스Last commit or release 2026-07-23github.com/firish/webfetch ↗통과
- OpenSSF Scorecard검사되지 않음
- 패키지 이름이 인기 패키지와 유사하지 않음No popular package one edit away from webfetch-llm통과
- 패키지 및 해당 종속성에 중요한 보안 권고 없음72 resolved dependencies checked; no critical advisoryosv.dev ↗통과
- 모델에 대한 숨겨진 지침 없음0 tool descriptions and the README read; no override phrases, credential paths or hidden characters통과
- 파괴적인 도구에 라벨 표시됨검사되지 않음
- 원격 엔드포인트가 MCP 핸드셰이크에 응답검사되지 않음
README
GitHub에서 보기webfetch
Web search for LLM agents that you run yourself - up to 8x fewer input tokens and 3x lower cost than hosted web_search, at the same accuracy.
Hosted web-search tools charge $10 per thousand searches and then bill you
again for every token of retrieved content they push into your context
window. webfetch replaces them with a local pipeline - multi-engine
search, page fetching and extraction, semantic reranking, sentence-level
compression - exposed as a web_search tool your model calls like any
other. And unlike every hosted tool and search API we surveyed, repeated
and paraphrased queries are served from a semantic cache for free.
(Install with pip install webfetch-llm; the import name is webfetch.)
Jump to: The headline · What you get · Getting started · Check your setup · Full benchmark results · Claude Code · Agent loop · Savings report · How it works · Caveats
Same accuracy. A third of the cost. An eighth of the tokens.
One agent loop, one model, one judge, 50 SimpleQA questions. The only thing that changes between rows is the search tool:
| search tool | accuracy | input tok/query | cost/query |
|---|---|---|---|
| Anthropic hosted web_search | 96% | 17,408 | $0.108 |
| webfetch (4-engine fusion) | 92% | 3,467 | $0.035 |
| webfetch (DDG only, $0 in fees) | 84% | 3,623 | $0.026 |
Swap Opus for gpt-5.6-sol and the same webfetch tool hits 96% - hosted parity - at $0.040/query and 2,156 tokens: an eighth of what the hosted tool pushes into your context. Full results cover every arm we ran.
These numbers are the WORST case for webfetch - measured on an empty cache. In real use the gap widens on its own: repeats and rewords serve from cache for free, and the token advantage is paid again on every later turn that keeps search results in context. It adds up to receipts like this one, from an ordinary Claude Code session:
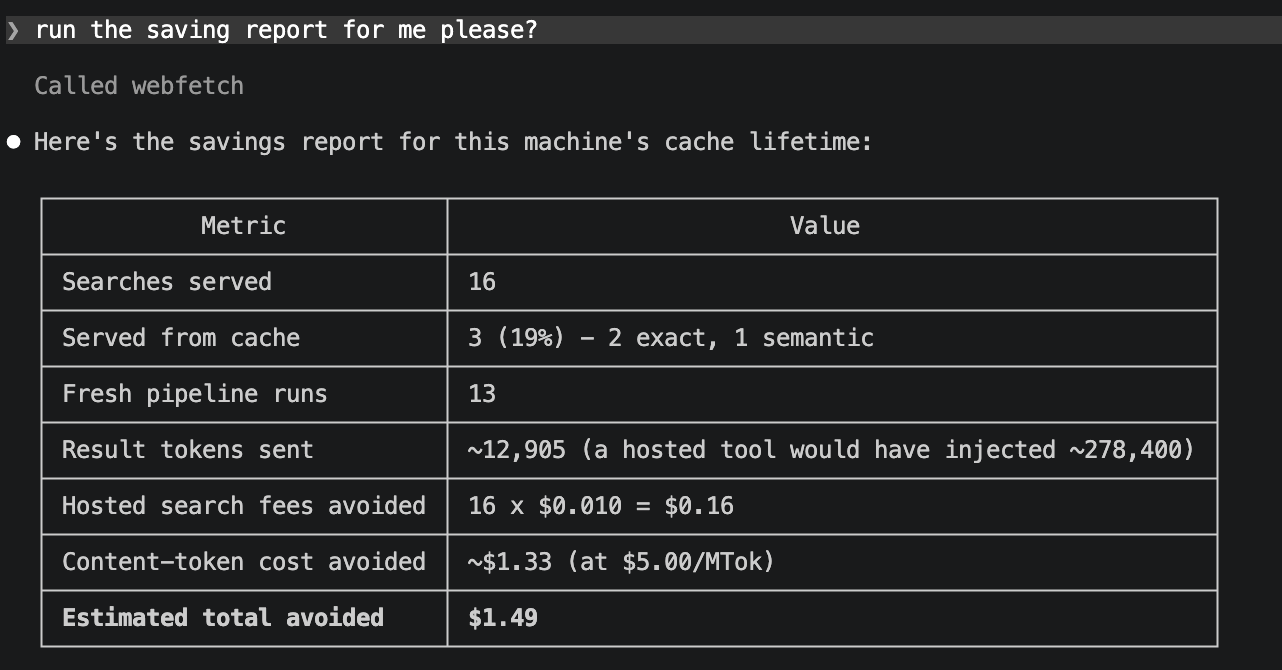
Every claim in this README is generated by an eval harness that ships in this repo - the question sets, per-question records, judging protocol, and the negative results are all in evals/, and every table can be regenerated with one command. Don't take our word for the grading: evals/results/README.md maps every table row to the raw result file that produced it, down to per-question judge verdicts.
What you get
A search pipeline you own (4-engine RRF fusion, local extraction, sentence-level compression). Results come from reciprocal-rank fusion across DuckDuckGo, Brave, Serper, and Tavily - whichever of them you have keys for. DDG needs no key, so the tool works at literally zero cost out of the box; every key you add joins the fusion automatically. Pages are fetched and extracted locally (trafilatura, readability, newspaper4k, Playwright rendering for JS pages and 403 walls), chunked, ranked by a hybrid BM25 + bi-encoder cascade with a cross-encoder on top, then compressed to the sentences that answer the query - measured 50% fewer tokens at zero recall loss.
Caching nobody else has (exact + semantic matching, volatility-aware
TTLs). Two layers in one sqlite file: page text by
URL, ranked results by query. Identical queries hit an exact cache.
Paraphrased queries hit a semantic cache - an embedding shortlist
verified by an NLI cross-encoder, tuned eval-first for precision (zero
wrong-target matches across every live run we have done). Cache lifetimes
adapt to the query: prices and scores expire in 15 minutes, current-ish
topics in 7 days, release notes and specs in 90 - classified by the
calling model's hint or a local classifier. The model sees provenance on
every cached result ([cache: semantic match to "...", 2h old, recent])
and can send force_fresh when it disagrees. No hosted tool or search
API we surveyed offers any client-visible caching at all.
The model can maintain its own cache (save_finding, labeled
UNVERIFIED, kill switch included). If a search comes up empty and
the model answers from some other source (a hosted search fallback, say),
it can call save_finding to store what it learned - marked
model-contributed, served with an explicit UNVERIFIED warning and a
force_fresh escape hatch, and aged out on the normal TTL rules. A kill
switch (SAVE_FINDING_ENABLED = False) exists for deployments that never
want unverified content cached.
Levers where models actually need them (full_results, fetch_url,
freshness, force_fresh). full_results returns
uncompressed excerpts for list and ranking queries (compression trims
parallel list items - we measured it). fetch_url pulls one cited page
in full, instantly if the pipeline has ever fetched it. freshness hints
control cache lifetime; force_fresh bypasses it.
Receipts (session and lifetime, exact counters). Usage counters
persist in the cache file;
webfetch-savings (or the savings_report tool) shows what you did not
pay hosted-search pricing for, split by this session and lifetime.
Sample below.
Getting started
The one-liner (uv installs the package on first launch, @latest picks
up new releases automatically):
claude mcp add webfetch -- uvx --from webfetch-llm@latest webfetch-mcp
Or manage the install yourself, two commands:
pip install "webfetch-llm[all]"
claude mcp add webfetch -- webfetch-mcp
The slim install (webfetch-llm without extras) starts in seconds and
runs degraded: BM25 ranking, exact-only cache, lexical compression.
[all] pulls the semantic stack (torch - a few minutes once) plus
Playwright, PDF, and table extraction; it is the configuration every
benchmark number in this README was measured on. Needs pip >= 24 in fresh
venvs (python -m pip install -U pip - older pips crash on a duplicated
extra in our dependency tree). If you install into a venv, register the
absolute path to webfetch-mcp or keep the venv active.
Keys are optional (DDG works with none) but improve recall - all the engines have free tiers:
cp .env.example .env # fill in what you have
The console scripts and the MCP server pick up a .env from the
directory they run in; exported env vars and --env flags on
claude mcp add always take precedence. import webfetch as a library
never reads .env - your process env is yours.
Check your setup
webfetch-status (or asking the model to call the status tool) answers
"is my key being picked up, and what am I actually running?":
webfetch 0.1.3

search engines:
  ddg      ready (no key needed)
  brave    ready (BRAVE_API_KEY is set)
  serper   off   (SERPER_API_KEY not set)
  tavily   ready (TAVILY_API_KEY is set)

active provider: multi(ddg+brave+tavily) (RRF fusion)

optional features:
  semantic ranking/cache/compression: on
  JS-page rendering (playwright):     on
  PDF extraction (pdfplumber):        OFF (pip install 'webfetch-llm[pdf]')
  HTML tables (pandas+tabulate):      on
  result compression:                 on (crossencoder)

cache: /Users/you/.webfetch/cache.db
  5.4 MB, 70 lifetime searches (webfetch-savings for the receipt)
Key names only - values are never printed. Configuration is environment variables, read at server start:
| variable | effect |
|---|---|
BRAVE_API_KEY, SERPER_API_KEY, TAVILY_API_KEY |
each key adds an engine to the fusion |
WEBFETCH_PROVIDER |
multi (default: fuse everything keyed), fallback (DDG serves, keyed engines catch its blocks), or a single engine name |
WEBFETCH_CACHE_DB |
relocate the cache file (default ~/.webfetch/cache.db) |
With zero keys the default resolves to plain DDG; the status output says
so honestly rather than calling it fusion. Library users can skip env
entirely: Pipeline(search=get_search_adapter("fallback"), cache=...).
Full benchmark results
Every arm, same 50 SimpleQA questions, same judge, one same-day run (2026-07-14). Agent-loop arms share an identical loop; only the search tool differs. Costs include model tokens plus each provider's published per-search fees; ours include estimated engine fees.
| search tool | model | accuracy | input tok/q | cost/q |
|---|---|---|---|---|
| OpenAI hosted web_search | gpt-5.6-sol | 100% | 10,027 | $0.066 |
| webfetch (4-engine fusion) | gpt-5.6-sol | 96% | 2,156 | $0.040 |
| Anthropic hosted web_search | Opus 4.7 | 96% | 17,408 | $0.108 |
| webfetch (4-engine fusion) | Opus 4.7 | 92% | 3,467 | $0.035 |
| Exa (search + contents) | Opus 4.7 | 90% | 5,496 | $0.053 |
| Tavily | Opus 4.7 | 88% | 6,387 | $0.047 |
| webfetch (DDG only) | Opus 4.7 | 84% | 3,623 | $0.026 |
| webfetch (4-engine fusion) | Haiku 4.5 | 76%* | 3,021 | $0.031 |
* Haiku's failures were mostly re-searching past the turn cap, and its last few questions ran on a degraded engine set after we exhausted a free tier mid-benchmark. Treat it as a floor.
Notice the token column: webfetch results cost half the input tokens of the snippet APIs and a fifth to an eighth of the hosted tools - which is why our cost stays lowest even where per-search fees are similar.
On a second dataset of 27 questions about events from the two weeks before the run (hand-written, never published, so no vendor could have tuned on them), webfetch scored 100% with fusion and 100% with DDG alone; the hosted tools also scored 100%. Fresh events are not the hard part - the date-injection trap is.
Reproduce: python evals/run_e2e_eval.py --arms ours-multi,hosted - the
harness, datasets, and per-question records are in evals/. The
table above comes from
e2e_eval_20260714_005531.json
(plus the Haiku run and the fresh-events set - the full claim-to-file map
is in evals/results/README.md). The questions
are a seeded sample (seed 42) of OpenAI's public SimpleQA set, so
build_datasets.py regenerates the identical 50 on your machine. One
honest caveat: the live web moves between runs, and at n=50 the 96-vs-92
accuracy gap is 48-vs-46 correct - parity within noise. The token and
cost columns are the mechanically stable result.
Using it in Claude Code / Claude Desktop
Fastest route in Claude Code - install it as a plugin, two slash commands (runs the same uv one-liner under the hood):
/plugin marketplace add firish/webfetch
/plugin install webfetch@webfetch
Or register the MCP server yourself. Either way, a
new session shows webfetch under /mcp with five tools: web_search, fetch_url,
save_finding, status, and savings_report. Ask anything recent and
watch the tool calls; ask the same thing reworded and the result comes
back with a [cache: semantic match ...] header instead of a fresh
search. First call in a session is slow (encoder warm-up plus real page
fetches, 10-40s); cached calls are instant.
Toggle the server off per-session in /mcp; remove it with
/plugin uninstall webfetch or claude mcp remove webfetch, matching
how you installed it. Your cache and its receipt history live in
~/.webfetch/ and survive reinstalls. Run one server per machine - the
semantic cache assumes a single process owns its file.
Update notice: the server makes one request to pypi.org per process to
check for a newer release, surfaced as one line in savings_report
output. UPDATE_CHECK_ENABLED = False in webfetch/config.py disables
it; nothing else is ever sent anywhere.
Use it in your own agent loop
import time
import anthropic
from webfetch import WEB_SEARCH_TOOL, handle_web_search

client = anthropic.Anthropic()
messages = [{"role": "user", "content": "What did the FOMC decide this week?"}]
system = (f"Today's date is {time.strftime('%Y-%m-%d')}. "
          "Use web_search for recent facts.")

while True:
    response = client.messages.create(
        model="claude-opus-4-7", max_tokens=2000, system=system,
        tools=[WEB_SEARCH_TOOL], messages=messages,
    )
    if response.stop_reason != "tool_use":
        break
    messages.append({"role": "assistant", "content": response.content})
    results = [{"type": "tool_result", "tool_use_id": b.id,
                "content": handle_web_search(b.input)}
               for b in response.content if b.type == "tool_use"]
    messages.append({"role": "user", "content": results})
A complete version with prompt caching and adaptive thinking is in examples/agent_loop.py. The tool schema is provider-agnostic in spirit - OpenAI function calling needs only a mechanical reshape of the dict.
Put today's date in your system prompt. This is not optional. Models refuse to search for events they believe have not happened yet: on our fresh-events dataset, loops without the date declined to even call the tool on up to 10 of 27 questions ("Wimbledon 2026 hasn't taken place yet"). One line fixes it. Hosted search tools do this server-side, which is part of why nobody notices until they run their own tool.
handle_web_search never raises. Engine failures, empty results, and
malformed input come back as readable strings the model can react to,
because an exception mid-conversation kills the whole agent loop.
The savings report
Counters accumulate in the cache file as you search. Ask the model to run
the report, or run webfetch-savings yourself. The MCP tool splits this
session from lifetime, so you can see what one conversation saved:

That one-liner unpacked - a 30-search session on this machine:
| this session | lifetime | |
|---|---|---|
| searches served | 30 | 76 |
| served from cache | 17 (57%) - 10 exact, 7 semantic | - |
| search fees avoided | ~$0.30 | |
| content-token cost avoided | ~$2.56 | |
| estimated total avoided | ~$2.86 | ~$7.21 |
Counters are exact; the dollar lines are estimates with the assumptions
(hosted per-search fee, hosted tokens per call - both measured - and your
model's token price) exposed as arguments to webfetch.savings_report().
How it works
query -> multi-engine search (RRF fusion, circuit breakers)
      -> semantic query cache? serve with provenance header
      -> fetch pages concurrently (page cache by URL)
      -> extract (trafilatura -> readability -> newspaper4k -> playwright)
      -> chunk (400 chars) -> BM25 + bi-encoder fusion -> cross-encoder top 5
      -> compress to query-relevant sentences -> source-labeled result
Everything heavy is optional: without [rerank] you get BM25 ranking,
exact-match caching, and lexical compression, with a logged warning
instead of an ImportError. DDG deserves a special note: it
fingerprint-blocks automated clients with silent empty responses.
webfetch detects that (empty-with-peers in fusion, any empty in the
fallback chain), benches the engine on a circuit breaker, and routes
around it; the TLS side is handled by the ddgs dependency.
Design decisions and their measurements are documented as they happened in docs/architecture.md and docs/ROADMAP.md - including the negative results.
Caveats, honestly
- Latency. A fresh search takes 10-40 seconds - real pages get fetched and ranked locally. Hosted search returns in ~10s, snippet APIs in ~6s. Cache hits are instant. If you need sub-second search and do not care about cost, this is not your tool.
- The cache is single-process. One agent loop, one MCP server, or one notebook at a time; a shared team cache backend is on the roadmap.
- Engine free tiers are real quotas. We exhausted Brave's monthly tier during benchmarking. The resilience layer degrades gracefully, but your recall degrades with it. Engine fees in the tables are estimates from published prices.
- Answer quality depends on the model driving the tool - weak models formulate worse queries and re-search instead of reading (see the Haiku row).
- Semantic-cache recall on cross-form rewords ("what did X add" vs "X new features") is partial: measured 6/10 on real pairs after tuning, because some paraphrase forms defeat every available verifier. Misses cost a re-search, never a wrong answer.
Benchmarks and data
Three eval layers, all in evals/: an offline matcher eval that picks the semantic-cache thresholds, a live retrieval eval (recall, tokens, cache diagnostics), and the end-to-end answer eval quoted above (SimpleQA protocol: normalized exact match, then an LLM judge). Datasets are built deterministically from SimpleQA (MIT), QQP/GLUE, and FreshQA (CC-BY-SA), with provenance sidecars next to each file. The fresh-events set was hand-written against verified news sources days before the benchmark ran, specifically so no model or vendor pipeline could have seen it.
License
MIT.
webfetch MCP 질문
webfetch MCP를 Claude Code에 추가하려면 어떻게 하나요?
터미널에서 claude mcp add --env 'BRAVE_API_KEY=<YOUR_BRAVE_API_KEY>' --env 'SERPER_API_KEY=<YOUR_SERPER_API_KEY>' --env 'TAVILY_API_KEY=<YOUR_TAVILY_API_KEY>' webfetch -- uvx webfetch-llm를 실행합니다. 모든 프로젝트에서 사용할 수 있게 하려면 --scope user를 추가합니다.
webfetch MCP를 Cursor에 추가하려면 어떻게 하나요?
~/.cursor/mcp.json를 열고 mcpServers 아래에 서버를 추가합니다. 위 설치 섹션에 표시된 Cursor 구성을 사용합니다.
webfetch를 사용하려면 API 키가 필요한가요?
아니요, DuckDuckGo는 키 없이 작동하므로 별도 비용 없이 바로 사용할 수 있습니다. Brave, Serper 또는 Tavily의 키를 추가하면 엔진 퓨전을 통해 검색 결과의 재현율을 높일 수 있습니다.
시맨틱 캐시는 어떻게 작동하나요?
SQLite 파일 내에 두 가지 레이어를 사용합니다. URL별 페이지 텍스트와 쿼리별 순위가 매겨진 결과가 저장됩니다. 동일한 쿼리에 대한 완전 일치뿐만 아니라, 유사하게 표현된 쿼리에 대한 시맨틱 매칭도 지원합니다.
webfetch는 토큰 사용량을 어떻게 줄이나요?
문장 단위 압축을 사용하여 쿼리에 답변하는 문장만 추출하므로, 재현율을 유지하면서도 토큰 사용량을 50%까지 줄일 수 있습니다.