
AI 코딩 에이전트가 가공의 API, 정의되지 않은 심볼, 잘못된 메서드 호출을 잡아낼 수 있도록 결정론적 검증 레이어를 제공합니다.
다른 이름 Fengrru/honestcode
- 스타
- 0
- Tools
- 7
- 다운로드, 30일
- 20
- 최신 버전
- 0.5.1
- 마지막 커밋
- 2026년 10월 25일
- 라이선스
- MIT
HonestCode MCP란?
HonestCode은(는) MCP server입니다. AI 코딩 에이전트가 가공의 API, 정의되지 않은 심볼, 잘못된 메서드 호출을 잡아낼 수 있도록 결정론적 검증 레이어를 제공합니다. 7개 도구를 제공합니다. 예: scan_file, verify_file, index_project.
프로젝트 README에서 생성된 요약
HonestCode MCP server 정보
HonestCode는 AI 코딩 에이전트의 할루시네이션을 잡아내기 위해 설계된 결정론적 검증 레이어입니다. 에이전트가 작성한 코드를 작업 중인 실제 리포지토리와 대조하여, 가공의 API, 정의되지 않은 심볼, 잘못된 메서드 호출을 구체적으로 식별합니다. 일반적인 린터와 달리, 이 도구는 모든 함수나 메서드 호출이 코드베이스 내에 존재하는 실제 심볼로 해결되는지 확인하는 리포지토리 그라운딩에 집중합니다.
이 서버는 AST 및 심볼 해석을 사용하여 완전히 로컬에서 실행되므로 LLM 호출이나 네트워크 접속이 필요하지 않습니다. Claude Desktop, Cursor, VS Code와 호환됩니다. 개발자는 uvx를 사용하거나, 지원되는 클라이언트를 자동으로 구성하는 내장 설치 명령어를 통해 설치할 수 있습니다. 시스템은 verify_file 및 scan_file과 같은 도구를 통해 구조화된 증거를 제공하므로, 에이전트가 사용 가능한 메서드나 오류 수정을 위한 제안과 같은 구체적인 피드백을 즉시 받아볼 수 있습니다.
활용 사례
- 1가공의 라이브러리 API 탐지AI 에이전트가 방금 생성한 메서드가 로컬 프로젝트 클래스에 실제로 존재하는지 확인하는 데 사용할 수 있습니다.
- 2할루시네이션된 메서드 호출 수정개발자가 에이전트에게 새 파일에 대한 검증을 실행하도록 요청하여 일치하지 않는 메서드 이름을 잡아낼 수 있습니다.
- 3코드 검증 루프 자동화에이전트가 작성하는 모든 Python 파일을 자동으로 검증하도록 post-tool hook을 구성할 수 있습니다.
프로젝트의 README를 바탕으로 작성되었습니다. 모든 활용 사례는 해당 내용의 인용문과 대조하여 확인합니다.
HonestCode MCP 설치 방법
형식 확인: 2026년 11월 10일Cursor에 추가Goose에 추가Claude Code에 HonestCode MCP 설치
$ claude mcp add honestcode -- uvx honestcodeCursor에 HonestCode MCP 설치
~/.cursor/mcp.json
{
  "mcpServers": {
    "honestcode": {
      "command": "uvx",
      "args": [
        "honestcode"
      ]
    }
  }
}VS Code에 HonestCode MCP 설치
.vscode/mcp.json
{
  "servers": {
    "honestcode": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "honestcode"
      ]
    }
  }
}VS Code CLI에 HonestCode MCP 설치
$ code --add-mcp '{"name":"honestcode","type":"stdio","command":"uvx","args":["honestcode"]}'Claude Desktop에 HonestCode MCP 설치
claude_desktop_config.json
{
  "mcpServers": {
    "honestcode": {
      "command": "uvx",
      "args": [
        "honestcode"
      ]
    }
  }
}Codex에 HonestCode MCP 설치
$ codex mcp add honestcode -- uvx honestcodeCodex config.toml에 HonestCode MCP 설치
~/.codex/config.toml
[mcp_servers.honestcode]
command = "uvx"
args = ["honestcode"]
Gemini CLI에 HonestCode MCP 설치
$ gemini mcp add -s user honestcode uvx -- honestcodeGemini settings.json에 HonestCode MCP 설치
~/.gemini/settings.json
{
  "mcpServers": {
    "honestcode": {
      "command": "uvx",
      "args": [
        "honestcode"
      ]
    }
  }
}HonestCode MCP 도구 7
README에서 감지됨scan_fileverify_fileindex_projectload_project_depscheck_symbolcheck_apivalidate_types
| scan_file | — | |
| verify_file | — | |
| index_project | — | |
| load_project_deps | — | |
| check_symbol | — | |
| check_api | — | |
| validate_types | — |
자동 검사
2026년 11월 14일에 실행됨전체 보고서 →자동 검사를 통과했습니다. 이는 보안 감사가 아닙니다. 코드를 직접 읽고 서버에 필요한 최소한의 권한만 부여하십시오. 검사 방식

- 소스 저장소 연결 및 접근 가능fengrru/honestcode is public and reachablegithub.com/fengrru/honestcode ↗통과
- 패키지가 이 저장소를 소스로 명시honestcode names fengrru/honestcode as sourcepypi.org/project/honestcode/ ↗통과
- 빌드 출처(Sigstore 증명)Sigstore attestation for honestcodepypi.org/project/honestcode/ ↗통과
- 오픈 소스 라이선스 (OSI)MITspdx.org/licenses/MIT.html ↗통과
- 최근 1년 내 커밋 또는 릴리스Last commit or release 2026-10-25github.com/fengrru/honestcode ↗통과
- OpenSSF Scorecard검사되지 않음
- 패키지 이름이 인기 패키지와 유사하지 않음No popular package one edit away from honestcode통과
- 패키지 및 해당 종속성에 중요한 보안 권고 없음31 resolved dependencies checked; no critical advisoryosv.dev ↗통과
- 모델에 대한 숨겨진 지침 없음7 tool descriptions and the README read; no override phrases, credential paths or hidden characters통과
- 파괴적인 도구에 라벨 표시됨No tool named like delete, drop or exec통과
- 원격 엔드포인트가 MCP 핸드셰이크에 응답검사되지 않음
README
GitHub에서 보기HonestCode
The deterministic verification layer for AI coding agents.
Catch invented APIs, undefined symbols, wrong calls, and other code hallucinations before your agent moves on.


The problem
AI coding agents hallucinate. They invent function names, fabricate library APIs, and call methods that do not exist.
HonestCode is the layer that checks what the agent just wrote against the repository it is supposed to be grounded in.
Agent
  ↓
writes code
  ↓
HonestCode
  ↓
evidence
  ↓
Agent fixes
  ↓
verified code
No LLM calls. No network. Pure AST + symbol resolution.
Demo
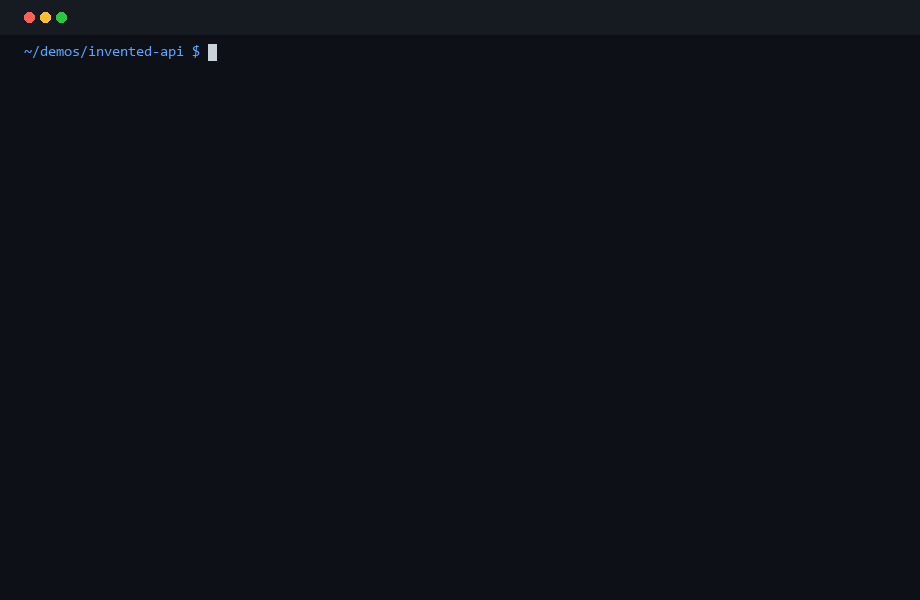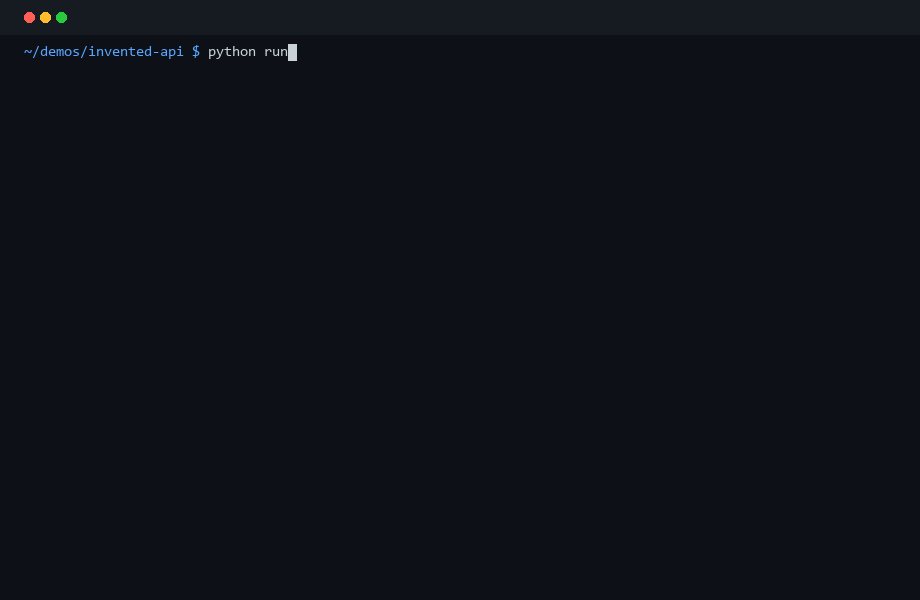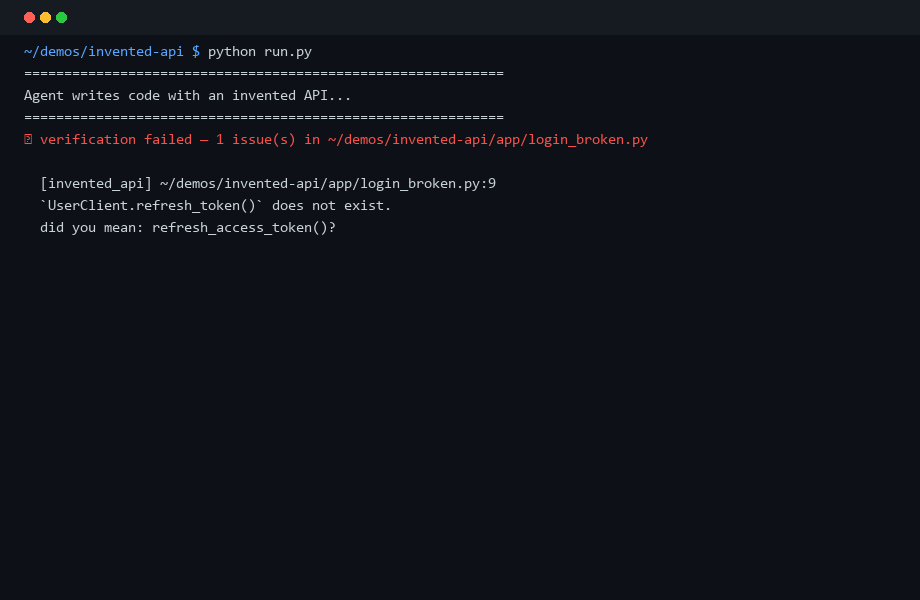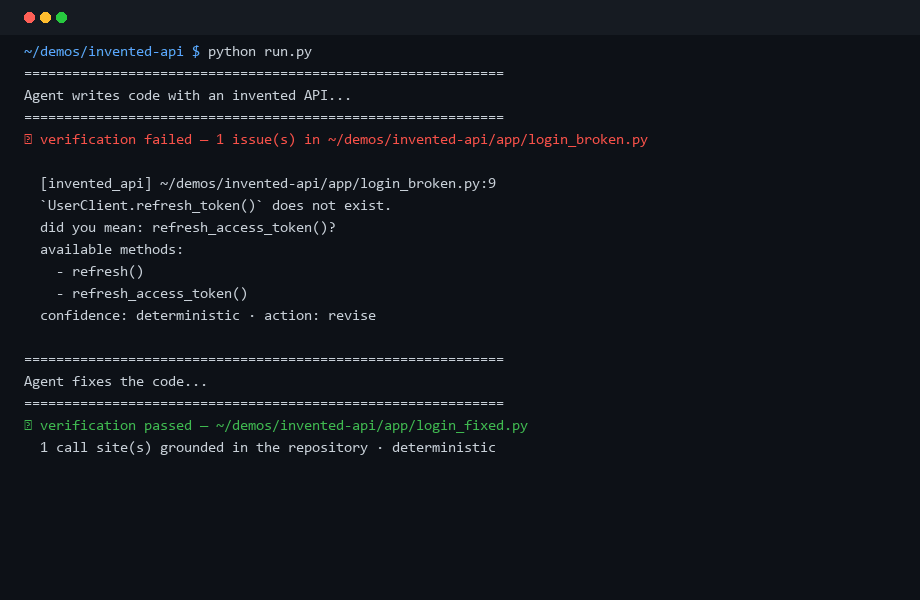
The agent was asked to "add authentication using the existing UserClient."
It generated:
client.refresh_token()
The real project only has:
class UserClient:
    def refresh(self): ...
    def refresh_access_token(self): ...
HonestCode catches it deterministically:
✗ verification failed — 1 issue in app/login_broken.py

  [invented_api] app/login_broken.py:9
  `UserClient.refresh_token()` does not exist.
  did you mean: refresh_access_token()?
  available methods:
    - refresh()
    - refresh_access_token()
  confidence: deterministic · action: revise
Run it yourself:
cd demos/invented-api
python run.py
Why not just use Ruff / Pyright?
HonestCode is not a replacement — it is a verification layer that answers a specific question: did the agent's code actually come from this repository?
| Error | Ruff | Pyright | HonestCode |
|---|---|---|---|
| Syntax error | ✓ | ✓ | ✓ |
| Type mismatch | — | ✓ | structural only |
| Undefined symbol | ✓ | ✓ | ✓ |
| Invented API | partial | partial | core |
| Wrong method call | — | partial | core |
| Agent-generated API mismatch | — | — | core |
The key difference is repository grounding. Ruff checks the file. Pyright
types the call. HonestCode checks whether the call resolves to a real symbol
that exists in the codebase the agent is editing. (HonestCode does not do full
type inference — its structural checks catch mismatched arities, iterating
None, and calling constants, not general type errors.)
What a call site is checked against depends on how the receiver's type is known:
an annotation (client: UserClient), a constructor assignment
(client = UserClient()), self/cls, and an inline constructor
(UserClient().refresh()) are all resolved. A receiver produced by a factory
function (make_client().refresh()) is not judged — function signatures
carry no return type in the surface model, and guessing there would trade a
missed finding for a false one.
Install
One line — no clone, no virtualenv:
claude mcp add honestcode -- uvx honestcode-mcp
uvx fetches the server into an isolated environment on first use; install
uv first if you do not have it. From a checkout
(to hack on the code, or if you prefer not to use uv):
git clone https://github.com/Fengrru/honestcode
cd honestcode
pip install -e .
claude mcp add honestcode -- honestcode-mcp
Cursor / VS Code / Claude Desktop: the honestcode install command probes
those clients' config files and registers the server for you:
honestcode install            # all detected clients
honestcode install --client cursor --dry-run   # preview without writing
Requires Python >= 3.10. 100% local.
30-second setup with Claude Code
# Add HonestCode as an MCP server
claude mcp add honestcode -- honestcode-mcp
Or add it manually to your Claude Code config (~/.claude.json on
macOS/Linux, %USERPROFILE%\.claude.json on Windows):
{
  "mcpServers": {
    "honestcode": {
      "command": "honestcode-mcp",
      "args": []
    }
  }
}
Restart Claude Code. You now have two verification tools available:
scan_file(path)— legacy tool, returnsissuesplus the new evidence shape.verify_file(path)— agent-facing tool, returnsstatus,findingswithevidence, and a human-readabletextsummary.
Try prompting Claude:
Add a login endpoint using the existing UserClient, then run verify_file on the
file you just wrote and fix anything it reports.
HonestCode auto-discovers the project root from the file path, indexes the codebase, and returns grounded evidence.
Making it automatic (no prompt discipline required)
MCP tools only run when the model chooses to call them. To make verification
unconditional, wire the hook in scripts/claude_hook.py into Claude Code's
PostToolUse event — every .py file the agent writes is verified, and a
finding blocks the edit with the evidence fed straight back into the
conversation:
{
  "hooks": {
    "PostToolUse": [
      {
        "matcher": "Write|Edit",
        "hooks": [
          {
            "type": "command",
            "command": "python /absolute/path/to/honestcode/scripts/claude_hook.py"
          }
        ]
      }
    ]
  }
}
Put that in ~/.claude/settings.json (all projects) or
.claude/settings.json (one project). The hook never blocks on its own
failures: unreadable input, non-Python files, and verification crashes all
exit silently, so it can never turn into a wall that blocks every edit.
Real example
# auth/client.py
class UserClient:
    def refresh_access_token(self): ...

# auth/login.py
from auth.client import UserClient

def login(client: UserClient):
    client.refresh_token()  # invented API
>>> from honestcode.mcp.tools import verify_file
>>> verify_file("auth/login.py")
{
  "status": "fail",
  "file": "auth/login.py",
  "findings": [
    {
      "line": 7,
      "kind": "invented_api",
      "symbol": "refresh_token",
      "owner": "UserClient",
      "message": "`UserClient.refresh_token()` does not exist.",
      "evidence": {
        "available_methods": ["refresh", "refresh_access_token"],
        "did_you_mean": "refresh_access_token"
      },
      "confidence": "deterministic",
      "action": "revise"
    }
  ],
  "text": "✗ verification failed — 1 issue in auth/login.py\n  ..."
}
Agent output protocol
verify_file returns evidence an agent can act on directly, not just an error
message:
{
  "status": "fail",
  "file": "auth/client.py",
  "line": 42,
  "kind": "invented_api",
  "symbol": "refresh_token",
  "owner": "UserClient",
  "message": "UserClient.refresh_token() does not exist.",
  "evidence": {
    "available_methods": ["refresh", "refresh_access_token"]
  },
  "confidence": "deterministic",
  "action": "revise"
}
How it works
- Auto-index the project (or reuse the cached symbol index).
- Parse the target file with the standard-library
astmodule. - Resolve every call site to a concrete symbol:
- infer the receiver type from annotations, constructors, and imports;
- reconstruct the class's member surface from the repository AST;
- mark the surface as unknown when a base class cannot be resolved or the
class defines
__getattr__.
- Emit findings with
kind,owner,evidence,confidence, andaction.
The loop is deterministic and auditable.
Scope and limitations
The verifier stays silent wherever it cannot prove absence — that is the feature, but it means detection has known boundaries:
- Decorated classes are not judged for invented members. Any class
decorator (including
@dataclass) may add or rewrite members, so invented method calls on such classes are not reported. Undecorated classes are fully checked. - Standard-library member calls are not checked.
from typing import TypeVarr(an invented import) is caught, butos.path.joinn()(an invented call on a real module) is not — third-party and project members are the covered surface. - Factory-function receivers are not judged.
make_client().refresh()is skipped; annotations, constructor assignments,self/cls, and inline constructors (UserClient().refresh()) are resolved. undefined_symbolcarriesconfidence: high, notdeterministic. Only member-surface claims (invented APIs on a fully enumerated class) are provable from the repository; name absence rests on the syntactic binding model and keeps the lower confidence. Variables reassigned across types in one scope are treated as unknown and never judged.- Graph tools are anchored to the last indexed project.
scan_file/verify_fileresolve the project root per file (including monorepo sub-projects);find_dead_code,explore_call_graph,search_codeand friends operate on the project most recently passed toindex_project. check_apiimports the base package on demand — but only when it is genuinely installed (or stdlib). A bare file dropped into the workspace is never imported, so agent-authored code cannot be executed server-side through this tool.
MCP tools
By default scan_file and verify_file are exposed. Set HONESTCODE_TOOLS=all
to enable the full set, including:
| Tool | Purpose |
|---|---|
scan_file |
Scan a file for invented APIs, undefined calls, and wrong arities. |
verify_file |
Return the agent-facing structured evidence protocol. |
index_project |
Build or reuse the project symbol index. |
load_project_deps |
Load dependency APIs from requirements.txt / pyproject.toml. |
check_symbol |
Verify a symbol is defined. |
check_api |
Verify a library API call exists. |
validate_types |
Structural type checks. |
Dependency manifests (requirements.txt, pyproject.toml) are declared
automatically on the first scan, so imports from a dependency that is not
installed in the MCP server's interpreter are trusted rather than reported as
invented. Set HONESTCODE_AUTO_DEPS=0 to disable that.
See the old tool reference below for the complete list.
Crash-safe side effects
verify_file checks code before it runs. guards/ covers what happens after:
an agent that retries a tool call can charge a card twice, and no durable
execution engine prevents it — Temporal and Restate both guarantee deterministic
replay of orchestration and leave exactly-once external effects to the
application.
from honestcode.guards import EffectStore, SideEffectGuard, durable_scope

guard = SideEffectGuard(session_id="run-42", store_path=".agent/effects.db")

outcome = guard.run(
    "charge",
    target="cus_123",
    payload={"cents": 4200},
    execute=lambda: charge_card("cus_123", 4200),
    approve_irreversible=True,
    scope=durable_scope("order-4711", "charge", "cus_123"),
)

outcome.executed     # False on the retry — a receipt, not a second charge
outcome.effect_id    # stable across a restart, because the key is on disk
The interesting part is what scope does. Pass it and the effect's identity
comes from the scope rather than the session — which is the difference between a
retry being recognised and a customer being charged twice, because a restart is
a new session id. Pass nothing and the guard stays session-scoped.
Refusing is the default direction: an unrecognised action is treated as
irreversible rather than idempotent, and irreversible effects need explicit
approval. A run that dies between the call and the record leaves the effect
executing, and the next attempt reports the outcome as unknown instead of
guessing — which is what stops the retry. Scoped effects are recovered with
guard.recover(scope=durable_scope(...)), and guard.effects(scope=...) /
guard.summary(scope=...) report them; the records live under a namespace
derived from the scope so a restart can still find them.
For a framework, integrations/ binds the guard to pydantic-ai, where a
committed effect replaces the tool result instead of re-running the tool. See
honestcode/integrations/README.md.
Benchmark
HonestCode includes four benchmark suites that run automatically in CI on every
push and pull request to main:
Agent-accuracy benchmark
benchmarks/agent_accuracy/ is a deterministic, LLM-free benchmark that
measures how well HonestCode catches common agent hallucinations (recall).
Each task is a tiny agent episode: the agent writes a broken file, HonestCode verifies it, then the file is replaced with the fix and verified again.
cd benchmarks/agent_accuracy
python run.py
Current results (6 tasks, deterministic verification):
| task | expected issue | broken detected | fixed clean | broken ms | fixed ms |
|---|---|---|---|---|---|
| invented_method | invented_api (UserClient.refresh_token) |
yes | yes | 4.18 | 3.78 |
| invented_module_attr | invented_api (Connection.query) |
yes | yes | 4.19 | 3.95 |
| undefined_import | undefined_symbol (delete_user) |
yes | yes | 2.69 | 3.55 |
| wrong_signature | wrong_call (add()) |
yes | yes | 3.56 | 3.35 |
| cross_file_new_symbol | invented_api (fly) |
yes | yes | 3.85 | 2.45 |
| dep_alias_and_pypi_name | invented_api (toll) |
yes | yes | 3.44 | 2.9 |
Summary: precision 1.0, recall 1.0, F1 1.0, false-positive rate 0.0, median verify time 4–7 ms on a laptop.
The per-task milliseconds above are one run's output, not a guarantee — they move a few tens of percent between runs on the same machine. What is stable, and what the benchmark is gating on, is the first four columns plus the summary's counts.
The summary line is python benchmarks/agent_accuracy/run.py verbatim rather
than a figure copied into this file, because a timing quoted here goes stale the
moment the code gets faster — as one did. Reproduce it with --format markdown.
The cross_file_new_symbol task pins the agent-session flow (write a module,
then a file importing it — the index must be fresh, never stale); the
dep_alias_and_pypi_name task pins dependency grounding through aliased
submodules and PyPI-named requirements (PyYAML → yaml).
Real-world false-positive benchmark
benchmarks/realworld_fp/ measures precision on real code: it scans a
vendored snapshot of psf/requests (19 files, ~6.4k LOC, Apache-2.0) and
asserts HonestCode reports zero findings. Real code exercises the
constructs synthetic tasks never do — stdlib imports, keyword-call style,
@staticmethod members, classes inheriting stdlib ABCs, compat re-export
modules — and any finding on this corpus is, by construction, a false
positive.
The same run also scans benchmarks/realworld_fp/regressions/: one tiny
project per false-positive class found in the wild (a receiver rebound across
types, with ... as bindings, monorepo sub-project imports, local binding
forms). Each scenario fails the benchmark by name if the regression returns.
python benchmarks/realworld_fp/run.py
# files: 25  findings: 0  elapsed: 0.7s (~26 ms/file)
The finding count is the claim; the elapsed time is indicative, and varies with the machine.
Value-drift benchmark
benchmarks/value_drift/ asks a different question: when a formatting-tolerant
edit matcher resolves a search string, did the edit land on the region the
caller named, or silently on a near-miss sibling that carries a different value?
It runs ten scenarios across a guarded matcher cascade and an unguarded one, and
classifies each edit as correct, silent_drift, no_match, or wrong_span.
The guarded matcher must produce the intended edit on every scenario; a
no_match is a refusal, not a pass.
python benchmarks/value_drift/run.py            # human-readable
python benchmarks/value_drift/run.py --json     # machine-readable (status on stderr)
Performance benchmark
scripts/benchmark.py measures the latency of core operations (index, scan,
graph, dead code detection, similarity search) on the repository itself.
python scripts/benchmark.py                          # text output
python scripts/benchmark.py --format markdown        # table for README
python scripts/benchmark.py --repo psf/requests      # benchmark a real-world repo
All four benchmarks run in CI (.github/workflows/ci.yml) as separate jobs:
benchmark-accuracy, benchmark-realworld, benchmark-value-drift, and
benchmark-performance. The accuracy job gates on precision and recall staying
at 1.0, the real-world job on any finding or failed scan, and the value-drift
job on every guarded scenario landing correctly. The performance job reports
numbers rather than gating on them.
See benchmarks/agent_accuracy/README.md for the dataset format and how to
add new accuracy tasks.
Architecture
honestcode/
├── verify/        # Evidence protocol + repository-grounded verification
├── mcp/           # MCP server layer
├── honest/        # Symbol index + project binding
├── graph/         # Persistent call graph (SQLite)
├── structure/     # AST extraction
├── sandbox/       # Sandboxed execution
├── guards/        # Crash-safe side effects (stdlib-only, extractable)
├── integrations/  # Framework bindings — pydantic-ai today
└── cli.py         # Command-line interface
verify_file is the agent interface. scan_file is exposed alongside it by
default and returns both the new evidence shape and the legacy issues list.
Two of those directories answer a different question from the rest. Everything
above guards/ asks is this code consistent with the repository. guards/
asks did this effect already happen — an agent that retries a tool call after
a crash can charge a card twice, and durable-execution engines leave exactly-once
external effects to the application. integrations/ binds the guard to a
framework; pydantic-ai's wrap_tool_execute is the first, and a tool result is
replaced rather than re-run when the effect has already been committed.
guards/ is deliberately stdlib-only and does not depend on this package's
protocols, so it can be extracted into its own distribution. tests/test_guards.py
enforces that with an AST import check.
Roadmap
v0.1 — Repository grounding (done)
- symbol / API / function / class / method / import / call verification
- invented API detection with structured evidence
- auto-index on
scan_file
Beyond the roadmap — crash-safe side effects (now)
Not a verification layer, so it has no place in the v0.2/v0.3 sequence below:
guards/ makes an effect idempotent across a crash, and integrations/ binds
it to pydantic-ai. It answers "did this already happen", which is a runtime
question rather than a static one.
v0.2 — Semantic contract verification
- function expects
UserID, agent passesUser→ suspicious
v0.3 — Execution verification
- static verification → tests → runtime evidence
v1.0 — Verification Runtime for Coding Agents
                 Coding Agent
                      │
              ┌───────▼───────┐
              │   HonestCode  │
              │ Verification  │
              │    Runtime    │
              └───────┬───────┘
                      │
       ┌──────────────┼──────────────┐
       ↓              ↓              ↓
   Static          Semantic       Runtime
 Verification     Verification   Verification
       │              │              │
       └──────────────┼──────────────┘
                      ↓
                   Evidence
                      ↓
                     Agent
Development
git clone https://github.com/Fengrru/honestcode.git
cd honestcode
python -m venv .venv
.venv\Scripts\activate  # Windows
# source .venv/bin/activate  # macOS/Linux
pip install -e ".[dev]"
pytest
ruff check honestcode tests scripts
Run benchmarks locally:
# Accuracy benchmark
python benchmarks/agent_accuracy/run.py

# Performance benchmark
python scripts/benchmark.py
See CONTRIBUTING.md for pull request guidelines.
Security
See SECURITY.md for vulnerability reporting.
Telemetry
HonestCode collects no telemetry. There are no analytics libraries, no background services, and no phone-home endpoints.
License
MIT - Copyright (c) 2026 HonestCode Team
MCP Registry: mcp-name: io.github.Fengrru/honestcode
HonestCode MCP 질문
HonestCode MCP를 Claude Code에 추가하려면 어떻게 하나요?
터미널에서 claude mcp add honestcode -- uvx honestcode를 실행합니다. 모든 프로젝트에서 사용할 수 있게 하려면 --scope user를 추가합니다.
HonestCode MCP를 Cursor에 추가하려면 어떻게 하나요?
~/.cursor/mcp.json를 열고 mcpServers 아래에 서버를 추가합니다. 위 설치 섹션에 표시된 Cursor 구성을 사용합니다.
HonestCode MCP는 어떤 도구를 제공하나요?
7개 도구를 제공합니다. 예: scan_file, verify_file, index_project, load_project_deps, check_symbol.
HonestCode는 Ruff나 Pyright와 어떻게 다른가요?
Ruff와 Pyright는 구문과 타입을 검사하지만, HonestCode는 에이전트가 작성한 코드가 특정 코드베이스에 실제로 존재하는 심볼을 사용하는지 확인하기 위해 리포지토리 그라운딩(repository grounding)을 제공합니다.
HonestCode를 사용하려면 LLM 호출이나 네트워크 접속이 필요한가요?
아니요, LLM 호출이나 네트워크 연결 없이 AST 및 심볼 해석을 사용하여 완전히 로컬에서 작동합니다.
Claude Desktop이나 Cursor에서 HonestCode를 사용할 수 있나요?
네, honestcode install 명령어를 통해 Claude Desktop, Cursor, VS Code용 서버를 자동으로 탐색하고 등록할 수 있습니다.