
Git 방식의 콘텐츠 주소 지정 저장소를 사용하여 여러 기기와 도구 간에 동기화되는 버전 관리 및 검색 가능한 AI 메모리를 제공합니다.
다른 이름 code4161/memgit, memgit-mcp
- 스타
- 4
- Tools
- —
- 다운로드, 30일
- 925
- 최신 버전
- 0.16.0
- 마지막 커밋
- 2026년 11월 12일
- 라이선스
- MIT
memgit MCP란?
memgit은(는) MCP server입니다. Git 방식의 콘텐츠 주소 지정 저장소를 사용하여 여러 기기와 도구 간에 동기화되는 버전 관리 및 검색 가능한 AI 메모리를 제공합니다.
프로젝트 README에서 생성된 요약
memgit MCP server 정보
memgit은 여러 기기와 도구 간에 동기화되는 AI 코딩 agent용 버전 관리 및 검색 가능한 메모리 레이어를 제공합니다. SHA-256 기반의 콘텐츠 주소 지정 객체 저장소를 사용하여 모든 메모리의 안정성과 복구 가능성을 보장합니다. 이 시스템을 통해 개발자는 노트북, 데스크톱 또는 원격 서버와 같이 환경을 전환할 때 일관된 컨텍스트를 유지할 수 있으며, 동기화 과정에서 종단간 암호화를 사용하여 데이터를 보호합니다.
사용자는 MCP 또는 직접 설치를 통해 Claude Code, Cursor, Windsurf, Gemini CLI를 포함한 다양한 AI 클라이언트에 이 메모리를 통합할 수 있습니다. 이 server는 변경 사항 비교(diff) 및 잘못된 항목 복구(rollback)와 같은 고급 버전 관리 기능을 지원합니다. 또한 기존 저장소에서 프로젝트 정보를 추출하는 onboard라는 시딩 메커니즘을 포함합니다. 팀 단위에서는 메모리를 git 저장소처럼 취급하여 GitHub와 같은 플랫폼에 push함으로써 학습된 규칙과 컨벤션을 그룹 전체가 공유할 수 있습니다.
활용 사례
- 1기기 간 메모리 동기화개발자는 클라우드 동기화 기능을 사용하여 AI agent가 학습한 규칙을 로컬 노트북과 원격 서버 모두에서 사용할 수 있습니다.
- 2잘못된 AI 메모리 업데이트 되돌리기AI agent가 중요한 프로젝트 규칙을 잘못된 정보로 덮어쓴 경우, 개발자는 rollback 명령어를 사용하여 이전 상태로 복구할 수 있습니다.
- 3기존 코드베이스로부터 메모리 초기화새 프로젝트를 시작할 때 개발자는 아키텍처와 컨벤션을 자동으로 추출하여 AI에게 즉각적인 컨텍스트를 제공할 수 있습니다.
- 4팀과 AI 컨텍스트 공유팀은 표준 git 명령어를 사용하여 AI가 학습한 지식을 공유 저장소에 push하고 모든 팀원이 이를 사용할 수 있습니다.
프로젝트의 README를 바탕으로 작성되었습니다. 모든 활용 사례는 해당 내용의 인용문과 대조하여 확인합니다.
memgit MCP 설치 방법
형식 확인: 2026년 11월 10일Claude Code에 memgit MCP 설치
$ claude mcp add memgit -- npx -y memgit-mcpCursor에 memgit MCP 설치
~/.cursor/mcp.json
{
  "mcpServers": {
    "memgit": {
      "command": "npx",
      "args": [
        "-y",
        "memgit-mcp"
      ]
    }
  }
}VS Code에 memgit MCP 설치
.vscode/mcp.json
{
  "servers": {
    "memgit": {
      "type": "stdio",
      "command": "npx",
      "args": [
        "-y",
        "memgit-mcp"
      ]
    }
  }
}Claude Desktop에 memgit MCP 설치
claude_desktop_config.json
{
  "mcpServers": {
    "memgit": {
      "command": "npx",
      "args": [
        "-y",
        "memgit-mcp"
      ]
    }
  }
}Codex에 memgit MCP 설치
~/.codex/config.toml
[mcp_servers.memgit]
command = "npx"
args = ["-y", "memgit-mcp"]
Gemini CLI에 memgit MCP 설치
~/.gemini/settings.json
{
  "mcpServers": {
    "memgit": {
      "command": "npx",
      "args": [
        "-y",
        "memgit-mcp"
      ]
    }
  }
}자동 검사
2026년 11월 14일에 실행됨전체 보고서 →자동 검사를 통과했습니다. 이는 보안 감사가 아닙니다. 코드를 직접 읽고 서버에 필요한 최소한의 권한만 부여하십시오. 검사 방식
- 소스 저장소 연결 및 접근 가능code4161/memgit is public and reachablegithub.com/code4161/memgit ↗통과
- 패키지가 이 저장소를 소스로 지정memgit-mcp, memgit name code4161/memgit as sourcenpmjs.com/package/memgit-mcp ↗통과
- 빌드 출처(Sigstore 증명)No build attestation published for this release검사되지 않음
- 오픈 소스 라이선스 (OSI)MITspdx.org/licenses/MIT.html ↗통과
- 최근 1년 내 커밋 또는 릴리스Last commit or release 2026-11-12github.com/code4161/memgit ↗통과
- OpenSSF Scorecard검사되지 않음
- 패키지 이름이 인기 패키지와 유사하지 않음No popular package one edit away from memgit-mcp, memgit통과
- 패키지와 의존성에 심각한 보안 권고 없음the package checked; no critical advisoryosv.dev ↗통과
- 모델에 대한 숨겨진 지침 없음0 tool descriptions and the README read; no override phrases, credential paths or hidden characters통과
- 파괴적인 도구에 라벨 표시됨검사되지 않음
- 원격 endpoint가 MCP 핸드셰이크에 응답검사되지 않음
README
GitHub에서 보기memgit — one memory for your AI coding agents
The same memory in every session, on every machine, in every tool. Versioned, so a wrong memory is one command to undo.
Claude Code now remembers things on its own, on one machine. Its docs are plain about the limit: auto memory is machine-local and is not shared across machines or cloud environments. memgit is the layer on top. It imports what Claude Code already keeps and adds the three things built-in memory does not do:
- Every machine. Your laptop, your desktop and a server hold the same memory, synced end-to-end encrypted.
- Every tool. Claude Code, Cursor, Codex, Windsurf, Gemini CLI and any MCP host read and write one store.
- History. Every change is a checkpoint.
memgit diffshows what an agent changed andmemgit rollbackputs it back.
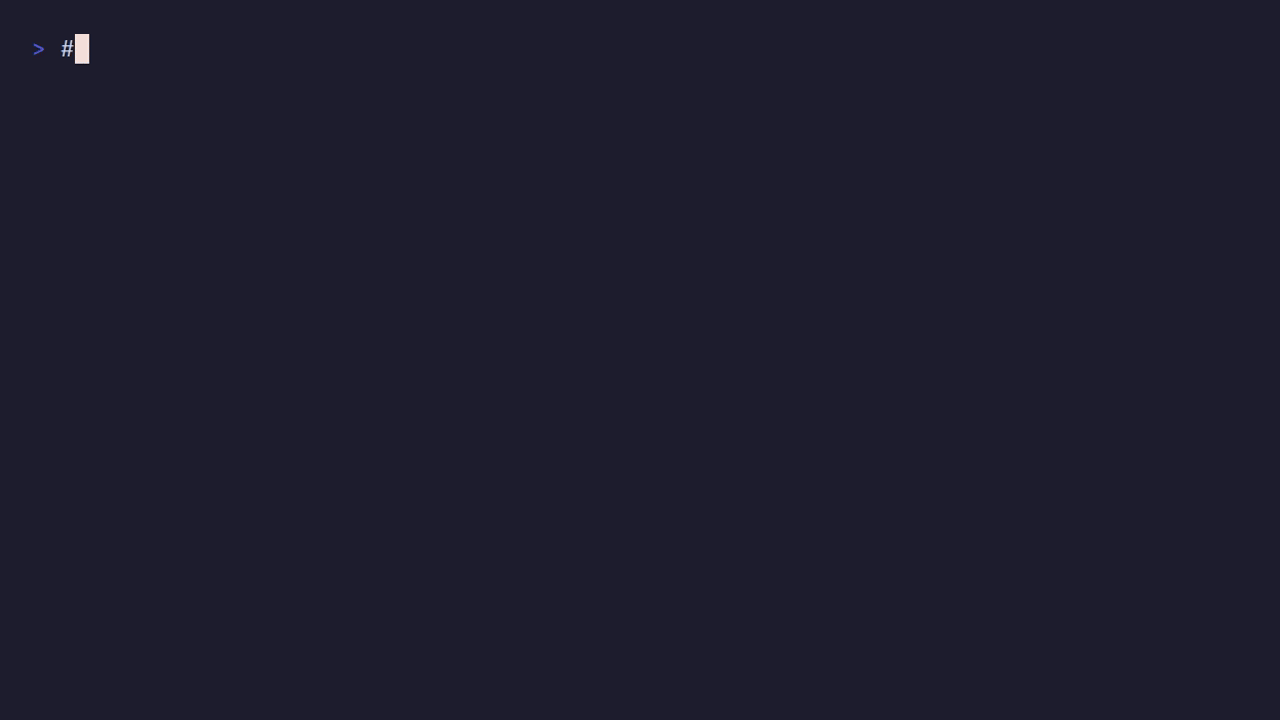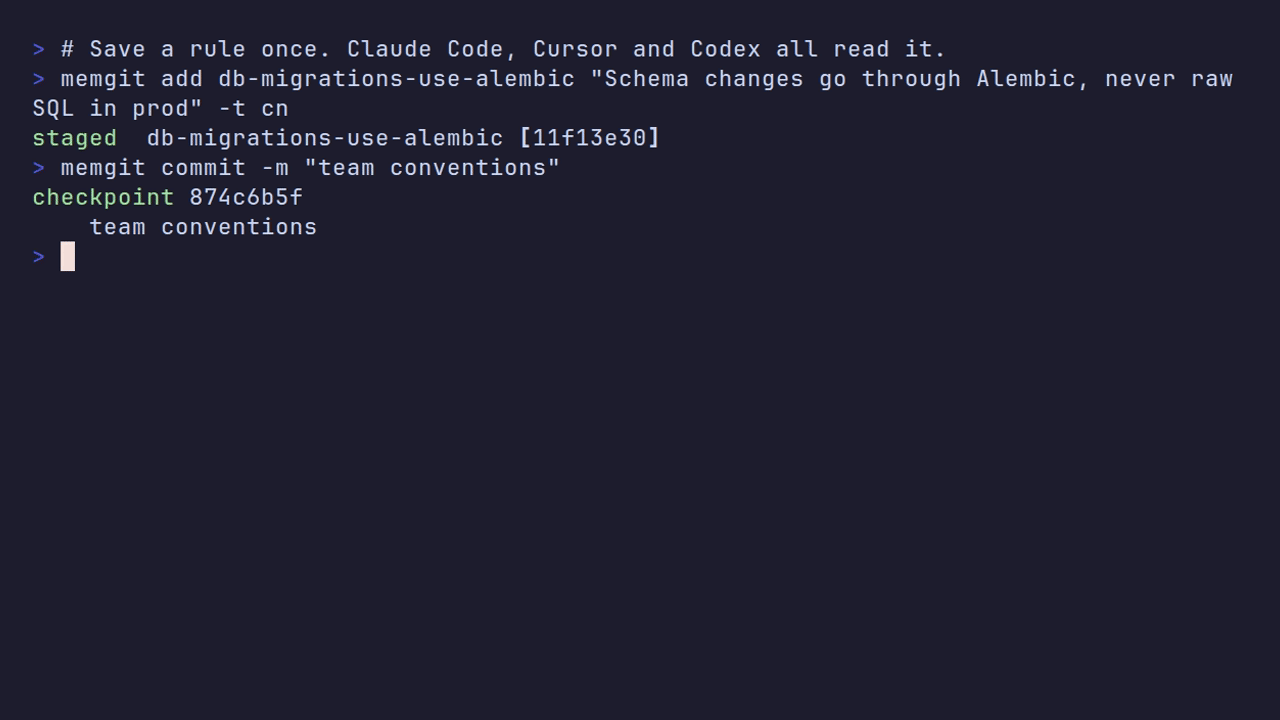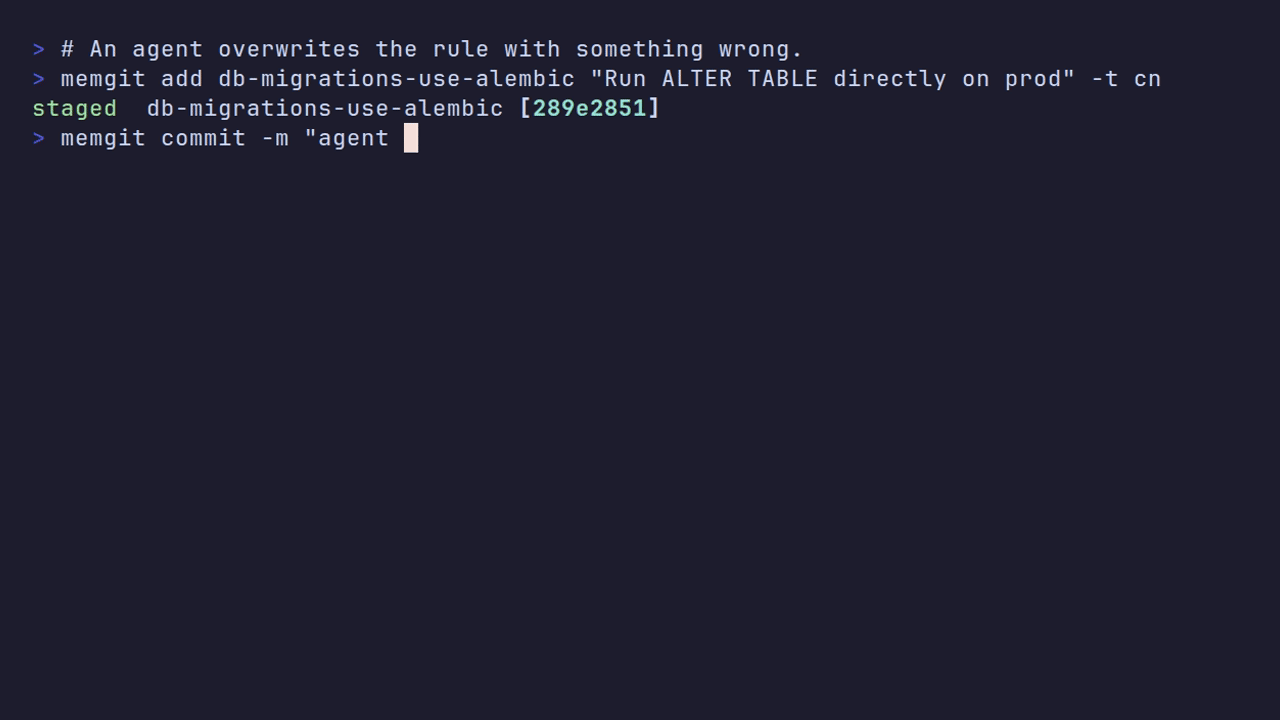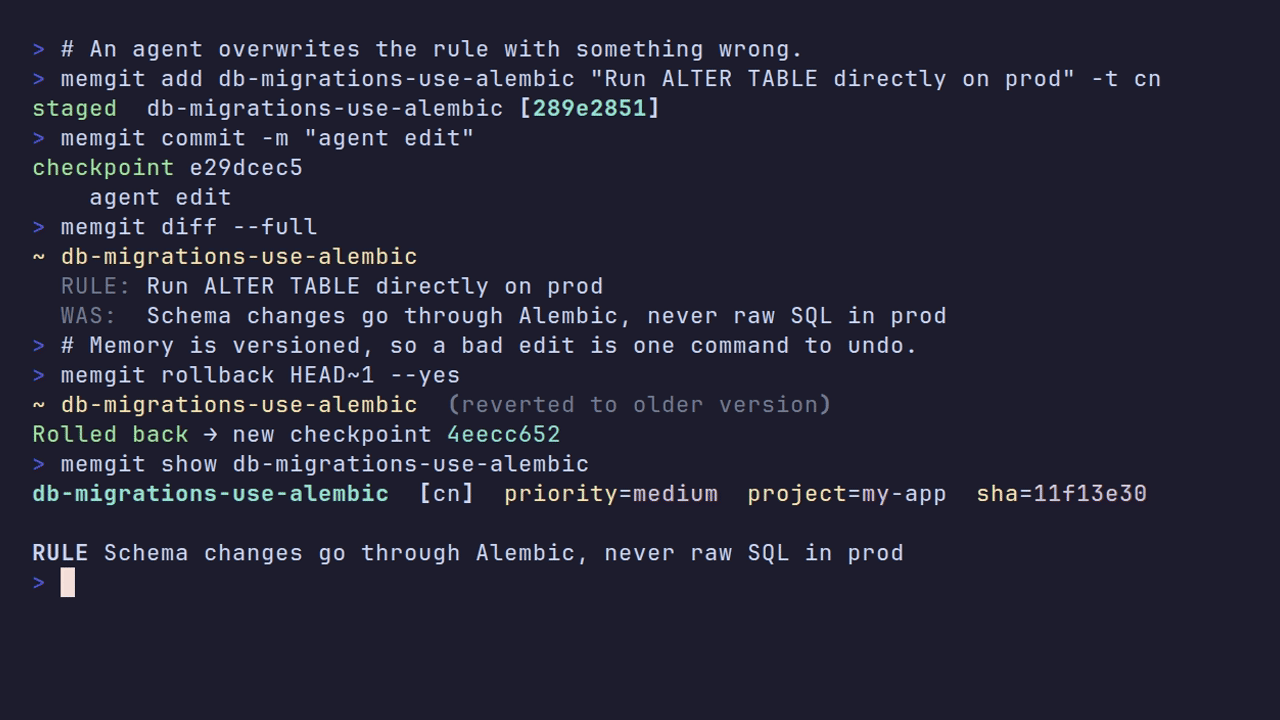
Unedited terminal recording, regenerated from the released package on every release.


Install
Claude Code (two commands inside Claude Code, nothing else to set up):
/plugin marketplace add code4161/claude-plugins
/plugin install memgit@memgit
The plugin starts the memory server, creates the store on first use and adds the hooks that bring memory in at session start and save what a session learns. It needs Node and Python 3.11+ on the machine.
Any other tool, or the full CLI:
pip install memgit        # or: brew tap code4161/tap && brew install memgit
memgit init               # creates the store, imports the memory Claude Code already keeps,
                          # and offers to connect every AI tool it finds on this machine
That is the whole setup. Restart your AI tool: it now starts each session with your memory and saves what it learns. memgit resume shows exactly what it will see.
Any MCP host by config (needs Python 3.11+ on PATH; the first run installs memgit into its own environment and creates the store):
{ "mcpServers": { "memgit": { "command": "npx", "args": ["-y", "memgit-mcp"] } } }
Windows: choco install memgit (new versions can wait a few days in Chocolatey moderation; pip install memgit always has the latest).
The same memory on your other machines
memgit cloud signup       # on the first machine: one passphrase, then it syncs on its own
memgit cloud login        # on every other machine
Every save goes up in the background and other machines' memories arrive at session start and while you work. The server stores ciphertext only; the passphrase never leaves your machine. Free for 14 days with no card, then $12 a month or $99 a year. The local engine, the store, the MCP server and every command are MIT and never gated, and a lapsed plan never locks your data: it stays on your machine, readable and exportable.
Until a store is connected, memgit may show one line about this, decided on your machine and sent nowhere: when the store reaches 50 and 250 memories, when it is opened on a second machine, and after an export or a backup, each at most once, for example "214 memories are on this machine. memgit cloud signup puts them on your other machines too (14 days free, no card). Setup tips by email: memgit tips ." Turn it off with memgit cloud hint off or MEMGIT_NO_SYNC_HINT=1.
memgit tips you@example.com asks memgit.dev for four short setup emails over ten days. It sends that address and nothing else; memgit.dev emails a confirmation link first, and every tip has a one-click unsubscribe link.
Check it yourself
memgit fsck                                   # every object verified by SHA-256
memgit stats                                  # what your context costs with and without memgit, measured on your store
memgit cloud auto status                      # whether anything leaves this machine, and when it last did
With no cloud login and no licence key, memgit talks to nothing.
Why not claude.md? Why not mem-search?
You've probably already tried both. Here's why they hit a ceiling:
| Capability | claude.md | mem-search plugin | memgit |
|---|---|---|---|
| Loads only relevant context | ❌ loads everything | ⚠️ loads recent observations | ✅ BM25 search — top-k per query |
| Project-aware across a multi-repo life | ❌ per-file | ❌ | ✅ memories carry a project; the current workspace ranks first |
| Adopt on an existing codebase | ❌ starts blank | ❌ starts blank | ✅ memgit onboard — seed the store from the repo in one pass |
| Version history | ❌ | ❌ | ✅ full commit log |
| Diff between sessions | ❌ | ❌ | ✅ memgit diff |
| Roll back a wrong memory | ❌ manual edit | ❌ | ✅ memgit rollback |
| Works in Cursor, Windsurf, GPT | ❌ Claude only | ❌ Claude only | ✅ all via MCP / HTTP |
| Team sync | ❌ copy-paste files | ❌ | ✅ memgit git push |
| Scales to 10k+ sessions | ❌ file grows | ❌ search slows | ✅ memgit squash |
| Measurable token savings | ❌ | ❌ | ✅ memgit stats |
| Export / import standard format | ❌ | ❌ | ✅ TOON + git |
Proof — context costs you can measure
Run this on your own store to see the actual numbers (measured where possible; estimates labeled):
$ memgit stats

  Total memories:   108   (41 feedback · 23 user · 19 project · 12 reference · 8 convention · 5 lesson)
  Priority:          3 critical · 67 medium · 38 low

  Context footprint  (measured where possible; estimates labeled)

  Surface                                             Tokens
  Full store (every memory as context)                12,840
  Resume digest  (measured render)                       540
  Recall block  (estimate: top-3 rules ≈ chars/4)        ~60

  per-session injected ≈ 600 tokens (estimate) vs 12,840 tokens if the full store were loaded
Why such a big difference? claude.md loads all context every session. memgit injects a bounded resume digest plus BM25-matched recall — only what is relevant to this session, not everything you've ever recorded. The digest is measured by actually rendering it, and the store total is the real corpus size; nothing here is a simulated benchmark.
The git analogy is literal
memgit's data model maps exactly to git:
| memgit | git |
|---|---|
mnemonic |
file |
MindState |
tree |
checkpoint |
commit |
thread |
branch |
memgit commit |
git commit |
memgit diff |
git diff |
memgit log |
git log |
memgit squash --keep-last 100 |
git rebase -i --autosquash |
memgit git push |
git push |
This is not metaphorical — memgit uses a content-addressed object store (SHA-256 blobs) identical to git's architecture. Every memory has a stable SHA. Identical content has identical SHAs. Old state is always recoverable.
The store IS a git repo
Every memory is a readable .toon file under memories/. Push your entire memory set to GitHub with standard git:
memgit git init --remote git@github.com:yourteam/ai-memory.git
memgit git push
Teammates pull and start with your AI's learned rules from session 1:
git clone git@github.com:yourteam/ai-memory.git ~/.claude/memgit-store
memgit setup all
You can grep, git blame, and git diff your memories just like code:
grep -rl "database" ~/.claude/memgit-store/memories/
git log --follow memories/no-db-mock.toon
git diff HEAD~7 memories/
Adopting memgit mid-project
Memory tools have a cold-start problem: install one halfway through a project and it knows nothing — there's no initial point, and context only trickles in from future sessions. memgit solves this with a one-time seeding pass:
cd your-project
memgit onboard          # mines the repo, prints the bootstrap brief
onboard first extracts a repo digest deterministically — git history (recent commit subjects, hot files/directories by churn, authors, branch, tags), detected stack from manifests, and the docs worth reading — using bounded, read-only probes that stay near-instant even on huge repositories. The brief then tells your AI agent exactly what to do with it: read only the listed files (no tree crawling), extract 10–20 durable facts (purpose, architecture, conventions, current state, gotchas), save each as a typed memory, and checkpoint the seed set. Paste it into a session — or don't: if the AI searches memory in a project that has none, the MCP server itself replies with the bootstrap instructions instead of a bare "no results."
Memories are project-scoped, filter-by-default (v0.7.0): each carries the workspace it belongs to, and searches, recall injections, and the resume digest (recent memories, checkpoints, depth hints) are filtered to the current project's family plus explicitly-global memories — another project's content never leaks in. Widen deliberately with memgit search --all-projects / all_projects: true (every hit then carries its project label), or hard-filter one project with --project. A memory with no project is explicitly global (applies everywhere): save one with memgit add --global or project: "". A save whose project cannot be determined is never silently global — it's quarantined under _unknown (visible in list as [?project], flagged by lint, surfaced nowhere) until you relabel it with memgit doctor --relabel.
Resume where you left off
Ask an AI "can we proceed on the pending tasks?" in a fresh session and it will guess from whatever file happens to be open. memgit resume replaces the guess with the record:
memgit resume            # last checkpoints, work in flight, recent + critical memories
memgit resume --plain    # plain text, for piping into an AI context
memgit resume --json     # for tooling
Wire it into Claude Code so memory becomes automatic — no tool call, no judgment required:
memgit setup hooks # installs all six hooks (~/.claude/settings.json)
| Hook | What it enforces |
|---|---|
SessionStart |
every session opens with the resume digest in context — status board, checkpoints, critical rules, memory index |
UserPromptSubmit |
each prompt is BM25-matched against the store; relevant memories are injected, ending with a "+N more on ''" depth hint when more exists (silent when nothing clears the relevance bar; never repeats within a session) — --no-recall to skip |
PreToolUse |
a Bash or file-write call that matches a memory's triggers is refused with the rule as the reason (priority-3 feedback and conventions) or gets the rule as context (the rest). memgit allow SLUG opens a short override window. Trigger cache only, --no-gate to skip |
PostToolUse |
reading a file whose path matches a memory tag surfaces a one-line hint ("6 memories tagged 'x' relate to this path") — tagmap cache only, capped 3/session, --no-ctx-recall to skip |
Stop (guard) |
a governed call that went through without the gate, or a session that did real work but saved nothing, gets ONE block before finishing. --no-guard to skip |
Stop (sync) |
markdown memories are checkpointed asynchronously at session end |
Why hooks and not just good tool descriptions? We measured it: across 166 real sessions, hook-injected context was delivered in 100% of them while voluntary memory-tool calls happened in 6%. What a hook enforces happens.
The resume digest is deliberately bounded (~350 tokens measured on a 500-memory store): rules are clipped, the critical list is capped, and full text is one get_memory call away.
Scale to 10,000+ sessions
After months of use, your checkpoint history grows. Squash compresses it, gc reclaims the disk:
memgit squash --keep-last 100    # keep last 100 checkpoints, squash everything older
memgit squash --older-than 30    # squash everything older than 30 days
memgit squash --dry-run          # preview first

memgit gc                        # delete unreachable objects, trim reflogs
memgit gc --dry-run              # preview
memgit gc --squash-keep 200      # compact history, then sweep
The current memory state is always preserved — and squash is lossless-in-substance: every collapsed checkpoint leaves a one-line record (time, author, diff, message) in an append-only archive under .memgit/logs/archive/ that gc never touches. Benchmark on a 2,000-checkpoint store: 94% smaller (39.5 MB → 2.2 MB), fsck clean. History operations stay O(1) as the chain grows (SHA resolution and checkpoint counting measured at ~0.08 ms at 2,000 checkpoints).
Multiple agents, one memory
All writes go through a git-style store lock (0.08 ms overhead), so concurrent agents can't corrupt the store or lose each other's updates. Two patterns:
Shared thread — agents write concurrently; if one commits while another has work staged, the second commit auto-merges (three-way, against the recorded base) instead of clobbering. Set MEMGIT_AUTHOR=agent-name so each checkpoint says who did it.
Thread per agent — isolate, then integrate:
memgit thread create agent-1     # branch off for each agent
# ... agents work on their own threads ...
memgit merge agent-1             # three-way merge back (common-ancestor based)
Conflicts (same memory changed on both sides) resolve to the newest version; an edit always beats a delete. Both histories are preserved.
What the AI sees
Once registered via MCP, every AI tool gets 6 tools:
| Tool | When the AI uses it |
|---|---|
resume_session |
When the request depends on prior state — "continue", "the pending tasks", session start |
search_memories |
Before answering anything that touches past work or preferences |
get_memory |
When it needs full details of a specific memory |
list_memories |
To browse or audit what's stored |
save_memory |
When it learns something worth keeping for next time |
get_checkpoint_log |
To check when memories were last synced |
The tool descriptions teach the AI judgment — "does this request depend on state you don't have in context?" — rather than keyword triggers. Measured cost of the whole tool surface: ~1,150 tokens once per session; a resume_session reply is ~335.
A save that arrives damaged is refused, not stored (v0.13.0). A model sometimes closes a value with a tag named after the field (</rule>), and the host then delivers the next parameters inside that value: why, when, tags and type_code never arrive, and the memory is stored with defaults. On one machine that was 748 of 3,025 saves. save_memory now refuses any value carrying tool-call markup, names the field and the parameters it swallowed, and the model retries in the same turn. Markup quoted on purpose inside backticks is allowed. Every successful save echoes the length of each field it stored, which fields arrived empty, and which values came from a default. Damaged memories already in a store are never served back into context: the digest, the recall hook and read results show each field cut at the damage. memgit doctor counts them, and memgit doctor --repair-markup splits them back into their fields.
Core operating guide (v0.5.0)
A project's hardest onboarding problem isn't what it does — it's how to work in it: which skill to invoke, which command to run, which tool to reach for. That lives in a CLAUDE.md or a skills folder the AI host may or may not be configured to read. memgit carries it for you.
memgit core seed distills a compact operating guide from the project's existing skills + rule files. memgit core sync writes it into every AI host's own rules surface as a dedicated, memgit-owned file — .claude/rules/memgit.md, .cursor/rules/memgit.mdc, .windsurf/rules/memgit.md, .clinerules/, .roo/rules/, .continue/rules/ — and marker-delimited blocks in the shared GEMINI.md (Gemini CLI auto-loads only that file) and Codex's AGENTS.md. It's additive only — memgit never touches your own config or content — and injected at session start, so any tool knows how to work in the project even when its native setup is missing.
And it learns: a sidecar usage ledger tracks which memories actually get recalled, and the most-used ones are auto-promoted as pointers into the guide over time (budget-capped, decaying, and always subordinate to the repo's own rules — it never restates or overrides them). Drifted? memgit core heal rebuilds it.
Since 0.8.0 it also starts itself: a project's first guide is created automatically once it holds a handful of memories, so the loop no longer waits on someone remembering to run core seed. The guide leads with what the project actually holds — "this project has N saved memories covering topics" — because a stated count of real prior work is evidence a model can act on, where an abstract instruction to check memory is something it can weigh against its own confidence and skip.
memgit Pro — one memory across every machine
The local engine, the store, the MCP server and every command below are MIT and never gated. Pro is the hosted layer for people who work on more than one machine or with a team: end-to-end-encrypted sync where the server stores ciphertext only, unlocked by one licence key.
memgit pro activate <key>     # validate the key with Polar and store it (mode 0600)
memgit pro status             # Free / Pro, last verification, expiry
memgit pro deactivate         # remove the key from this machine
- Buy a key at memgit.dev/#pricing — $12/month or $99/year, billed by Polar (merchant of record, taxes handled). The key arrives by email and in your Polar purchases page.
- The only bytes that leave your machine are the key and memgit's public organisation id, sent to Polar's validation endpoint. No memory content is ever sent.
- Headless hosts: set
MEMGIT_LICENSE_KEY=<key>in the MCP server's environment; it is validated with the same cache and never written to disk. - Fail-open: a key that verified in the last 14 days keeps working offline; a rejected key drops to Free with a clear message. A lapsed plan never locks your data — reads, pulls and exports keep working.
- If this store is logged in to memgit cloud,
pro activatealso upgrades that account.
Sync between machines and with a team
memgit cloud signup           # creates your account, a personal team and repo, links this store and turns sync on
memgit cloud login            # on another machine: links to the same repo and turns sync on
memgit cloud team invite personal   # prints the one command a teammate runs:
                                    #   memgit cloud signup --invite '<link>'
A teammate who joins by invite is linked to the team's memory, not to a new personal repo of their own. The same repository cloned at a different path, on another machine or by a teammate shares its memories: inside a git repository a project is identified by its remote as well as by its folder (see "How the project label is decided" below).
With autosync on, each save (including every save_memory your AI makes) starts one
background pull-then-push and returns immediately, and each session start pulls what other
machines saved. memgit cloud auto status shows the last run and why it would not run.
On a machine that runs an agent but no interactive sessions (a Mac mini, a VM), log in and link once, then keep it current under systemd or launchd:
memgit cloud watch --interval 60                       # pull and push forever, one JSON line per run
memgit cloud watch --export ~/agent/.hermes.md         # also write the digest for agents that read context files
Everything leaves the machine end-to-end encrypted; the server stores ciphertext only.
Backups that actually happen
memgit's premise is that the AI is the operator — but backup used to require a human to remember memgit git init --remote <url> and keep pushing. On this project's own store that meant 1,734 memories on one disk with no copy anywhere, five weeks in. A maintenance task that needs a human command is a task that will not happen.
Since 0.9.0 it runs itself, at the end of a session, with the safety boundary drawn at network egress rather than effort:
- Local destinations are automatic — a cloud-synced folder you already have (iCloud, Dropbox, Google Drive, OneDrive) or an external volume. memgit copies files; it opens no connection and signs up for no service. Your existing sync client does the rest.
- A git remote is pushed to only if you already configured one. memgit never invents a remote, never creates a repository, and never sends memories to a host you did not choose — memories can contain credentials, and convenience is not a reason to publish them somewhere you never picked.
The backup is a single memgit-store.tar.gz, not a directory tree: a 203 MB store is 10,295 small object files, and giving a sync client 10k files to reconcile every time is how you get a sync client that never finishes. It is staged and renamed atomically, keeping the old copy until the new one lands — an interrupted backup must never leave a corrupt file where a good one used to be.
memgit backup status # where the last copy went, and what else is available
Ranking you can prove
Retrieval quality used to be adjusted on intuition. memgit eval replaces that with a measurement, using two frozen sets mined from the store itself:
- recall — real prompts and the memories memgit actually surfaced for them. Measures stability: did a change break what used to work?
- synthetic — each memory queried by its own
why, expecting itself back, with the slug's own words stripped out of the query. Measures correctness, independently of any past ranking. (The recall set alone is circular — its answers came from the ranking under test.)
Both report hit@1, recall@3/5/10 and MRR against a pinned baseline. There is deliberately no single blended score, and no fabricated "tokens saved" number.
It earns its keep immediately. Two changes built for 0.8.0 looked obviously right and were measured wrong: a recency multiplier (cut — real-prompt hit@1 −0.020, MRR −0.018) and destructive stemming, which fixed its motivating query while costing hit@1 −0.038 overall (rebuilt as an additive field, then +0.020/+0.041/+0.019). A BM25 normalisation bug introduced in the same release was caught the same way.
memgit MCP 질문
memgit MCP를 Claude Code에 추가하려면 어떻게 하나요?
터미널에서 claude mcp add memgit -- npx -y memgit-mcp를 실행합니다. 모든 프로젝트에서 사용할 수 있게 하려면 --scope user를 추가합니다.
memgit MCP를 Cursor에 추가하려면 어떻게 하나요?
~/.cursor/mcp.json를 열고 mcpServers 아래에 서버를 추가합니다. 위 설치 섹션에 표시된 Cursor 구성을 사용합니다.
memgit은 서로 다른 기기 간의 메모리를 어떻게 처리하나요?
memgit cloud를 통해 노트북, 데스크톱, 서버 간에 종단간 암호화된 상태로 메모리를 동기화합니다.
AI agent가 메모리에 실수한 내용을 되돌릴 수 있나요?
네, rollback 명령어를 사용하여 이전 상태로 복구하거나 diff를 사용하여 변경 사항을 확인할 수 있습니다.
Claude Code 이외의 도구와도 작동하나요?
네, Cursor, Codex, Windsurf, Gemini CLI 및 모든 MCP host와 호환됩니다.
기존 코드베이스를 사용하여 memgit에 데이터를 초기화하려면 어떻게 하나요?
onboard 명령어를 사용하여 저장소의 히스토리, 스택, 문서를 분석하고 초기 메모리 세트를 생성할 수 있습니다.
클라우드 서비스 결제를 중단해도 데이터가 안전한가요?
네, 로컬 엔진과 저장소는 항상 사용 가능하며, 플랜이 만료되어도 데이터가 잠기지 않습니다. 데이터는 사용자의 기기에서 계속 읽고 내보낼 수 있습니다.