
Convert des ebooks en chapitres Markdown propres pour permettre un RAG déterministe et la vérification de citations par des clients IA.
Aussi connu sous Terobyte/librarian-cli, librarian-cli
- Étoiles
- 2
- Outils
- —
- Téléchargements, 30 jours
- 169
- Dernière version
- 0.1.1
- Dernier commit
- 1 sept. 2026
- Licence
- MIT
Qu'est-ce que Librarian MCP ?
Librarian est un serveur MCP. Convert des ebooks en chapitres Markdown propres pour permettre un RAG déterministe et la vérification de citations par des clients IA.
Résumé généré à partir du README du projet
À propos du MCP server Librarian
Librarian permet aux développeurs utilisant des clients IA de convertir des ebooks en chapitres Markdown propres pour un RAG déterministe. Il transforme divers formats tels que EPUB, FB2, DOCX et les PDF avec couche de texte en une bibliothèque structurée de chapitres avec des comptes de tokens précis. Ce processus s'effectue entièrement en local, sans aucun accès réseau, sans embeddings ni clés API, garantissant que la même entrée produit toujours une sortie identique au niveau de l'octet.
Les utilisateurs peuvent connecter ce MCP server à Claude Desktop ou Claude Code via une connexion MCP stdio. Une fois configuré avec un chemin de bibliothèque, le serveur fournit six outils en lecture seule, notamment list_books, find et verify_quote. Ces outils permettent à une IA de parcourir un catalogue, d'effectuer des recherches plein texte via BM25 et de récupérer des chapitres spécifiques dans le respect d'un budget de tokens défini. Il est spécifiquement conçu pour aider les modèles d'IA à vérifier leurs propres citations par rapport au texte source original afin d'éviter les hallucinations.
Ce que vous pouvez faire avec
- 1Rechercher dans des bibliothèques d'ebooksEffectuez des recherches plein texte sur tous les titres et auteurs d'une collection locale.
- 2Récupérer du texte dans des limites de tokensExtrayez des chapitres consécutifs d'un livre tout en respectant un budget de tokens spécifique.
- 3Auditer la qualité des livresÉvaluez la structure et la qualité de l'encodage des fichiers d'ebooks ingérés.
Extrait du README du projet. Chaque cas d'utilisation est vérifié par rapport à une citation du document.
Comment installer Librarian MCP
Formats vérifiés le 10 nov. 2026Ajouter à CursorAjouter à GooseInstaller Librarian MCP dans Claude Code
$ claude mcp add librarian-cli -- uvx librarian-cliInstaller Librarian MCP dans Cursor
~/.cursor/mcp.json
{
  "mcpServers": {
    "librarian-cli": {
      "command": "uvx",
      "args": [
        "librarian-cli"
      ]
    }
  }
}Installer Librarian MCP dans VS Code
.vscode/mcp.json
{
  "servers": {
    "librarian-cli": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "librarian-cli"
      ]
    }
  }
}Installer Librarian MCP dans VS Code CLI
$ code --add-mcp '{"name":"librarian-cli","type":"stdio","command":"uvx","args":["librarian-cli"]}'Installer Librarian MCP dans Claude Desktop
claude_desktop_config.json
{
  "mcpServers": {
    "librarian-cli": {
      "command": "uvx",
      "args": [
        "librarian-cli"
      ]
    }
  }
}Installer Librarian MCP dans Codex
$ codex mcp add librarian-cli -- uvx librarian-cliInstaller Librarian MCP dans Codex config.toml
~/.codex/config.toml
[mcp_servers.librarian-cli]
command = "uvx"
args = ["librarian-cli"]
Installer Librarian MCP dans Gemini CLI
$ gemini mcp add -s user librarian-cli uvx -- librarian-cliInstaller Librarian MCP dans Gemini settings.json
~/.gemini/settings.json
{
  "mcpServers": {
    "librarian-cli": {
      "command": "uvx",
      "args": [
        "librarian-cli"
      ]
    }
  }
}Configuration
LIB_HOMELibrary root directory (default ./library)
| Nom | Description | Type |
|---|---|---|
| LIB_HOME | Library root directory (default ./library) |
Vérifications automatisées
Exécuté le 14 nov. 2026Rapport complet →A passé nos vérifications automatisées. Il ne s'agit pas d'un audit de sécurité : lisez le code et donnez au serveur l'accès le plus restreint dont il a besoin. Fonctionnement des vérifications

- Dépôt source lié et accessibleterobyte/librarian-cli is public and reachablegithub.com/terobyte/librarian-cli ↗Réussi
- Le nom du package correspond au dépôt sourcelibrarian-cli names terobyte/librarian-cli as sourcepypi.org/project/librarian-cli/ ↗Réussi
- Provenance du build (attestation Sigstore)Sigstore attestation for librarian-clipypi.org/project/librarian-cli/ ↗Réussi
- Licence open source (OSI)MITspdx.org/licenses/MIT.html ↗Réussi
- Commit ou version publiée au cours de l'année écouléeLast commit or release 2026-09-01github.com/terobyte/librarian-cli ↗Réussi
- OpenSSF ScorecardNon vérifié
- Nom du package non proche d'un package populaireNo popular package one edit away from librarian-cliRéussi
- Aucun avis critique dans le package ou ses dépendances70 resolved dependencies checked; no critical advisoryosv.dev ↗Réussi
- Aucune instruction cachée destinée au modèle0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersRéussi
- Les outils destructifs sont étiquetésNon vérifié
- Le point de terminaison distant répond à la poignée de main MCPNon vérifié
README
Voir sur GitHub📚 librarian




Turn any ebook into clean, token-counted Markdown chapters — let Claude read your bookshelf over MCP and catch it misquoting your books. Deterministic RAG: no embeddings, no network, no API keys.
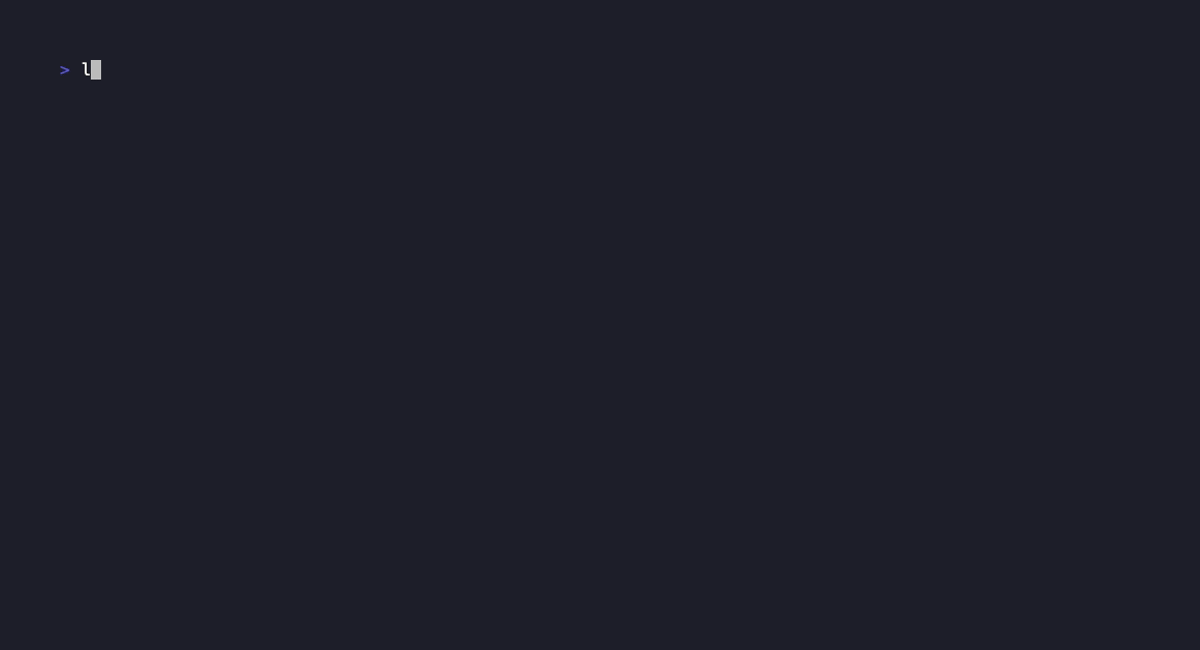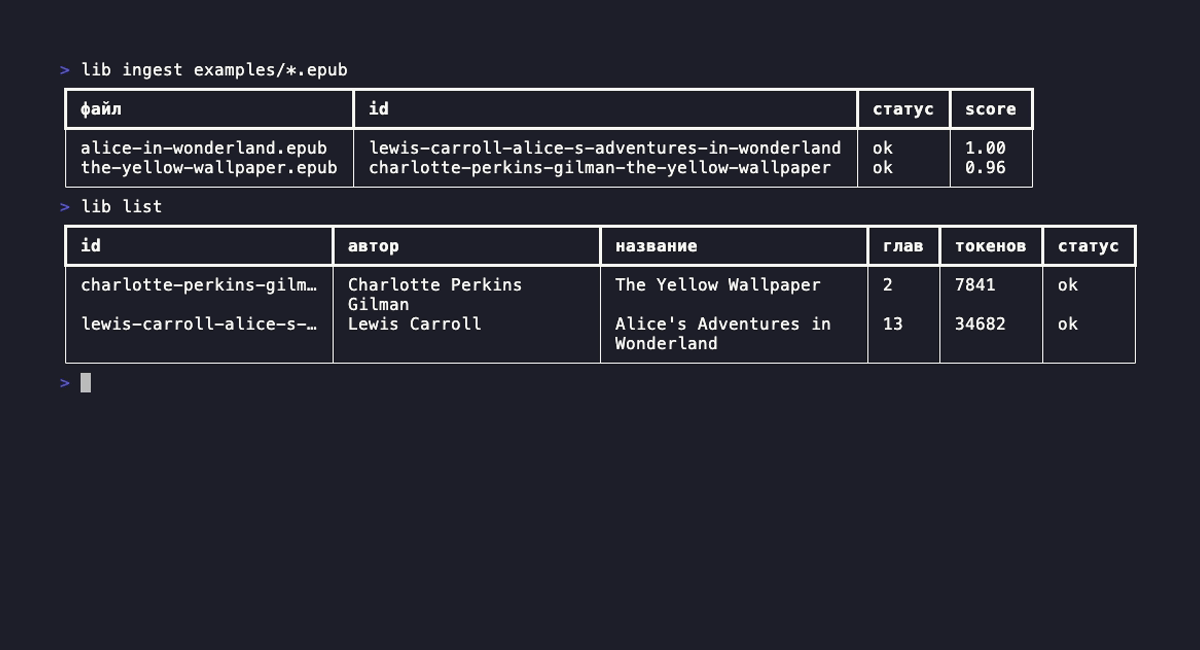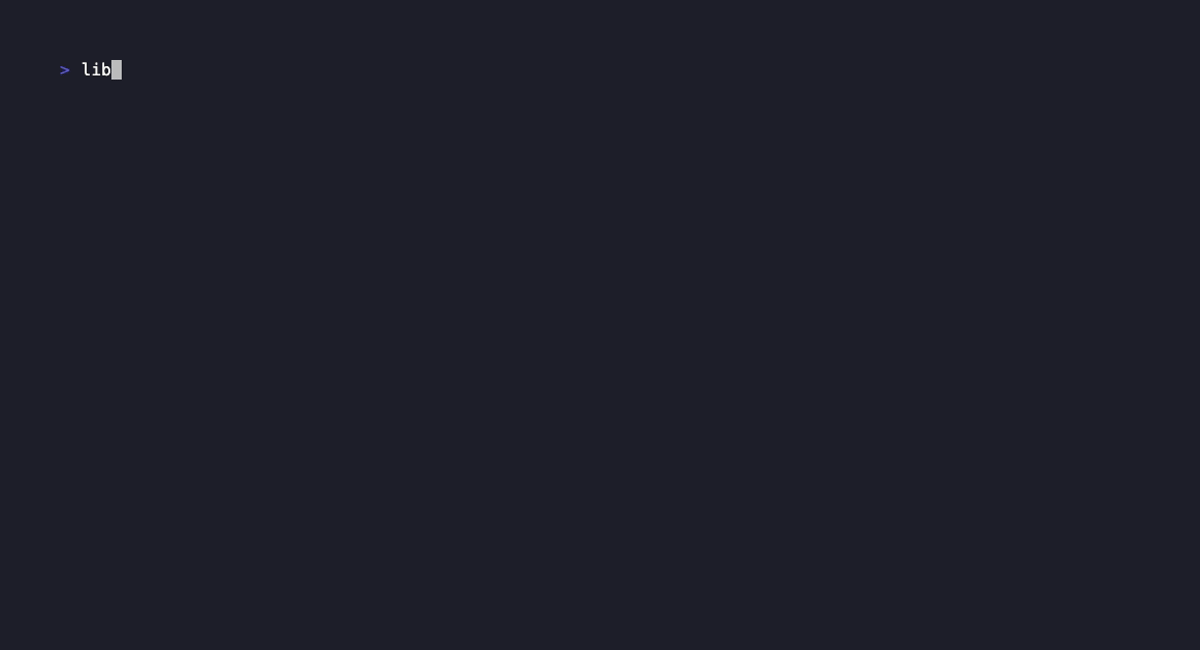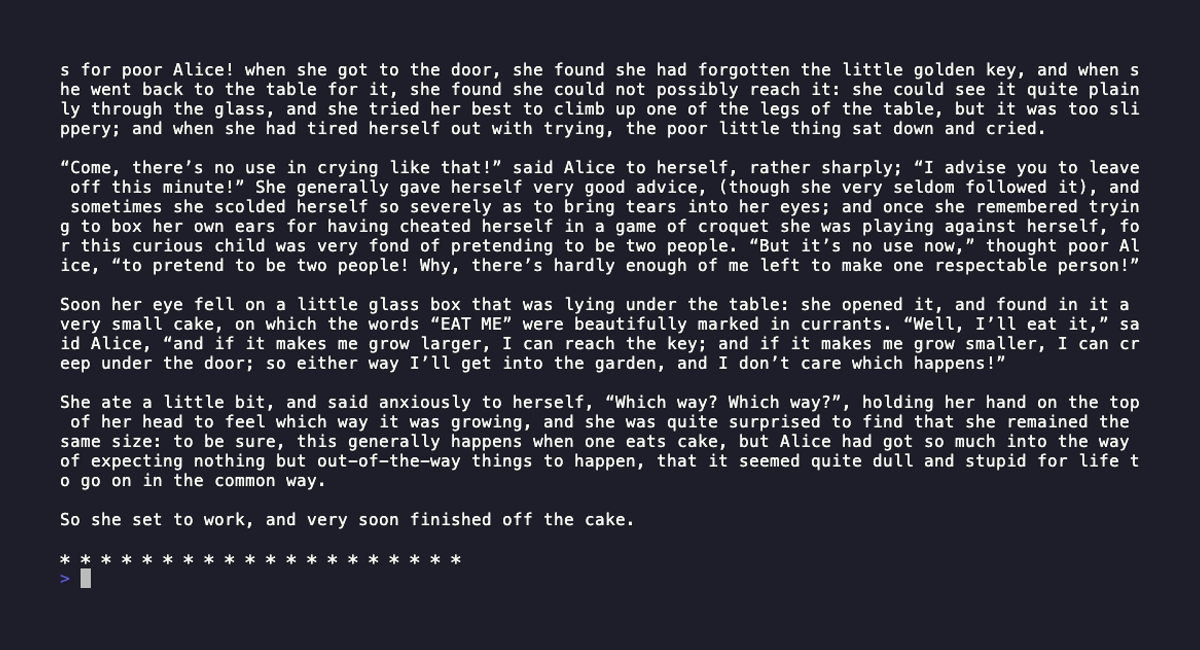
Any input format — FB2, EPUB, DOCX, HTML, TXT/MD, text-layer PDF — becomes a directory of clean chapters with token counts. No network, no LLM, no randomness: the same input always produces byte-identical output.
Install
uv tool install librarian-cli
# or: pipx install librarian-cli
Offline contract: install and runtime need no network (the tokenizer's vocabulary is vendored in the package).
Quick start
lib ingest examples/*.epub
lib list
lib find curiouser
lib get <book-id> --budget 3000
Commands
| Command | Purpose |
|---|---|
lib ingest <files…> [--force] [--no-keep-source] [--config cfg.toml] [--verbose] |
Process books into the library; prints a file · id · status · score table. |
lib list [<book-id>] |
No argument — all books; with an id — that book's chapters (n, title, tokens, summary). |
lib get <book-id> <spec> |
Print chapters by range (1-3,7) to stdout. |
lib get <book-id> --budget N [--from K] |
Greedily print consecutive chapters from K while the token sum stays ≤ N. |
lib find <query> [--limit 10] [--book <id>] [--reindex] [--json] |
Full-text search across chapters and titles/authors library-wide (bm25, snippets, RU/EN stemming). |
lib info <book-id> |
JSON: book metadata + quality metrics. |
lib doctor [<book-id>] |
No id — books in review and broken directories; with id — that book's report. |
lib reingest --all [--config cfg.toml] [--verbose] |
Rebuild the library from source/ with the current code/config. |
lib rm <book-id> |
Delete a book and rebuild the index. |
lib serve [--library <path>] |
Stdio MCP server over the library. |
lib verify "quote" [--book ID] [--json] [--limit N] |
Check a quote against one book or attribute it across the library. |
Library root: --library <path> (or the LIB_HOME env var, default ./library). Data goes
to stdout, diagnostics to stderr. Exit codes: 0 success, 1 runtime error, 2 usage error.
Give Claude your bookshelf
librarian-cli ships a built-in stdio MCP server with 6 read-only tools — list_books,
list_chapters, find, get_chapters, book_info, verify_quote — so Claude can browse
the catalog, search it, pull chapters under a token budget, and check its own quotes against
the source on its own: deterministic RAG with no embeddings, no network, and no API keys.
Claude Code:
claude mcp add librarian --env LIB_HOME=$HOME/books -- uvx librarian-cli
Claude Desktop (claude_desktop_config.json):
{
  "mcpServers": {
    "librarian": {
      "command": "uvx",
      "args": ["librarian-cli"],
      "env": { "LIB_HOME": "/path/to/books" }
    }
  }
}
Verify quotes
An MCP server that catches Claude misquoting your books.
lib verify "quote" checks whether a quote actually appears in your library, verbatim —
punctuation, case, ё/е, and markdown formatting don't count. Two modes:
- Book mode (
--book <id>): full scan of one book — "does this book actually say this?" Works without the search index. - Shelf mode (no
--book): attribution across the whole library via FTS5 candidates — "which book is this from?" The quote needs at least 5 significant words (stop words don't count), or the check is skipped withverdict: null.
lib verify "Рукописи не горят" --book bulgakov-master-i-margarita
lib verify "рукописи не горят никогда"
| verdict | meaning |
|---|---|
exact |
matches after normalization (punctuation/case/ё/typography don't count) |
close |
similarity ≥ 0.95 — near-exact, differences shown as a word-diff |
distorted |
similarity ≥ 0.75 — the right place, but the quote is misremembered |
not_found |
similarity < 0.75 — nothing like it in the book/library |
null |
check wasn't run: empty quote, or a short quote without --book |
Exit codes (grep-style semantics, a deliberate departure from the project's usual
"1 = runtime error" — see docs/MILESTONES.md deviation 38):
| exit | case | stdout |
|---|---|---|
| 0 | exact / close — quote confirmed |
full report / JSON |
| 1 | distorted / not_found — not confirmed |
full report / JSON |
| 1 | runtime error (unknown book id, no search index, locked index) | empty |
| 2 | usage error: empty/short quote (verdict: null), --limit < 1 |
empty (message on stderr) |
Script discriminator: exit 1 with non-empty stdout means "checked, not confirmed"; exit
1 with empty stdout means an error (diagnostics went to stderr instead). Exit 0
includes close — a strict CI gate must check verdict == "exact" in the --json
output, not the exit code alone.
Quality
Every book gets a score from five metrics (coverage, structure, garbage, encoding,
dehyphenation): ok (score ≥ 0.90, no hard triggers) — saved silently; review
(0.60 ≤ score < 0.90, or triggers present) — saved with a warning, details via
lib doctor <id>; failed (score < 0.60) — not saved. Scans and password-protected PDFs
honestly fail (OCR and DRM removal are out of scope).
Determinism
The pipeline has no network access, no LLM calls, and no randomness — the same input file
always produces byte-identical output. That makes ingestion reproducible and cacheable, and
it's what makes lib serve's RAG deterministic: no embeddings to drift, no model calls to
vary between runs.
Limitations
- PDF: works well on typographically normal books; complex layouts may land in
review. - DRM is not circumvented; source legality is the user's responsibility.
- Networked filesystems (NFS/SMB) are not supported (the advisory lock isn't reliable there).
- MOBI/DJVU and text-less scans are not supported (v3 candidates: OCR, calibre).
- CLI messages are currently in Russian; English output is planned.
lib verify: quotes spanning a chapter boundary are not supported (v1) — the best you'll get isdistortedon one half.lib verify:closeon a single-word replacement is realistic from ~150 characters of quote; shorter quotes with a replaced word honestly land indistorted— a third of a three-word quote really is a distortion.lib verifyshelf mode (no--book) needs the FTS5 search index; book mode (--book <id>) works without it in the CLI.lib serveas a whole still requires FTS5 — it syncs the index at startup regardless of which tool gets called.lib verifyin book mode scans the whole chapter text in pure Python; a long book can take a few seconds of CPU. The MCP tool runs it in a worker thread so it doesn't block the rest of the server.
Русская версия
See README.ru.md for the Russian documentation.
Questions sur Librarian MCP
Comment ajouter Librarian MCP à Claude Code ?
Exécutez claude mcp add librarian-cli -- uvx librarian-cli dans votre terminal. Ajoutez --scope user pour le rendre disponible dans tous les projets.
Comment ajouter Librarian MCP à Cursor ?
Ouvrez ~/.cursor/mcp.json et ajoutez le serveur sous mcpServers, avec la configuration Cursor indiquée dans la section d'installation ci-dessus.
Librarian nécessite-t-il une connexion Internet ou des clés API ?
Non, il fonctionne entièrement hors ligne sans accès réseau, sans appels LLM et sans aucune clé API requise.
Quels formats d'ebooks sont pris en charge ?
L'outil prend en charge les formats FB2, EPUB, DOCX, HTML, TXT/MD et les PDF avec couche de texte.
Comment fonctionne la vérification des citations ?
Il vérifie si une citation apparaît textuellement dans votre bibliothèque, en fournissant des verdicts tels que exact, proche, déformé ou non trouvé.
Le résultat est-il cohérent ?
Oui, le pipeline est déterministe, ce qui signifie que la même entrée produit toujours une sortie identique au niveau de l'octet.