
Serveur MCP AccessFlow
Commit 11 nov. 2026Une plateforme de proxy de requête et de gouvernance qui propose des flux de travail de révision, d'approbation et d'audit pour les accès SQL, NoSQL et API.
Aussi connu sous bablsoft/accessflow
- Étoiles
- 13
- Outils
- —
- Téléchargements, 30 jours
- —
- Dernière version
- —
- Dernier commit
- 11 nov. 2026
- Licence
- Apache-2.0
Qu'est-ce que AccessFlow MCP ?
AccessFlow est un serveur MCP. Une plateforme de proxy de requête et de gouvernance qui propose des flux de travail de révision, d'approbation et d'audit pour les accès SQL, NoSQL et API.
Résumé généré à partir du README du projet
À propos du MCP server AccessFlow
Les ingénieurs et les administrateurs de bases de données utilisent AccessFlow pour mettre en œuvre un accès en libre-service et gouverné aux données et services de production. Il agit comme un proxy de requête complet situé entre les utilisateurs et divers moteurs de données, notamment les bases de données relationnelles comme PostgreSQL et MySQL, les systèmes NoSQL tels que MongoDB et Redis, ainsi que les entrepôts de données cloud comme Snowflake ou BigQuery. La plateforme étend également la gouvernance aux appels API sortants REST, SOAP, GraphQL et gRPC.
Au lieu de partager des identifiants de production, les utilisateurs soumettent des requêtes via le proxy, qui conserve les identifiants chiffrés via AES-256-GCM. Chaque requête est analysée, classifiée et optionnellement examinée par une IA pour un scoring de risque avant d'être acheminée via des flux de travail d'approbation humaine configurables. Cette configuration permet des approbations séquentielles multi-étapes, un routage automatisé basé sur la structure de la requête ou le niveau de risque, et un journal d'audit infalsifiable pour chaque décision. Le système est conçu pour s'exécuter entièrement au sein de votre propre infrastructure et prend en charge l'authentification via JWT, SAML 2.0 et OAuth 2.0/OIDC.
Ce que vous pouvez faire avec
- 1Prévenir la suppression accidentelle de donnéesUn ingénieur peut soumettre une commande SQL destructive qui sera automatiquement signalée pour révision humaine au lieu d'être exécutée immédiatement.
- 2Sécuriser les communications API sortantesLes équipes peuvent appliquer un scoring de risque par IA et une approbation multi-étapes aux appels REST ou GraphQL sortants pour garantir la sécurité des services.
- 3Tester de nouvelles politiques de sécuritéUn développeur peut tester une ébauche de politique de routage ou de masquage sur le trafic historique pour voir comment elle aurait affecté les requêtes passées.
- 4Automatiser les revues d'accès aux bases de donnéesLes administrateurs peuvent configurer des règles pour approuver automatiquement les requêtes en lecture seule tout en exigeant une validation manuelle pour toute opération d'écriture.
Extrait du README du projet. Chaque cas d'utilisation est vérifié par rapport à une citation du document.
Vérifications automatisées
Exécuté le 14 nov. 2026Rapport complet →Pas encore vérifié. Un serveur nécessite un score de 80, aucune faille sérieuse et suffisamment de données pour que nous puissions effectuer les vérifications. Fonctionnement des vérifications · Ce qu'il faut corriger pour gagner des points

- Dépôt source lié et accessiblebablsoft/accessflow is public and reachablegithub.com/bablsoft/accessflow ↗Réussi
- Le nom du package correspond au dépôt sourceNon vérifié
- Provenance du build (attestation Sigstore)Non vérifié
- Licence open source (OSI)Apache-2.0spdx.org/licenses/Apache-2.0.html ↗Réussi
- Commit ou version publiée au cours de l'année écouléeLast commit or release 2026-11-11github.com/bablsoft/accessflow ↗Réussi
- OpenSSF ScorecardNon vérifié
- Nom du package non proche d'un package populaireNon vérifié
- Aucun avis critique dans le package ou ses dépendancesNon vérifié
- Aucune instruction cachée destinée au modèle0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersRéussi
- Les outils destructifs sont étiquetésNon vérifié
- Le point de terminaison distant répond à la poignée de main MCPNon vérifié
README
Voir sur GitHubAccessFlow sits as a full query proxy in front of your databases — the relational engines PostgreSQL, MySQL, MariaDB, Oracle, and Microsoft SQL Server are supported out of the box via a declarative connector catalog (additional engines such as ClickHouse install with one click), any other JDBC-compatible engine can be added by uploading its driver JAR, the NoSQL document engines MongoDB and Couchbase (SQL++), the NoSQL key-value engine Redis, the NoSQL wide-column engines Apache Cassandra (CQL) and ScyllaDB (CQL-compatible), the NoSQL search engines Elasticsearch and OpenSearch, the NoSQL key-value engine Amazon DynamoDB (PartiQL), the NoSQL graph engine Neo4j (Cypher over Bolt), and the cloud data warehouses Snowflake, Google BigQuery (GoogleSQL), and Databricks SQL install the same way through on-demand native engine plugins. The catalog separates the SQL (relational) family, the cloud data-warehouse family, and the NoSQL umbrella of native engine-managed connectors. Every query a user submits — SQL, a MongoDB shell / JSON command, a Couchbase SQL++ statement, a Redis command, a Cassandra/ScyllaDB CQL statement, an Elasticsearch/OpenSearch query, a DynamoDB PartiQL statement, a Neo4j Cypher statement, or a Snowflake / BigQuery / Databricks warehouse SQL statement — is parsed, classified, optionally analyzed by AI, and routed through a configurable human-approval workflow before it ever reaches live data. The same governance extends beyond databases: outbound REST, SOAP, GraphQL, and gRPC calls against registered API connectors run through that identical pipeline — AI risk scoring, attribute-based routing, multi-stage approval — with response masking and immutable, downloadable response snapshots. Every request, decision, and execution is captured in a tamper-evident metadata audit log. Authentication is JWT (RS256) with optional SAML 2.0 SSO and OAuth 2.0 / OIDC sign-in (built-in templates for Google, GitHub, GitHub Enterprise Server, Microsoft, GitLab, and self-managed GitLab), and SCIM 2.0 provisioning lets the identity provider drive user & group lifecycle end to end. AccessFlow ships as a single open-source product under Apache 2.0 and is designed to run entirely inside your own infrastructure.
Why AccessFlow
Most teams pick one of two extremes for database access:
- Shared production credentials — anyone with the password can run
DELETE. Fast, but a single mistake is unbounded and there is no record of who did what. - Ticket-driven DBA access — every change goes through a manual DBA queue. Safe, but slow enough that engineers route around it.
AccessFlow provides the missing middle: governed, self-service access where every query is reviewable, every approval is traceable, and AI catches the obvious problems before a human ever sees the request.
See it in action
A glance at the day-to-day flows engineers and approvers actually use.
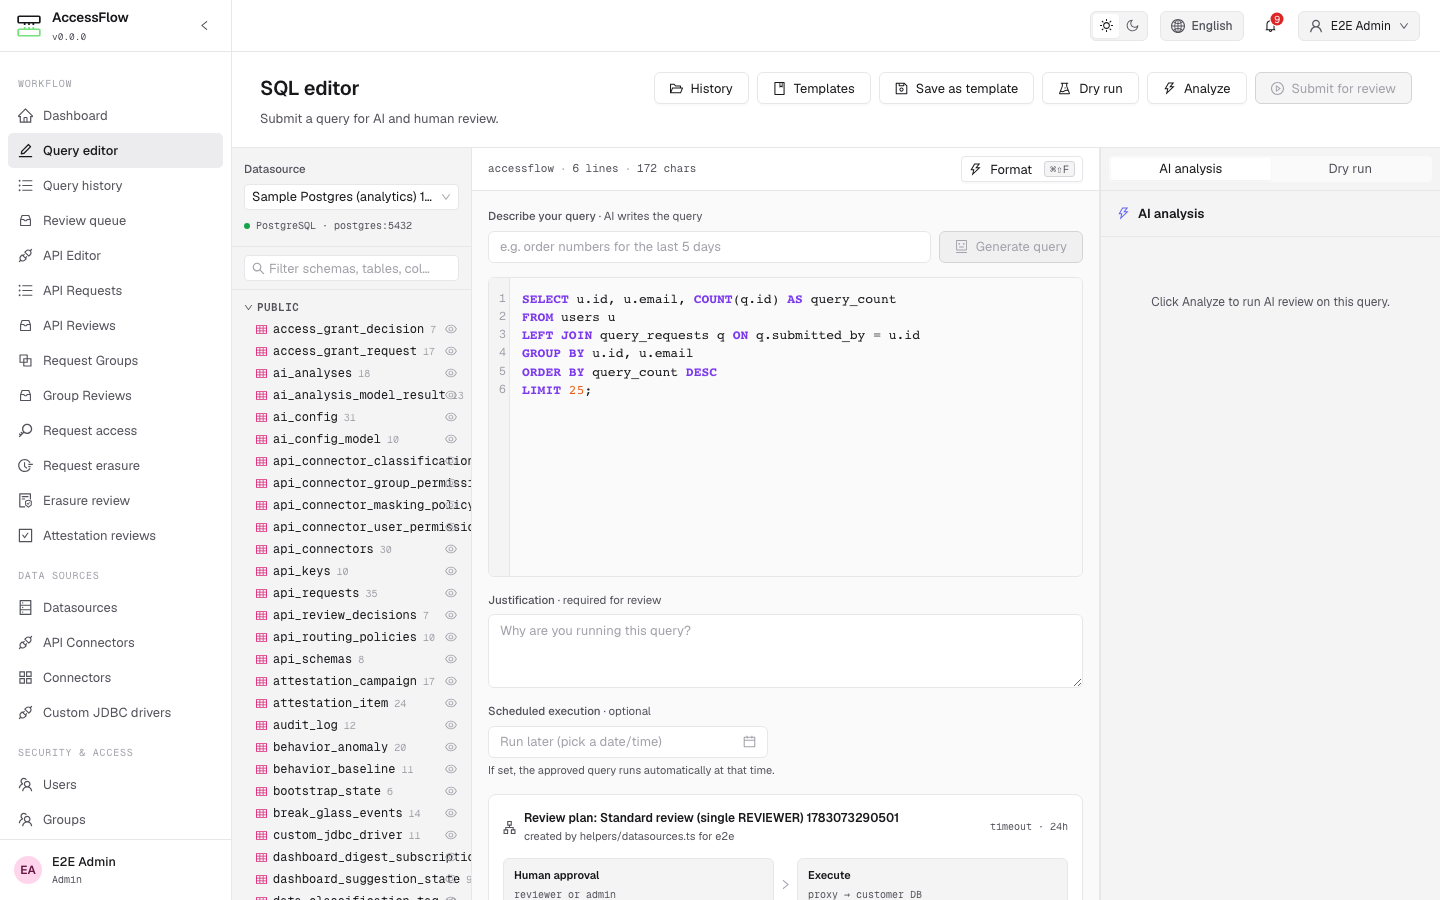
Submit a query — CodeMirror 6 with dialect-aware highlighting, live schema autocomplete, and an inline review-plan preview that shows exactly which approvals the submission will trigger.
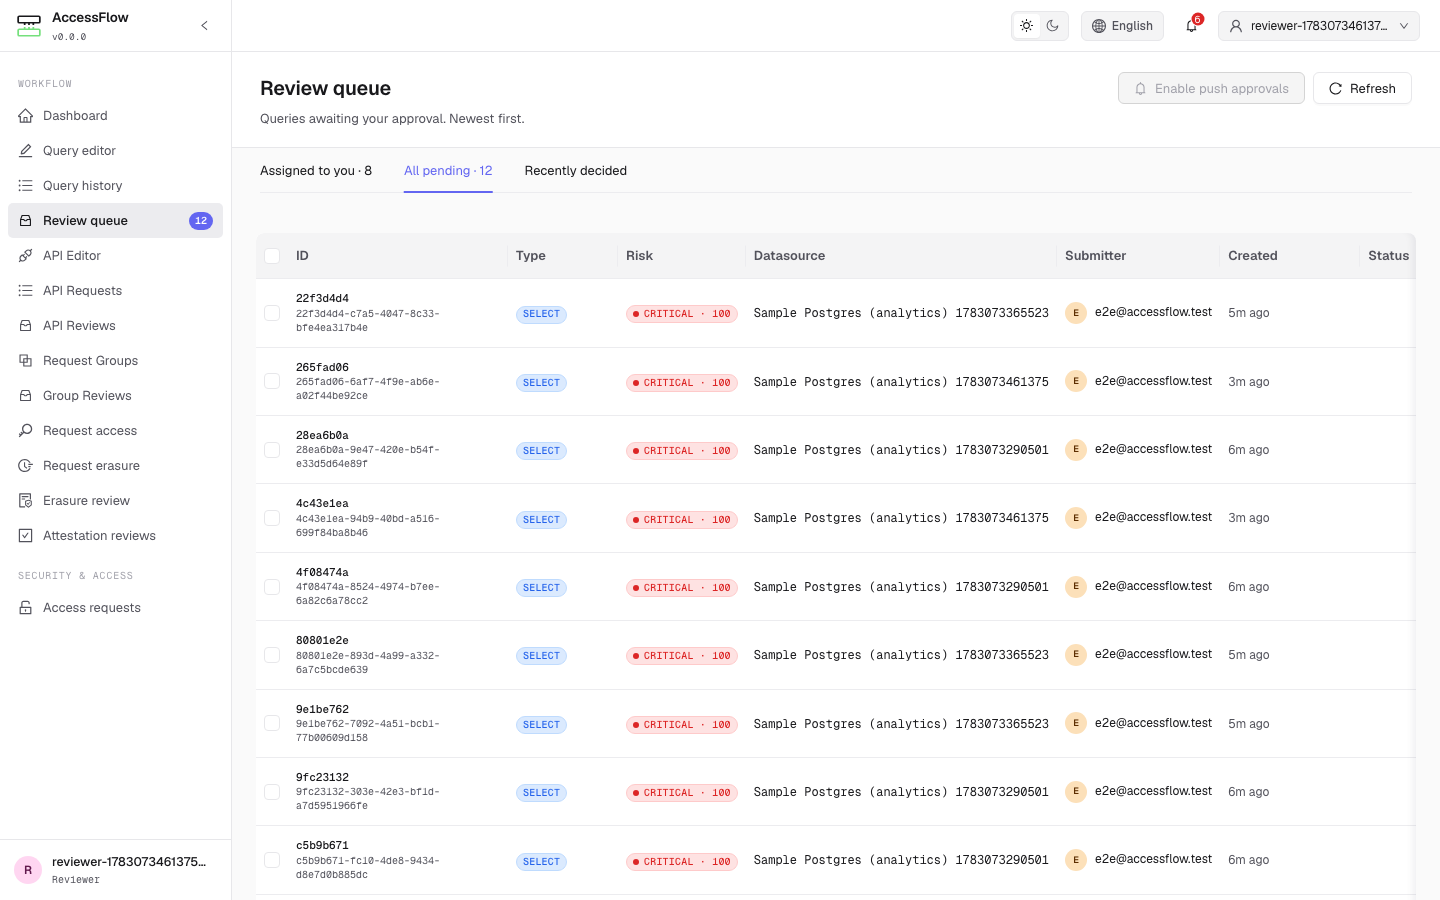
Approve or reject pending writes from one place — the queue is scoped to queries assigned to you, with risk score, query type, and submitter at a glance. A user can never approve their own query.
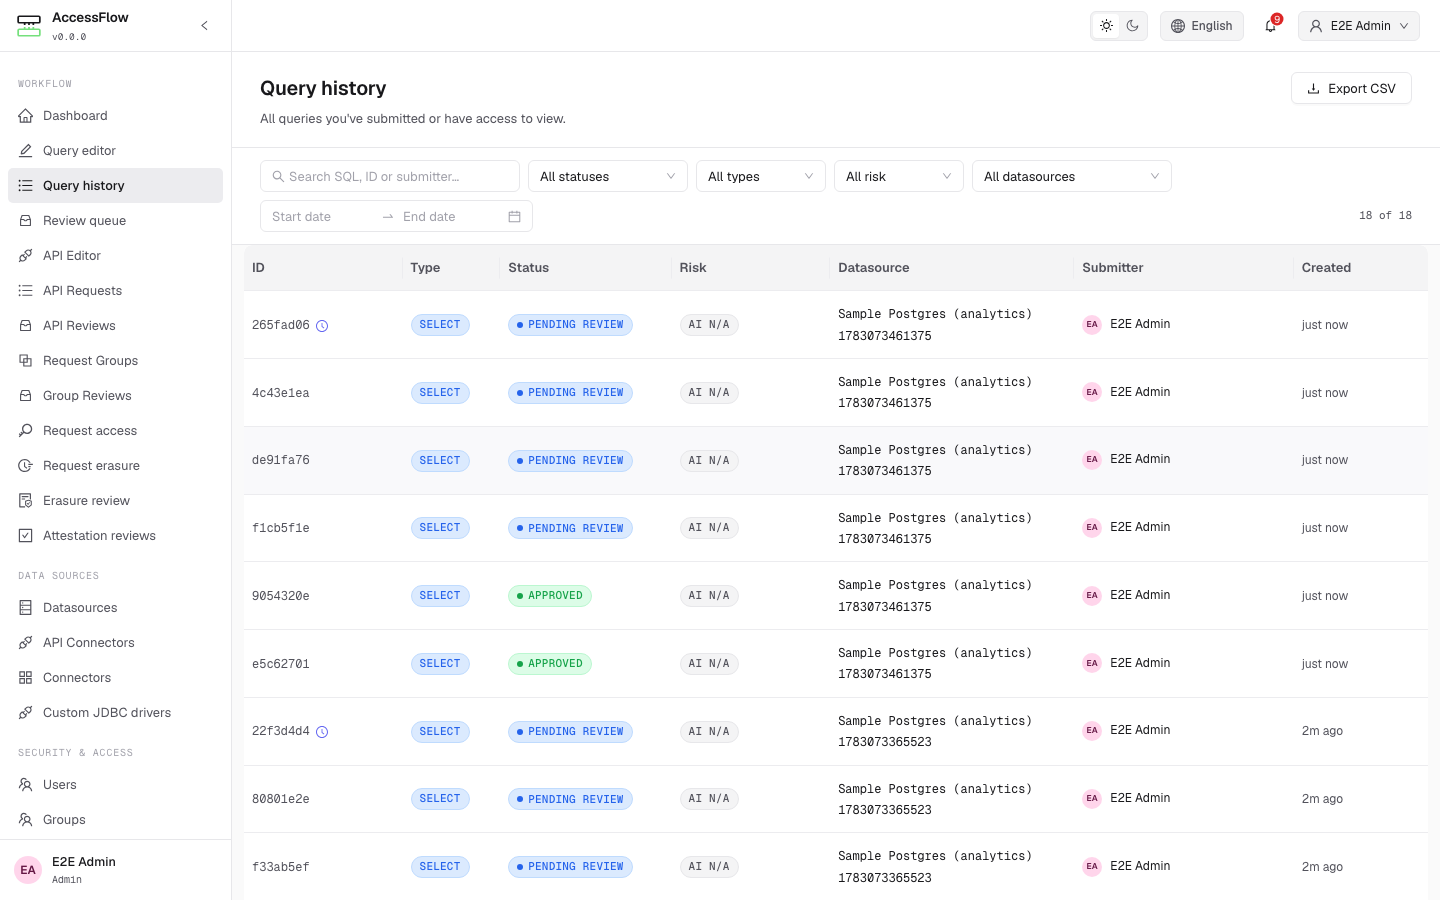
Searchable, filterable history of every query — by status, type, risk, datasource, submitter, or date range — with CSV export. Each row links to the full request, AI analysis, approval timeline, and result set.
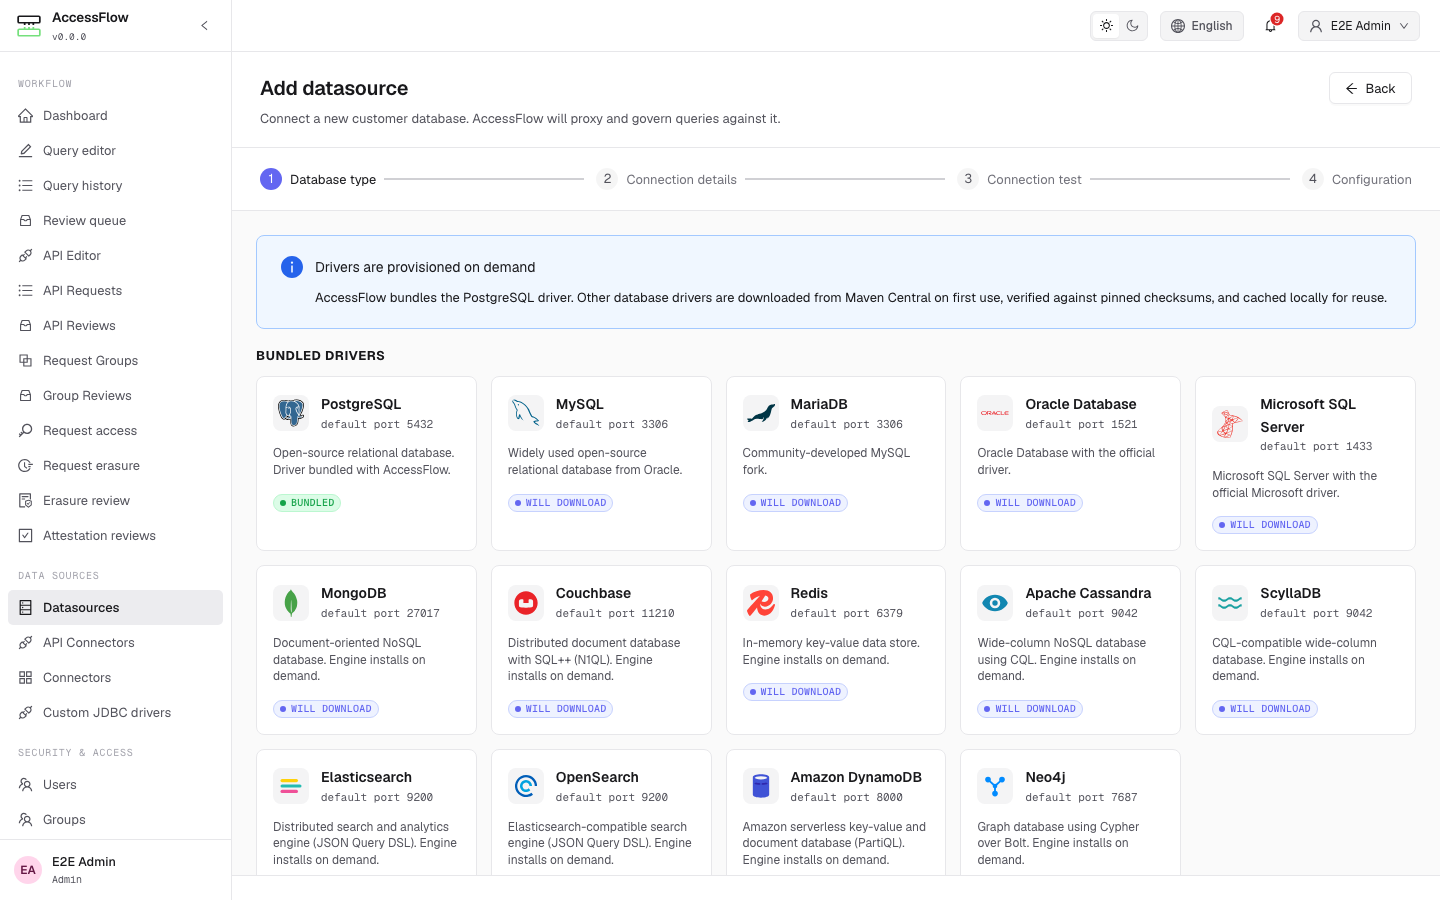
Connect a database in the admin UI — credentials are AES-256-GCM encrypted at rest, the proxy holds them, and end users never see them.
More walkthroughs — the Guides section carries step-by-step manuals for the setup tasks: your first governed query, adding a datasource, notifications and SMTP, users and roles, single sign-on, AI risk analysis, outbound API calls, gating a CI/CD pipeline, Terraform and the in-app help assistant — which, once enabled, answers all of the above from inside the app. Review plans, AI provider configuration, notification channels (Email, Slack, Discord, Telegram, Teams, PagerDuty, ServiceNow, Jira, webhooks), OAuth 2.0 / OIDC sign-in, SAML 2.0 SSO, users & invitations, and system SMTP each have their own reference chapter with screenshots on the public documentation site.
Features
- Proxy-first execution — no user ever holds production credentials; the proxy holds them encrypted and opens connections only after approval. Single SQL statements run with autocommit; multi-statement INSERT/UPDATE/DELETE batches wrapped in
BEGIN; … COMMIT;execute atomically inside one JDBC transaction (mixed SELECT/DML batches are rejected at parse time), with homogeneous INSERT runs collapsed into JDBCexecuteBatch()for bulk-load throughput. Optional multi-replica read load balancing: attach any number of replica endpoints to a datasource and SELECT traffic round-robins across the healthy ones — per-node health checks with circuit-breaker failover skip downed replicas, and only full replica-set exhaustion falls back to the primary (with an audit row). Optional SELECT result caching: opt a datasource into a Redis-backed result cache (per-datasource TTL) keyed over the security-rewritten query — masking and row-level security still apply — and invalidated on any proxied write to a referenced table. - Configurable review workflows — per-datasource review plans, multi-stage sequential approval chains, optional auto-approve for reads, approval timeouts with auto-reject. Reviewers can be scoped per-datasource (directly or via groups) so different teams see only the queues that belong to them. Reviewers going away can set an out-of-office delegation naming a colleague to cover their review duty for a window — across queries, governed API calls, and grouped requests — with every decision recording both identities. A delegate can never act on the delegator's own requests, delegation never grants a permission they lack, and it does not chain. Plans can also escalate a request that nobody has decided on to the reviewers at its current stage plus your admins before the approval timeout auto-rejects it, and nudge those same reviewers on a cadence — both optional, both notify-only, so waiting never changes who may approve.
- Policy-as-code routing — ordered, attribute-based routing policies decide a query's path after AI analysis and before reviewers see it: auto-approve, auto-reject, require N approvals, or escalate. Conditions match on query type, referenced tables (glob), AI risk level / score, requester role or group, time-of-day / day-of-week, WHERE / LIMIT presence, query shape (joins, set operations, subqueries, CTEs, GROUP BY / HAVING, aggregates, window functions), the transactional flag, the pre-flight estimate (estimated rows, estimated bytes scanned, scan type), the submitter's data-budget usage, and the submission client context — source IP / CIDR, user-agent, time-since-last-approval, and CI/CD origin (API key or
X-AccessFlow-CIheader) — combined with AND / OR / NOT. Client-context conditions fail closed (missing context never auto-approves), so an off-network or stale-approval query escalates to stricter review instead. First match by priority wins; on no match the query falls through to the datasource's review plan. Every automated decision is recorded in the audit log. - External policy decision hook (#945) — for rules that do not decompose into routing conditions, point AccessFlow at your own policy service (an OPA sidecar, an in-house API). It is consulted over HMAC-signed HTTPS for every query no routing policy matched, just before the grant fast path, and may allow, escalate, require approvals (never below the plan minimum) or reject — it can never approve. Every failure — timeout, error status, redirect, bad or missing response signature, unknown answer — sends the query to human review, and a per-hook circuit breaker stops a dead endpoint from stalling submissions. The SQL text is sent only on opt-in; the endpoint URL is SSRF-guarded (private and metadata addresses refused unless the deployment allows them). Managed at
/admin/decision-hooksor with the Terraformaccessflow_decision_hookresource. - Policy simulator — dry-run a draft routing, row-security, or masking policy against your own historical query traffic before you save it. AccessFlow replays the window twice — once against your current policies, once with the draft applied — and reports the difference between those two runs: how many past queries would change, which users would be affected, and which queries a row predicate would newly filter, deny, or reject outright. It is strictly read-only — no connection to your database, nothing executed, nothing persisted — and it names its own approximations (memberships are read as they are now; an engine that cannot classify a query shape offline is reported as unclassifiable, never as safe) instead of implying a precision the data does not have.
- Deterministic SQL review rules (#860) — a named rule catalog that judges every SQL query alongside the AI verdict and routing policies, and shows its findings in the editor as you type. Eighteen built-in rules derived from the parsed statement alone (missing
WHEREonUPDATE/DELETE, an always-trueWHERE,SELECT *, unbounded reads, cross joins, leading-wildcardLIKE,DROP/TRUNCATE/ DDL, banned functions, protected tables by glob, DML outside a transaction, and risky migrations — aNOT NULLcolumn added without a default, a PostgreSQLCREATE INDEXwithoutCONCURRENTLY, an in-place column type change,SET NOT NULLon an existing column), each at an admin-setOFF/WARN/BLOCKseverity configured per environment (DEVELOPMENT/TEST/STAGING/PRODUCTION, plus an organisation default).BLOCKescalates, it never rejects: a blocking finding suppresses every auto-approve path and sends the query to a human reviewer; a routing auto-reject still rejects. Evaluated synchronously at submission so findings exist even when AI analysis is off or fails, rendered in each reader's language on the query detail, review queue, break-glass retro-review and request-group detail; break-glass runs record findings but are never gated by them, and non-relational engines report not applicable. Admins can add custom rules of their own without code (v2.8, epic #1008) — composed from criteria over the parsed statement (statement type, tables and columns by pattern, functions called, missing clauses) or a bounded regular expression, tested against sample SQL before they are switched on, and configured per environment exactly like the built-ins; also manageable from Terraform. Seedocs/19-sql-review.md. - Just-in-time (JIT) access requests — users self-request temporary, scoped access to a datasource (read/write/DDL, optional schema/table scope) or an API connection (read/write, optional operation allow-list) for an ISO-8601 duration. Requests flow through the same approval engine, a time-boxed permission is granted on approval, and a clustered scheduler auto-revokes it on expiry (admins can also revoke early). A grant can opt into query pre-approval: while it is active, queries it covers skip human review and are auto-approved with the grant recorded as the approval provenance — routing policies, high-risk AI verdicts, and behavioural anomalies still override.
- Break-glass / emergency access — a gated emergency path for when production is on fire and approvers are asleep. A per-user/per-datasource
can_break_glasspermission (required for everyone, including admins; time-boxed) lets a query execute immediately, bypassing review — still through every proxy guard (allow-list, masking, row-level security, row caps). Compensating controls: a mandatory justification, instant fanout to all org admins (incl. PagerDuty), a prominently-tagged audit row, and a mandatory retro-review an admin (never the submitter) must acknowledge on the/admin/break-glasslog. - Dynamic data masking — per-column masking policies (full, partial last-N, keep first-N, stable hash, email-preserving, format-preserving, constant, nullify, regex replace, numeric bucketing, date generalization — configured by parameters and validated on save, never user code; every strategy fails closed to a full mask on a value it cannot handle) with role / group / user reveal conditions evaluated per requester. Masking is applied at result-read time before results are serialized or stored, so unmasked values never persist; applied policy ids are recorded in the audit log. Extends the static
restricted_columnsmasking; for a column that must never be read at all, a grant'sdenied_columnsrejects any query that references it — including throughSELECT *— before it runs (relational engines). - Row-level security — per-table row predicates the proxy injects into the parsed SQL so a scoped user only sees (SELECT) or affects (UPDATE/DELETE) the rows they are authorised for. Admins author a structured
column operator valuepredicate where the value is a fixed literal or a:user.*variable (built-in id / email / role / groups, or an admin-set per-user attribute). Values are bound as JDBC parameters — never concatenated; predicates that can't be safely applied are rejected, never run unfiltered. Composes with column masking and the schema/table allow-list — and with table/schema deny-lists that always beat it ("all ofcrmexceptcrm.salary", tables created later included) — and with query-shape deny-lists on a grant, which refuse joins, unions, subqueries, CTEs, grouping, aggregates or window functions anywhere in a statement before it runs (relational engines, fail-closed). - Per-table row limits — cap how many rows a SELECT may return from a specific table, for everyone or for chosen roles, groups or users, so two tables on one datasource (or two teams on one table) get different limits. A limit only ever lowers the cap set by the datasource and the access grant; a query across several limited tables takes the lowest one, and an unqualified table name still matches a schema-qualified policy. The policies that applied are recorded on the execution's audit entry.
- Data classification tagging — tag tables and columns as PII, PCI, PHI, GDPR, FINANCIAL, or SENSITIVE right in the schema explorer. Tagging a column auto-applies a masking policy, the AI analyzer raises a query's risk score when it touches a tagged object, and a derivation preview suggests a stricter review posture. Tags are audited and queryable org-wide as the evidence base for compliance reporting.
- Automated sensitive-data discovery — an opt-in per-datasource scanner samples column data through the same governed sampling path, detects sensitive values with local regex + checksum detectors (emails, credit-card PANs with Luhn, SSNs, IBANs, phone numbers) and optionally your bound AI analyzer (which only ever sees column names, types, and redacted samples), and proposes classification tags in a review worklist. Confirming a finding applies the tag — deriving masking automatically — while dismissing suppresses it permanently; scans and decisions are audited, and an on-demand "Scan now" complements the scheduled cadence. Proposals the scanner keeps sampling but no longer finds — the column was dropped, the data cleaned up, or masking added by hand — are marked stale after a few consecutive misses and leave the active worklist for a filtered bulk dismissal, reversibly: re-detection returns them to pending, and a run cut short by its table cap or time budget never ages proposals it did not look at.
- Result-export governance & DLP — masking governs what a user sees; export policies govern what leaves. Per-datasource policies with role / group / user targeting (
allow/watermark/row-cap/deny-when-classified, most-restrictive-wins, no admin bypass) gate the signed CSV/PDF result-export endpoint and the results attachment on recurring-run emails. Classified detection reuses the classification tags at export time; watermarked exports carry the exporter, timestamp, and query id inside the signed bytes (stripping the stamp invalidates the signature); every export writes aRESULT_EXPORTEDaudit row, and classified exports notify org admins — so "who downloaded this data" always has an answer. - User groups — bundle reviewers (and other users) into groups; groups can be assigned as datasource reviewers, granted data/API access (a whole team inherits a datasource or API-connector grant — read/write/DDL/break-glass — instead of a row per member; effective access is the most-permissive union of a user's direct and group grants), and auto-synced from SAML / OAuth2 IdP claims via per-IdP
group_mappings(admin-managed memberships are preserved across logins). - AI query analysis — pluggable adapters for OpenAI, Anthropic Claude, self-hosted Ollama, any OpenAI API–compatible backend (vLLM, LM Studio, Together, Groq, OpenRouter, …) via a custom endpoint, and Hugging Face (Inference Providers router or a local / self-hosted TGI server); risk scoring (0–100), missing-index detection, anti-pattern hints. Embeddings for the RAG knowledge base are configured separately on the same row and draw on a different list — Voyage AI belongs there and nowhere else, which gives an Anthropic-only install an embedding path without a second chat vendor (Claude has no embeddings API). Per-organization configuration via the admin UI, including an editable analyzer prompt per configuration (override the built-in template, or leave it blank to use the default); admin AI analyses dashboard charts average risk over time, top issue categories, and most active submitters. A per-organization rate limit (requests/minute, default 30) and optional monthly token budget cap AI usage so a runaway editor or compromised account can't drain the provider API key — enforced before every analysis call; exceedance returns HTTP 429 in the editor or records a sentinel
CRITICALanalysis row on the async path. A per-organization fallback pool marks configurations (typically a local Ollama) to retry in priority order when the primary provider is unreachable — air-gap-friendly resilience without weakening any failure semantics. - Multi-model orchestration, voting & guardrails — an AI configuration can run several models in parallel (the primary plus weighted
{provider, model, weight}members — e.g. a fast local Ollama pre-score alongside a deep Claude analysis) and combine their verdicts by a configurable voting strategy (weighted average, highest risk, or majority); issues are merged and risk aggregated. Guardrails block configured prompt patterns (case-insensitive regex) before any model is called, and the strict output-schema validation rejects malformed responses without failing the query. Per-model cost (tokens) and latency are recorded for every analysis and charted on the admin dashboard. - Query-optimization suggestions — alongside the risk verdict, the analyzer returns concrete, dialect-aware optimization suggestions: index recommendations (
CREATE INDEX …) and query rewrites. Each suggestion has a one-click "Apply as draft" that pre-fills the editor with the suggested statement and routes it through the normal review pipeline — nothing auto-executes, and the draft is audited as AI-suggested. - Query playground / dry-run sandbox — preview a query's impact before submitting it for review. A Dry run action returns the engine's execution plan (node type, estimated rows, cost, filters) and a best-effort estimated row impact without executing or mutating data, shown in the editor next to the AI panel. It runs through the same governance as a real execution (datasource access, table allow-list, row-level security) but creates no review. Dialect-aware across every engine with a plan concept — relational
EXPLAIN(PostgreSQL / MySQL / MariaDB / Oracle / SQL Server), MongoDBexplain, Couchbase / Neo4jEXPLAIN, Elasticsearch / OpenSearch query validation; engines without one degrade gracefully. Cloud warehouses additionally report the estimated bytes the query would scan (BigQuery's native dry-run job) — the direct cost signal for bytes-billed engines. SELECT dry-runs prefer the read replica when configured. - Pre-flight cost & blast-radius estimation (AF-624) — every submitted query automatically gets a persisted cost estimate before review: the engine's own
EXPLAINplan (estimated rows, scan type, cost) plus, for UPDATE/DELETE, an exact affected-row count computed with a governed, non-mutating count (relationalSELECT COUNT(*)rewrite; MongoDBcountDocuments, SQL++COUNT(*), Cyphercount(*), Elasticsearch_count). Reviewers see it on the query detail page ("this DELETE touches ~2.4M rows via Seq Scan"), routing policies can match onestimated_rows/scan_type(e.g. auto-escalate full-scan DELETEs over 100k rows), and the estimate is folded into the AI analyzer's prompt so risk scoring reflects the act
Questions sur AccessFlow MCP
Quelles bases de données AccessFlow prend-il en charge ?
Il prend en charge PostgreSQL, MySQL, MariaDB, Oracle, Microsoft SQL Server, MongoDB, Couchbase, Redis, Apache Cassandra, ScyllaDB, Elasticsearch, OpenSearch, Amazon DynamoDB, Neo4j, Snowflake, Google BigQuery et Databricks SQL.
Comment AccessFlow gère-t-il les accès API ?
La gouvernance s'étend aux appels sortants REST, SOAP, GraphQL et gRPC grâce au scoring de risque par IA, au routage basé sur les attributs et à une approbation multi-étapes avec masquage des réponses.
Puis-je utiliser mon propre fournisseur d'authentification ?
Oui, il prend en charge JWT (RS256) avec une option SSO SAML 2.0 et une connexion OAuth 2.0 / OIDC, incluant des modèles pour Google, GitHub, Microsoft et GitLab.