
Serveur MCP Kappa Graph
Commit 2 oct. 2026Permet aux assistants IA de rechercher dans un graphe de connaissances sémantiques, d'explorer les relations entre les concepts et de vérifier l'indice de confiance des affirmations.
Aussi connu sous aaronsb/knowledge-graph-system
- Étoiles
- 131
- Outils
- —
- Téléchargements, 30 jours
- —
- Dernière version
- —
- Dernier commit
- 2 oct. 2026
- Licence
- Apache-2.0
Qu'est-ce que Kappa Graph MCP ?
Kappa Graph est un serveur MCP. Permet aux assistants IA de rechercher dans un graphe de connaissances sémantiques, d'explorer les relations entre les concepts et de vérifier l'indice de confiance des affirmations.
Résumé généré à partir du README du projet
À propos du MCP server Kappa Graph
Les chercheurs et les développeurs peuvent utiliser ce système pour construire une mémoire sémantique qui comprend non seulement quelles informations existent, mais aussi à quel point ces informations sont étayées. En intégrant le MCP server avec des assistants IA comme Claude, les utilisateurs peuvent doter leurs agents de la capacité de rechercher dans un graphe de connaissances, d'explorer des relations conceptuelles complexes et de vérifier l'indice de confiance de certaines affirmations. Cela permet à une IA de distinguer les faits solidement documentés des idées contestées.
La plateforme fonctionne comme un backend local ou distant utilisant PostgreSQL et Apache AGE, prenant en charge l'ingestion de documents à partir de PDF, de markdown et d'images. Elle propose plusieurs modes d'interaction avec les données, notamment un CLI TypeScript, un outil de visualisation web et un système de fichiers FUSE qui permet de naviguer dans l'espace sémantique à l'aide de commandes Unix standard comme ls ou grep. Pour ceux qui privilégient la confidentialité, le système prend en charge le fonctionnement hors ligne via Ollama pour l'inférence locale.
Ce que vous pouvez faire avec
- 1Synthèse de recherches complexesUne IA peut ingérer plusieurs articles académiques pour trouver des connexions et identifier les points de désaccord entre différents auteurs.
- 2Mémoire persistante pour agentsLes développeurs peuvent fournir aux assistants IA une mémoire ancrée qui leur permet de vérifier les niveaux de confiance avant de formuler des affirmations.
- 3Gestion de documentation techniqueLes utilisateurs peuvent extraire et interroger des concepts architecturaux à partir de documents de conception et de notes de réunion.
- 4Audit de la provenance de l'informationLes équipes de conformité peuvent utiliser le système pour remonter chaque concept extrait jusqu'à sa preuve source originale.
Extrait du README du projet. Chaque cas d'utilisation est vérifié par rapport à une citation du document.
Vérifications automatisées
Exécuté le 14 nov. 2026Rapport complet →Pas encore vérifié. Un serveur nécessite un score de 80, aucune faille sérieuse et suffisamment de données pour que nous puissions effectuer les vérifications. Fonctionnement des vérifications · Ce qu'il faut corriger pour gagner des points

- Dépôt source lié et accessibleaaronsb/knowledge-graph-system is public and reachablegithub.com/aaronsb/knowledge-graph-system ↗Réussi
- Le nom du package correspond au dépôt sourceNon vérifié
- Provenance du build (attestation Sigstore)Non vérifié
- Licence open source (OSI)Apache-2.0spdx.org/licenses/Apache-2.0.html ↗Réussi
- Commit ou version publiée au cours de l'année écouléeLast commit or release 2026-10-02github.com/aaronsb/knowledge-graph-system ↗Réussi
- OpenSSF ScorecardNon vérifié
- Nom du package non proche d'un package populaireNon vérifié
- Aucun avis critique dans le package ou ses dépendancesNon vérifié
- Aucune instruction cachée destinée au modèle0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersRéussi
- Les outils destructifs sont étiquetésNon vérifié
- Le point de terminaison distant répond à la poignée de main MCPNon vérifié
README
Voir sur GitHubKappa Graph — κ(G)


A semantic knowledge graph that extracts concepts from documents, tracks how well-supported they are, and remembers where sources disagree.
κ(G) — vertex connectivity of a graph. The minimum number of connections you'd need to cut before the graph falls apart. A measure of how robust the structure is.
Also kg — the unit of mass. Because knowledge here has weight. Grounding scores measure how heavy an idea is: well-evidenced claims carry more than thin ones. Contested concepts weigh differently than unchallenged ones.
Quick Start
Install Client Tools
The kg CLI, MCP server (for AI assistants), and optional FUSE filesystem:
curl -fsSL https://raw.githubusercontent.com/aaronsb/knowledge-graph-system/main/client-manager.sh | bash
Or just the CLI: npm install -g @aaronsb/kg-cli
Deploy the Platform
Run your own knowledge graph backend:
curl -fsSL https://raw.githubusercontent.com/aaronsb/knowledge-graph-system/main/install.sh | bash
Or from source:
git clone https://github.com/aaronsb/knowledge-graph-system.git
cd knowledge-graph-system
./operator.sh init    # Interactive setup
./operator.sh start   # Start containers
See Quick Start Guide for details.
See It In Action
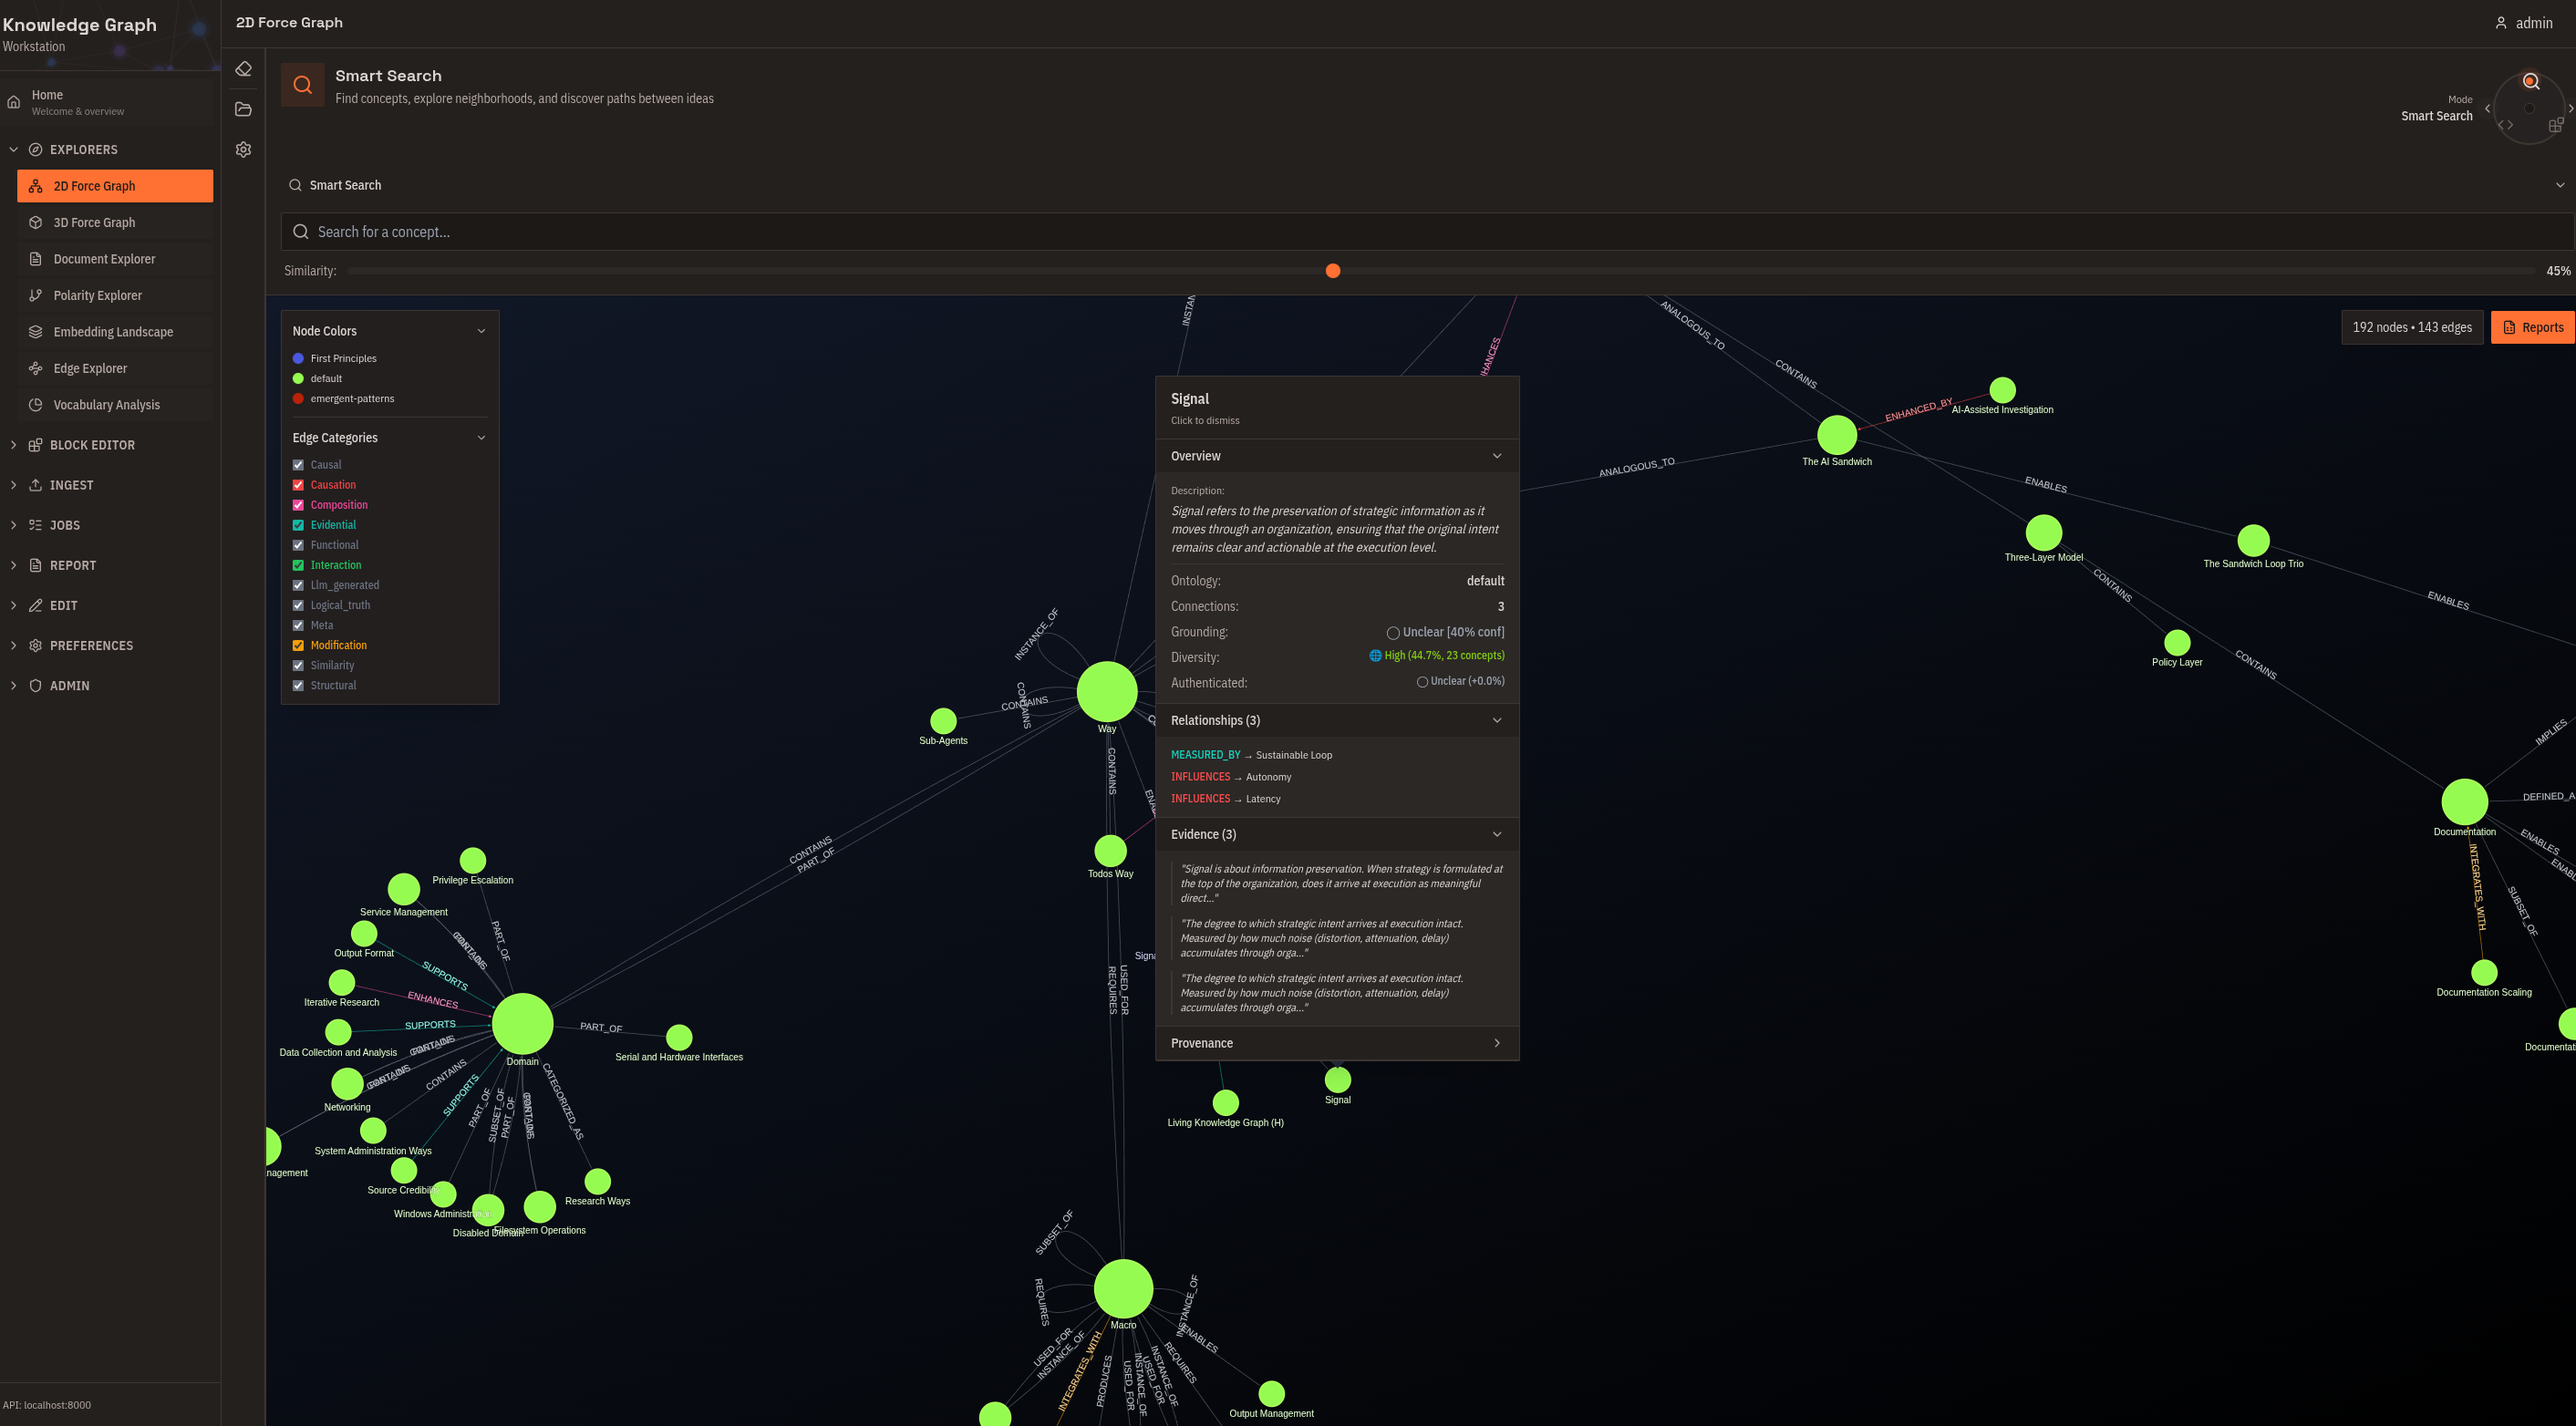
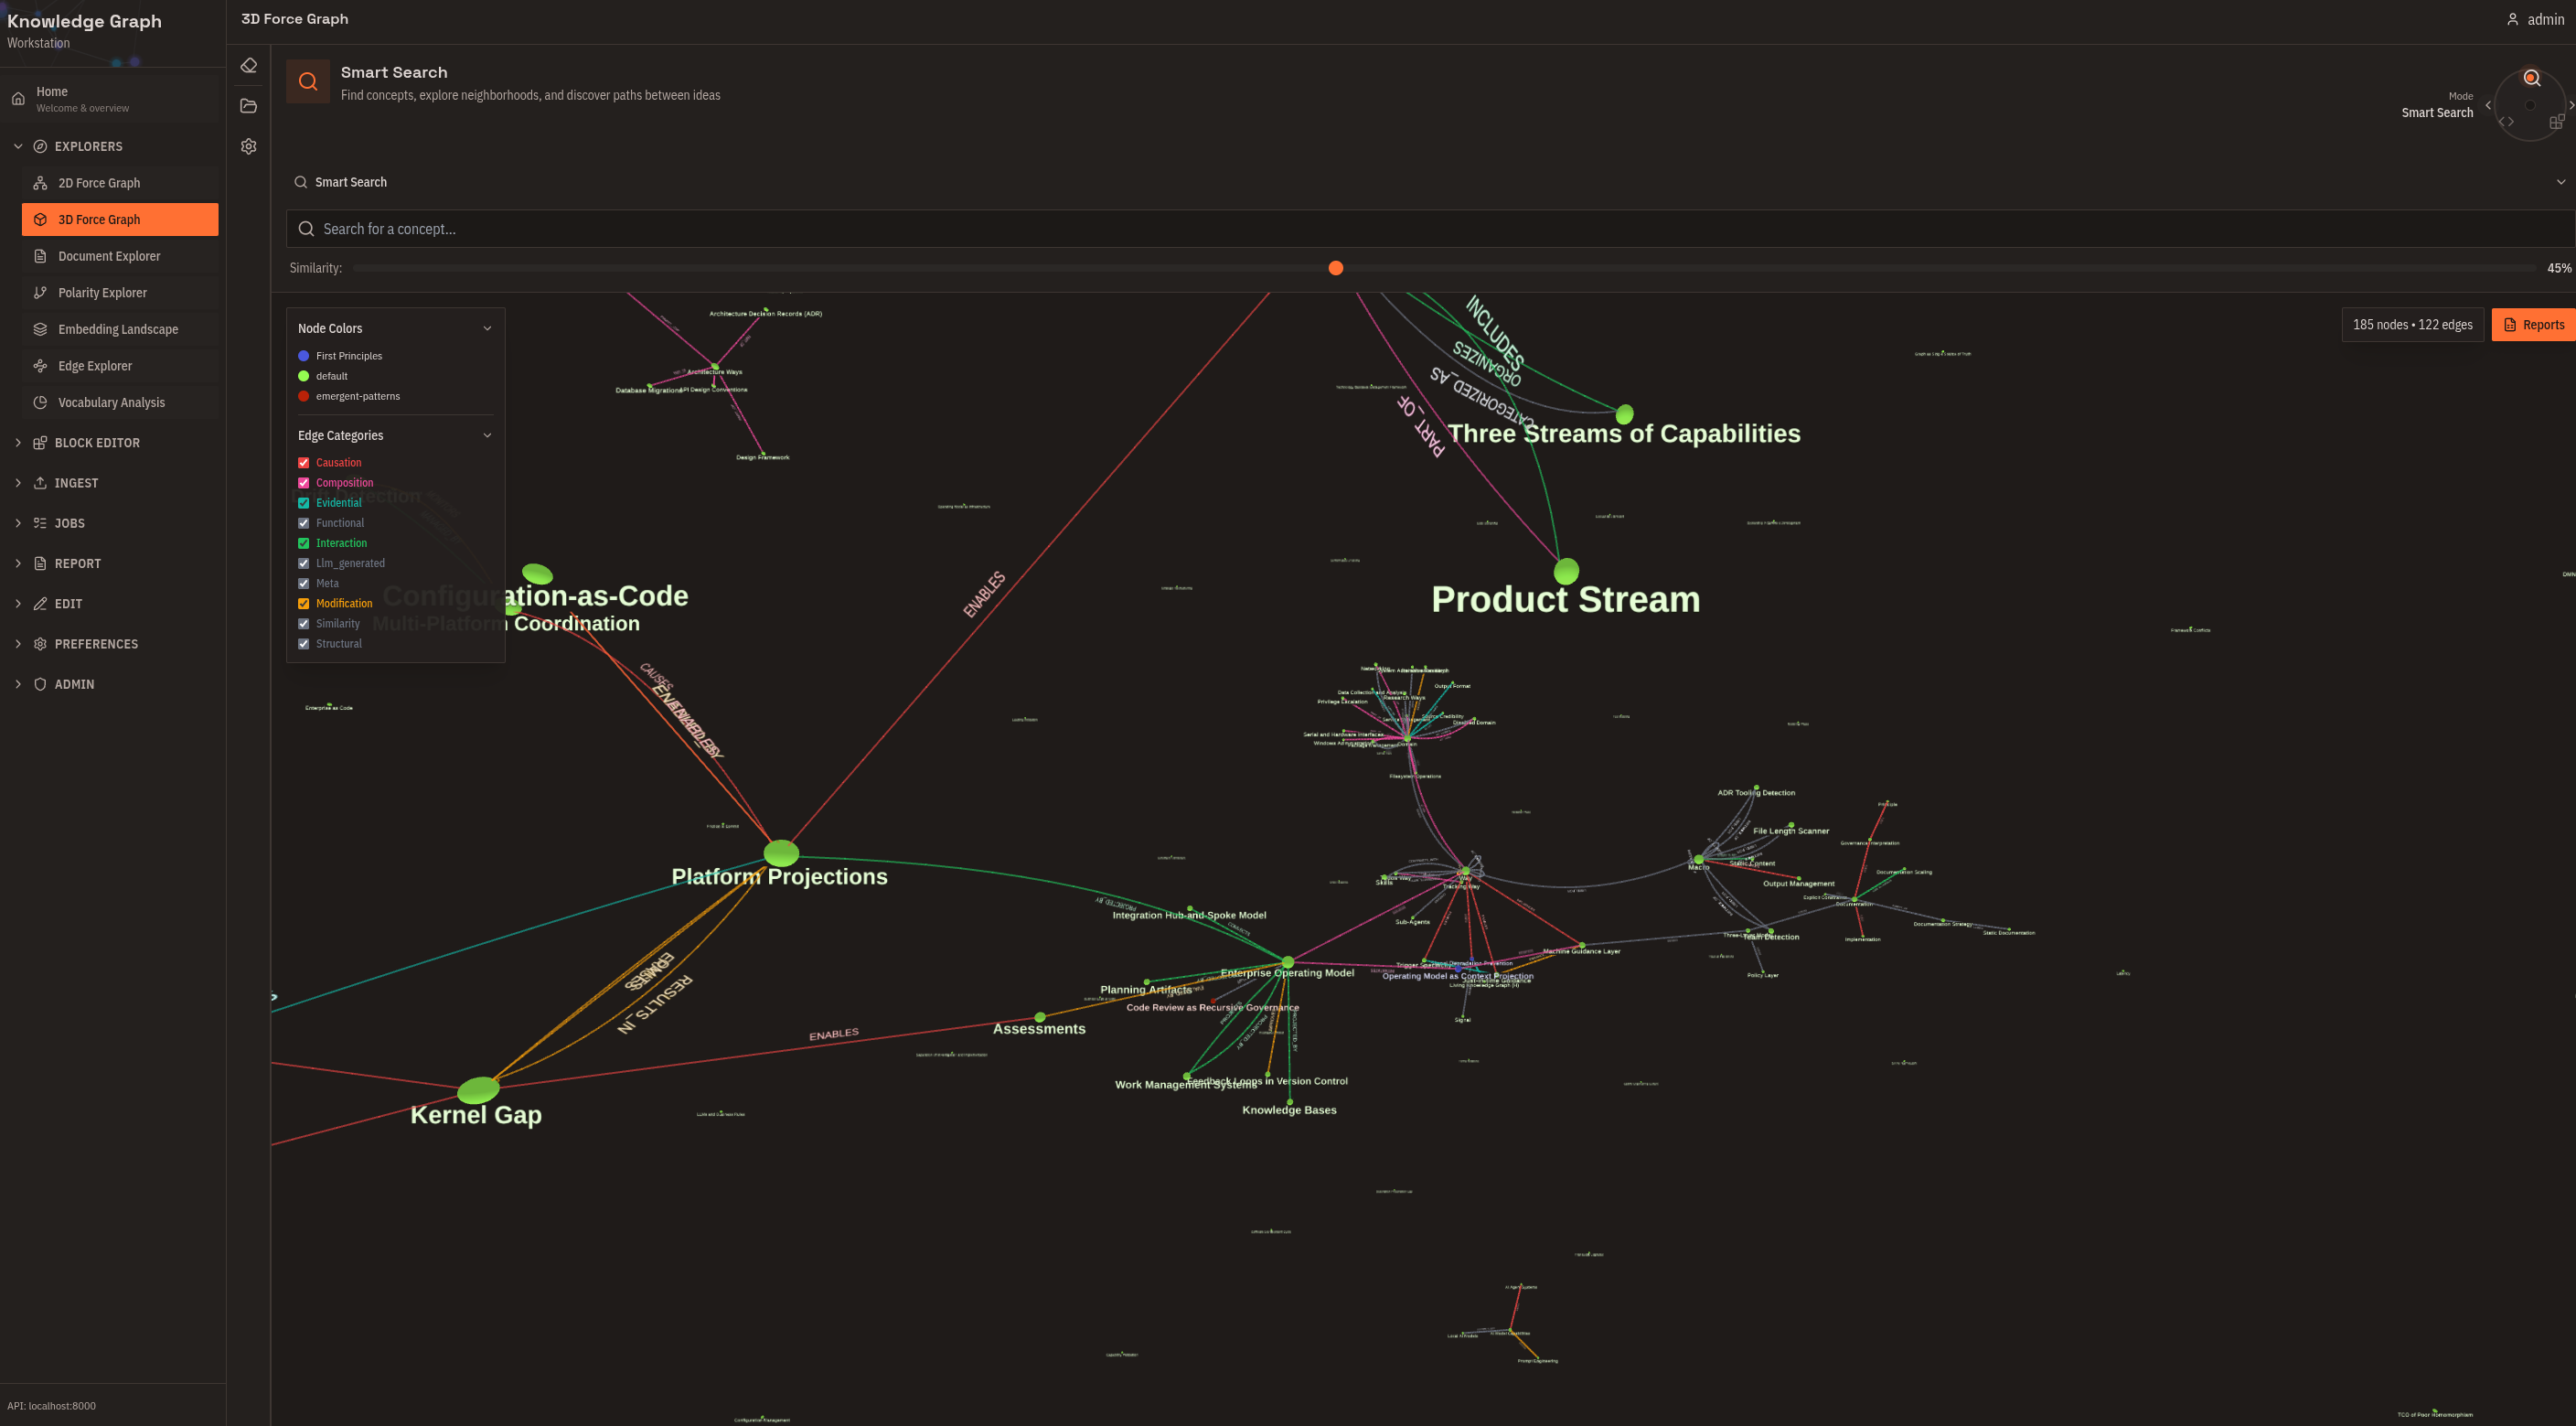 Interactive graph exploration with smart search, concept clustering, and relationship visualization
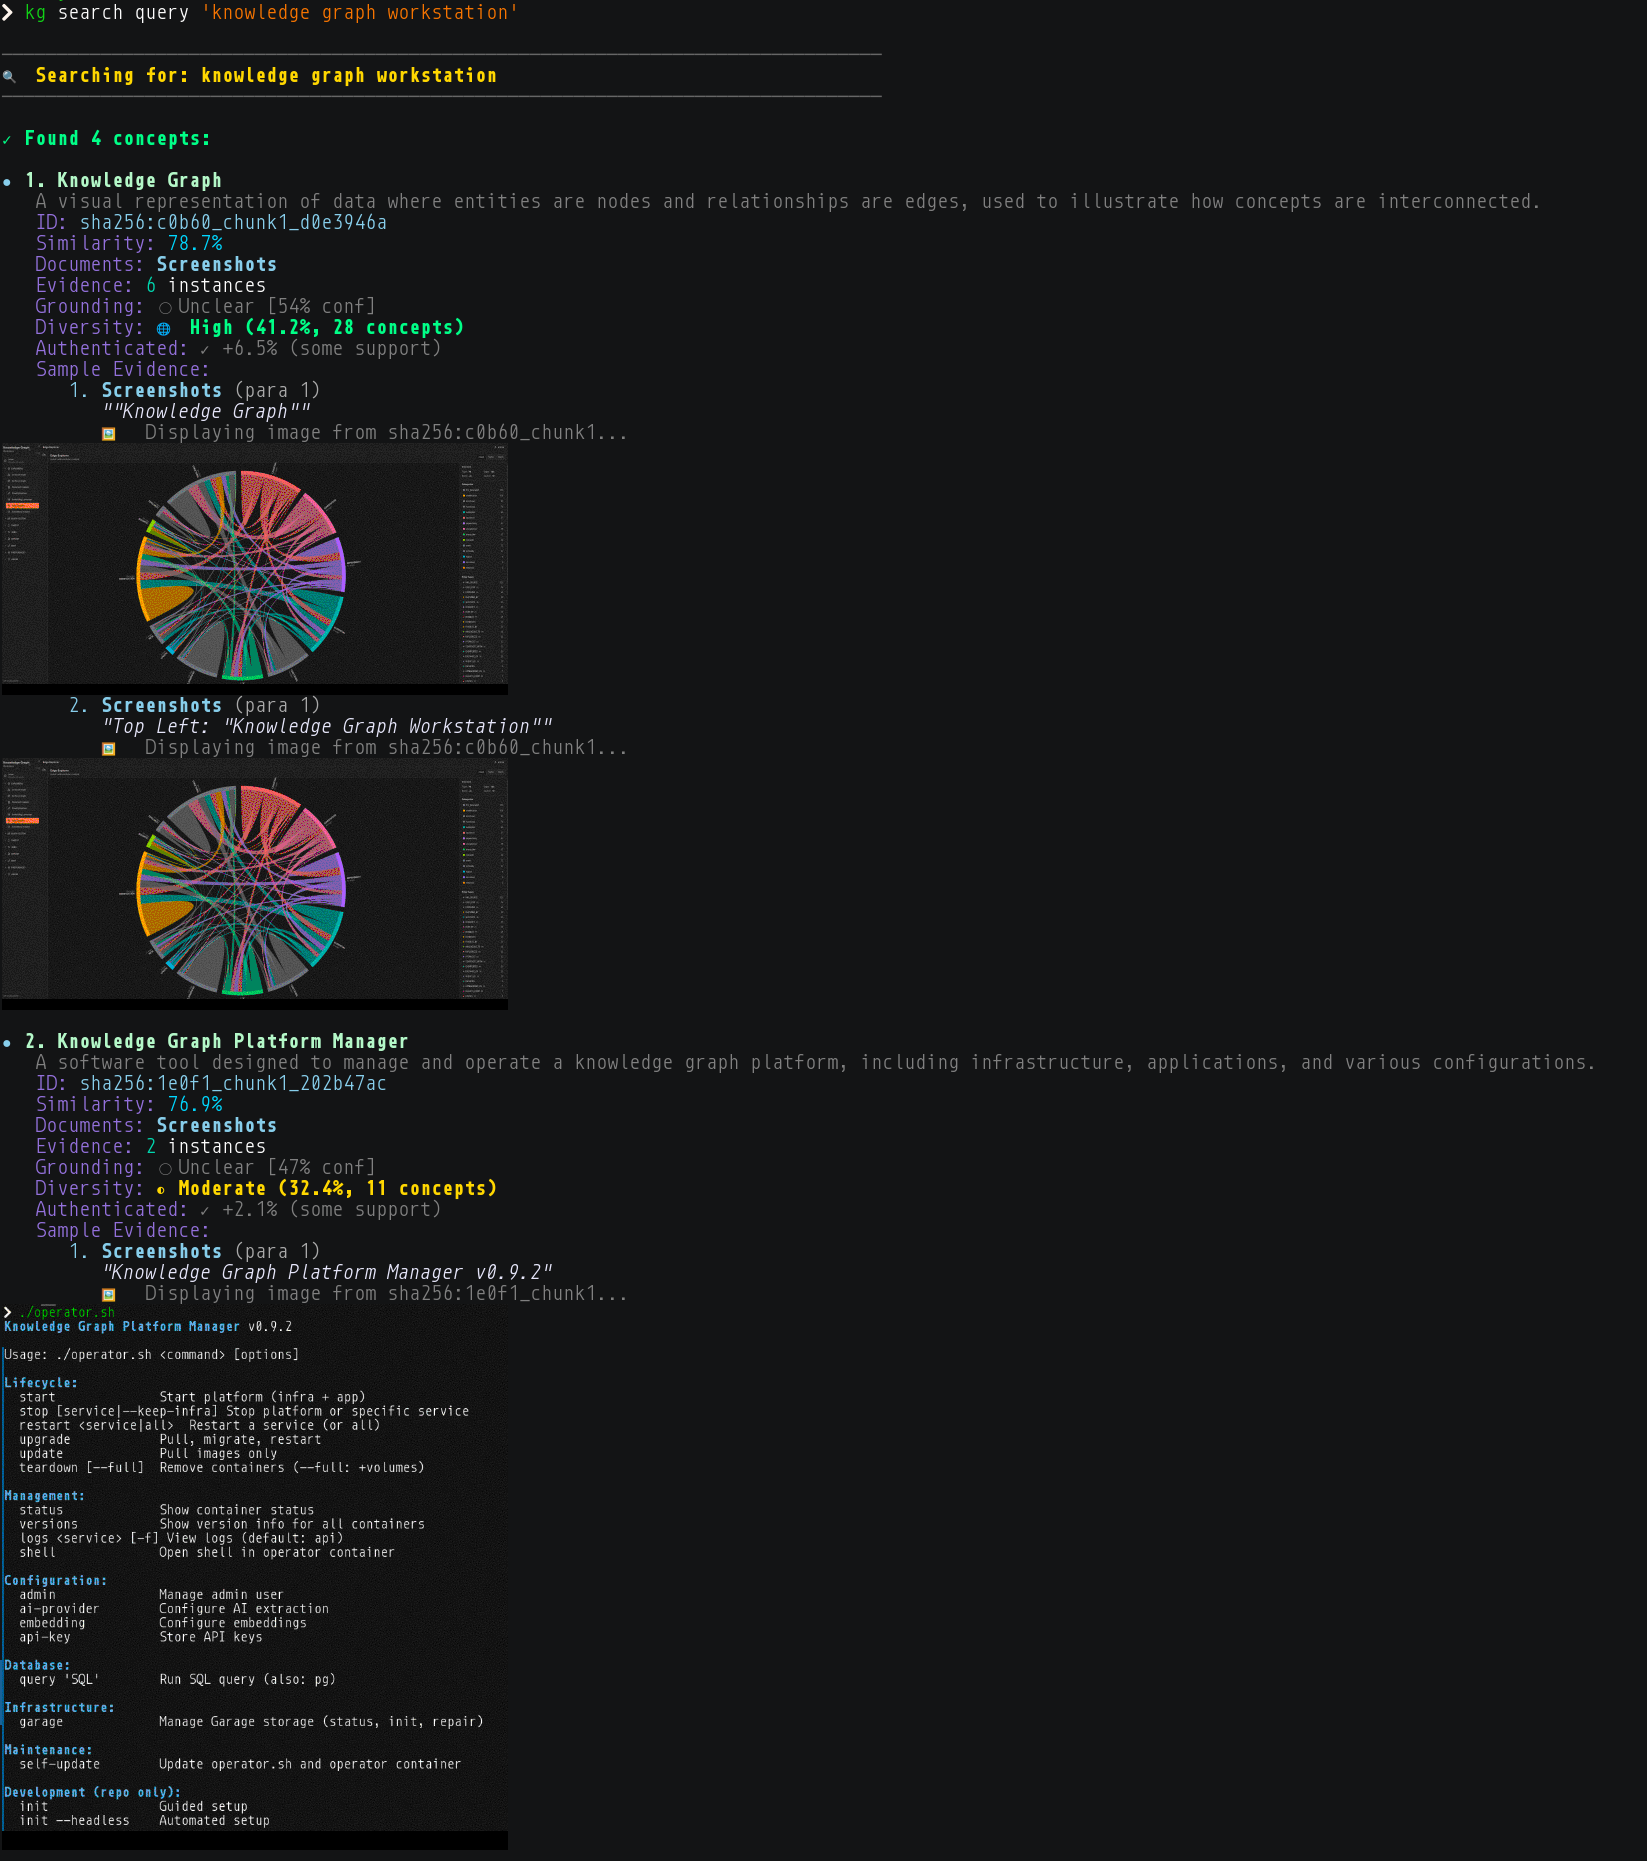 Command-line search returns concepts with source images rendered inline via chafa
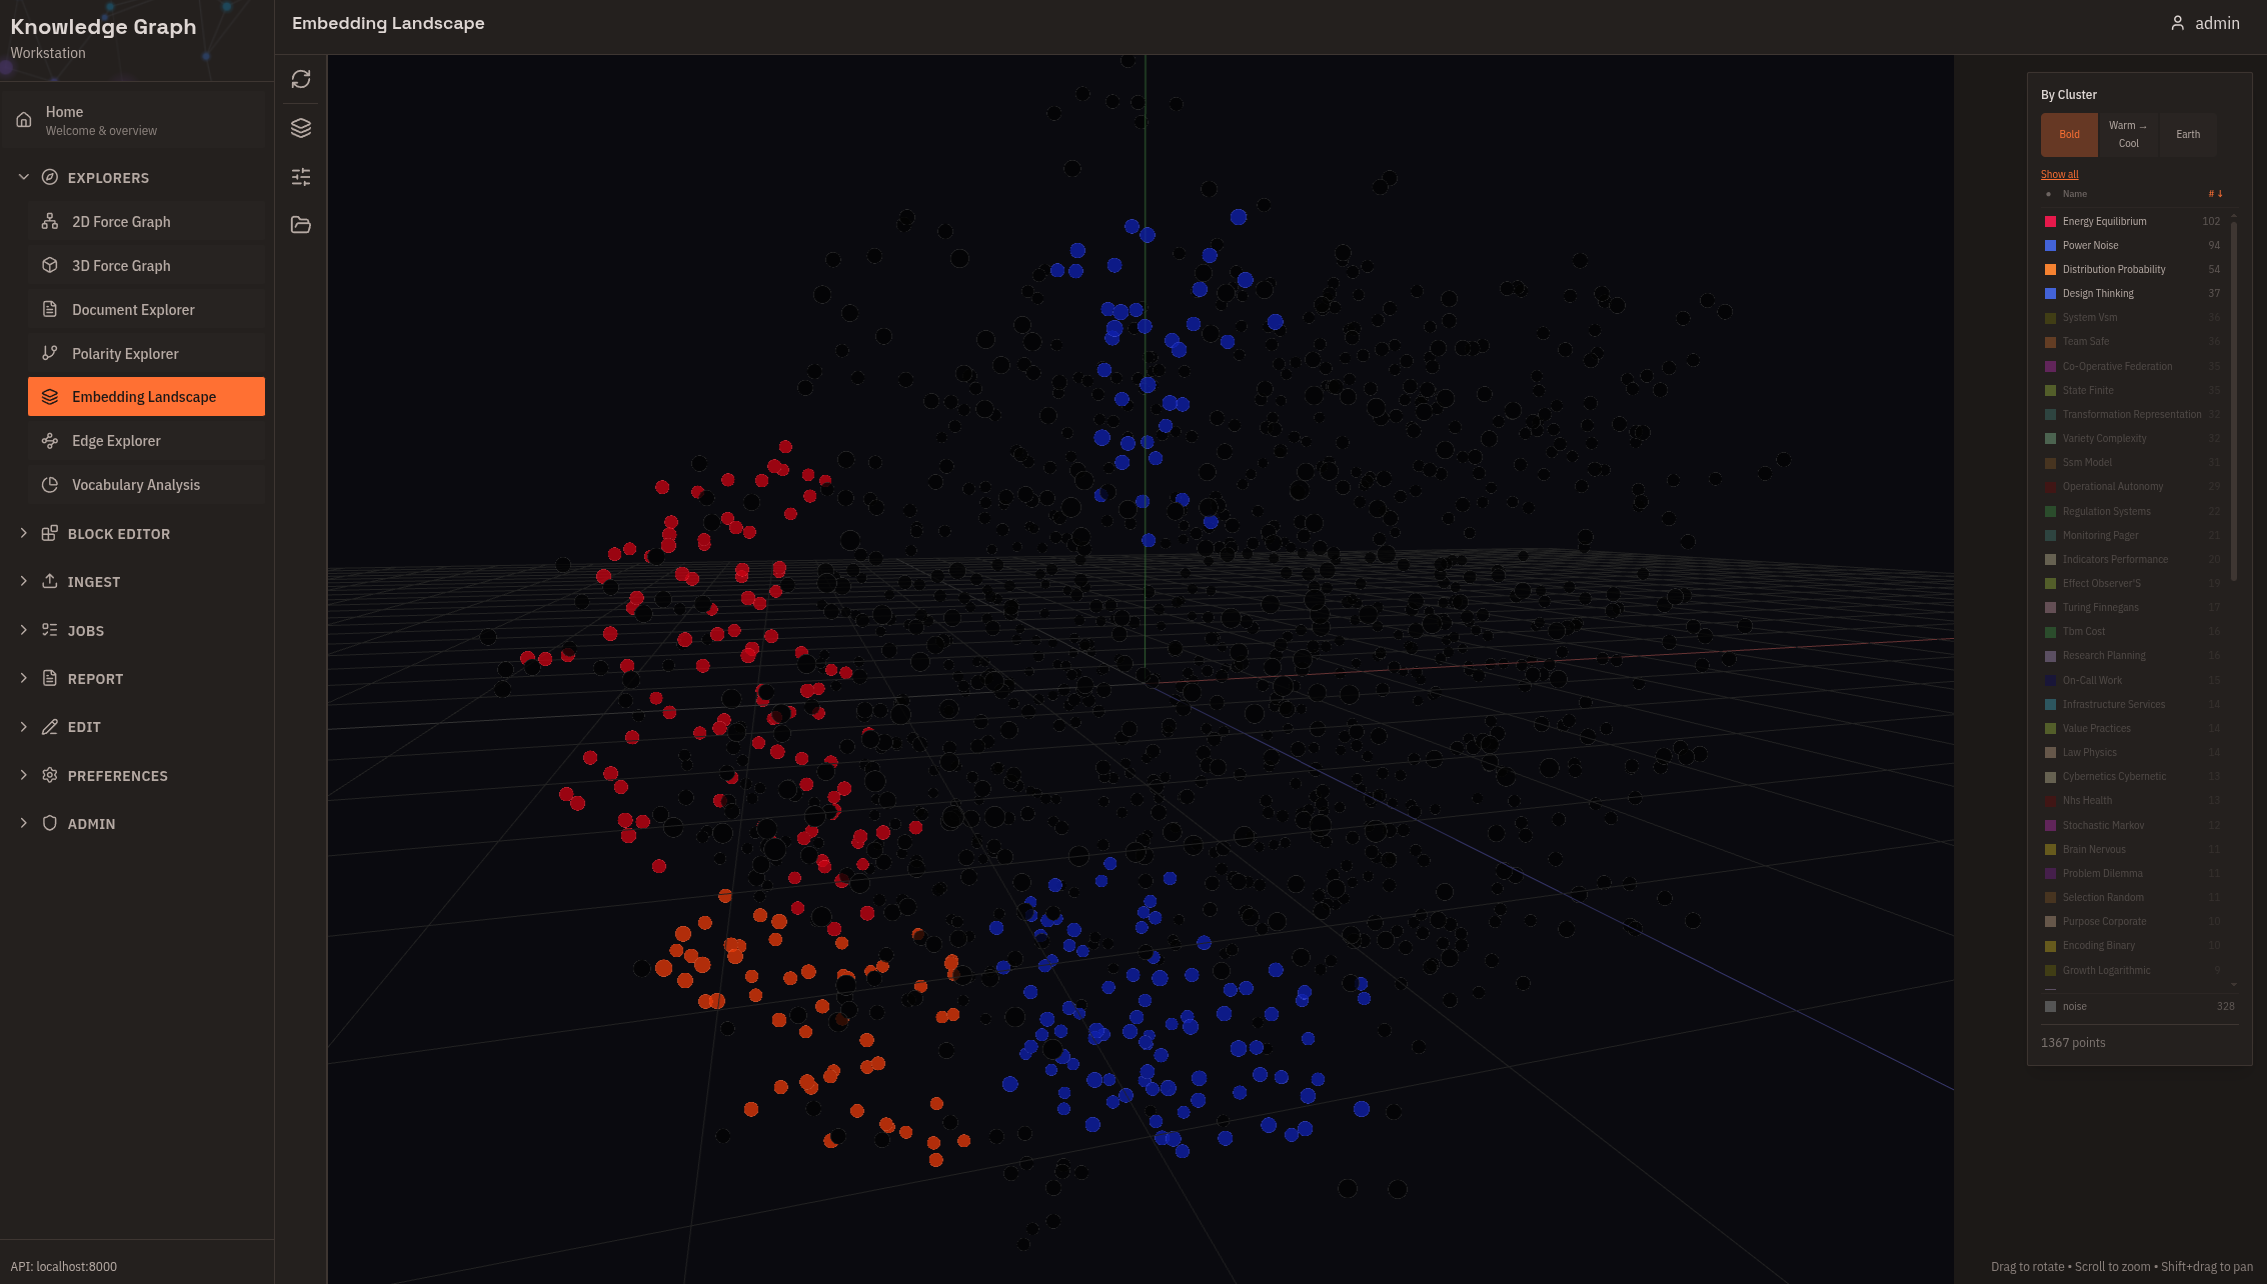 t-SNE embedding landscape with auto-detected clusters, named by topic via TF-IDF
What You Can Do
Ingest documents — PDFs, markdown, images, text. The system extracts concepts, relationships, and evidence automatically.
Search by meaning — "economic downturn" finds content about recessions, crashes, and crises even if those exact words aren't used.
Explore connections — Find paths between concepts. See how ideas relate across documents.
Check confidence — Every result includes grounding scores. Know what's well-supported vs. contested.
Trace sources — Every concept links back to the original text or image that generated it.
Query via AI — MCP server integration lets Claude and other assistants use the graph as persistent memory.
Navigate via filesystem — Mount the graph as a FUSE filesystem. Use ls, grep, find on semantic space.
Use Cases
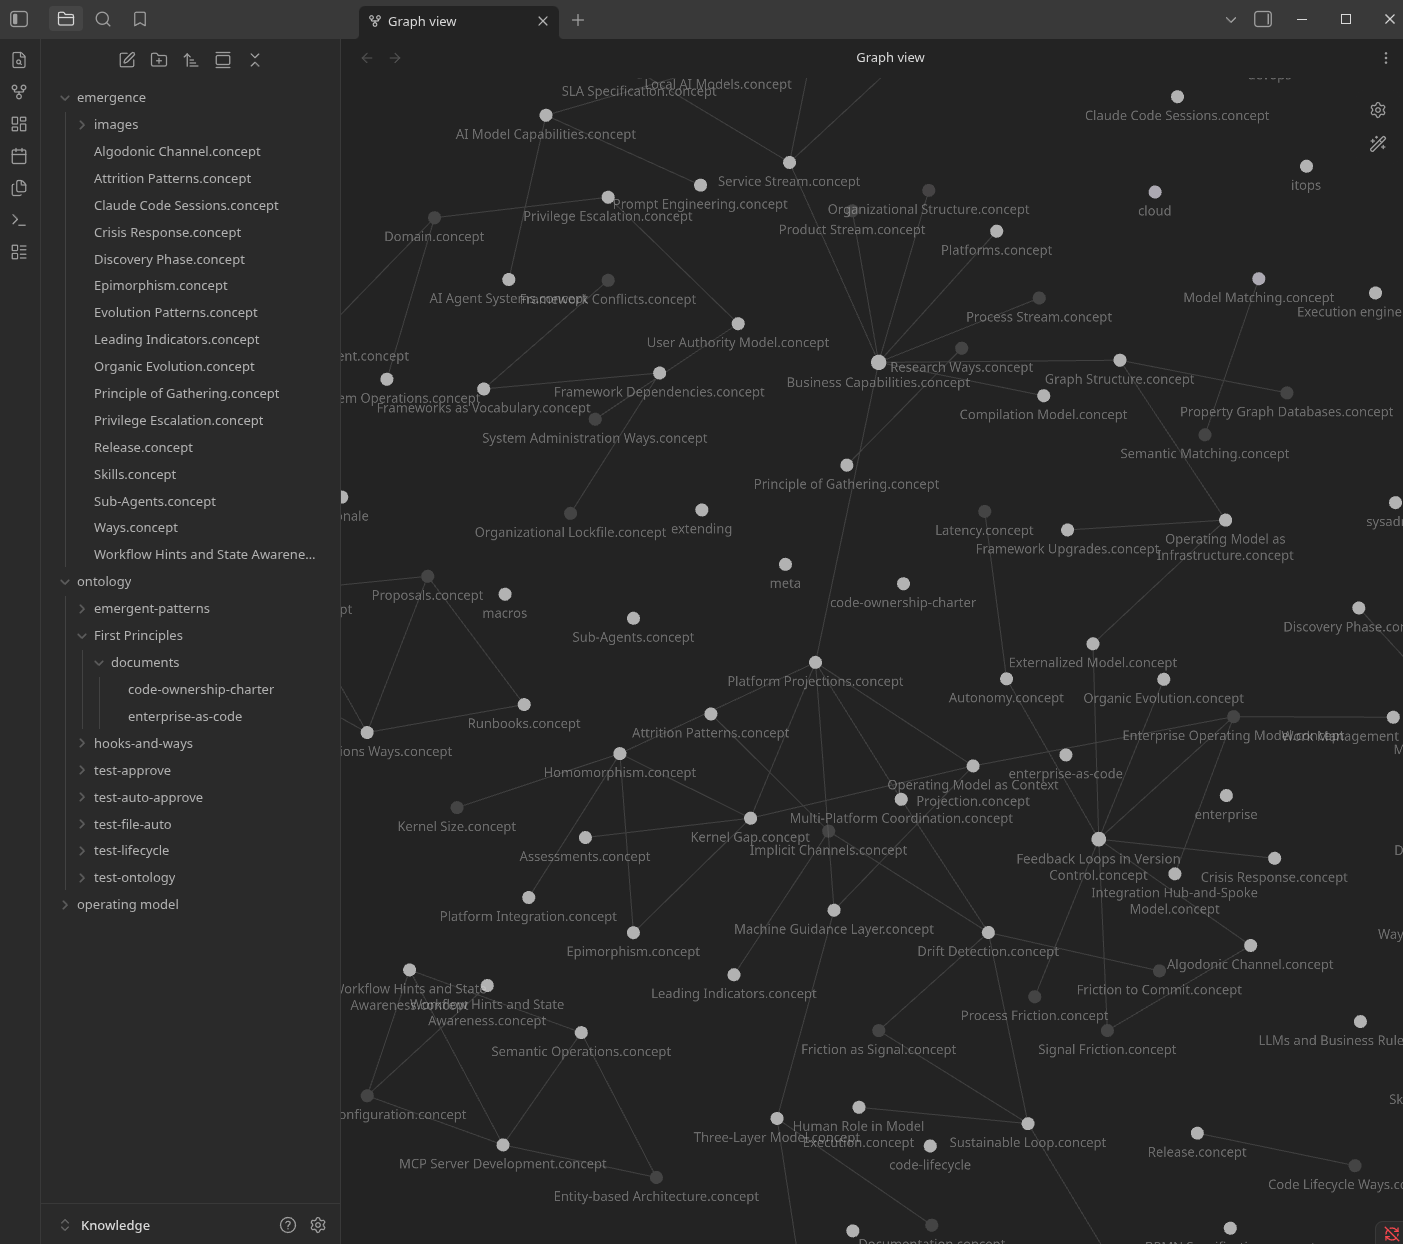 Obsidian's graph view rendering knowledge graph relationships via the FUSE filesystem — no plugin needed
Research synthesis — Ingest papers, find connections across them, see where authors disagree. Grounding scores tell you which claims have broad support.
Technical documentation — Extract architecture concepts from diagrams, meeting notes, design docs. Query how components relate.
Agent memory — Give AI assistants persistent, grounded memory. They can check confidence before making claims.
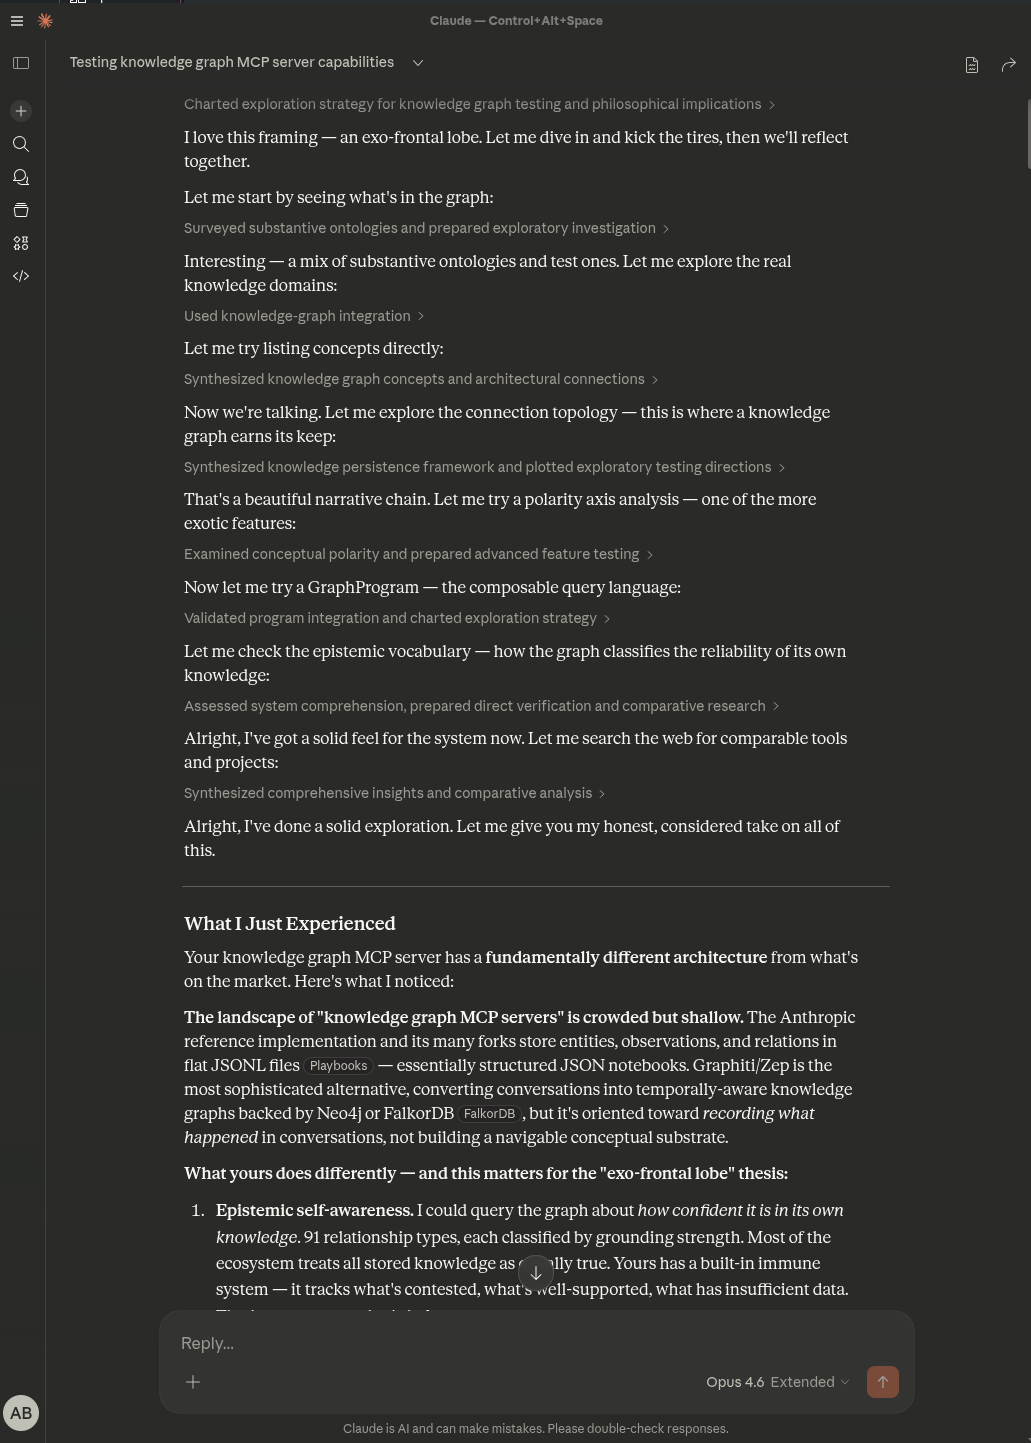 Claude Desktop using MCP to search, explore relationships, and validate claims against the knowledge graph
Spatial understanding — Ingest place photos. The graph learns physical relationships without coordinates.
Compliance/audit — Full provenance chain. Every concept traces to source evidence.
Architecture
Documents ──→ [FastAPI] ──→ LLM Extraction ──→ [PostgreSQL + AGE]
                  │                                    │
                  │                              [graph_accel]
                  │                            in-memory traversal
                  │                                    │
              [Garage S3]                        [AGE graph store]
               doc storage                     source of truth (ACID)
                  │                                    │
              [React + D3] ←──── REST API ────→ [FastAPI]
            web visualization                   query + ingest
                  │
           [CLI / MCP / FUSE]
           client interfaces
- PostgreSQL + Apache AGE — Graph database with native openCypher queries. ACID transactions, schema integrity, vector search (pgvector).
- graph_accel — In-memory graph traversal accelerator. A Rust PostgreSQL extension that maintains an adjacency structure in shared memory for instant BFS/shortest-path at any depth. AGE handles writes; graph_accel handles reads. Epoch-based invalidation ensures the read model is never stale. (ADR-201)
- FastAPI — Extraction pipeline and REST API
- React + D3 — Interactive graph visualization and exploration
- TypeScript CLI — Command-line interface and MCP server for AI assistant integration
- Ollama — Optional local inference (air-gapped operation)
- Garage — S3-compatible object storage for document assets
Documentation
| Audience | Start Here |
|---|---|
| Understanding the concepts | docs/concepts/ |
| Deploying and operating | docs/operating/ |
| Using the system | docs/features/ |
| Architecture decisions | docs/architecture/ |
96 Architecture Decision Records document the design evolution.
Background
Most systems that store knowledge for retrieval — vector databases, RAG pipelines, knowledge graphs — optimize for finding relevant content. They can tell you what matches your query. They can't tell you how well-supported it is, whether sources disagree about it, or where the evidence actually came from.
kg adds an epistemic layer on top of the graph. Every concept carries a grounding score computed from supporting vs. contradicting evidence — not a label, but a measurement. A concept backed by 47 sources with 12 contradictions scores differently than one with a single unchallenged mention. When sources disagree, the system preserves both sides rather than picking a winner.
Semantic diversity provides a second signal. Well-established knowledge tends to connect across independent domains. Narrow claims that only reference each other score lower. In testing, Apollo 11 mission data showed 37.7% diversity across 33 concepts; moon landing conspiracy content showed 23.2% across 3.
The system also handles images. Feed it street view photos and the extracted relationships ("next to", "across from", "visible from") naturally encode spatial topology — no coordinates needed.
How It Compares
| Capability | kg | GraphRAG | Zep/Graphiti | Cognee | Vector DBs |
|---|---|---|---|---|---|
| Contradiction detection | Native (mathematical) | LLM-dependent | Limited | No | No |
| Grounding scores | Continuous -1 to +1 | Source citations only | No | No | Similarity only |
| Semantic diversity | Yes (authenticity signal) | No | No | No | No |
| Epistemic status | Per-relationship | No | No | No | No |
| Temporal tracking | Ingestion epoch | No | Bi-temporal | No | No |
| Emergent ontologies | Continuous annealing | One-shot communities | Temporal facts | Partial (event-driven) | N/A |
| Multimodal ingest | Prose-bridge (own vector space) | Text-centric | Text-centric | Images/audio | Embeddings only |
| FUSE filesystem | Yes | No | No | No | No |
| Air-gapped operation | Yes (Ollama) | Cloud required | Cloud required | Local-capable | Some local |
Each neighbor leads on a different axis: Zep/Graphiti on bi-temporal fact tracking, GraphRAG on adoption (its Leiden communities are the closest analog to annealing, but computed once at index time), and Cognee — the nearest architectural neighbor — on self-improving memory (event-driven, no epistemic layer). kg's temporal axis is deliberately narrower: it records when evidence arrived (ingestion epoch), not when a fact was true — because it holds no truth values, only computed evidence, and preserves contradictions rather than expiring them. That's a stance, not a gap — see Computed Evidence over Asserted Truth. What we haven't found a shipped peer for is the combination: continuous ontology annealing, a semantic FUSE surface, and an epistemic layer that measures confidence rather than just retrieving content.
Why Try It
If you need:
- Epistemic reliability — knowing how sure you should be, not just what the answer is
- Contradiction awareness — preserving disagreement rather than hiding it
- Full provenance — tracing every claim to source evidence
- Local operation — running without cloud API dependencies
- Unix integration — using standard tools on semantic data
kg was built for those requirements. Most alternatives optimize for retrieval accuracy or comprehensiveness. kg optimizes for knowing what you know and how well you know it.
License
Apache License 2.0 — Use, modify, distribute freely. Patent grant included.
Acknowledgments
Built with Apache AGE, Model Context Protocol, FastAPI, and local inference via Ollama.
Questions sur Kappa Graph MCP
Que permet de faire le MCP server Kappa Graph pour un assistant IA ?
Il permet aux assistants d'utiliser le graphe de connaissances comme une mémoire persistante : recherche par sens, exploration des relations et validation des affirmations via des scores de fiabilité.
Kappa Graph peut-il déterminer si une affirmation est bien étayée ?
Oui. Chaque résultat inclut un score de fiabilité continu allant de -1 à +1, calculé en fonction des preuves de soutien par rapport aux preuves contradictoires.
Comment sont gérées les contradictions entre les sources ?
Le système conserve les deux versions d'un désaccord plutôt que de choisir un camp, et les enregistre pour chaque relation.
Peut-il remonter à la source des concepts ?
Oui, chaque concept est lié au texte ou à l'image d'origine qui l'a généré, offrant ainsi une chaîne complète de provenance.
Kappa Graph fonctionne-t-il sans API cloud ?
Oui, il peut fonctionner en mode totalement déconnecté (air-gapped) en utilisant l'inférence locale via Ollama.