
MCP server Zap Coding Agent
Коммит 4 окт. 2026 г.Локальный ИИ-агент для кодинга с терминальным интерфейсом, написанный на Rust. Использует индексацию на базе AST и внедрение навыков (skill injection) для минимизации затрат на токены контекста.
Также известен как zap-coding-agent/zap-coding-agent
- Звёзды
- 38
- Инструменты
- 26
- Загрузки, 30 дней
- —
- Последняя версия
- —
- Последний коммит
- 4 окт. 2026 г.
- Лицензия
- MIT
Что такое Zap Coding Agent MCP?
Zap Coding Agent — это MCP server. Локальный ИИ-агент для кодинга с терминальным интерфейсом, написанный на Rust. Использует индексацию на базе AST и внедрение навыков (skill injection) для минимизации затрат на токены контекста. Он предоставляет 26 инструментов, например read_file, edit_file, batch_edit.
Сводка сгенерирована из README проекта
О Zap Coding Agent MCP server
Zap Coding Agent — это локальный ИИ-агент для кодинга с терминальным интерфейсом, написанный на Rust. Он разработан для разработчиков, которые хотят минимизировать затраты на токены контекста и избежать раздувания промптов во время сессий программирования. Агент работает как единый бинарный файл без необходимости установки runtime, что упрощает локальную установку и запуск. Для выполнения задач он подключается к провайдерам LLM, таким как Anthropic, через API ключи.
В отличие от традиционных агентов, которые при каждом шаге отправляют массивные статические системные промпты, этот инструмент использует систему внедрения навыков. Он отправляет инструкции, специфичные для конкретного языка или задачи (например, навыки работы с Rust или React), только тогда, когда это требуется согласно вашему запросу. Также реализована индексация кодовой базы на базе AST, что помогает агенту понять структуру проекта перед внесением изменений. Чтобы контекст оставался чистым, агент управляет знаниями о проекте через специализированные файлы, такие как ZAP.md и .zap/understanding.md, которые загружаются по требованию, а не предустанавливаются в каждый промпт.
Что вы можете с ним делать
- 1Инициализация контекста проектаРазработчик может использовать команду init для анализа репозитория и подготовки базы знаний проекта за считанные секунды.
- 2Снижение потребления токеновРазработчики могут использовать агента для выполнения конкретных задач, таких как рефакторинг кода на Rust, не переплачивая за лишний контекст языка.
- 3Сохранение непрерывности сессииАгент может автоматически отслеживать, что было сделано в предыдущих сессиях, чтобы подготовиться к следующей.
Взято из README проекта. Каждый вариант использования проверен на соответствие цитате из него.
Инструменты Zap Coding Agent MCP 26
Определено из READMEread_fileedit_filebatch_editwrite_fileundo_editshellgit_statussearch_codelist_directoryglob_readcode_mapfind_definition
| read_file | — | |
| edit_file | — | |
| batch_edit | — | |
| write_file | — | |
| undo_edit | — | |
| shell | — | |
| git_status | — | |
| search_code | — | |
| list_directory | — | |
| glob_read | — | |
| code_map | — | |
| find_definition | — |
Показать все 26 инструментовПоказать меньше инструментов
find_referenceswho_callsfile_importswhere_importedfind_subtypesfind_supertypespack_contextripple_analysisget_diagnosticslsp_definitionlsp_type_atweb_fetchweb_searchspawn_agent
| find_references | — | |
| who_calls | — | |
| file_imports | — | |
| where_imported | — | |
| find_subtypes | — | |
| find_supertypes | — | |
| pack_context | — | |
| ripple_analysis | — | |
| get_diagnostics | — | |
| lsp_definition | — | |
| lsp_type_at | — | |
| web_fetch | — | |
| web_search | — | |
| spawn_agent | — |
Конфигурация
AGENT_API_KEYAGENT_MODELAGENT_PERMISSION_MODEAGENT_PROVIDERANTHROPIC_API_KEY
| Название | Описание | Тип |
|---|---|---|
| AGENT_API_KEY | — | |
| AGENT_MODEL | — | |
| AGENT_PERMISSION_MODE | — | |
| AGENT_PROVIDER | — | |
| ANTHROPIC_API_KEY | — |
Автоматические проверки
Запущено 14 нояб. 2026 г.Полный отчёт →Еще не проверено. Для сервера требуется оценка 80, отсутствие серьезных проблем и достаточно данных для нашей проверки. Как работают проверки · Что исправить, чтобы получить больше баллов

- Связанный и доступный исходный репозиторийzap-coding-agent/zap-coding-agent is public and reachablegithub.com/zap-coding-agent/zap-coding-agent ↗Пройдено
- Пакет указывает этот репозиторий как источникНе проверялось
- Происхождение сборки (аттестация Sigstore)Не проверялось
- Open source лицензия (OSI)MITspdx.org/licenses/MIT.html ↗Пройдено
- Коммит или релиз за последний годLast commit or release 2026-10-04github.com/zap-coding-agent/zap-coding-agent ↗Пройдено
- OpenSSF ScorecardНе проверялось
- Имя пакета не похоже на популярный пакетНе проверялось
- Нет критических предупреждений в пакете или его зависимостяхНе проверялось
- Нет скрытых инструкций для модели26 tool descriptions and the README read; no override phrases, credential paths or hidden charactersПройдено
- Деструктивные инструменты помеченыНе проверялось
- Удалённая конечная точка отвечает на рукопожатие MCPНе проверялось
README
Открыть на GitHub⚡ Zap Coding Agent
Website · Docs · Roadmap · Changelog · Install · Demo


ZAP is a terminal-first, local AI coding agent built in Rust. It uses AST-powered codebase indexing and lazy-loaded skills to completely eliminate prompt bloat and minimize context token costs — single binary, no runtime.
  ╭────────────────────────────────────────────────────────────────────╮
  │                                                                    │
  │   _____     _     ___                                              │
  │    ___/    /_\   | _ \   fast AI coding agent  v0.15.19           │
  │   /       / _ \  |  _/                                            │
  │  /_____  /_/ \_\ |_|                                              │
  │                                                                    │
  ├──────────────────────────────────────┬─────────────────────────────┤
  │  model     claude-sonnet-4-6         │  Tips for getting started   │
  │  backend   Anthropic API             │    Tab  ↑↓  autocomplete    │
  │  mode      ask                       │    /          commands      │
  │                                      │    /provider  switch LLM    │
  │  ~/my-project                        │    /help      all commands  │
  ╰──────────────────────────────────────┴─────────────────────────────╯
📺 Featured: "I Found a Better AI Coding Agent (ZAP)" — a video walkthrough by The Curious Guy (@dhanushnehru).
Eradicating Prompt Bloat in AI Coding Agents
Open any popular AI coding agent and inspect the raw request it sends to the LLM. You'll find hundreds — sometimes thousands — of lines of system prompt sent on every single turn, regardless of what you're actually doing.
We measured this. Here's what Gemini CLI and OpenCode send when you ask them to write a Spring Boot service vs. a React component — two completely different languages, frameworks, and conventions:
LLM Token Efficiency Matrix (Spring Boot vs. React Tasks)
| AI Coding Agent | Spring Boot Request | React Request | Identical Base Prompt? | Language Context Injected? |
|---|---|---|---|---|
| Gemini CLI | 4,096 tokens | 4,096 tokens | ✅ Yes | ❌ None (0 mentions of Java/React) |
| OpenCode | 2,003 tokens | 2,003 tokens | ✅ Yes | ❌ None (baseAnthropicCoderPrompt) |
| ZAP (Rust) | 1,889 tokens | 1,661 tokens | ❌ No | ✅ Yes (+650 Java / +422 React tokens) |
Gemini CLI sends the same 4,096-token prompt for both. The word "java" does not appear anywhere in its 68,410-character prompt file. Neither does "react", "kotlin", or any other language. The LLM writing your Spring Boot service and the LLM writing your React component receive identical instructions. (source)
OpenCode uses a single static string constant — baseAnthropicCoderPrompt — sent verbatim on every turn, every task type. Zero mentions of Java, TypeScript, Rust, Python, React, or any specific language. (source)
This isn't just waste. It's why these agents give inconsistent output — the model has no language-specific guidance, so it invents its own conventions turn by turn.
zap sends a different prompt for different tasks — the Java skill fires for Spring Boot, the React skill fires for components — and a greeting costs 12 tokens, not 2,000–4,000.
Full methodology, raw token counts, and source links:
content/evidence/system-prompt-comparison.mdMedium series: Introducing ZAP — The Open-Source AI Coding Agent That Doesn't Bloat Your LLM Context
Context Quality is Supreme
Every design decision in zap follows one principle: every token in the LLM's context window must earn its place. Context that doesn't improve output quality is waste — it dilutes attention, burns budget, and produces inconsistent results.
This principle drives everything:
| Mechanism | What it ensures |
|---|---|
| Skill injection | Only language- and task-specific guidance is sent, not a one-size-fits-all monolith |
| AST code index | The agent knows what exists before it decides what to create — no blind writes |
/init command |
Auto-generates project-specific context files so every session starts informed |
| Context files | ZAP.md, .zap/understanding.md, .zap/context.md, .zap/session_log.md — maintained automatically, loaded on demand |
| Casual-turn detection | Greetings cost ~31 tokens, not 2,000–4,000 |
| Lazy MCP | Server tool schemas stay out of context until the model explicitly connects them |
| Token-cost display | Every turn shows exactly what went into context — skills, message, system, and estimated $ |
What gets updated and when
zap maintains four project context files, each updated at a specific time to keep the agent current without polluting the context window:
| File | Updated when | What it contains | Loaded when |
|---|---|---|---|
ZAP.md |
/init (manual, once) |
Project overview, build commands, architecture, do-not-touch list | Every session (on-demand) |
.zap/understanding.md |
/init + /understand |
Navigation map + business-domain map | Every session (on-demand) |
.zap/context.md |
End of every session (auto) | Last session: goal, files touched, what's next | Session start (on-demand) |
.zap/session_log.md |
Every session (auto) | History of all past sessions, indexed by date | On request (on-demand) |
These files are never pre-loaded into the context window — the model reads them only when relevant, using read_file. This means a session about fixing a typo doesn't pay the cost of loading the entire project architecture.
The result
- First session:
/initanalyses your repo and bootstraps all project knowledge in ~30 seconds - Run
/understand: One LLM call maps every business domain to the files that own it — the agent navigates straight to the right module with no guessing - Returning sessions: The agent already knows what you were working on, which files changed, and what was left unfinished
- Every turn: Skills inject only what's relevant, the index tells the agent what exists, and casual messages skip the overhead entirely
Real output: /understand run on the zap repo itself
You: /understand
zap: ⚡ Extracting business domain map (one LLM call)…

  ↳ code_map '.'     → 2000 symbols  (6ms)
  ↳ code_map 'src'   → 1356 symbols  (3ms)
  ↳ edit_file '.zap/understanding.md'  ← domain map written
What it wrote into .zap/understanding.md:
## Domain Map

### Business Domains

| Domain                   | Owns                                     | Key entry points                    |
|--------------------------|------------------------------------------|-------------------------------------|
| Agent runtime            | agent_core, cli, main, lib               | authenticate, Session::new          |
| LLM provider integration | llm_client/*, http                       | send, stream                        |
| Tool execution + safety  | tools/*, permission_manager, shell_runner| ToolRegistry::execute               |
| Project context + prompt | context_manager, project, plan_execution | build_system_prompt, handle_user_turn|
| Code intelligence        | code_index/*                             | index_dir, global_callers_of        |
| MCP integration          | mcp                                      | mcp_connect, list_tools             |
| Persistence + memory     | persistence, project                     | init, save_session_context          |
| Skills + workflow        | skill_manager, default_skills/*          | detect_domain_scope                 |
| Remote session sharing   | remote, remote_channel                   | spawn_tunnel, broadcast             |

### Cross-Cutting Concerns
- Error handling: `anyhow::Result` everywhere; tool errors surfaced as text responses
- Logging: `crate::log::write` (file-only, never stdout)
- Config: `Config` struct in src/config.rs, loaded once at startup
- Security: `permission_manager`, `secret_scanner`, `audit` enforce approval and logging

### Dependency Direction
tools → session → agent_core; llm_client ← session only; nothing imports session from tools
Two code_map calls, zero source file reads, one edit_file. The domain map is injected into every future session automatically.
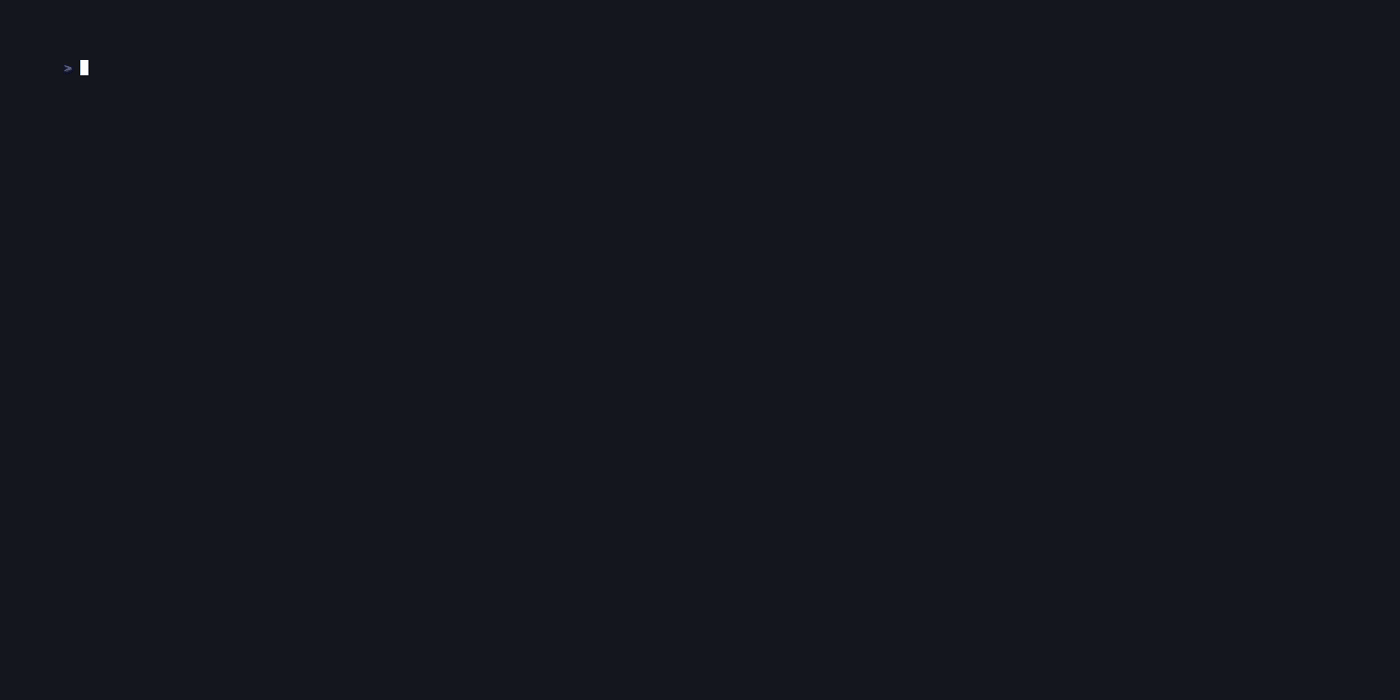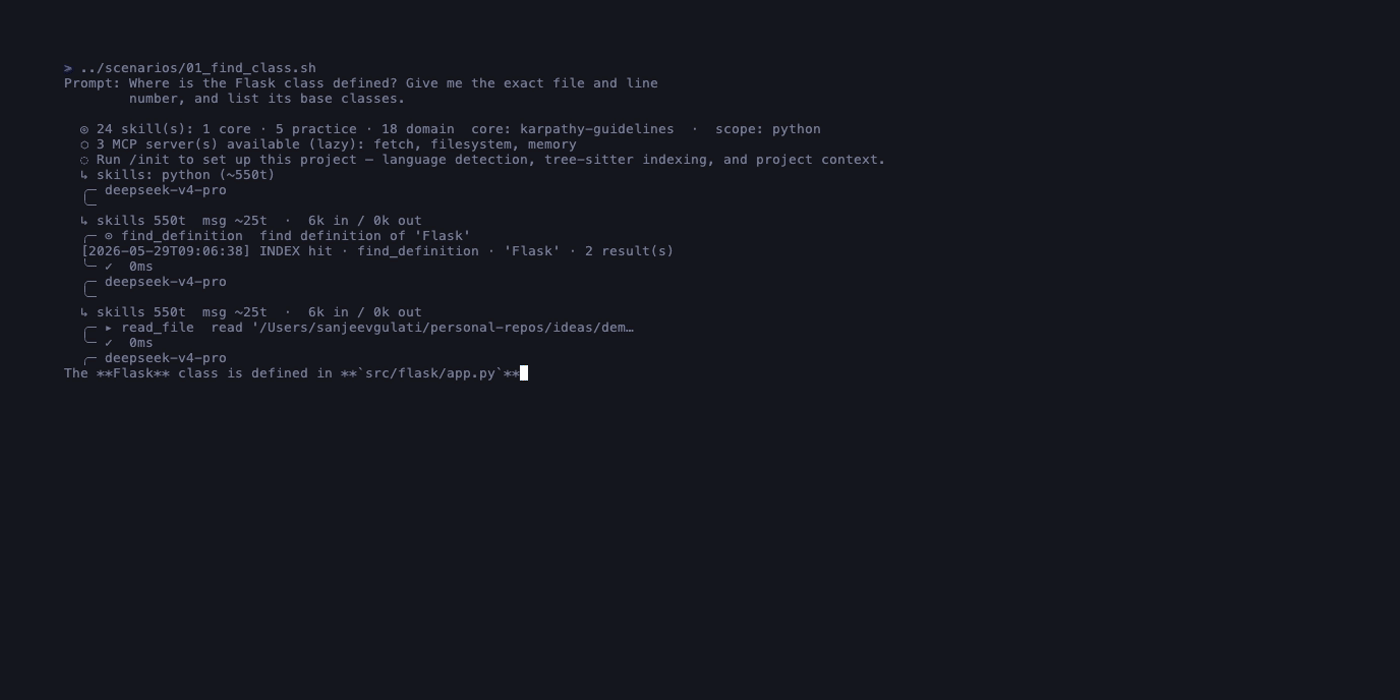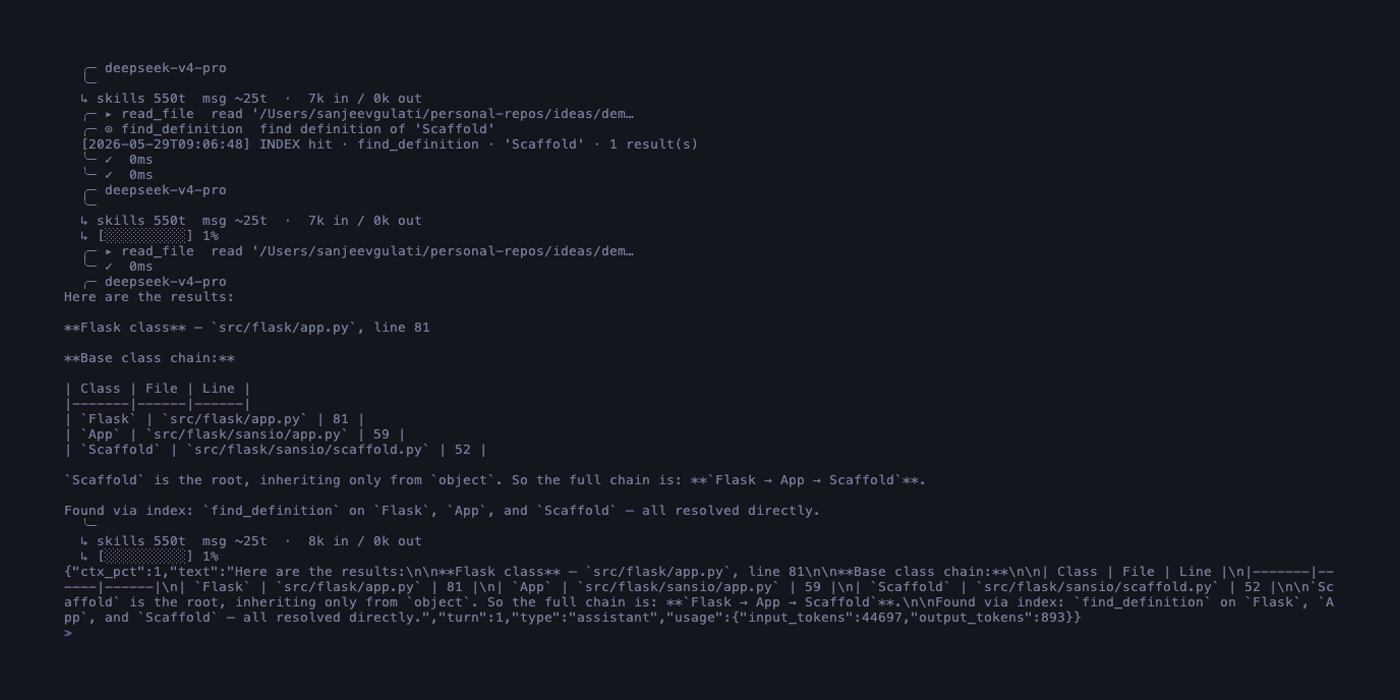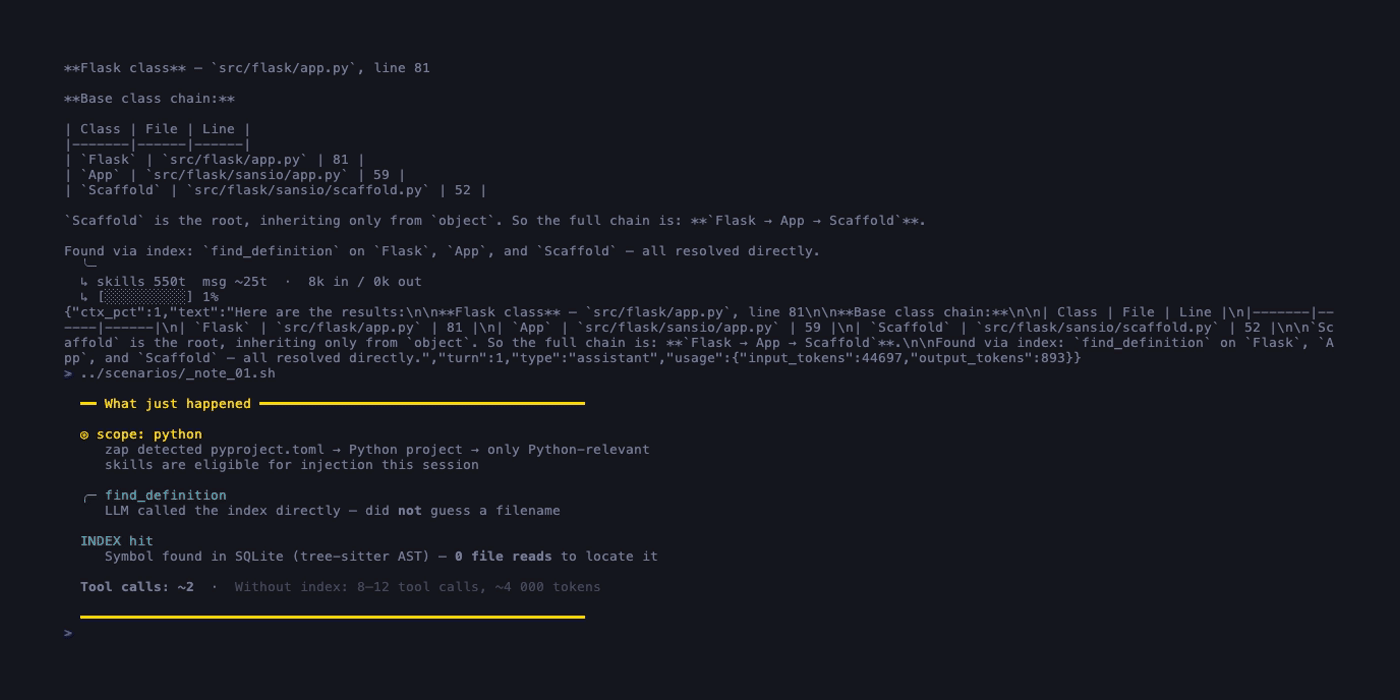
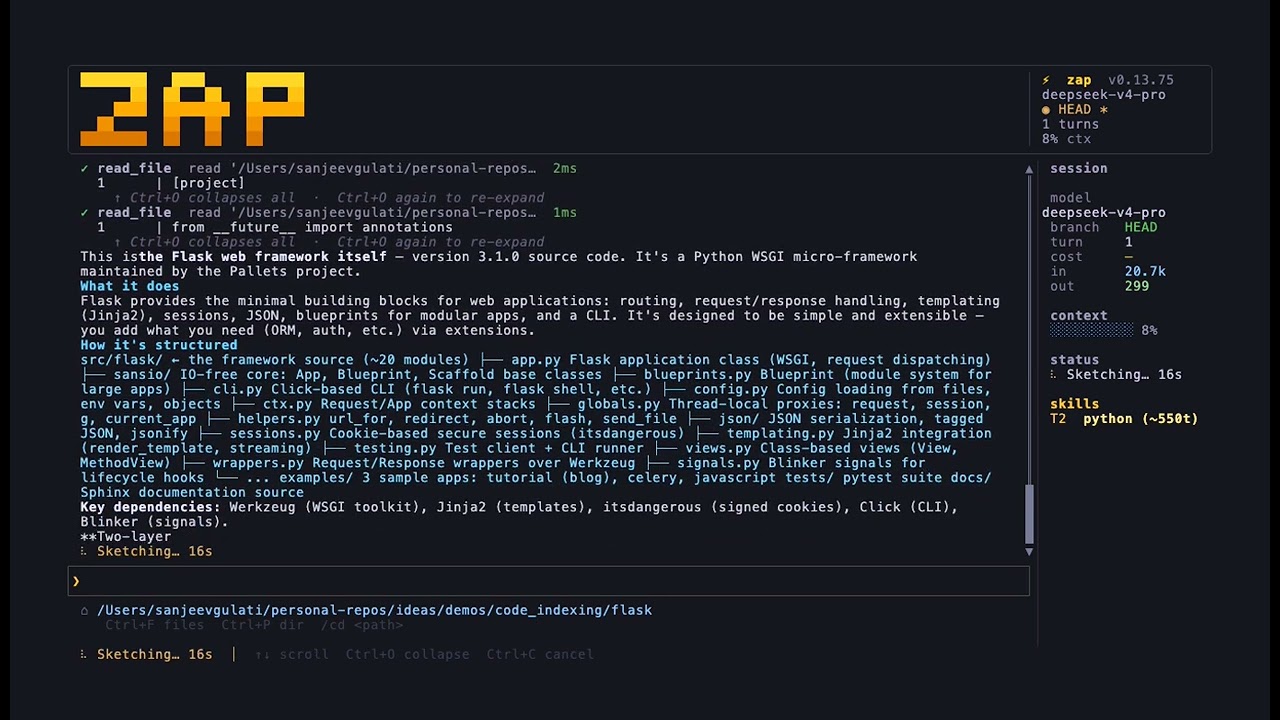
What makes zap different
1. Skill-First Approach — Context That Earns Its Place
Most AI coding agents front-load a massive system prompt every request — language conventions, architecture notes, team rules, API patterns, all of it, whether it's relevant or not. zap replaces that wall with a skill system: markdown files that are injected surgically, only when your message triggers them.
Two kinds of skills:
| Kind | When injected | Example |
|---|---|---|
| Always-on | Every turn, baked into the base system prompt | karpathy-guidelines — Andrej Karpathy's 4 coding principles |
| Triggered | Only when your message matches keywords | rust fires on "cargo", "fn ", "trait "; git fires on "commit", "push" |
Built-in skills (compiled into the binary, zero config):
| Skill | Type | Triggers on |
|---|---|---|
karpathy-guidelines |
always-on | every turn |
rust |
triggered | rust, cargo, crate, async fn, clippy… |
python |
triggered | python, pip, pytest, dataclass… |
typescript |
triggered | typescript, tsx, interface, npm… |
react |
triggered | react, component, jsx, hook, useState… |
go |
triggered | go, goroutine, chan, go.mod… |
git |
triggered | commit, branch, merge, pull request… |
code-review |
triggered | review, pr review, lgtm, critique… |
debugging |
triggered | debug, error, crash, panic, stacktrace… |
security |
triggered | auth, password, token, jwt, xss, sql injection… |
Stack auto-detection fires the right language skill on startup — Rust project with Cargo.toml gets the rust skill loaded automatically.
Example — a Rust project, custom api-conventions skill also loaded:
| You type | Skills injected | Base + skills |
|---|---|---|
"refactor this async fn to use channels" |
karpathy + rust | ~2.4k tokens |
"commit these changes" |
karpathy + git | ~2.0k tokens |
"add a new REST endpoint" |
karpathy + api-conventions | ~2.2k tokens |
"explain what this function does" |
karpathy only | ~1.8k tokens |
Honest baseline: the always-on karpathy-guidelines skill and the base system prompt together run ~1.8k tokens — much leaner than Claude Code (~10k) or Gemini CLI (~8k), but not the "200 token" figure you might see in older docs.
Custom skills override built-in ones of the same name. Write a skill once and zap injects it exactly when needed:
---
name: api-conventions
description: REST endpoint conventions for this project.
trigger: ["endpoint", "route", "handler", "REST"]
tokens: ~400
---
All endpoints must validate input with ValidateRequest(), return structured
errors as {"error": "...", "code": N}, and use snake_case JSON keys.
Always-on skill (no trigger: field — injected every turn):
---
name: our-principles
description: Team engineering principles.
---
We ship small, reversible changes. Every PR needs a test. No console.log in prod.
Where to put them:
| Path | Scope | Priority |
|---|---|---|
.zap/skills/ |
project — check into git, team-shared | highest |
~/.zap/skills/ |
personal — all projects | middle |
| binary | built-in defaults | lowest |
On first launch zap writes all built-in skills to ~/.zap/skills/ automatically — open any file there to read or edit it. Same-name files you create override the built-in version on the next run.
/skill list              # see all skills with source and always-on/triggered label
/skill show <name>       # preview content + description + license
/skill export <name>     # re-export a built-in to ~/.zap/skills/ (if you deleted it)
/skill export --all      # re-export every built-in skill
/skill create <name>     # scaffold a new skill in .zap/skills/
/skill capture <name>    # extract instructions from this session into a reusable skill
2. AST-Powered Code Indexing vs. Agentic Search
Most agents navigate code the same way a shell script does — grep for a string, hope the result is what you meant. zap builds a real AST symbol index at startup using tree-sitter + SQLite, giving the model genuine structural understanding of your codebase.
The problem: agents that write without looking
Ask most coding agents to "add all the API layers for user management" in an existing project and you'll see a predictable set of mistakes:
- Duplicate files created —
src/user_repository.rsalready exists, but the agent createssrc/repositories/user_repo.rsalongside it because it never checked - Existing patterns ignored — the project uses a
Repository<T>trait with a specific error type; the agent invents its own DB access style from scratch - Scaffolding over existing code —
src/routes/,src/models/,src/db/already exist with boilerplate; the agent recreates them - Missed abstractions — a
BaseRepositoryor sharedAppErrortype already exists; the agent writes a duplicate
These aren't model failures — they're context failures. The agent is writing blind because its context window never contained the files it needed to check.
How the index fixes it
When you ask zap the same question, before writing a single line it queries the index:
-- Does a user repository already exist?
SELECT path, line, kind FROM symbols WHERE name LIKE '%UserRepo%' OR name LIKE '%UserStore%';

-- What repository pattern does this project use?
SELECT name, path, line, signature FROM symbols WHERE kind = 'trait' AND name LIKE '%Repository%';

-- What's already in the db/ directory?
SELECT name, kind, line FROM symbols WHERE path LIKE '%/db/%' ORDER BY path, line;
This runs in milliseconds against the local SQLite index — no file reads, no grep, no context stuffing. The model knows what exists before it decides what to create. It adds to src/user_repository.rs instead of creating a new one. It implements the existing Repository<T> trait instead of inventing a new pattern.
When you ask zap to "refactor the UserStore struct", it doesn't search for the string "UserStore" — it looks up the symbol in the index, finds the exact file and line number, reads only that section, and makes a precise edit. No false matches, no reading entire files to find one function.
The index is incremental — on subsequent runs, only files that changed since the last session are re-parsed. A background indexer runs every 120s during interactive sessions so the index stays fresh as you edit. Cold-indexing a 50k-line repo takes a few seconds; warm starts are near-instant.
Always current during edits — every time zap writes a file, it immediately reindexes that file before the next LLM turn. The model never queries a stale index for files it just changed.
Index usage is logged per turn — every time a tool call is answered by the index (rather than falling back to grep), zap logs it to ~/.zap/zap.log and ~/.zap/audit.jsonl:
[INDEX] hit · find_definition · 'UserRepository' · 3 result(s)
[INDEX] hit · code_map · 'src/db/' · 42 symbol(s)
[INDEX] miss · find_definition · 'legacy_fn' · grep fallback
This makes it auditable — you can see exactly when the index was used vs. when the agent had to fall back to text search.
Supported languages: Rust, Python, TypeScript, JavaScript, Go, Java
Powered tools:
| Tool | What it does |
|---|---|
code_map |
Structural outline of any file or directory — functions, structs, classes, enums, with line numbers |
find_definition |
Jump directly to where a symbol is defined — AST index first, ripgrep fallback |
find_references |
Every call site of a symbol across the entire codebase |
who_calls |
All callers of a function, optionally filtered by qualifier |
file_imports |
Everything a file imports |
where_imported |
Every file that imports a given name — blast radius for renames |
find_subtypes / find_supertypes |
Type hierarchy traversal |
pack_context |
Auto-selects the most load-bearing files for a task and returns them in a token budget |
ripple_analysis |
BFS blast radius: who calls a symbol, who calls those callers, and so on — instant, no compiler |
get_diagnostics |
Compiler errors/warnings via language server — same as cargo check without running it |
lsp_definition |
Type-resolved go-to-definition for cross-crate symbols (std, deps, generics) |
lsp_type_at |
Exact inferred type of any expression — the tooltip your editor shows, in the agent |
The model is instructed to always use code_map or find_definition before reaching for read_file — so it reads only the lines it actually needs, not whole files.
How the index powers every LLM turn:
You: "refactor the UserStore struct"

  zap (tool call)  →  find_definition("UserStore")
  SQLite index     →  src/db/user_store.rs:42  ← instant, no file scan
  zap (tool call)  →  read_file("src/db/user_store.rs", offset=40, limit=60)
  zap (tool call)  →  edit_file(...)            ← precise edit, right lines

Without index: grep entire repo → read 3 wrong files → hallucinate location
With index:    SQLite lookup → read 20 lines → done
Blast radius before you touch anything:
You: "what breaks if I change the signature of parse_config?"

  zap (tool call)  →  ripple_analysis("parse_config", depth=3)
  call graph BFS   →  Depth 1 — 4 direct callers across 3 files
                       Depth 2 — 11 callers of callers across 6 files
                       Depth 3 — 2 more files indirectly affected
  zap              →  "Here's what's at risk — want me to check each caller?"
Compiler errors without running cargo check:
You: "check if my edit to src/lsp/client.rs is correct"

  zap (tool call)  →  get_diagnostics("src/lsp/client.rs")
  rust-analyzer    →  src/lsp/client.rs:47 error[E0308]: mismatched types
  zap              →  "Line 47 has a type mismatch — here's the fix..."
Code quality report — the same SQLite index powers /index quality, a human-readable health report run directly in the TUI:
Code Health  ·  27 files  ·  1043 symbols  ·  ⚡ 74/100
────────────────────────────────────────────────────────────

File sizes  (lines)
────────────────────────────────────────────────────────────
  ⚠ 2382  src/session/commands.rs    ████████████████████  37 sym
  ⚠ 2266  src/tui/render.rs          ████████████████████  48 sym
  ⚠ 1789  src/session/mod.rs         █████████████         45 sym
  ⚡ 1177  src/tui/mod.rs             ████████
  ·   527  src/tui/app.rs             ███
  ·   312  src/code_index.rs          ██

  ⚠ >1000 lines   ⚡ 500–1000   · healthy

God objects  (>15 methods — split candidates)
────────────────────────────────────────────────────────────
  Session                        45 methods  (mod.rs)
  ToolRegistry                   18 methods  (tool_registry.rs)

Dead code candidates  (pub fn, ≤1 reference)
────────────────────────────────────────────────────────────
  export_skill                   (skill_manager.rs:599)
Explore the index yourself
The index is a plain SQLite database at .zap/code.db — you can query it directly at any time, no zap session required.
macOS / Linux — interactive explorer script:
./scripts/explore-db.sh
Launches an interactive menu with 10 ready-made queries (overview, top files by symbol count, search by name, raw SQL, and more). Requires only sqlite3, which ships with macOS. On Linux: sudo apt install sqlite3.
Why zap indexes when Claude Code deliberately doesn't
Claude Code (Anthropic's own CLI) has no built-in code indexing. No tree-sitter, no SQLite, no ctags. It uses pure agentic search — grep + glob + read, chosen at runtime by the model. This was a deliberate, tested decision.
Boris Cherny (Claude Code's creator) confirmed publicly that Anthropic built and benchmarked a RAG/vector-index approach early on and dropped it because agentic search won "by a lot." The reasons:
- Grep finds exact matches; embeddings introduce false positives
- No index to build or maintain
- Index drift — code changes constantly during editing sessions
- Simpler architecture with fewer failure modes
Sources: Claude Code Doesn't Index Your Codebase — vadim.blog · Building Claude Code with Boris Cherny — Pragmatic Engineer · Official Claude Code docs
The community has noticed the gap — multiple open-source MCP servers exist to bolt indexing onto Claude Code:
- colbymchenry/codegraph — tree-sitter + SQLite FTS5
- cocoindex-io/cocoindex-code — AST-based search
- zilliztech/claude-context — vector search MCP
And open feature requests asking Anthropic to add this natively: #4556 · #9277
zap makes the opposite bet. Agentic search solves semantic questions well ("find code related to payment processing"). A persistent AST index solves structural questions better — "what already exists in this module?", "which files implement this pattern?", "is there already a UserRepository?" These are exactly the questions that matter when an agent is about to write new code. Without an index, the agent can only search for what it knows to look for. With an index, it knows what exists before it decides what to create.
The two approaches solve different failure modes. Agentic search avoids index drift. AST indexing avoids blind writes into a codebase the agent hasn't fully read.
Вопросы о Zap Coding Agent MCP
Какие инструменты предоставляет Zap Coding Agent MCP?
Он предоставляет 26 инструментов, включая read_file, edit_file, batch_edit, write_file, undo_edit.
Как Zap снижает расход токенов?
Он использует систему навыков, при которой в промпт внедряются только инструкции, специфичные для конкретного языка или задачи, вместо того чтобы каждый раз отправлять огромный статический системный промпт.
Для чего нужна команда /init?
Команда /init анализирует ваш репозиторий и за около 30 секунд загружает все знания о проекте в специальные файлы контекста.