
MCP server Kappa Graph
Коммит 2 окт. 2026 г.Позволяет ИИ-ассистентам искать информацию в семантическом графе знаний, изучать связи между концепциями и проверять степень обоснованности утверждений.
Также известен как aaronsb/knowledge-graph-system
- Звёзды
- 131
- Инструменты
- —
- Загрузки, 30 дней
- —
- Последняя версия
- —
- Последний коммит
- 2 окт. 2026 г.
- Лицензия
- Apache-2.0
Что такое Kappa Graph MCP?
Kappa Graph — это MCP server. Позволяет ИИ-ассистентам искать информацию в семантическом графе знаний, изучать связи между концепциями и проверять степень обоснованности утверждений.
Сводка сгенерирована из README проекта
О Kappa Graph MCP server
Исследователи и разработчики могут использовать эту систему для создания семантической памяти, которая понимает не только наличие информации, но и степень её обоснованности. Интегрируя MCP server с такими ИИ-ассистентами, как Claude, пользователи могут наделить своих агентов способностью искать в графе знаний, изучать сложные связи между концепциями и проверять уровень уверенности в конкретных утверждениях. Это позволяет ИИ отличать хорошо подтвержденные факты от спорных идей.
Платформа функционирует как локальный или удаленный бэкенд на базе PostgreSQL и Apache AGE, поддерживая загрузку документов из PDF, markdown и изображений. Она предоставляет несколько способов взаимодействия с данными, включая TypeScript CLI, веб-инструмент визуализации и файловую систему FUSE, которая позволяет перемещаться по семантическому пространству с помощью стандартных команд Unix, таких как ls или grep. Для тех, кто уделяет приоритетное внимание конфиденциальности, система поддерживает работу в изолированном режиме через Ollama для локального вывода.
Что вы можете с ним делать
- 1Синтез сложных исследованийИИ может обрабатывать множество научных работ, чтобы находить связи и выявлять моменты, в которых разные авторы расходятся во мнениях.
- 2Обеспечение постоянной памяти агентовРазработчики могут предоставить ИИ-ассистентам обоснованную память, которая позволит им проверять уровни уверенности перед тем, как делать какие-либо утверждения.
- 3Управление технической документациейПользователи могут извлекать архитектурные концепции и делать по ним запросы из проектной документации и протоколов встреч.
- 4Аудит происхождения информацииКоманды по комплаенсу могут использовать систему для отслеживания каждой извлеченной концепции до её исходного доказательства.
Взято из README проекта. Каждый вариант использования проверен на соответствие цитате из него.
Автоматические проверки
Запущено 14 нояб. 2026 г.Полный отчёт →Еще не проверено. Для сервера требуется оценка 80, отсутствие серьезных проблем и достаточно данных для нашей проверки. Как работают проверки · Что исправить, чтобы получить больше баллов

- Связанный и доступный исходный репозиторийaaronsb/knowledge-graph-system is public and reachablegithub.com/aaronsb/knowledge-graph-system ↗Пройдено
- Пакет указывает этот репозиторий как источникНе проверялось
- Происхождение сборки (аттестация Sigstore)Не проверялось
- Open source лицензия (OSI)Apache-2.0spdx.org/licenses/Apache-2.0.html ↗Пройдено
- Коммит или релиз за последний годLast commit or release 2026-10-02github.com/aaronsb/knowledge-graph-system ↗Пройдено
- OpenSSF ScorecardНе проверялось
- Имя пакета не похоже на популярный пакетНе проверялось
- Нет критических предупреждений в пакете или его зависимостяхНе проверялось
- Нет скрытых инструкций для модели0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersПройдено
- Деструктивные инструменты помеченыНе проверялось
- Удалённая конечная точка отвечает на рукопожатие MCPНе проверялось
README
Открыть на GitHubKappa Graph — κ(G)


A semantic knowledge graph that extracts concepts from documents, tracks how well-supported they are, and remembers where sources disagree.
κ(G) — vertex connectivity of a graph. The minimum number of connections you'd need to cut before the graph falls apart. A measure of how robust the structure is.
Also kg — the unit of mass. Because knowledge here has weight. Grounding scores measure how heavy an idea is: well-evidenced claims carry more than thin ones. Contested concepts weigh differently than unchallenged ones.
Quick Start
Install Client Tools
The kg CLI, MCP server (for AI assistants), and optional FUSE filesystem:
curl -fsSL https://raw.githubusercontent.com/aaronsb/knowledge-graph-system/main/client-manager.sh | bash
Or just the CLI: npm install -g @aaronsb/kg-cli
Deploy the Platform
Run your own knowledge graph backend:
curl -fsSL https://raw.githubusercontent.com/aaronsb/knowledge-graph-system/main/install.sh | bash
Or from source:
git clone https://github.com/aaronsb/knowledge-graph-system.git
cd knowledge-graph-system
./operator.sh init    # Interactive setup
./operator.sh start   # Start containers
See Quick Start Guide for details.
See It In Action
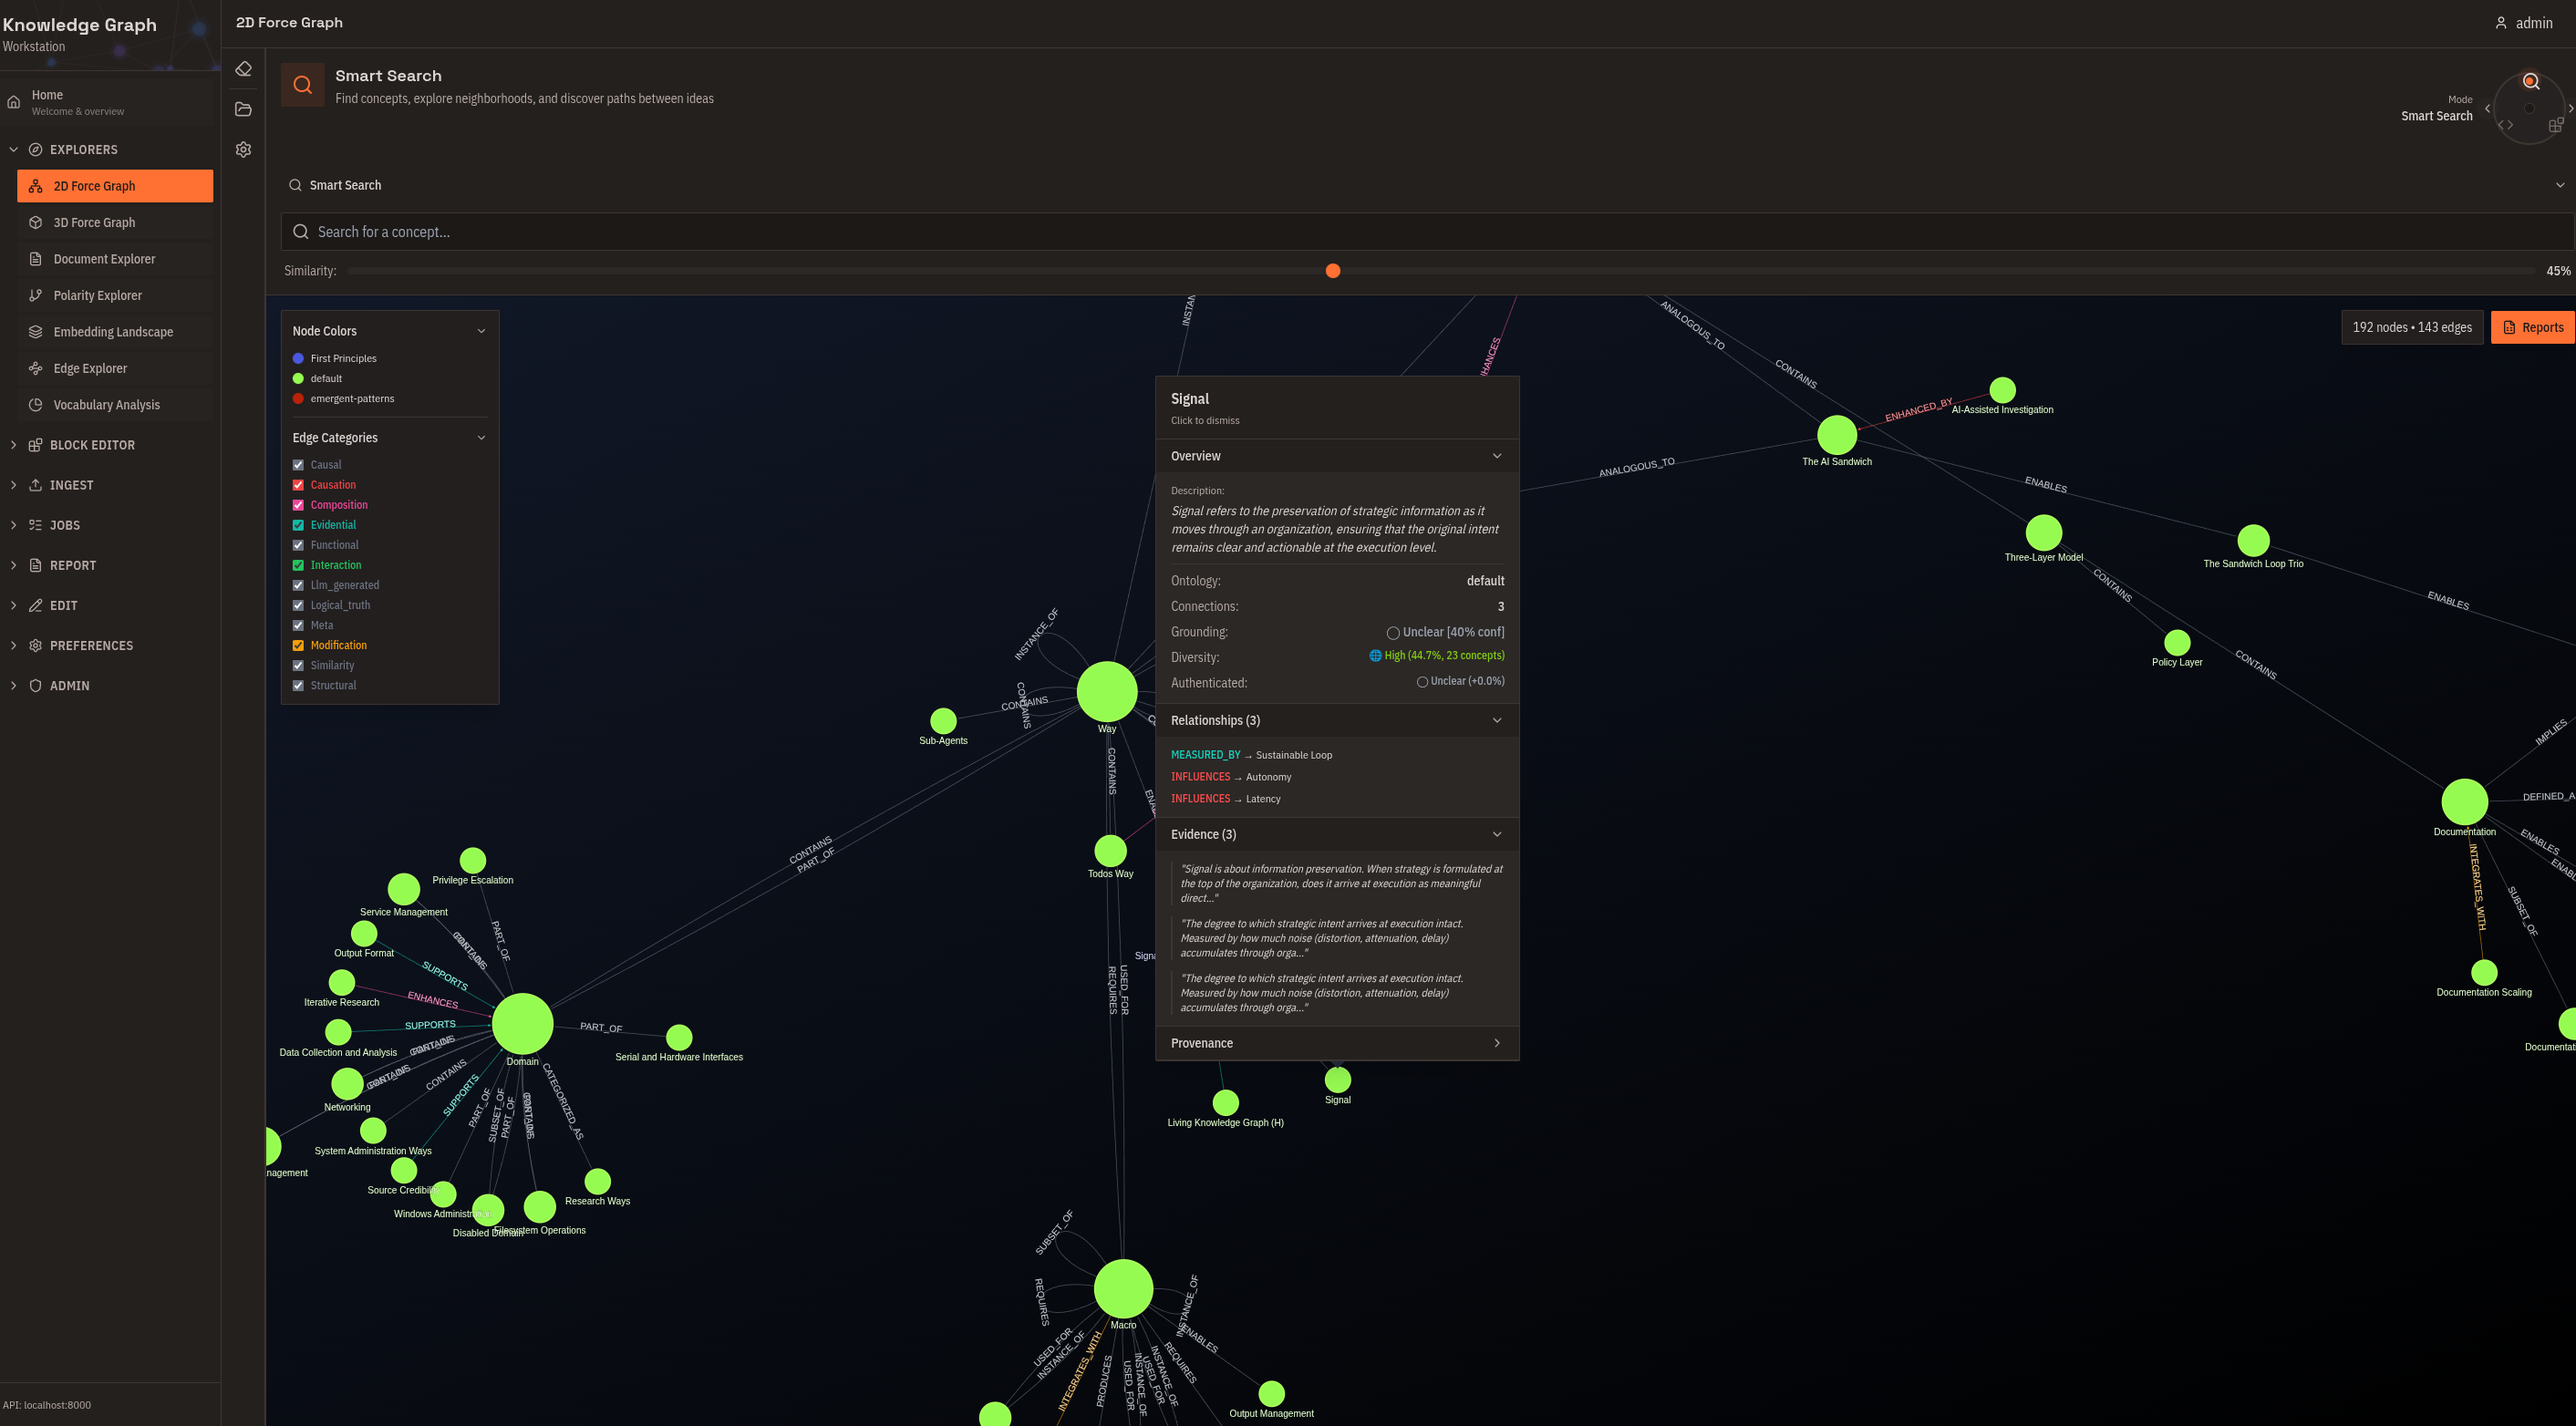
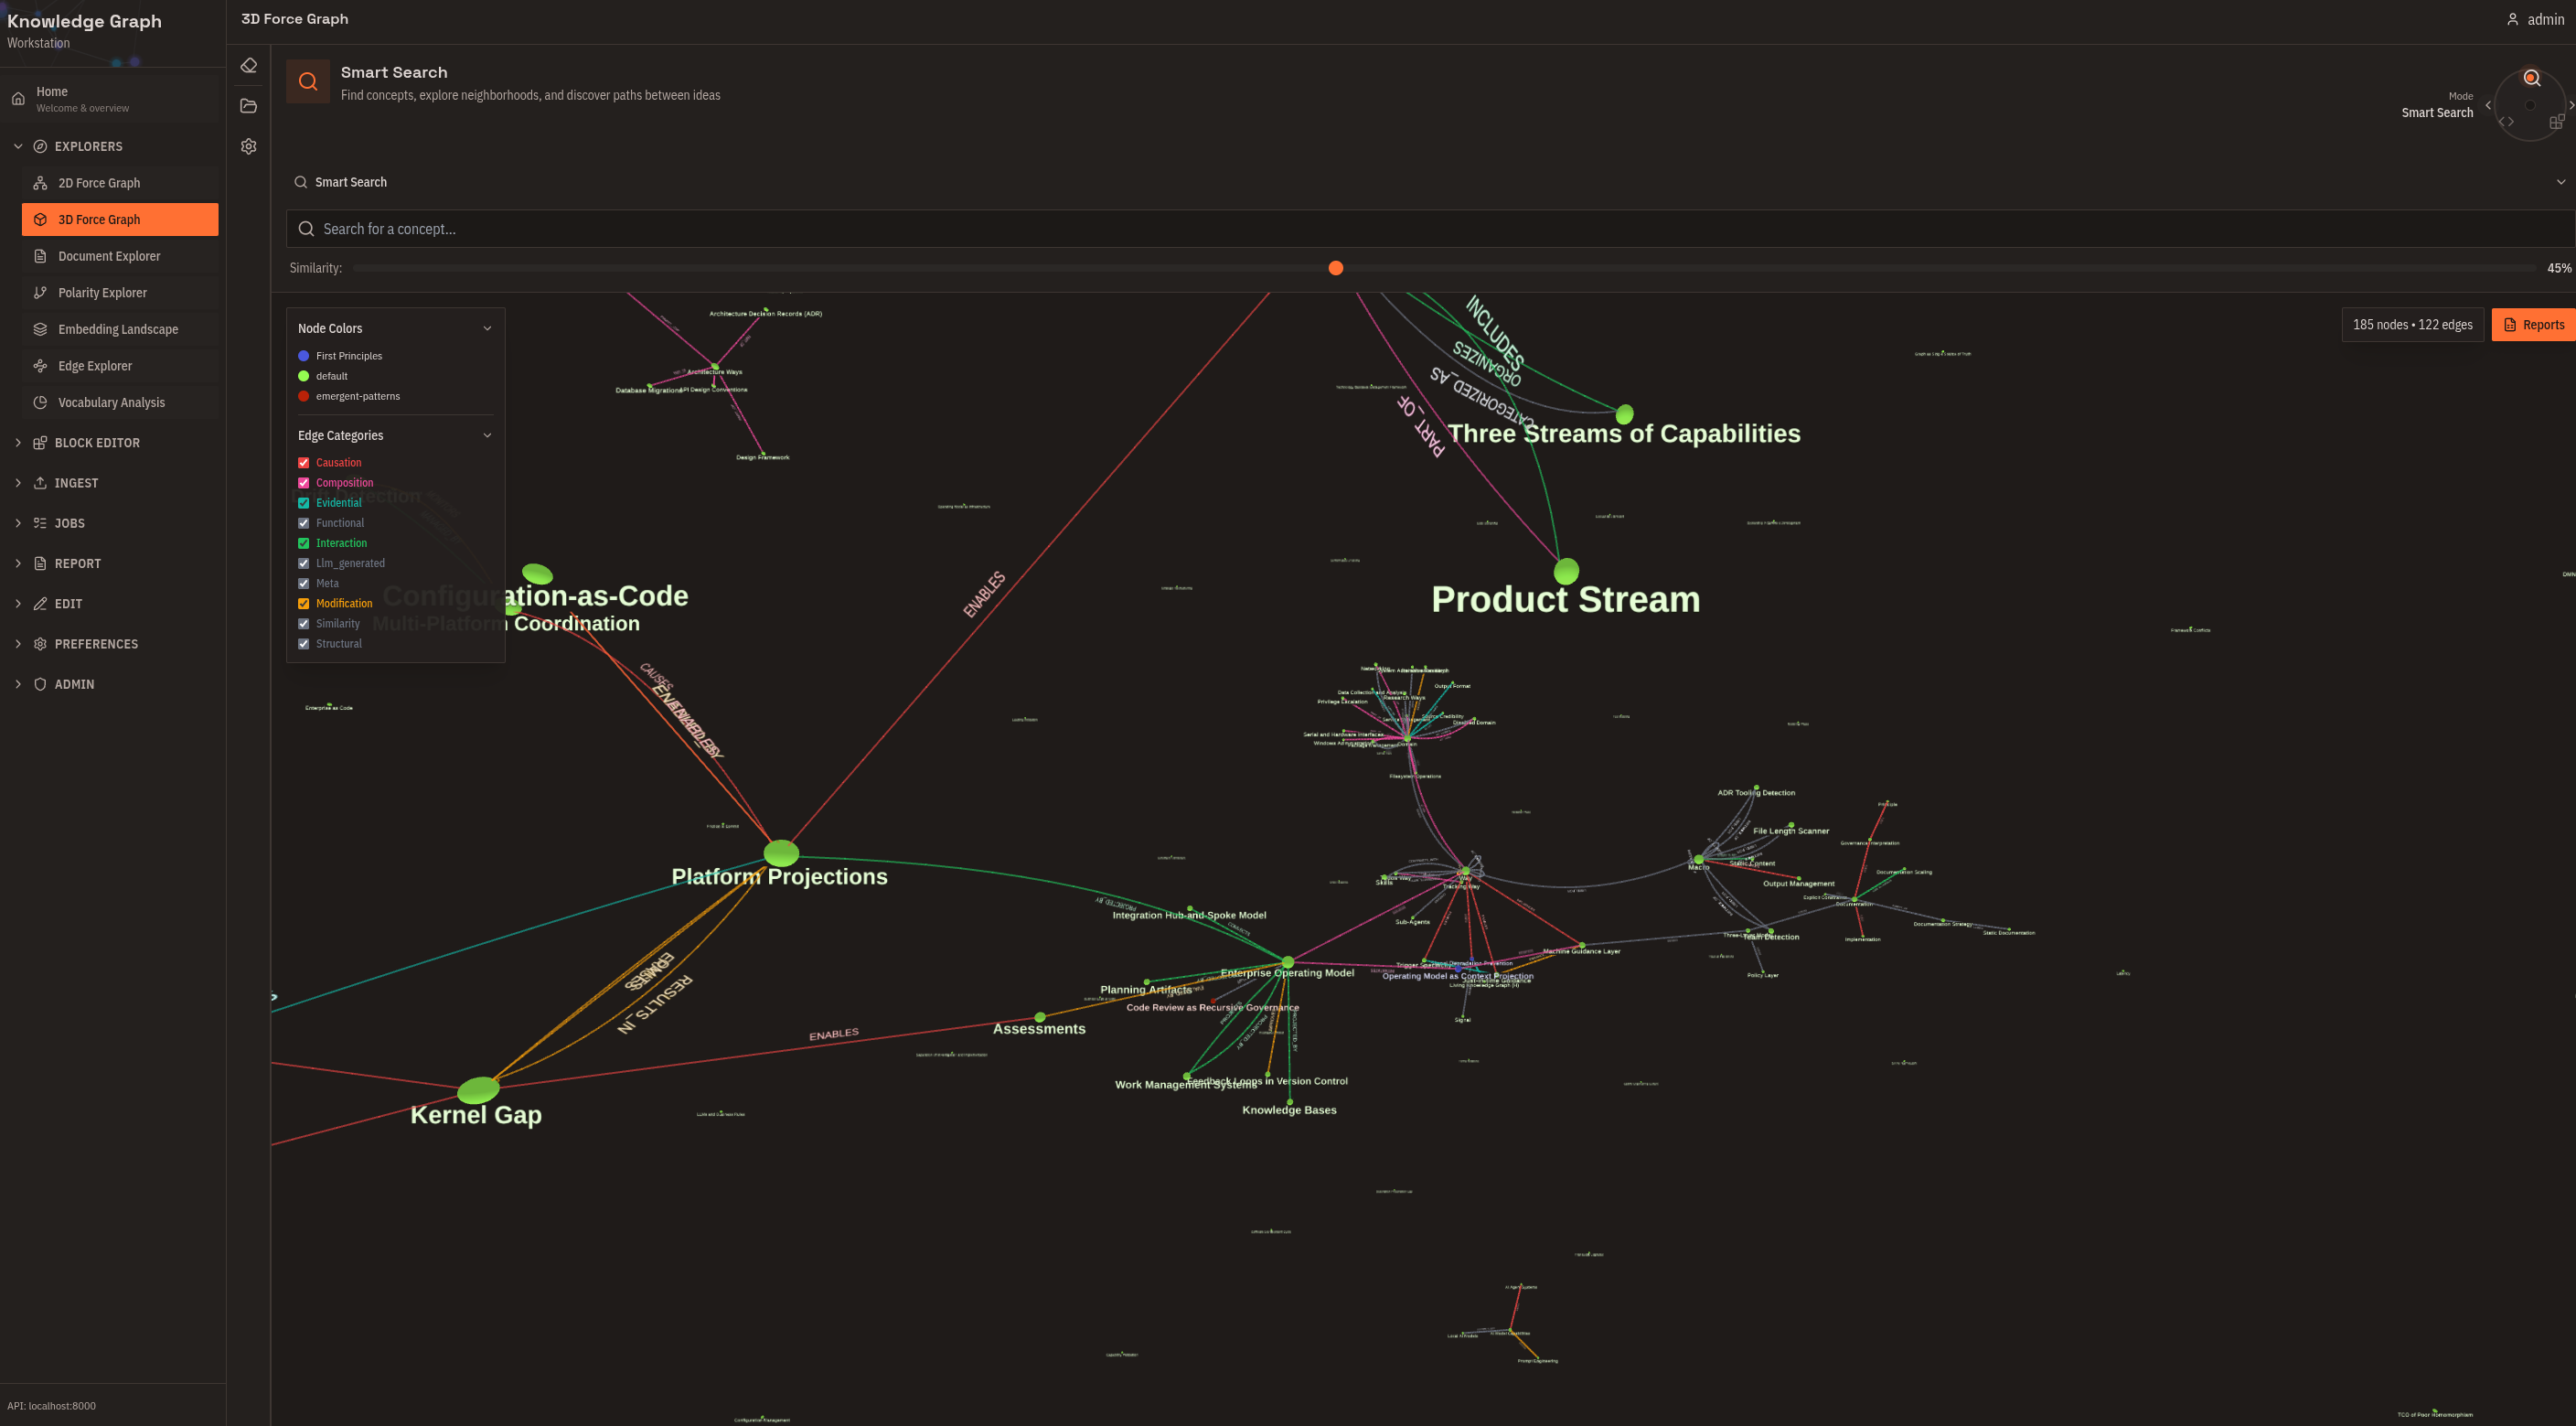 Interactive graph exploration with smart search, concept clustering, and relationship visualization
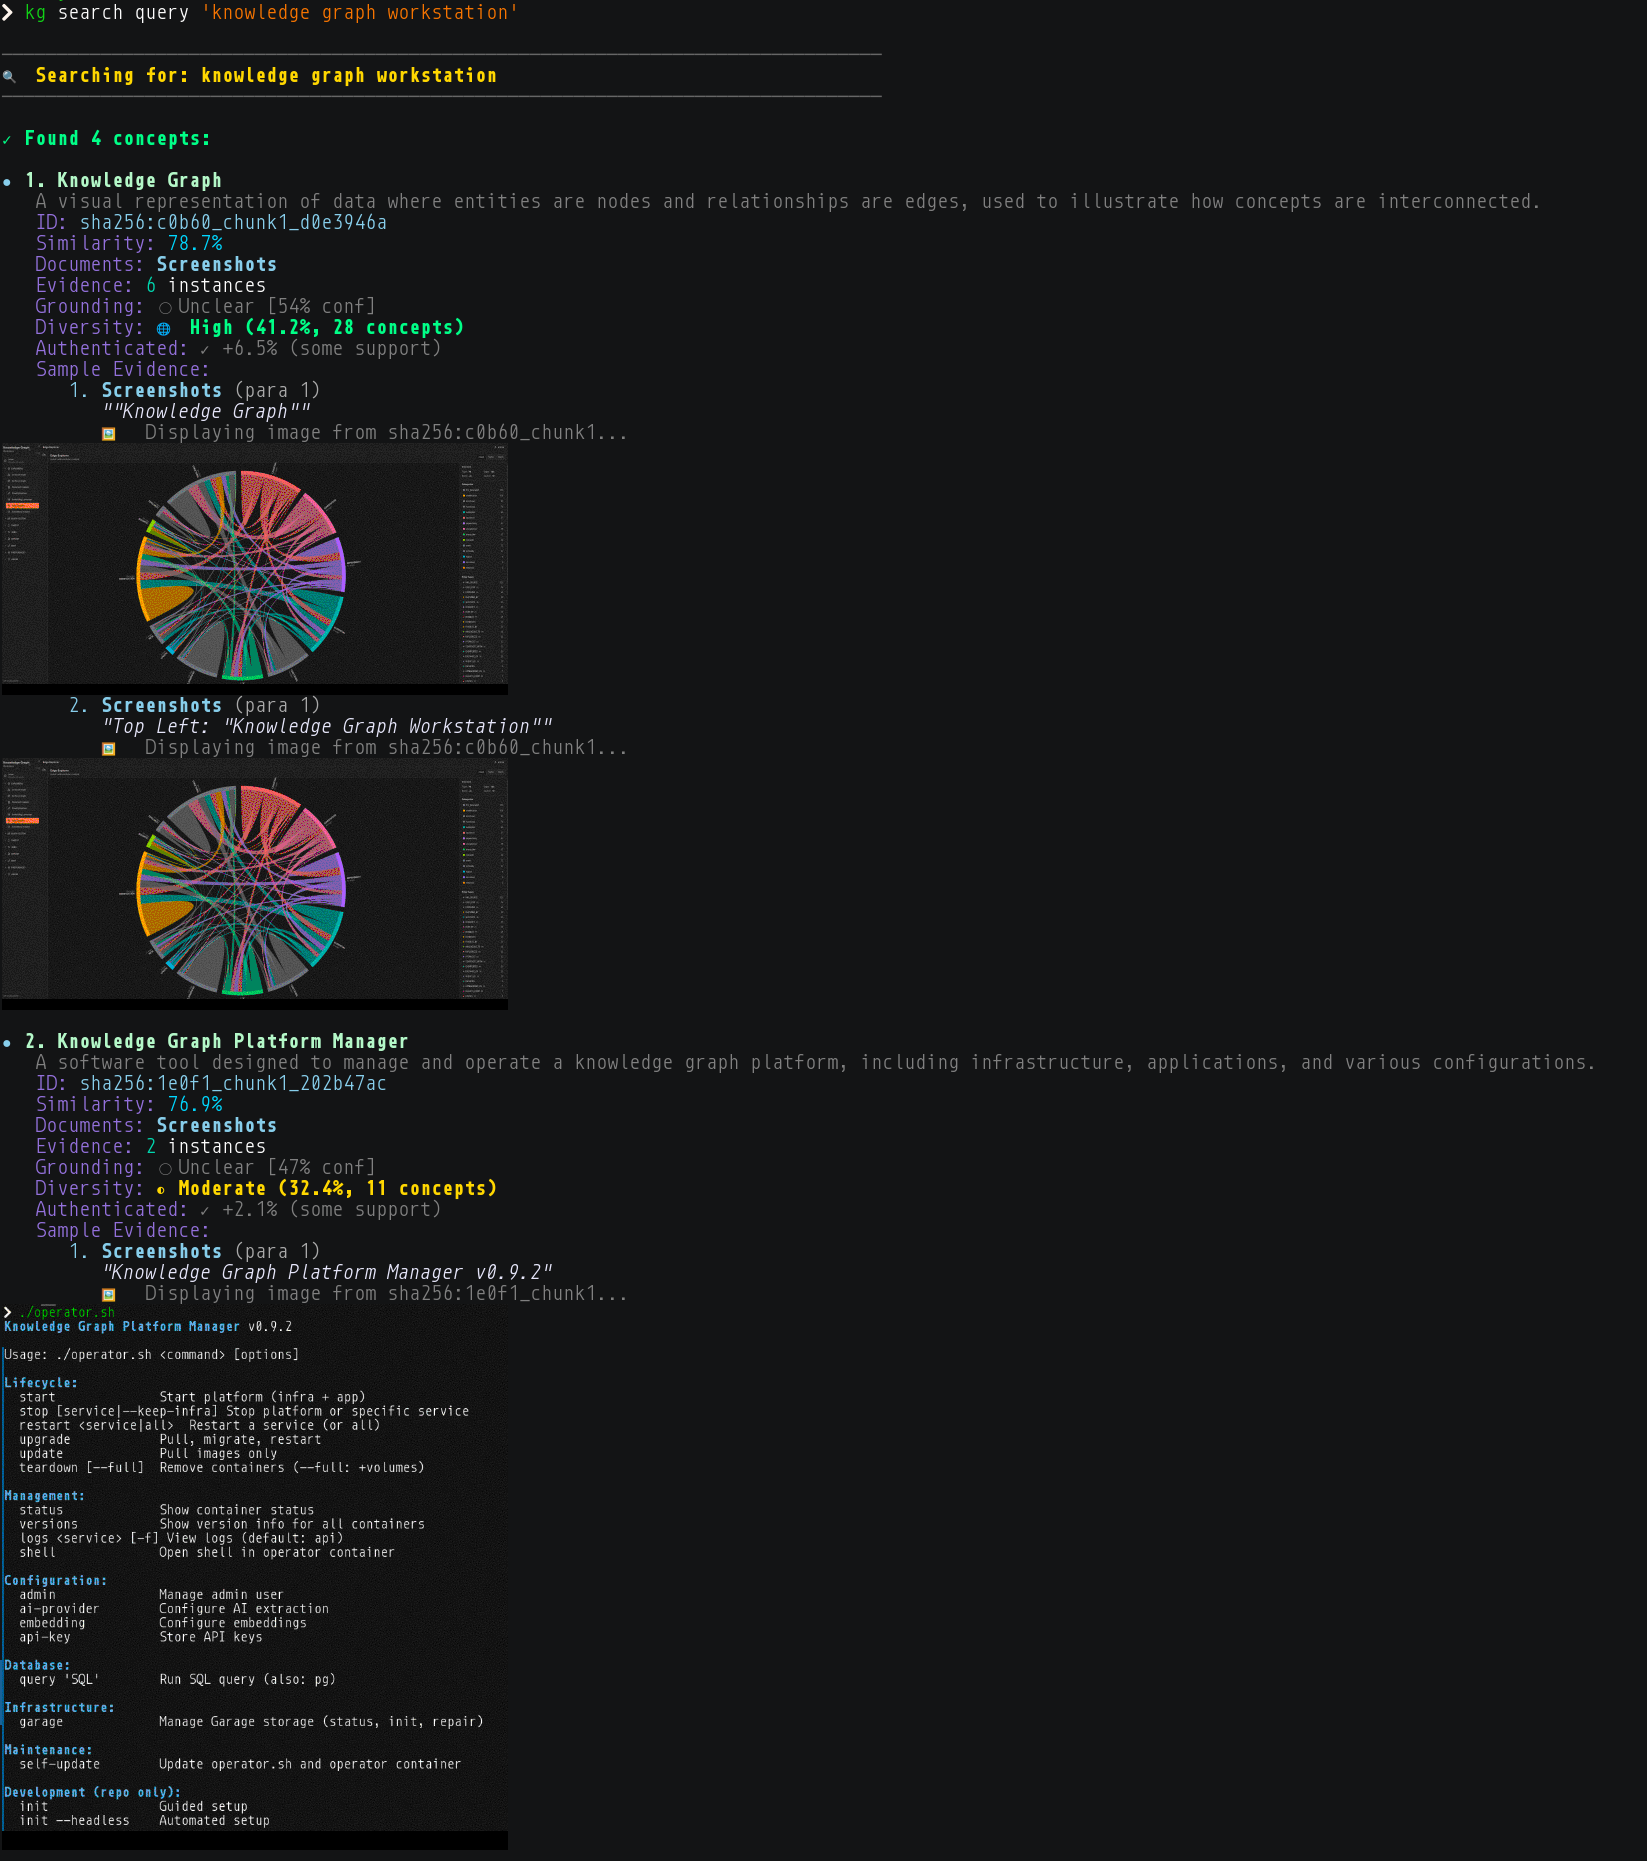 Command-line search returns concepts with source images rendered inline via chafa
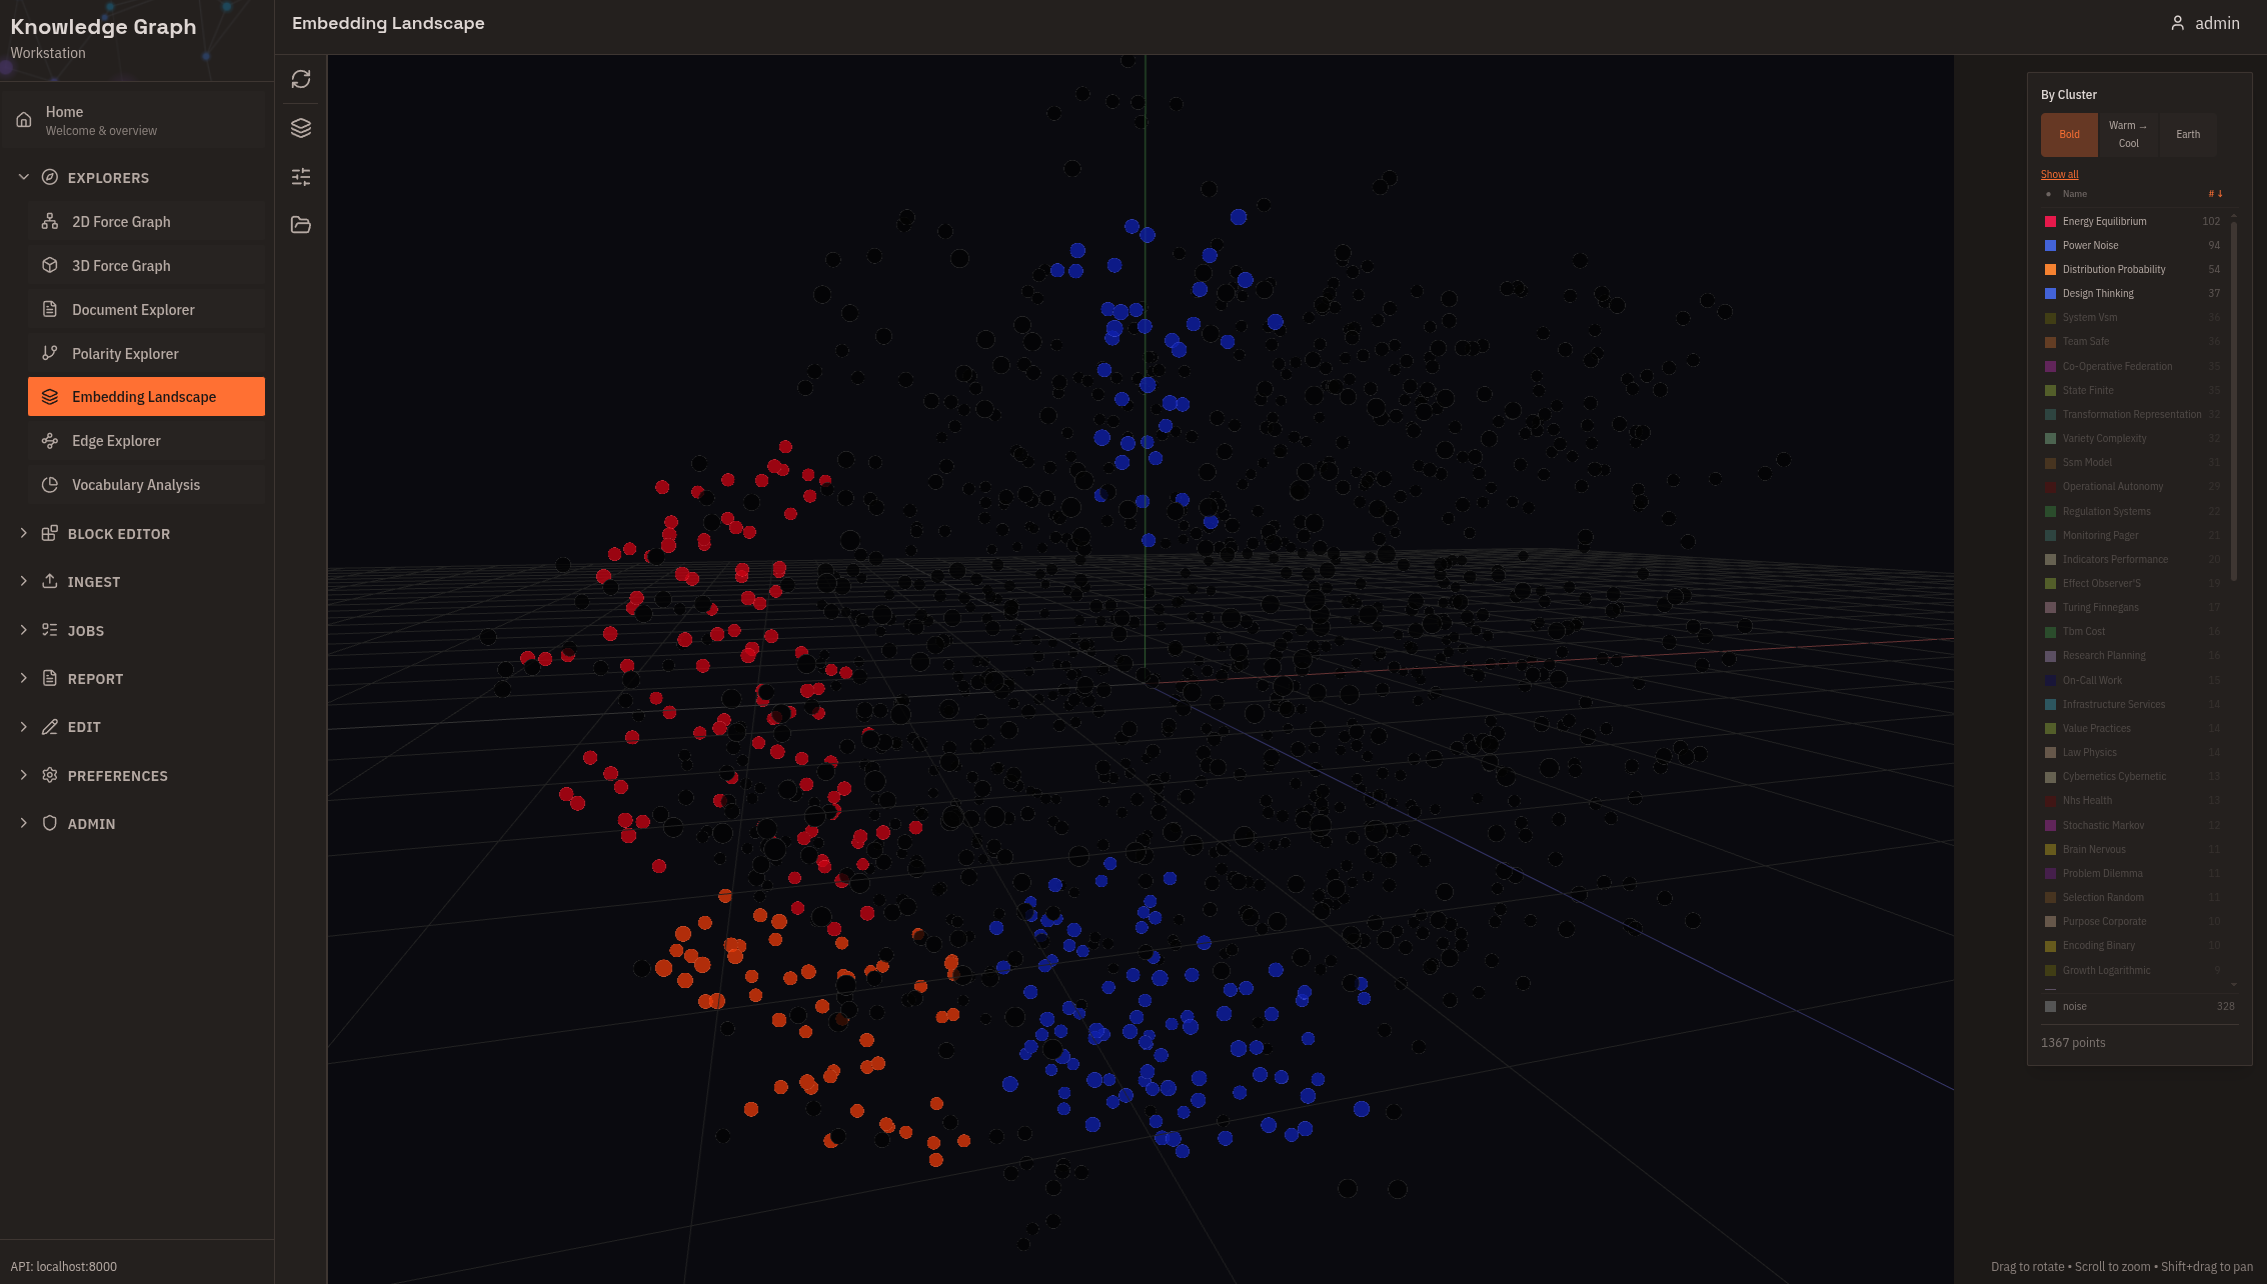 t-SNE embedding landscape with auto-detected clusters, named by topic via TF-IDF
What You Can Do
Ingest documents — PDFs, markdown, images, text. The system extracts concepts, relationships, and evidence automatically.
Search by meaning — "economic downturn" finds content about recessions, crashes, and crises even if those exact words aren't used.
Explore connections — Find paths between concepts. See how ideas relate across documents.
Check confidence — Every result includes grounding scores. Know what's well-supported vs. contested.
Trace sources — Every concept links back to the original text or image that generated it.
Query via AI — MCP server integration lets Claude and other assistants use the graph as persistent memory.
Navigate via filesystem — Mount the graph as a FUSE filesystem. Use ls, grep, find on semantic space.
Use Cases
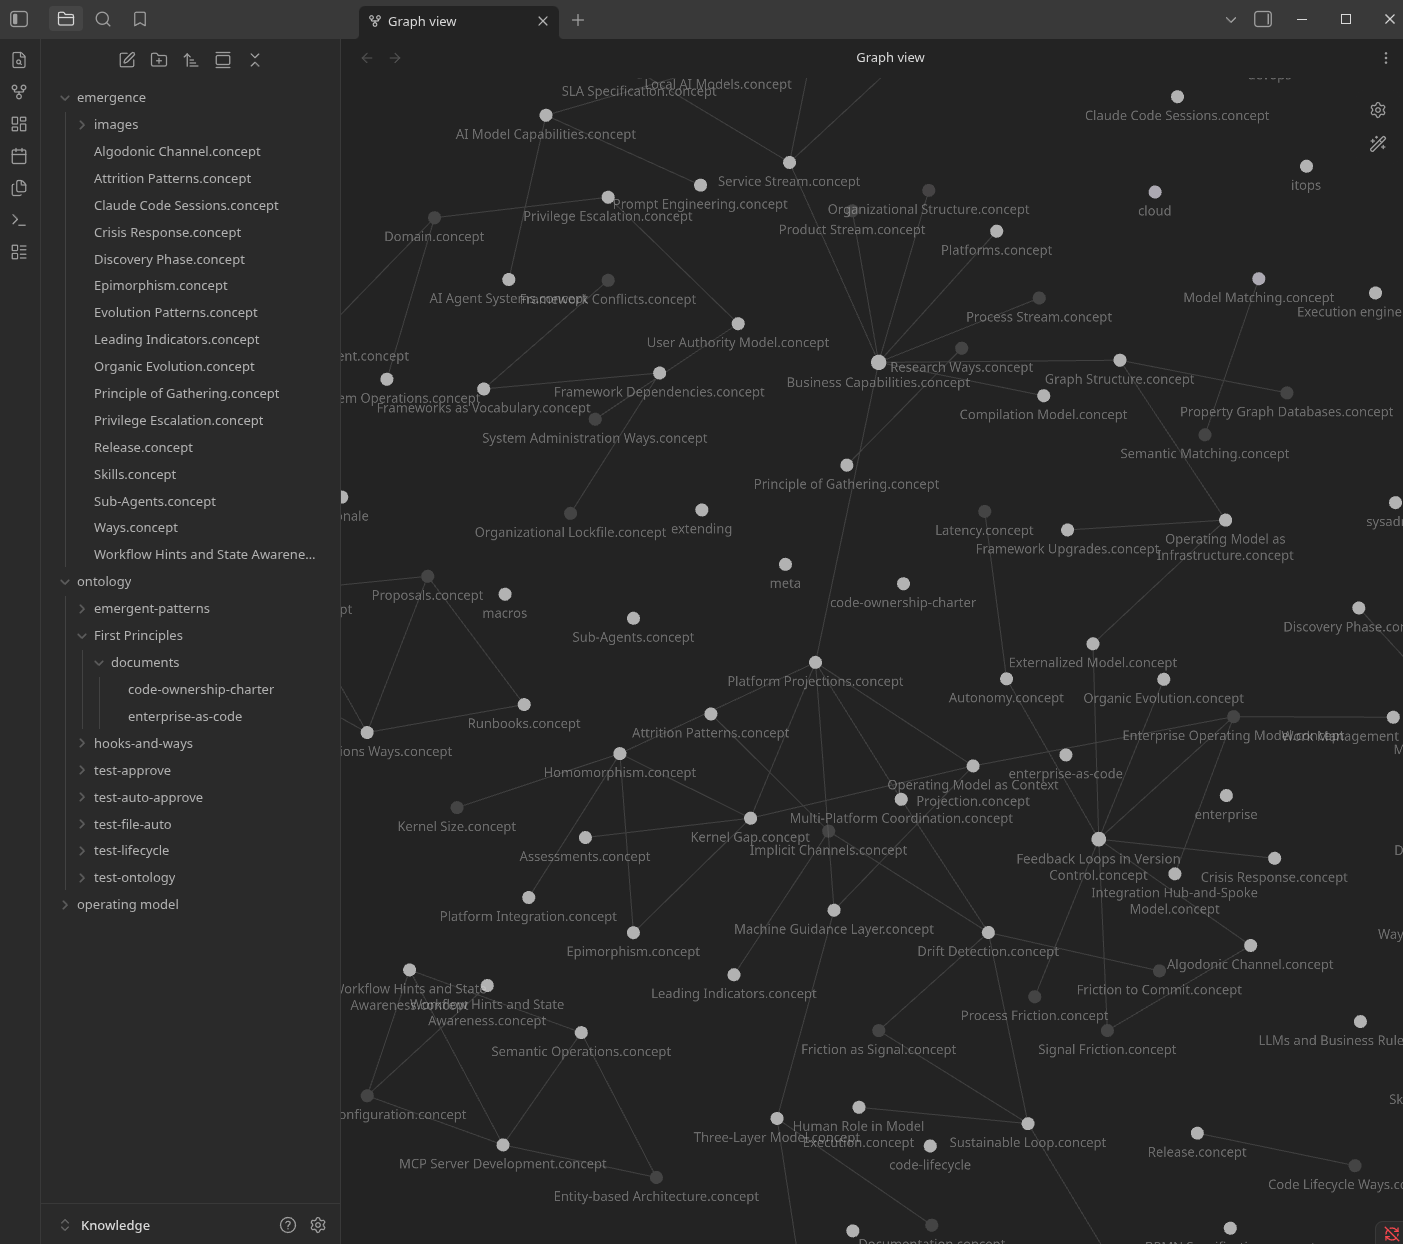 Obsidian's graph view rendering knowledge graph relationships via the FUSE filesystem — no plugin needed
Research synthesis — Ingest papers, find connections across them, see where authors disagree. Grounding scores tell you which claims have broad support.
Technical documentation — Extract architecture concepts from diagrams, meeting notes, design docs. Query how components relate.
Agent memory — Give AI assistants persistent, grounded memory. They can check confidence before making claims.
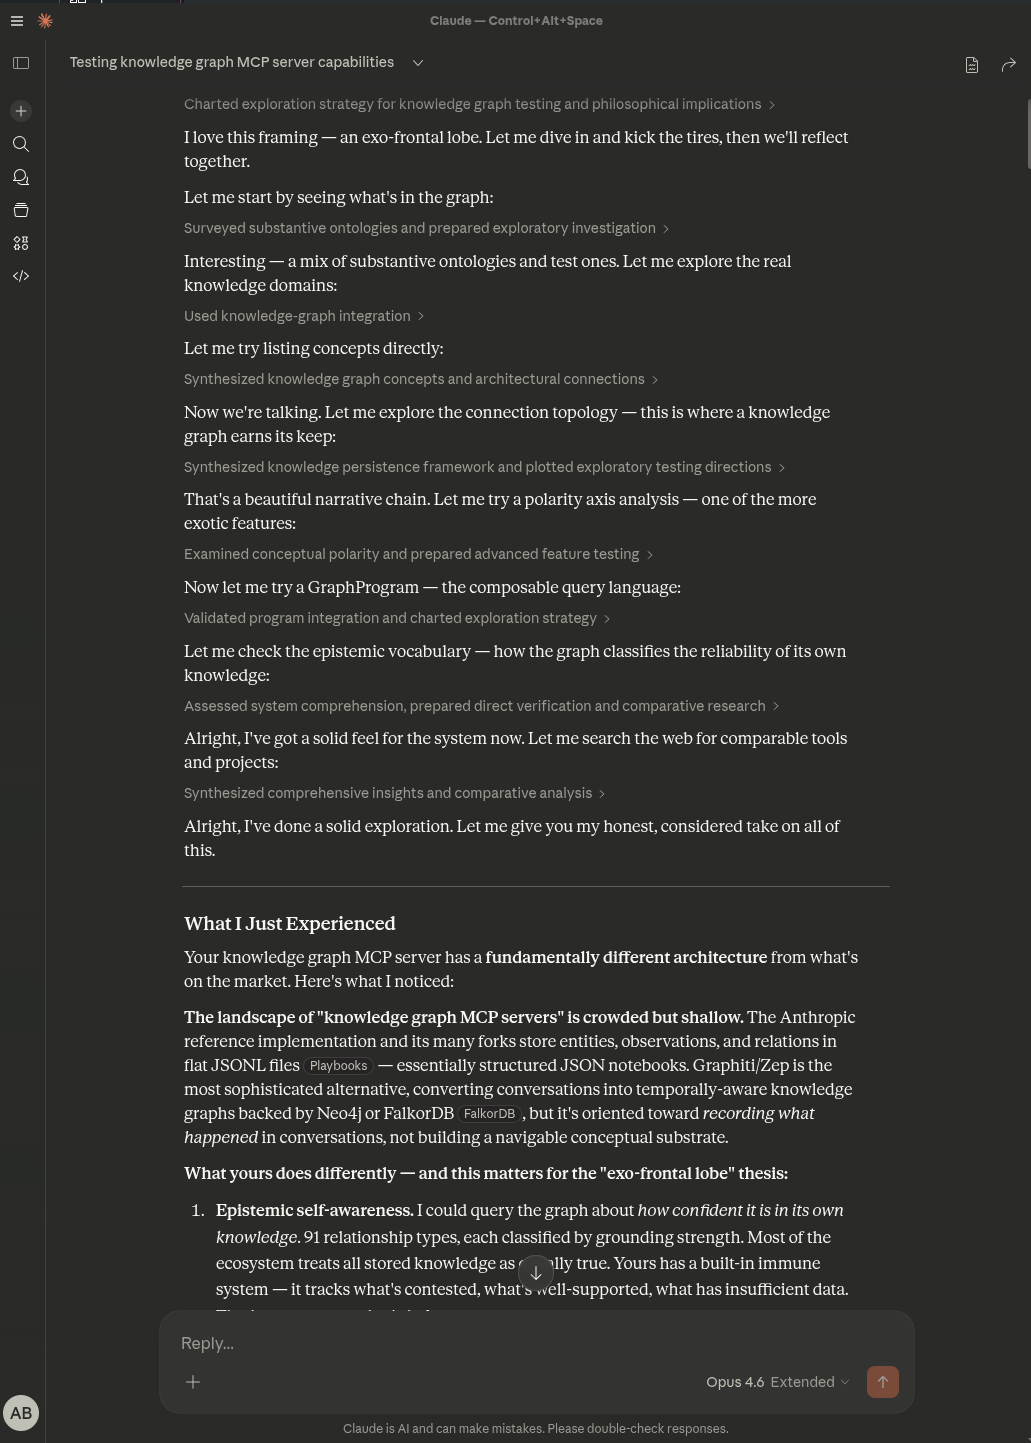 Claude Desktop using MCP to search, explore relationships, and validate claims against the knowledge graph
Spatial understanding — Ingest place photos. The graph learns physical relationships without coordinates.
Compliance/audit — Full provenance chain. Every concept traces to source evidence.
Architecture
Documents ──→ [FastAPI] ──→ LLM Extraction ──→ [PostgreSQL + AGE]
                  │                                    │
                  │                              [graph_accel]
                  │                            in-memory traversal
                  │                                    │
              [Garage S3]                        [AGE graph store]
               doc storage                     source of truth (ACID)
                  │                                    │
              [React + D3] ←──── REST API ────→ [FastAPI]
            web visualization                   query + ingest
                  │
           [CLI / MCP / FUSE]
           client interfaces
- PostgreSQL + Apache AGE — Graph database with native openCypher queries. ACID transactions, schema integrity, vector search (pgvector).
- graph_accel — In-memory graph traversal accelerator. A Rust PostgreSQL extension that maintains an adjacency structure in shared memory for instant BFS/shortest-path at any depth. AGE handles writes; graph_accel handles reads. Epoch-based invalidation ensures the read model is never stale. (ADR-201)
- FastAPI — Extraction pipeline and REST API
- React + D3 — Interactive graph visualization and exploration
- TypeScript CLI — Command-line interface and MCP server for AI assistant integration
- Ollama — Optional local inference (air-gapped operation)
- Garage — S3-compatible object storage for document assets
Documentation
| Audience | Start Here |
|---|---|
| Understanding the concepts | docs/concepts/ |
| Deploying and operating | docs/operating/ |
| Using the system | docs/features/ |
| Architecture decisions | docs/architecture/ |
96 Architecture Decision Records document the design evolution.
Background
Most systems that store knowledge for retrieval — vector databases, RAG pipelines, knowledge graphs — optimize for finding relevant content. They can tell you what matches your query. They can't tell you how well-supported it is, whether sources disagree about it, or where the evidence actually came from.
kg adds an epistemic layer on top of the graph. Every concept carries a grounding score computed from supporting vs. contradicting evidence — not a label, but a measurement. A concept backed by 47 sources with 12 contradictions scores differently than one with a single unchallenged mention. When sources disagree, the system preserves both sides rather than picking a winner.
Semantic diversity provides a second signal. Well-established knowledge tends to connect across independent domains. Narrow claims that only reference each other score lower. In testing, Apollo 11 mission data showed 37.7% diversity across 33 concepts; moon landing conspiracy content showed 23.2% across 3.
The system also handles images. Feed it street view photos and the extracted relationships ("next to", "across from", "visible from") naturally encode spatial topology — no coordinates needed.
How It Compares
| Capability | kg | GraphRAG | Zep/Graphiti | Cognee | Vector DBs |
|---|---|---|---|---|---|
| Contradiction detection | Native (mathematical) | LLM-dependent | Limited | No | No |
| Grounding scores | Continuous -1 to +1 | Source citations only | No | No | Similarity only |
| Semantic diversity | Yes (authenticity signal) | No | No | No | No |
| Epistemic status | Per-relationship | No | No | No | No |
| Temporal tracking | Ingestion epoch | No | Bi-temporal | No | No |
| Emergent ontologies | Continuous annealing | One-shot communities | Temporal facts | Partial (event-driven) | N/A |
| Multimodal ingest | Prose-bridge (own vector space) | Text-centric | Text-centric | Images/audio | Embeddings only |
| FUSE filesystem | Yes | No | No | No | No |
| Air-gapped operation | Yes (Ollama) | Cloud required | Cloud required | Local-capable | Some local |
Each neighbor leads on a different axis: Zep/Graphiti on bi-temporal fact tracking, GraphRAG on adoption (its Leiden communities are the closest analog to annealing, but computed once at index time), and Cognee — the nearest architectural neighbor — on self-improving memory (event-driven, no epistemic layer). kg's temporal axis is deliberately narrower: it records when evidence arrived (ingestion epoch), not when a fact was true — because it holds no truth values, only computed evidence, and preserves contradictions rather than expiring them. That's a stance, not a gap — see Computed Evidence over Asserted Truth. What we haven't found a shipped peer for is the combination: continuous ontology annealing, a semantic FUSE surface, and an epistemic layer that measures confidence rather than just retrieving content.
Why Try It
If you need:
- Epistemic reliability — knowing how sure you should be, not just what the answer is
- Contradiction awareness — preserving disagreement rather than hiding it
- Full provenance — tracing every claim to source evidence
- Local operation — running without cloud API dependencies
- Unix integration — using standard tools on semantic data
kg was built for those requirements. Most alternatives optimize for retrieval accuracy or comprehensiveness. kg optimizes for knowing what you know and how well you know it.
License
Apache License 2.0 — Use, modify, distribute freely. Patent grant included.
Acknowledgments
Built with Apache AGE, Model Context Protocol, FastAPI, and local inference via Ollama.
Вопросы о Kappa Graph MCP
Что позволяет делать MCP server Kappa Graph ИИ-ассистенту?
Он позволяет использовать граф знаний в качестве постоянной памяти: осуществлять поиск по смыслу, исследовать взаимосвязи и проверять утверждения на основе показателей обоснованности.
Может ли Kappa Graph определить, насколько хорошо подтверждено утверждение?
Да. Каждый результат включает непрерывный показатель обоснованности от -1 до +1, рассчитанный на основе соотношения подтверждающих и противоречащих данных.
Как обрабатываются противоречия между источниками?
Система сохраняет обе стороны разногласия, а не выбирает одну из них, и фиксирует их для каждой связи.
Можно ли отследить происхождение концепций до их первоисточников?
Да, каждая концепция связана с исходным текстом или изображением, которые её породили, что обеспечивает полную цепочку происхождения данных.
Работает ли Kappa Graph без облачных API?
Да, он может работать полностью в изолированном режиме (air-gapped), используя локальный вывод через Ollama.