
MCP server askdocs
Commit 14 de nov. de 2026Fornece um serviço de perguntas e respostas sobre corpora de documentos com fontes citadas, utilizando recuperação via MCP e LLMs locais.
Também conhecido como Simon-oid/askdocs
- Stars
- 1
- Ferramentas
- —
- Downloads, 30 dias
- —
- Versão mais recente
- —
- Último commit
- 14 de nov. de 2026
- Licença
- MIT
O que é o MCP askdocs?
askdocs é um MCP server. Fornece um serviço de perguntas e respostas sobre corpora de documentos com fontes citadas, utilizando recuperação via MCP e LLMs locais.
Resumo gerado a partir do README do projeto
Sobre o MCP server de askdocs
Desenvolvedores que precisam de um serviço confiável de perguntas e respostas sobre coleções de documentos privados podem usar o askdocs para recuperar respostas citadas usando LLMs locais. O sistema se integra a um MCP server via ferramenta crag-mcp para realizar a recuperação, garantindo que as respostas sejam fundamentadas em passagens específicas de um corpus de documentos. Ele foi projetado para rodar localmente usando Docker Compose, com suporte para GPUs NVIDIA ou AMD, ou pode ser configurado para usar APIs compatíveis com OpenAI.
Este serviço prioriza a precisão e a confiabilidade ao implementar um filtro de relevância que recusa perguntas fora do tópico antes que elas cheguem ao modelo. Ele utiliza llama.cpp para servir modelos locais e suporta arquivos GGUF customizados. Para evitar alucinações, o sistema verifica as citações em relação às fontes recuperadas e reporta quaisquer atribuições inválidas. Os usuários podem monitorar o desempenho através de rastreamento OpenTelemetry e gerenciar a concorrência via configuração ASKDOCS_MAX_CONCURRENT para evitar a sobrecarga do sistema.
O que você pode fazer com ele
- 1Consultar documentação privadaUm desenvolvedor pode fazer perguntas técnicas específicas sobre uma base de código ou conjunto de documentação e receber respostas com citações diretas da fonte.
- 2Reduzir custos de geração de LLMO sistema pode identificar perguntas fora do tópico durante a etapa de recuperação para evitar gastos com geração de modelo desnecessária.
- 3Verificar a fidelidade das respostasOs usuários podem identificar quando um modelo fornece uma resposta que não é realmente suportada pelo texto fornecido por meio do relatório de citações inválidas.
Escrito a partir do README do projeto. Cada caso de uso é verificado com uma citação dele.
Configuração
ASKDOCS_INTEGRATIONRENDER_GID
| Nome | Descrição | Tipo |
|---|---|---|
| ASKDOCS_INTEGRATION | — | |
| RENDER_GID | — |
Verificações automatizadas
Executado em 15 de nov. de 2026Relatório completo →Ainda não verificado. Um servidor precisa de uma pontuação de 80, nenhum problema grave e dados suficientes para verificarmos. Como as verificações funcionam · O que corrigir para ganhar mais pontos

- Repositório de origem vinculado e acessívelsimon-oid/askdocs is public and reachablegithub.com/simon-oid/askdocs ↗Passou
- O pacote indica este repositório como sua origemNão verificado
- Proveniência da build (atestação Sigstore)Não verificado
- Licença de código aberto (OSI)MITspdx.org/licenses/MIT.html ↗Passou
- Commit ou release no último anoLast commit or release 2026-11-14github.com/simon-oid/askdocs ↗Passou
- OpenSSF ScorecardNão verificado
- Nome do pacote não é próximo a um pacote popularNão verificado
- Nenhum aviso crítico no pacote ou em suas dependênciasNão verificado
- Sem instruções ocultas para o modelo0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersPassou
- Ferramentas destrutivas estão rotuladasNão verificado
- O endpoint remoto responde ao handshake do MCPNão verificado
README
Ver no GitHubaskdocs


A question-answering service over a document corpus that cites its sources:
FastAPI with streamed answers (SSE), retrieval through an MCP server
(cMCP's crag-mcp, backed by
cRAG), a local LLM served by llama.cpp,
and an evaluation that blocks regressions in CI.
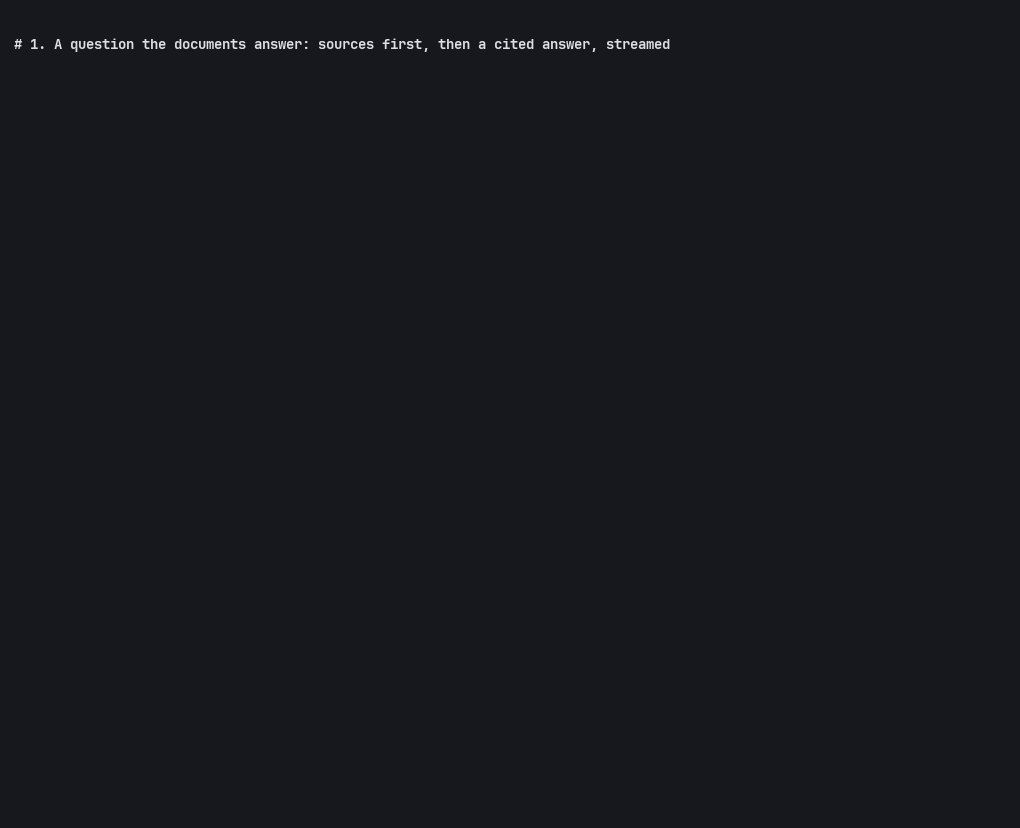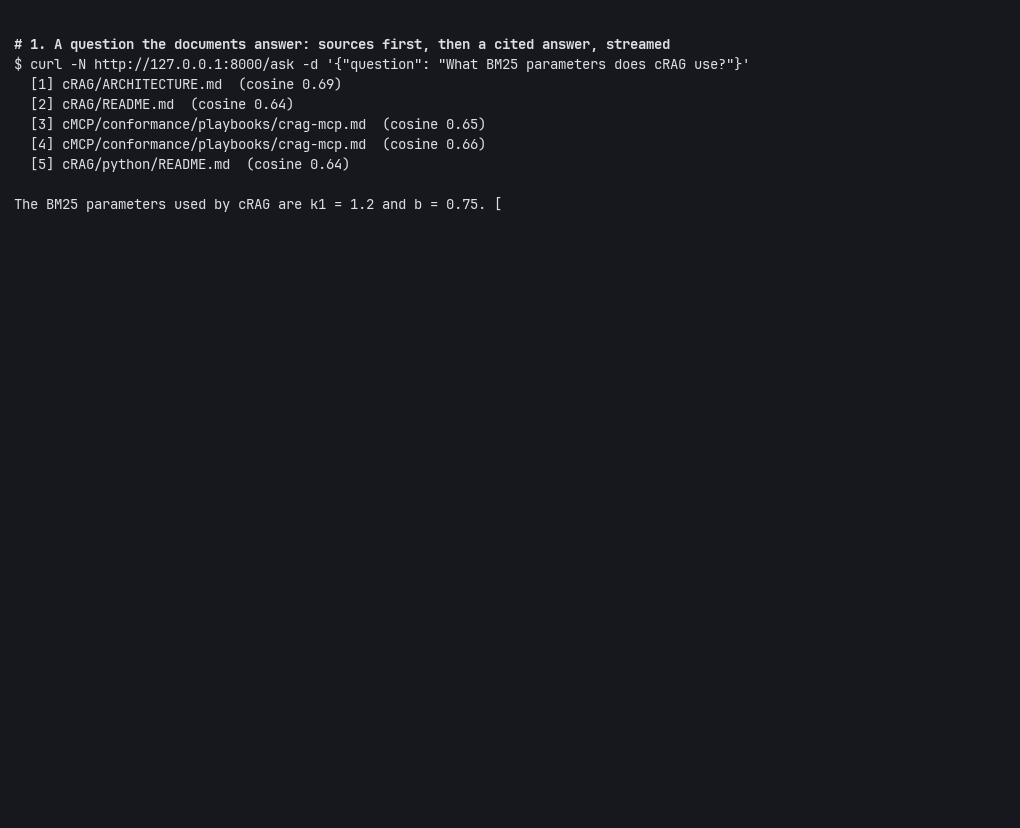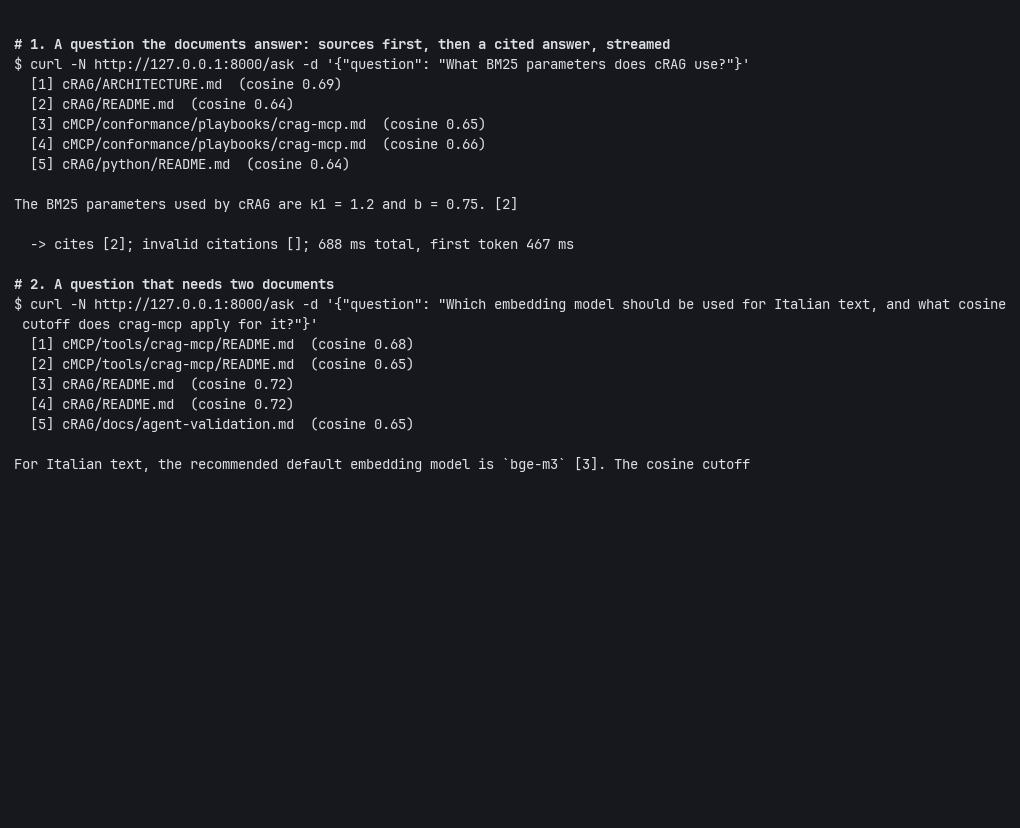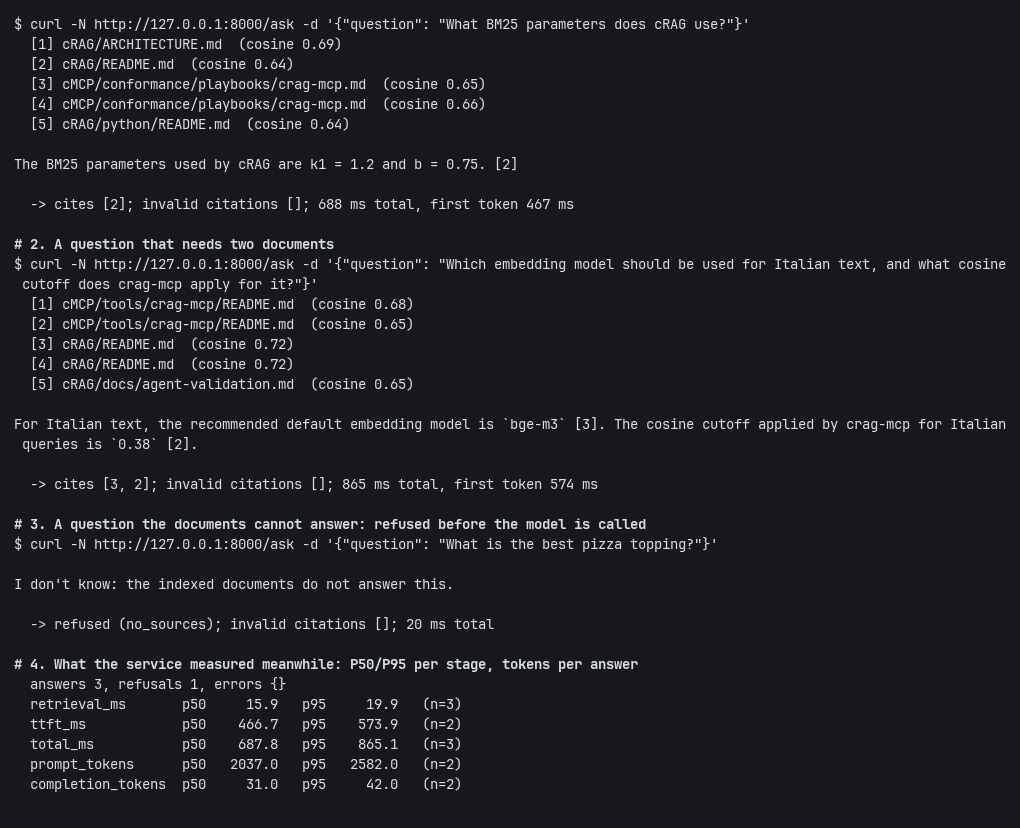
Status: complete. The service, a 45-case evaluation with a CI gate, OpenTelemetry tracing, a one-command Docker Compose stack, a load test and an AWS guide (prepared, not yet run on AWS). Every number here comes from a script, with its hardware and date.
docs/architecture.md explains the design: why
retrieval goes through MCP (measured: about 0.4 ms per question, below the
noise against an in-process call), and why the service refuses with 503
instead of queueing.
How an answer is made
POST /ask ──► crag_search over MCP (stdio) ──► passages [1..k]
                 │ nothing clears the relevance gate?
                 └──► "I don't know" — the model is never called
          ──► prompt: numbered sources + rules ──► LLM (streamed)
          ──► SSE: sources, token…, done {citations, refused, usage, timings}
- Citations are checked, not trusted.
done.citationslists the source numbers the answer uses;done.invalid_citationslists numbers that point at no source (a fabrication the eval counts). - Refusing is a first-class answer. Off-topic questions are refused in
the retrieval step, without paying for a generation; when passages exist
but do not contain the answer, the model is told to reply with one fixed
sentence, and
done.refusedreports it. - Failures are bounded. Per-chunk read timeout on the model stream;
retries (exponential backoff) only before the first token reaches the
client; one reconnect if the MCP server dies; at most
ASKDOCS_MAX_CONCURRENTanswers in flight, then503withRetry-After. - Incomplete is not short. A model stream that ends without
[DONE]or a finish reason, or carries an error chunk, is anerror, never a truncated "answer"; an answer cut bymax_tokenshasdone.truncated. - Documents are data. Sources and the question sit between per-request random fences that their text cannot close, so a document cannot forge a source header or an instruction.
- A client that disconnects stops the generation, in both modes: the
SSE stream is closed at once; a JSON request (
?stream=false) polls for the disconnect and cancels. Either way the upstream stream closes and llama.cpp cancels the task (tested with raw ASGI disconnects, and checked against a real llama.cpp server). - Bounded input. Request bodies over 16 KB get
413before they are read into memory, on Content-Length and on the bytes actually received (chunked uploads); questions over 2000 characters get422.
Quick start
With Docker, one command. It pulls the models, builds cRAG and crag-mcp from
source, builds the index, and serves the API on 127.0.0.1:8000:
docker compose up -d                                         # CPU (slow: ~14 s an answer)
RENDER_GID=$(getent group render | cut -d: -f3) \
  docker compose -f compose.yaml -f compose.rocm.yaml up -d  # AMD GPU (~0.7 s)
docker compose -f compose.yaml -f compose.cuda.yaml up -d    # NVIDIA GPU
To answer with a GGUF file of your own (a fine-tuned model, say), add
compose.local-model.yaml with
ASKDOCS_LLM_GGUF=/abs/path/model.gguf.
The first start takes a few minutes, and later starts reuse the volumes.
The ROCm image of llama.cpp is 22.9 GB. docs/deploy-aws.md
runs the same stack on one EC2 GPU instance, reached through Session Manager
with no open port.
With the service up, scripts/demo.sh walks through it in four
scenes (the recording above): a cited answer streamed, a two-document question, a refusal made
before the model is called, and the latency the service measured meanwhile.
Without Docker:
# 1. The models: an embedder in Ollama, an LLM in llama.cpp.
ollama pull mxbai-embed-large
# 4 slots (= ASKDOCS_MAX_CONCURRENT), 4096 tokens each: -c is for all slots together.
llama-server -hf Qwen/Qwen2.5-3B-Instruct-GGUF:Q4_K_M --port 8081 -ngl 99 -c 16384 -np 4

# 2. The demo corpus: cMCP + cRAG documentation at pinned commits, indexed by cRAG.
CRAG=/path/to/cRAG/crag scripts/build_corpus.sh

# 3. The service.
python -m venv .venv && .venv/bin/pip install -e '.[dev]'
cp .env.example .env            # set ASKDOCS_MCP_COMMAND to your crag-mcp build
.venv/bin/askdocs --port 8000
curl -N localhost:8000/ask -H 'content-type: application/json' \
     -d '{"question": "How is the requestState sealed in cMCP?"}'
event: sources
data: {"sources": [{"n": 1, "source": "cMCP/CHANGELOG.md", "text": "...", "cosine": 0.683, ...}, ...]}

event: token
data: {"text": "The requestState is sealed with HMAC-SHA256 "}
...
event: done
data: {"answer": "...", "citations": [2, 3], "invalid_citations": [], "refused": false,
       "usage": {"prompt_tokens": 1594, "completion_tokens": 101},
       "timings": {"retrieval_ms": ..., "ttft_ms": ..., "generation_ms": ..., "total_ms": ...}}
POST /ask?stream=false returns the same as one JSON envelope
({"success", "data", "error"}); GET /healthz reports load. done and
error also carry trace_id, and done carries cost_usd.
API
POST /ask |
body {"question": str (1–2000 chars), "k": int 1–20 (optional)}; SSE by default, JSON with ?stream=false |
| SSE events | sources → token* → done, or error {stage: retrieval|generation|internal, message, partial?}; a stream always ends with one of the two |
| Errors | 413 body over 16 KB · 422 bad input · 503 too many in flight · 502 (JSON mode) when retrieval or the model fails, 500 on an internal error; details stay in the server log |
GET /healthz |
{"status", "in_flight", "max_concurrent"} |
GET /stats |
answers, refusals, errors by stage, and P50/P95 of each stage, tokens and cost over the last 1000 answers |
Configuration
Environment variables (or .env), all prefixed ASKDOCS_; see
.env.example and src/askdocs/config.py,
where every limit carries its reason.
| Variable | Default | |
|---|---|---|
LLM_PROVIDER |
llamacpp |
llamacpp or openai (any OpenAI-compatible API; needs LLM_MODEL and LLM_API_KEY) |
LLM_BASE_URL |
per provider | http://localhost:8081/v1 / https://api.openai.com/v1 |
LLM_MAX_TOKENS, LLM_TEMPERATURE |
512, 0.0 |
temperature 0 keeps evals reproducible |
LLM_READ_TIMEOUT_S, LLM_MAX_RETRIES |
60, 2 |
timeout per streamed chunk, not per answer |
MCP_COMMAND, MCP_DB |
crag-mcp, data/docs.db |
the MCP server and its index |
EMBED_MODEL, EMBED_URL |
mxbai-embed-large, Ollama |
must match the model the index was built with |
TOP_K, MAX_CONCURRENT |
5, 4 |
|
WARMUP |
true |
one background retrieval at startup, so the embedder is loaded before the first question |
LLM_PRICE_INPUT_PER_MTOK, LLM_PRICE_OUTPUT_PER_MTOK |
0, 0 |
USD per million tokens, for cost_usd; 0 for a local model |
OTEL_ENDPOINT, OTEL_SERVICE_NAME |
unset, askdocs |
OTLP/HTTP collector, e.g. http://localhost:4318; needs pip install '.[otel]' |
Observability
Each answer is one OpenTelemetry trace: askdocs.answer with retrieval
(and the MCP SDK's crag_search call under it) and generation (tokens,
finish reason, a first_token event), under FastAPI's own POST /ask
span. Off by default; with no endpoint set the API is a no-op.
Measured over the 45 eval questions, one at a time (P50 / P95):
| Stage | ms |
|---|---|
| retrieval (MCP round trip, embedding included) | 14 / 18 |
| time to first token | 449 / 567 |
| answer, end to end | 683 / 1152 |
| Per answer | P50 / P95 |
|---|---|
| prompt tokens | 2009 / 2492 |
| completion tokens | 33 / 89 |
Generation is about 97% of an answer, and the prompt is about 60 times the
answer, so with a hosted model top_k drives the cost. Tracing adds about
94 µs per answer. docs/observability.md has the
trace tree, why the spans are not made "current" across the token stream,
the cold-start finding, and how the numbers were measured.
Tests
.venv/bin/pytest -q                      # hermetic: fake LLM, fake MCP server over real stdio
ASKDOCS_INTEGRATION=1 .venv/bin/pytest -m integration   # the real stack, running
The retriever is tested against a stand-in MCP server
(tests/fake_crag_mcp.py) spoken to over real
stdio, including a crash mid-session and the reconnect after it.
Evaluation
evals/cases.jsonl holds 45 labelled questions about
the demo corpus: 30 factual, 5 that need two sources, 6 in the corpus's
domain that it does not answer, 4 off-topic. Each answerable case lists the
files the answer lives in and the key facts it must contain.
python evals/run.py --phase answer    # answering model running (llama.cpp :8081)
python evals/run.py --phase judge     # then the judge model (:8082) grades that run
python evals/agreement.py             # judge vs a second grader on a sample
Two phases because 16 GB of RAM did not hold both models plus a desktop (the
kernel OOM-killed the answering model); one process can do both with
--phase all.
What is measured, and why apart:
- Retrieval recall@k: is the right file among the passages? Scored without the model, so a retrieval miss is not blamed on generation.
- Key-fact recall: does the answer contain the labelled facts? A refusal of an answerable question scores 0.
- Refusals: right for the 10 unanswerable/off-topic cases, wrong for the 35 others.
- Faithfulness: the answer is split into sentences; for each, a judge model (Qwen2.5-7B, not the 3B that wrote the answer) is asked one yes/no question per cited passage. An uncited sentence is unsupported.
Baseline (evals/results/report.md; Qwen2.5-3B
answering, top-k 5; bootstrap 95% intervals over cases):
| Metric | Mean [95% CI] | n |
|---|---|---|
| Retrieval recall@1 / @3 / @5 | 0.61 / 0.94 / 0.99 | 35 |
| Context recall (right file among the 5 passages the model got) | 0.94 [0.87, 1.00] | 35 |
| Key-fact recall | 0.87 [0.76, 0.96] | 35 |
| ... factual / multi-source | 0.92 / 0.60 [0.30, 0.90] | 30 / 5 |
| Wrong refusals | 0.03 [0.00, 0.09] | 35 |
| Correct refusals (unanswerable + off-topic) | 1.00 | 10 |
| Faithfulness (judged sentences supported) | 0.60 [0.45, 0.75] | 34 |
What it says:
- Retrieval is not the bottleneck. The right file is in the top 5 for 34 of 35 questions, but first only 61% of the time, so the prompt has to make the model read past source [1].
- Faithfulness is the weak point. The two failure modes found reading the verdicts: citing a neighbouring passage instead of the one holding the fact, and copying a passage as a list with no citations at all. The answer is often right and badly attributed.
- The judge is usable, not perfect. On a 25-sentence sample graded
independently against the full cited passages it agreed on 23 (Cohen's kappa
0.80): it rejected one sentence supported by a paraphrase and accepted one
that garbled its passage. At this sample size the errors do not lean either
way. The second grader was a stronger model (Claude Opus 5.5, recorded as
reference_by), not a person: a check of the judge, not ground truth. - Single runs are noisy. At temperature 0, four answer runs gave key-fact recall 0.77, 0.80, 0.81 and 0.87: the prompt fence is random per request and llama.cpp batches slots, so the text changes. Retrieval was identical every time. A difference of ~0.1 between two runs is not a regression.
- The corpus contradicts itself once: crag-mcp's README says schema errors
are JSON-RPC
-32602, a dogfood report says they areisError: true. Casef16follows the README.
The gate
python evals/gate.py check                    # what CI runs
python evals/gate.py compare evals/results NEW_RUN_DIR
python evals/gate.py noise RUN_DIR RUN_DIR ... --write
CI has no GPU and no models, so it cannot rerun the eval. It checks the
committed results instead: they must cover exactly the current
cases.jsonl (a case added or edited without a rerun fails) and clear the
floors in evals/gate.json.
The regression test runs where the models are. It pairs the two runs case by case and calls a drop a regression only if both
- the paired bootstrap interval of (new − base) excludes zero, and
- the drop is larger than the run-to-run noise: the largest gap between any two runs of the same code (4 runs: key facts 0.10, wrong refusals 0.06, faithfulness 0.05, retrieval 0).
The second condition is not decoration. Comparing the baseline with a rerun of the same code, the paired test alone flagged a key-fact "regression" of −0.10 with an interval of [−0.20, −0.01]. Run noise is not case-sampling noise, and a bootstrap over cases does not see it.
And it catches a real one: the same eval with ASKDOCS_TOP_K=1 (the model
sees one passage instead of five) is flagged on context recall −0.33, key facts
−0.27, wrong refusals +0.31 and out-of-range citations +0.24, and fails the
floors. Retrieval recall@k does not move in that run, because it measures the
retriever at k=10, not what reached the model; that is why context recall
exists.
Floors: each is the baseline's 95% interval bound moved by the noise, rounded outward to 0.05, so the committed baseline passes and a run as bad as the noisy end of the baseline still does. One exception, recorded in the file: correct refusals (n=10, never failed) would get a degenerate floor of 1.0 and get 0.9.
Load test
Locust in a closed loop over the eval questions (loadtest/run.sh), with a
limit of 4 on 4 llama.cpp slots (docs/load-test.md):
| users | answers/s | ttft P50 / P95 ms | answer P50 / P95 ms | rejected (503) | failed |
|---|---|---|---|---|---|
| 1 | 1.34 | 440 / 580 | 690 / 1700 | 0% | 0 |
| 4 | 1.78 | 540 / 1100 | 2100 / 4300 | 0% | 0 |
| 16 | 1.81 | 550 / 1500 | 2100 / 4000 | 87% | 0 |
- A configuration bug it caught. The first run failed 68 of 104 answers
at 4 users: llama.cpp's
-cis the context of all slots together, so 8192 was too small. It is now-c 16384 -np 4. - The service is prefill-bound. Each answer needs about 0.46 s of GPU just to read its 2000-token prompt, so throughput stops near 1.8 answers/s.
- The limit must equal the slots. With a limit of 8 on 4 slots, throughput stayed the same and time to first token went from 0.5 s to 2.6 s, as the extra answers queued unseen inside llama.cpp.
Limitations
KNOWN_LIMITATIONS.md lists where askdocs fails or is
untested, with the numbers: faithfulness at 0.60, no authentication, one
GPU's worth of throughput, an AWS deploy that has not been run.
License
MIT
Perguntas sobre o MCP askdocs
Como o serviço lida com as citações?
O serviço verifica as citações em vez de apenas confiar nelas; ele lista os números das fontes utilizadas e identifica quaisquer citações inválidas que não apontem para nenhuma fonte.
O que acontece se uma pergunta for fora do tópico?
Perguntas fora do tópico são recusadas durante a etapa de recuperação, o que evita custos desnecessários de geração do modelo.
Como o serviço é implantado?
O serviço pode ser implantado usando uma stack Docker Compose de um único comando, que gerencia os modelos, a indexação e a API.