
MCP server diffusers-workflow
Commit 14 de nov. de 2026Executa fluxos de trabalho de geração de imagem, vídeo e áudio do Hugging Face Diffusers como jobs na sua própria GPU, comandados por um agente de IA.
Também conhecido como dkackman/diffusers-workflow
- Stars
- 18
- Ferramentas
- —
- Downloads, 30 dias
- —
- Versão mais recente
- —
- Último commit
- 14 de nov. de 2026
- Licença
- Apache-2.0
O que é o MCP diffusers-workflow?
diffusers-workflow é um MCP server. Executa fluxos de trabalho de geração de imagem, vídeo e áudio do Hugging Face Diffusers como jobs na sua própria GPU, comandados por um agente de IA.
Resumo gerado a partir do README do projeto
Sobre o MCP server de diffusers-workflow
Gerar mídia através de agentes de IA no seu próprio hardware é o que o diffusers-workflow possibilita para desenvolvedores e criadores. Este MCP server permite que um agente comande pipelines do Hugging Face Diffusers para produzir imagens, vídeos e áudios diretamente na sua GPU local ou em uma máquina remota. Ele suporta diversos hardwares, incluindo NVIDIA CUDA, Apple Silicon MPS e CPU, e integra-se ao Claude Code ou outros clientes MCP para gerenciar tarefas generativas complexas.
Os usuários interagem com o sistema por meio de um agente que pode escrever, validar e executar workflows baseados em JSON. O servidor fornece uma interface web onde você pode direcionar o processo, editar variáveis em um formulário e visualizar uma galeria de resultados. Ele inclui ferramentas específicas para estimar custos de GPU via validate_workflow e gerenciar assets. Como utiliza um worker persistente, os modelos permanecem carregados na memória para acelerar execuções consecutivas. Para modelos com acesso restrito, como FLUX ou MiniMax, basta fornecer sua autenticação do Hugging Face via hf auth login.
O que você pode fazer com ele
- 1Estimativa de custo antes da renderizaçãoVocê pode pedir ao agente para calcular o tempo de GPU esperado para um workflow específico antes de se comprometer com uma renderização longa.
Escrito a partir do README do projeto. Cada caso de uso é verificado com uma citação dele.
Verificações automatizadas
Executado em 14 de nov. de 2026Relatório completo →Ainda não verificado. Um servidor precisa de uma pontuação de 80, nenhum problema grave e dados suficientes para verificarmos. Como as verificações funcionam · O que corrigir para ganhar mais pontos
- Repositório de origem vinculado e acessíveldkackman/diffusers-workflow is public and reachablegithub.com/dkackman/diffusers-workflow ↗Passou
- O pacote indica este repositório como sua origemNão verificado
- Proveniência da build (atestação Sigstore)Não verificado
- Licença de código aberto (OSI)Apache-2.0spdx.org/licenses/Apache-2.0.html ↗Passou
- Commit ou release no último anoLast commit or release 2026-11-12github.com/dkackman/diffusers-workflow ↗Passou
- OpenSSF ScorecardNão verificado
- Nome do pacote não é próximo a um pacote popularNão verificado
- Nenhum aviso crítico no pacote ou em suas dependênciasNão verificado
- Sem instruções ocultas para o modelo0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersPassou
- Ferramentas destrutivas estão rotuladasNão verificado
- O endpoint remoto responde ao handshake do MCPNão verificado
README
Ver no GitHub
diffusers-workflow
Your GPU, as something an agent can drive.
diffusers-workflow runs Hugging Face Diffusers image, video and audio generation as jobs on your own GPU. An agent does the work. Claude Code, or any MCP client, picks or writes the workflow, checks what it will cost, runs it, and looks at what came back. You steer from the browser. Every workflow, run and output the agent made is in the web UI, where you can change a variable, run it again, compare takes and keep the one you like.
Python 3.12-3.14 | CUDA (NVIDIA) | MPS (Apple Silicon) | CPU
Getting started
1. Install. The script picks the right torch build for your platform, creates a virtual environment and installs everything, MCP server included.
bash ./install.sh && source ./activate      # Linux / macOS
.\install.ps1; .\venv\scripts\activate      # Windows
2. Start the engine. Leave it running; the agent and the browser both talk to it.
dw-serve # web UI on http://127.0.0.1:8765
3. Connect your agent. Register the MCP server with the absolute path to dw-mcp
in the venv you just made (a relative path is the setup detail that most often goes
wrong). Then add the dw plugin:
claude mcp add dw -- "$(pwd)/venv/bin/dw-mcp"
/plugin marketplace add dkackman/diffusers-workflow
/plugin install dw@diffusers-workflow
Most of the shipped models (Flux, LTX, MiniMax, ...) are gated. Request access on
the model's Hugging Face page and run hf auth login once. Without it a run fails
partway through with a 401/403 from the Hub. templates/text-to-image uses a small,
ungated model, so it makes a good first run.
Start the engine on the GPU box with --mcp and connect over HTTP. There is nothing
to install on the laptop:
# on the GPU box
dw-serve --host 0.0.0.0 --token "$DW_API_TOKEN" --mcp --workspace ~/studio

# on your laptop
claude mcp add --transport http dw http://gpu-box:8765/mcp \
  --header "Authorization: Bearer $DW_API_TOKEN"
The server's Status page writes that line for you. The whole setup is in Remote GPU server.
On Linux with an NVIDIA GPU, the
dkackman/diffusers-workflow
image runs the server with torch, the engine and the web UI built in. It shares the
model cache and workspace with a native install on the same box. See
Docker.
Ask the agent
Describe what you want. The agent has 65 tools covering the workflow catalog, the real diffusers pipeline signatures, the job queue, the gallery and the model cache, and it stays with a long render until it finishes:
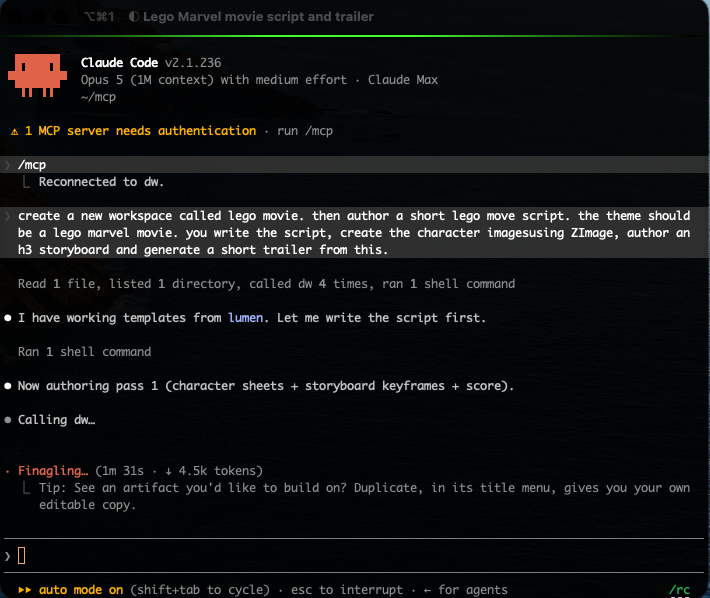
A session sounds like this:
- "Make a 30-second musical trailer: four men in boater hats, a giant eye, a
score under it." The agent picks a shape from the catalog (
list_workflows), breaks the brief into shots, writes each prompt to the prompt library, and builds the workflow that renders the shots and cuts them to the score. - "What will that cost?"
validate_workflowchecks the JSON against the schema and the real pipeline signatures, with no model loads, and quotes an estimate in GPU minutes from this box's own history. Anything that spends GPU time or disk refuses to run until the agent passesacknowledged_cost, so it has to tell you what it is about to spend first. - "How's it going?"
wait_for_jobwaits out a render without polling. Thenget_output_frames,get_output_imageandget_output_audiobring the result back into the conversation, so the agent judges what it made against what you asked for. - "Shot three is the one. Keep it and start the next scene from it."
keep_outputturns the file into a named asset, and the next workflow references it asasset:hero-frame.png.
The dw plugin adds what a general-purpose agent can't know on its own: one skill per model family (MiniMax H3 and Music 3, LTX-2.5, Kandinsky 6, FLUX 3 Klein) that picks the template for a request and states the rules that bite. Cross-cutting skills cover script-to-video, series with a consistent cast, storyboards and animatics, and a shared camera-and-look vocabulary.
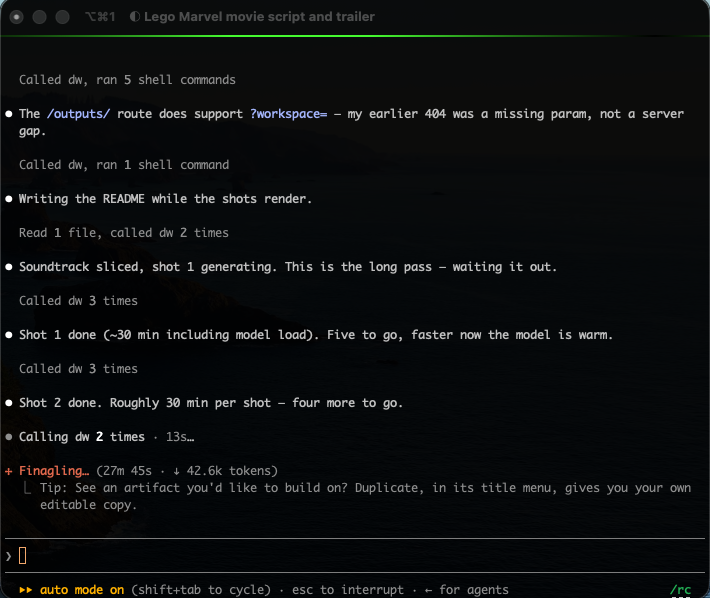
One server holds several workspaces, each with its own workflows, assets and outputs. Two agents, or an agent and you in the browser, can share one GPU without saving over each other's work.
The tool reference, setup for other MCP hosts and the troubleshooting table are in MCP Server.
Then tweak it in the browser
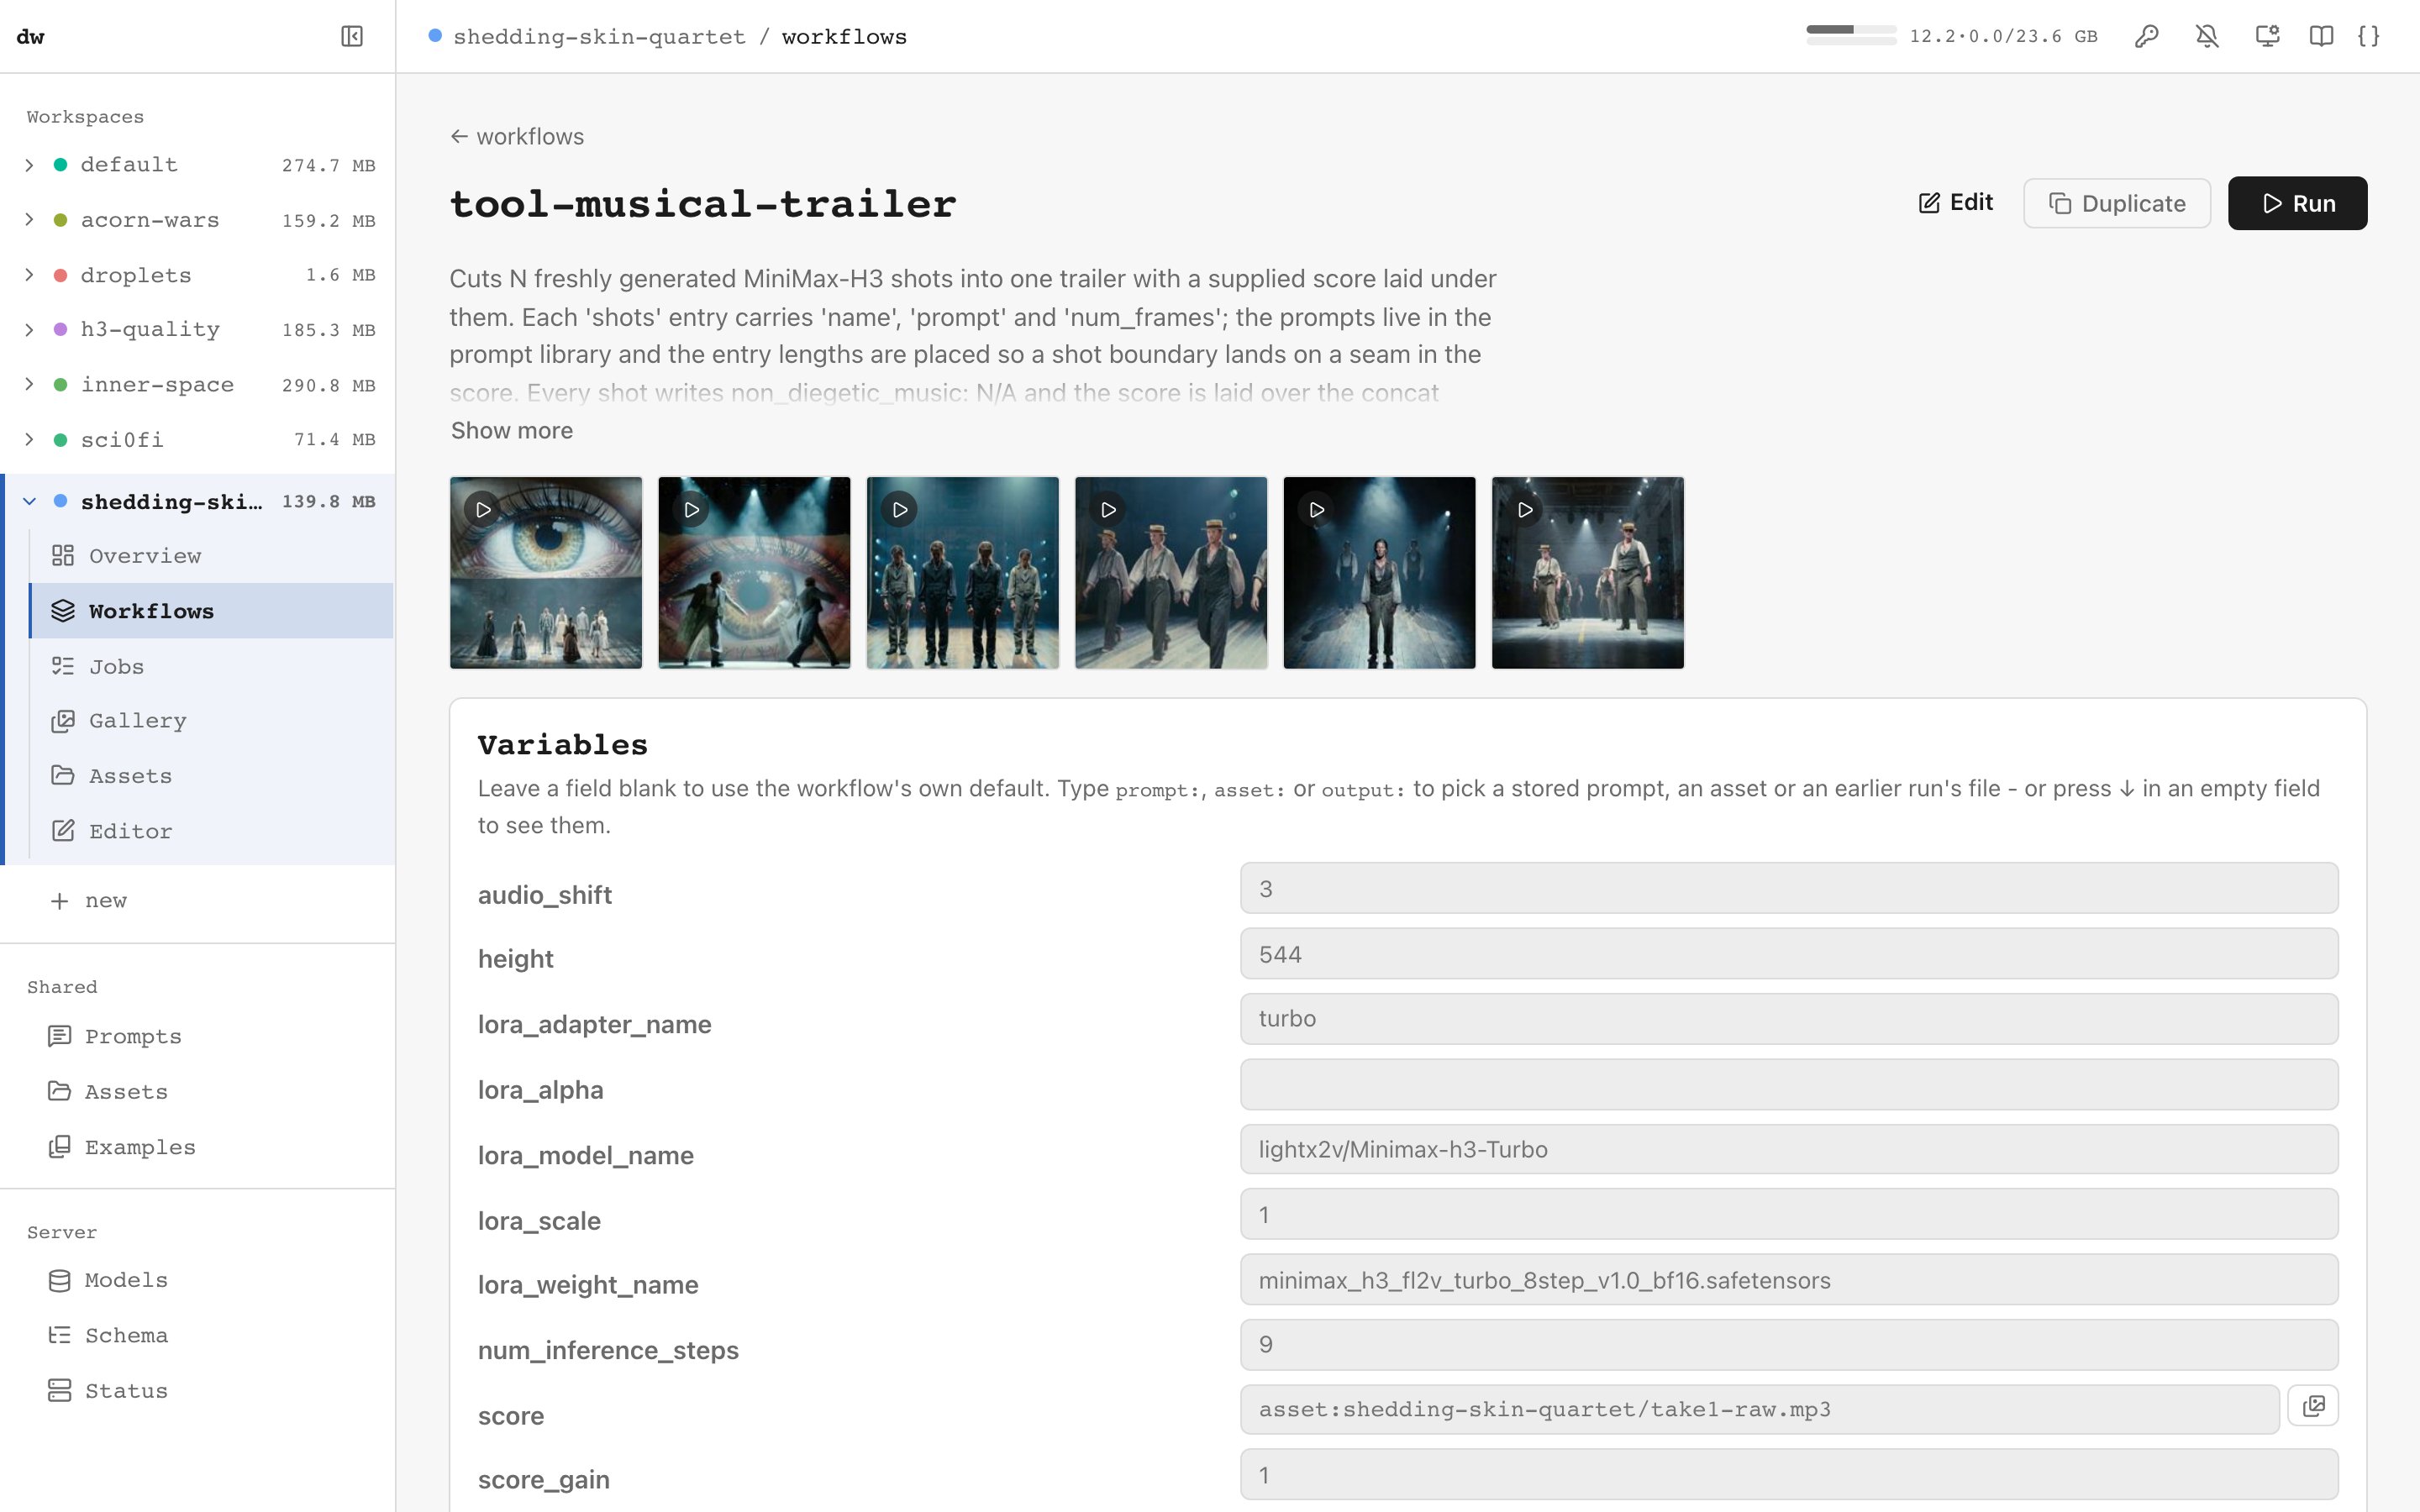
The web UI shows everything the agent made and lets you take over at any point. It runs on the same persistent GPU worker, so models stay loaded between runs.
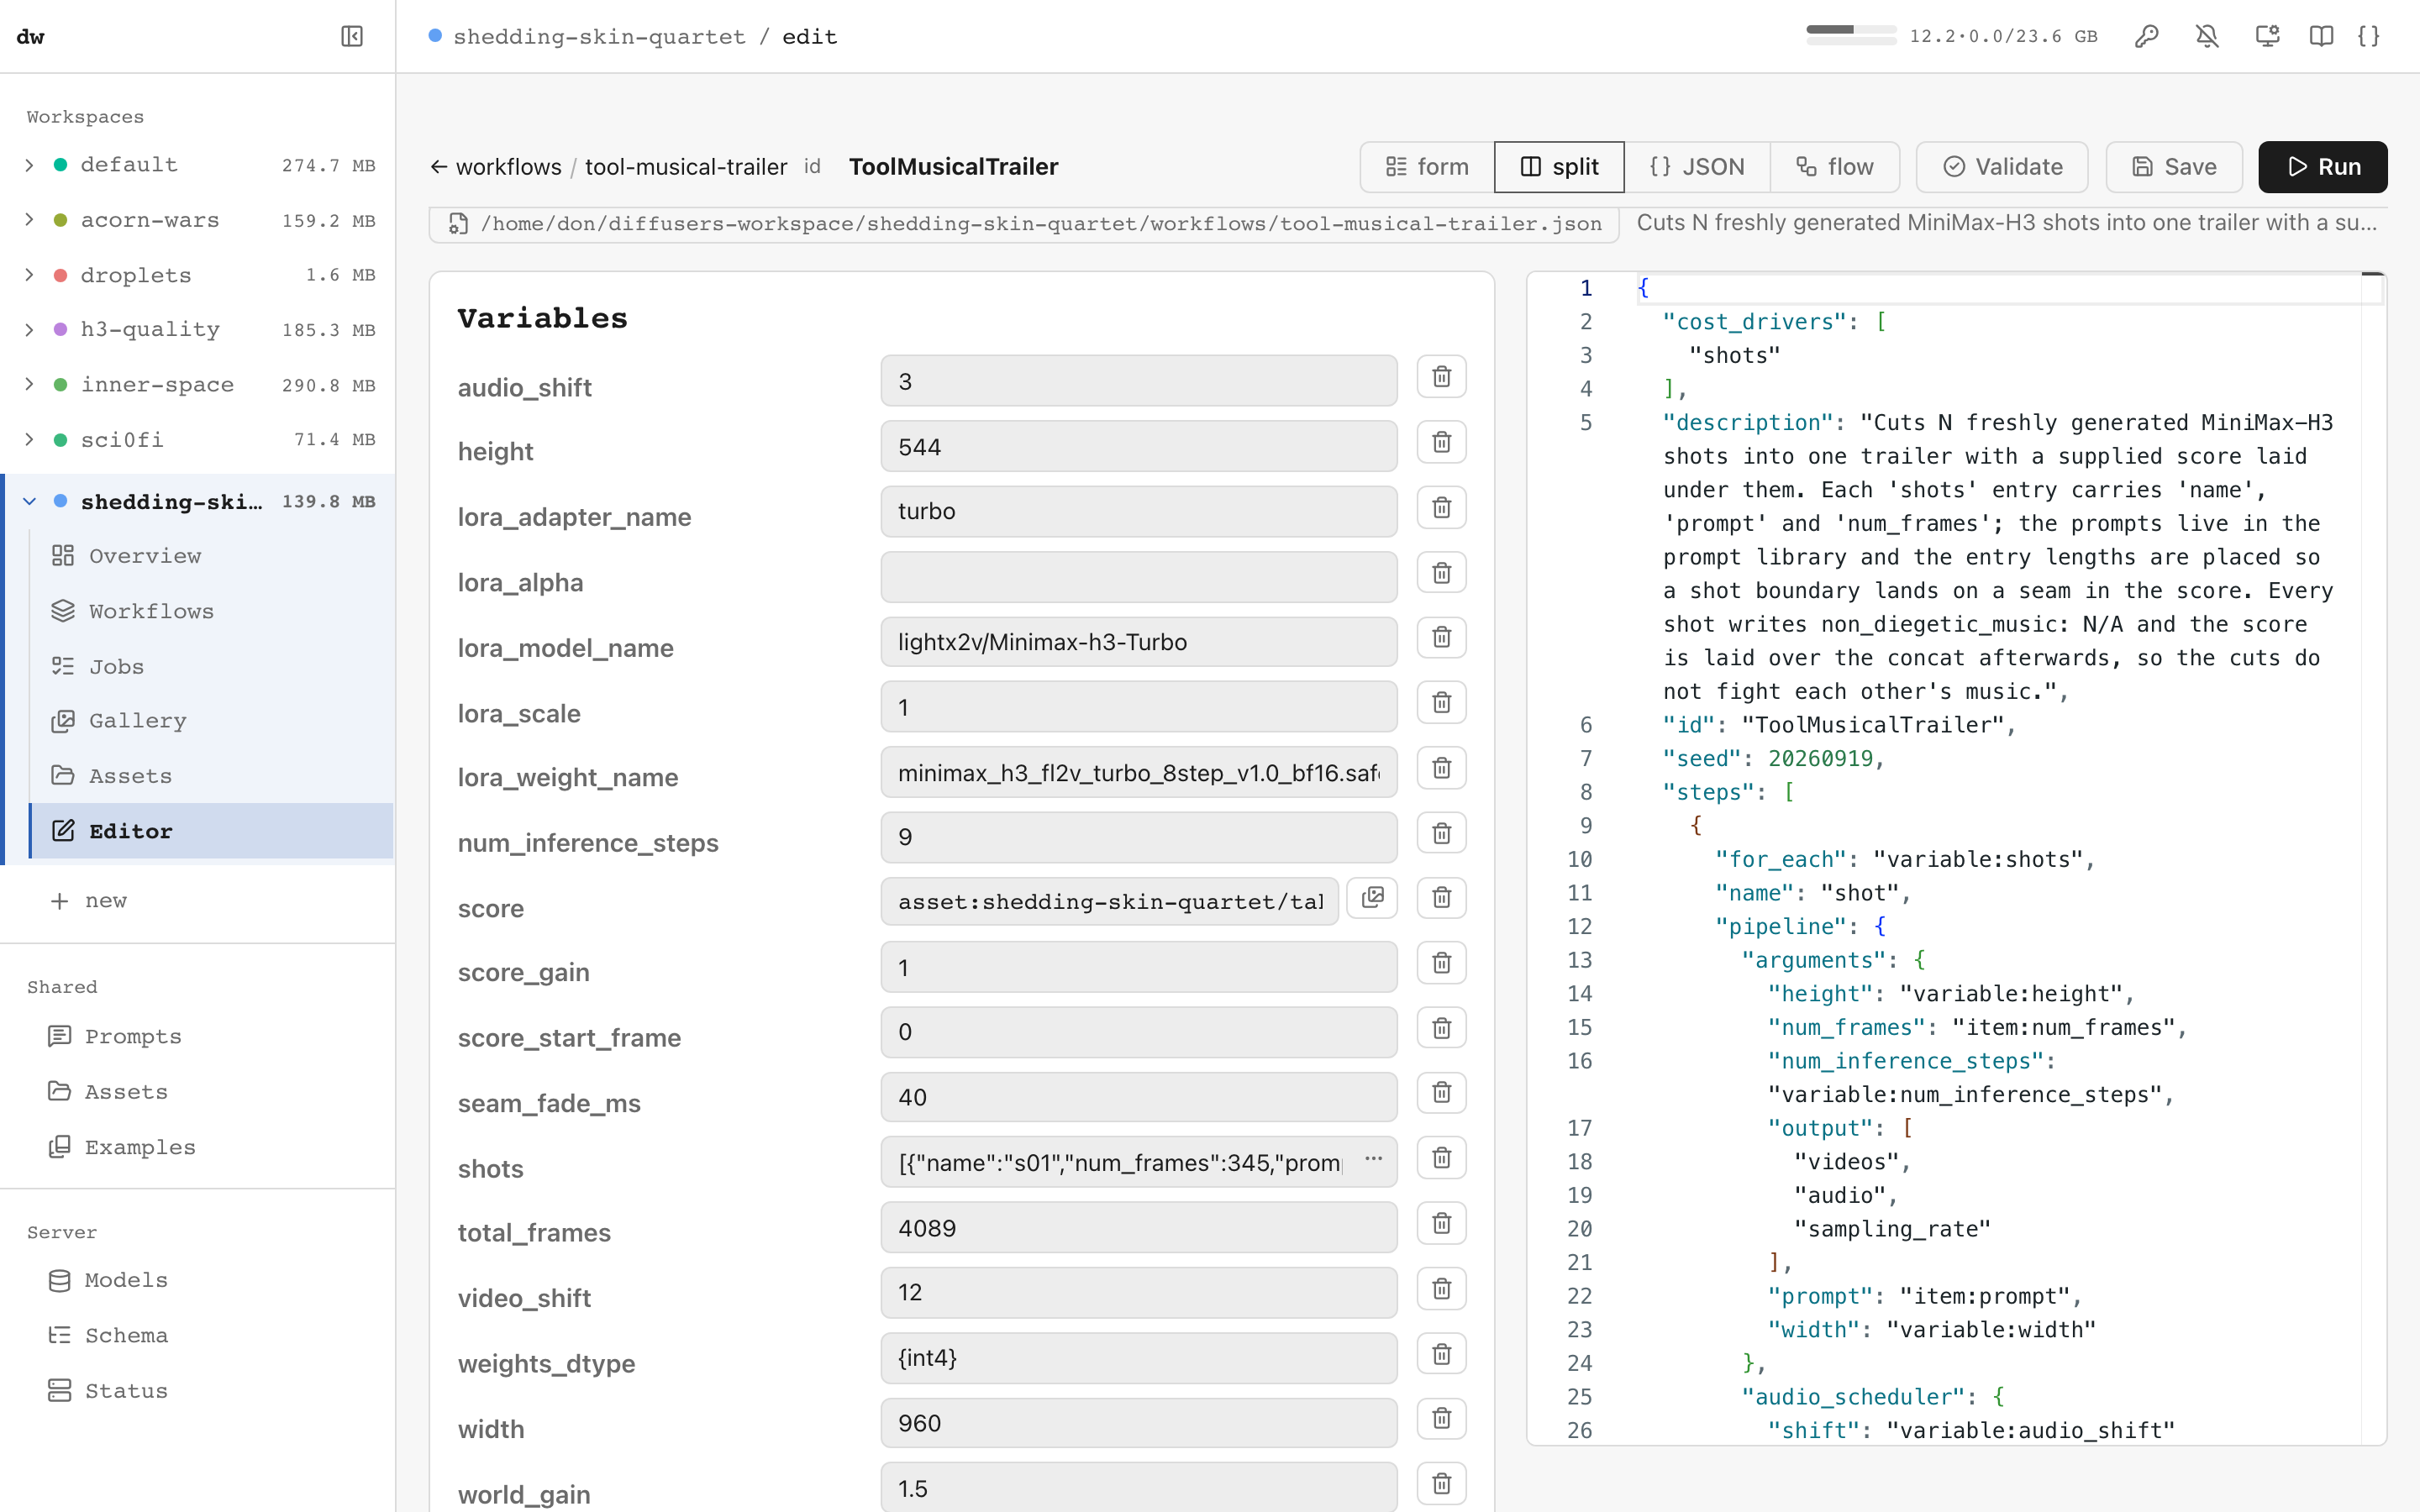
A workflow the agent wrote is a form you can edit. The workflow's description, recent outputs and variables are on one page. Change a prompt, a frame count or a LoRA scale and press Run.
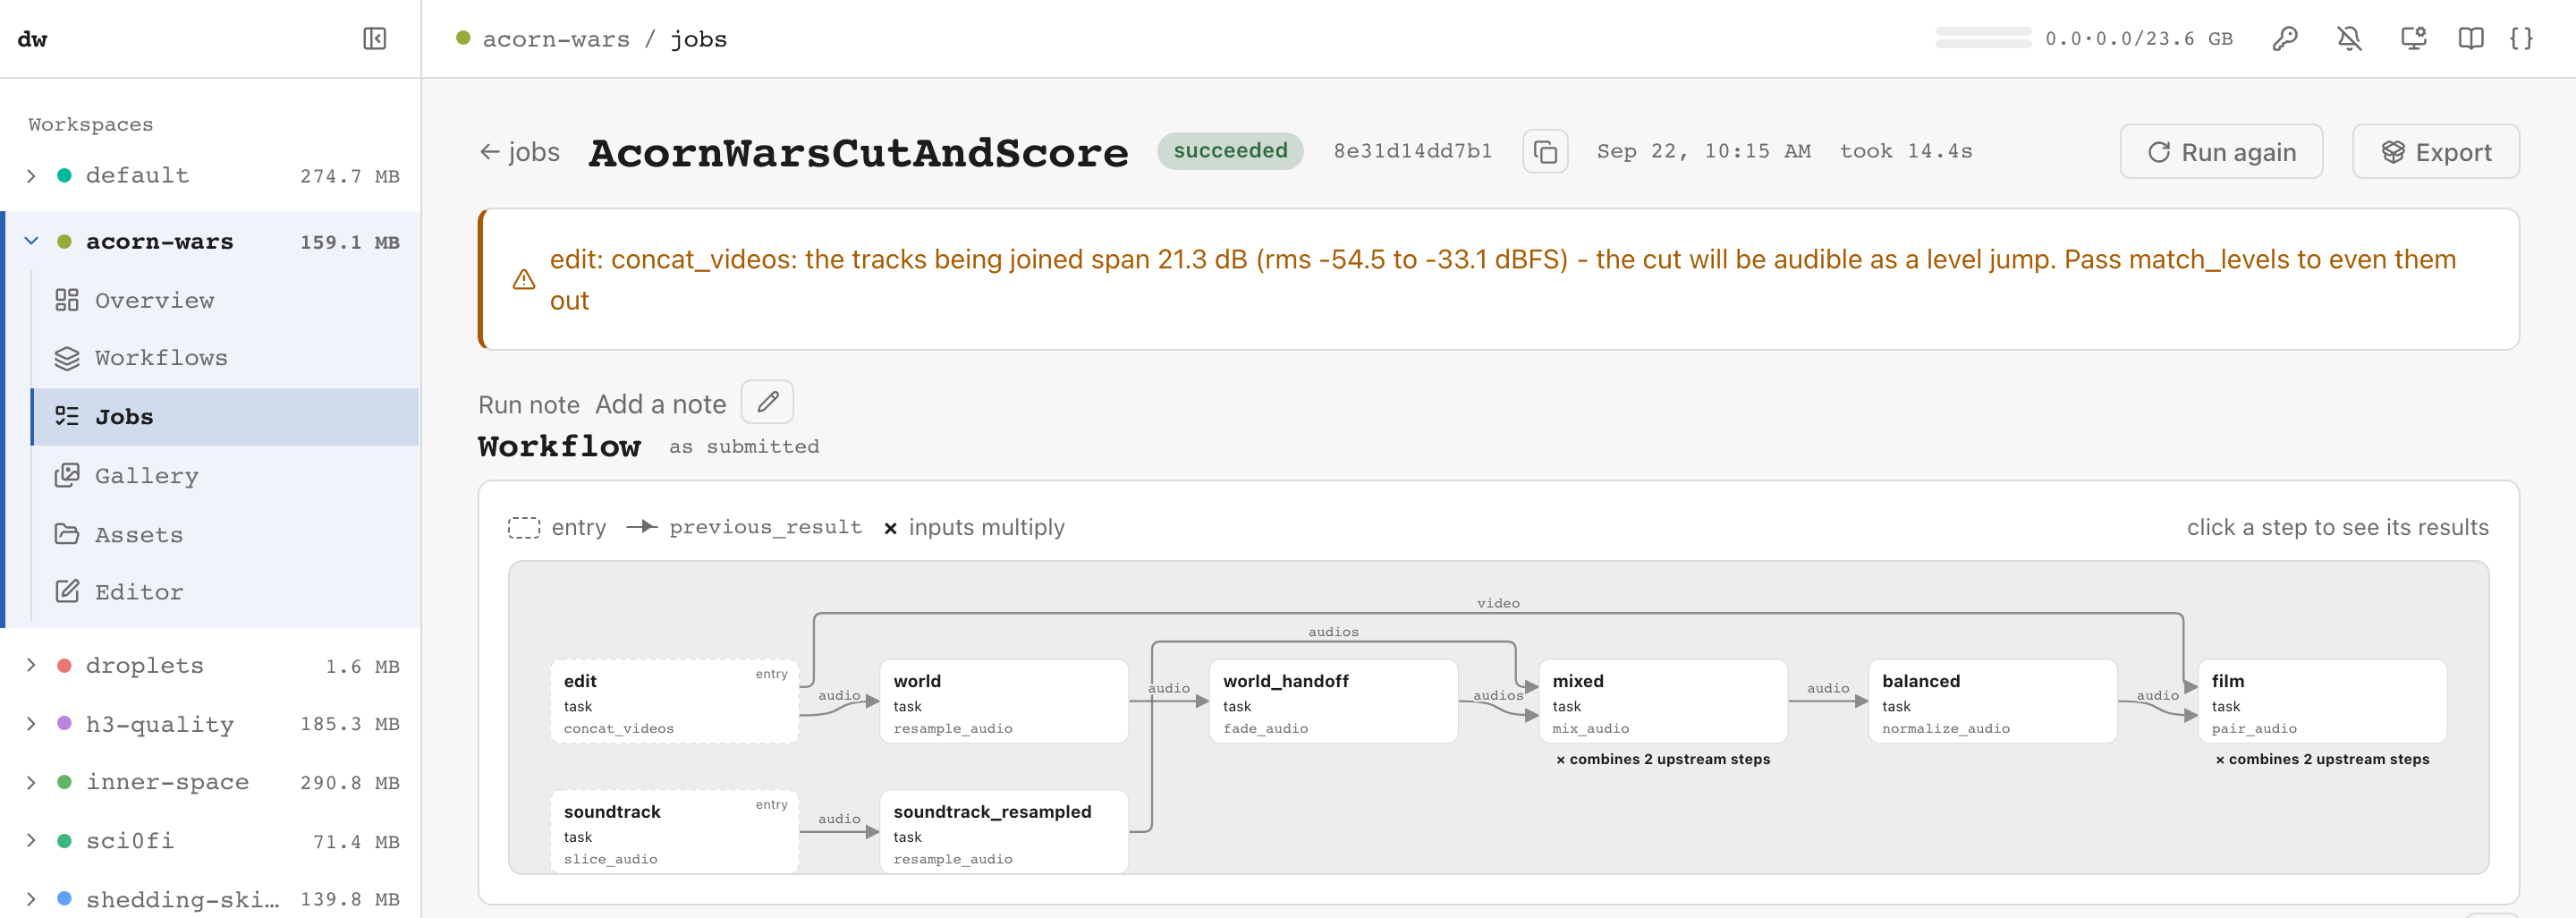
Every job is a recipe. A job keeps the exact workflow it ran and draws it as a graph of how data flows between steps. Click a step to see what it produced. The run's warnings sit above the graph, so a problem the agent missed, such as an audible level jump at a cut, is in front of you with the argument that fixes it. Run again repeats the job, and New seed gives you another take. Progress streams live for each denoising step, and a cancel stops the job cleanly at the next step.
The gallery groups outputs by the workflow that made them, with final and intermediate files kept apart. Any image reopens as the workflow that produced it. Keep as asset adds a file to the asset library for later workflows to use.
The editor works on the agent's JSON. You can view the workflow as a form, as JSON, side by side, or as a flow graph. The forms and autocomplete come from the real diffusers pipeline signatures, so every argument a pipeline takes is there with its documentation. Validate catches schema errors and argument typos before any model loads.
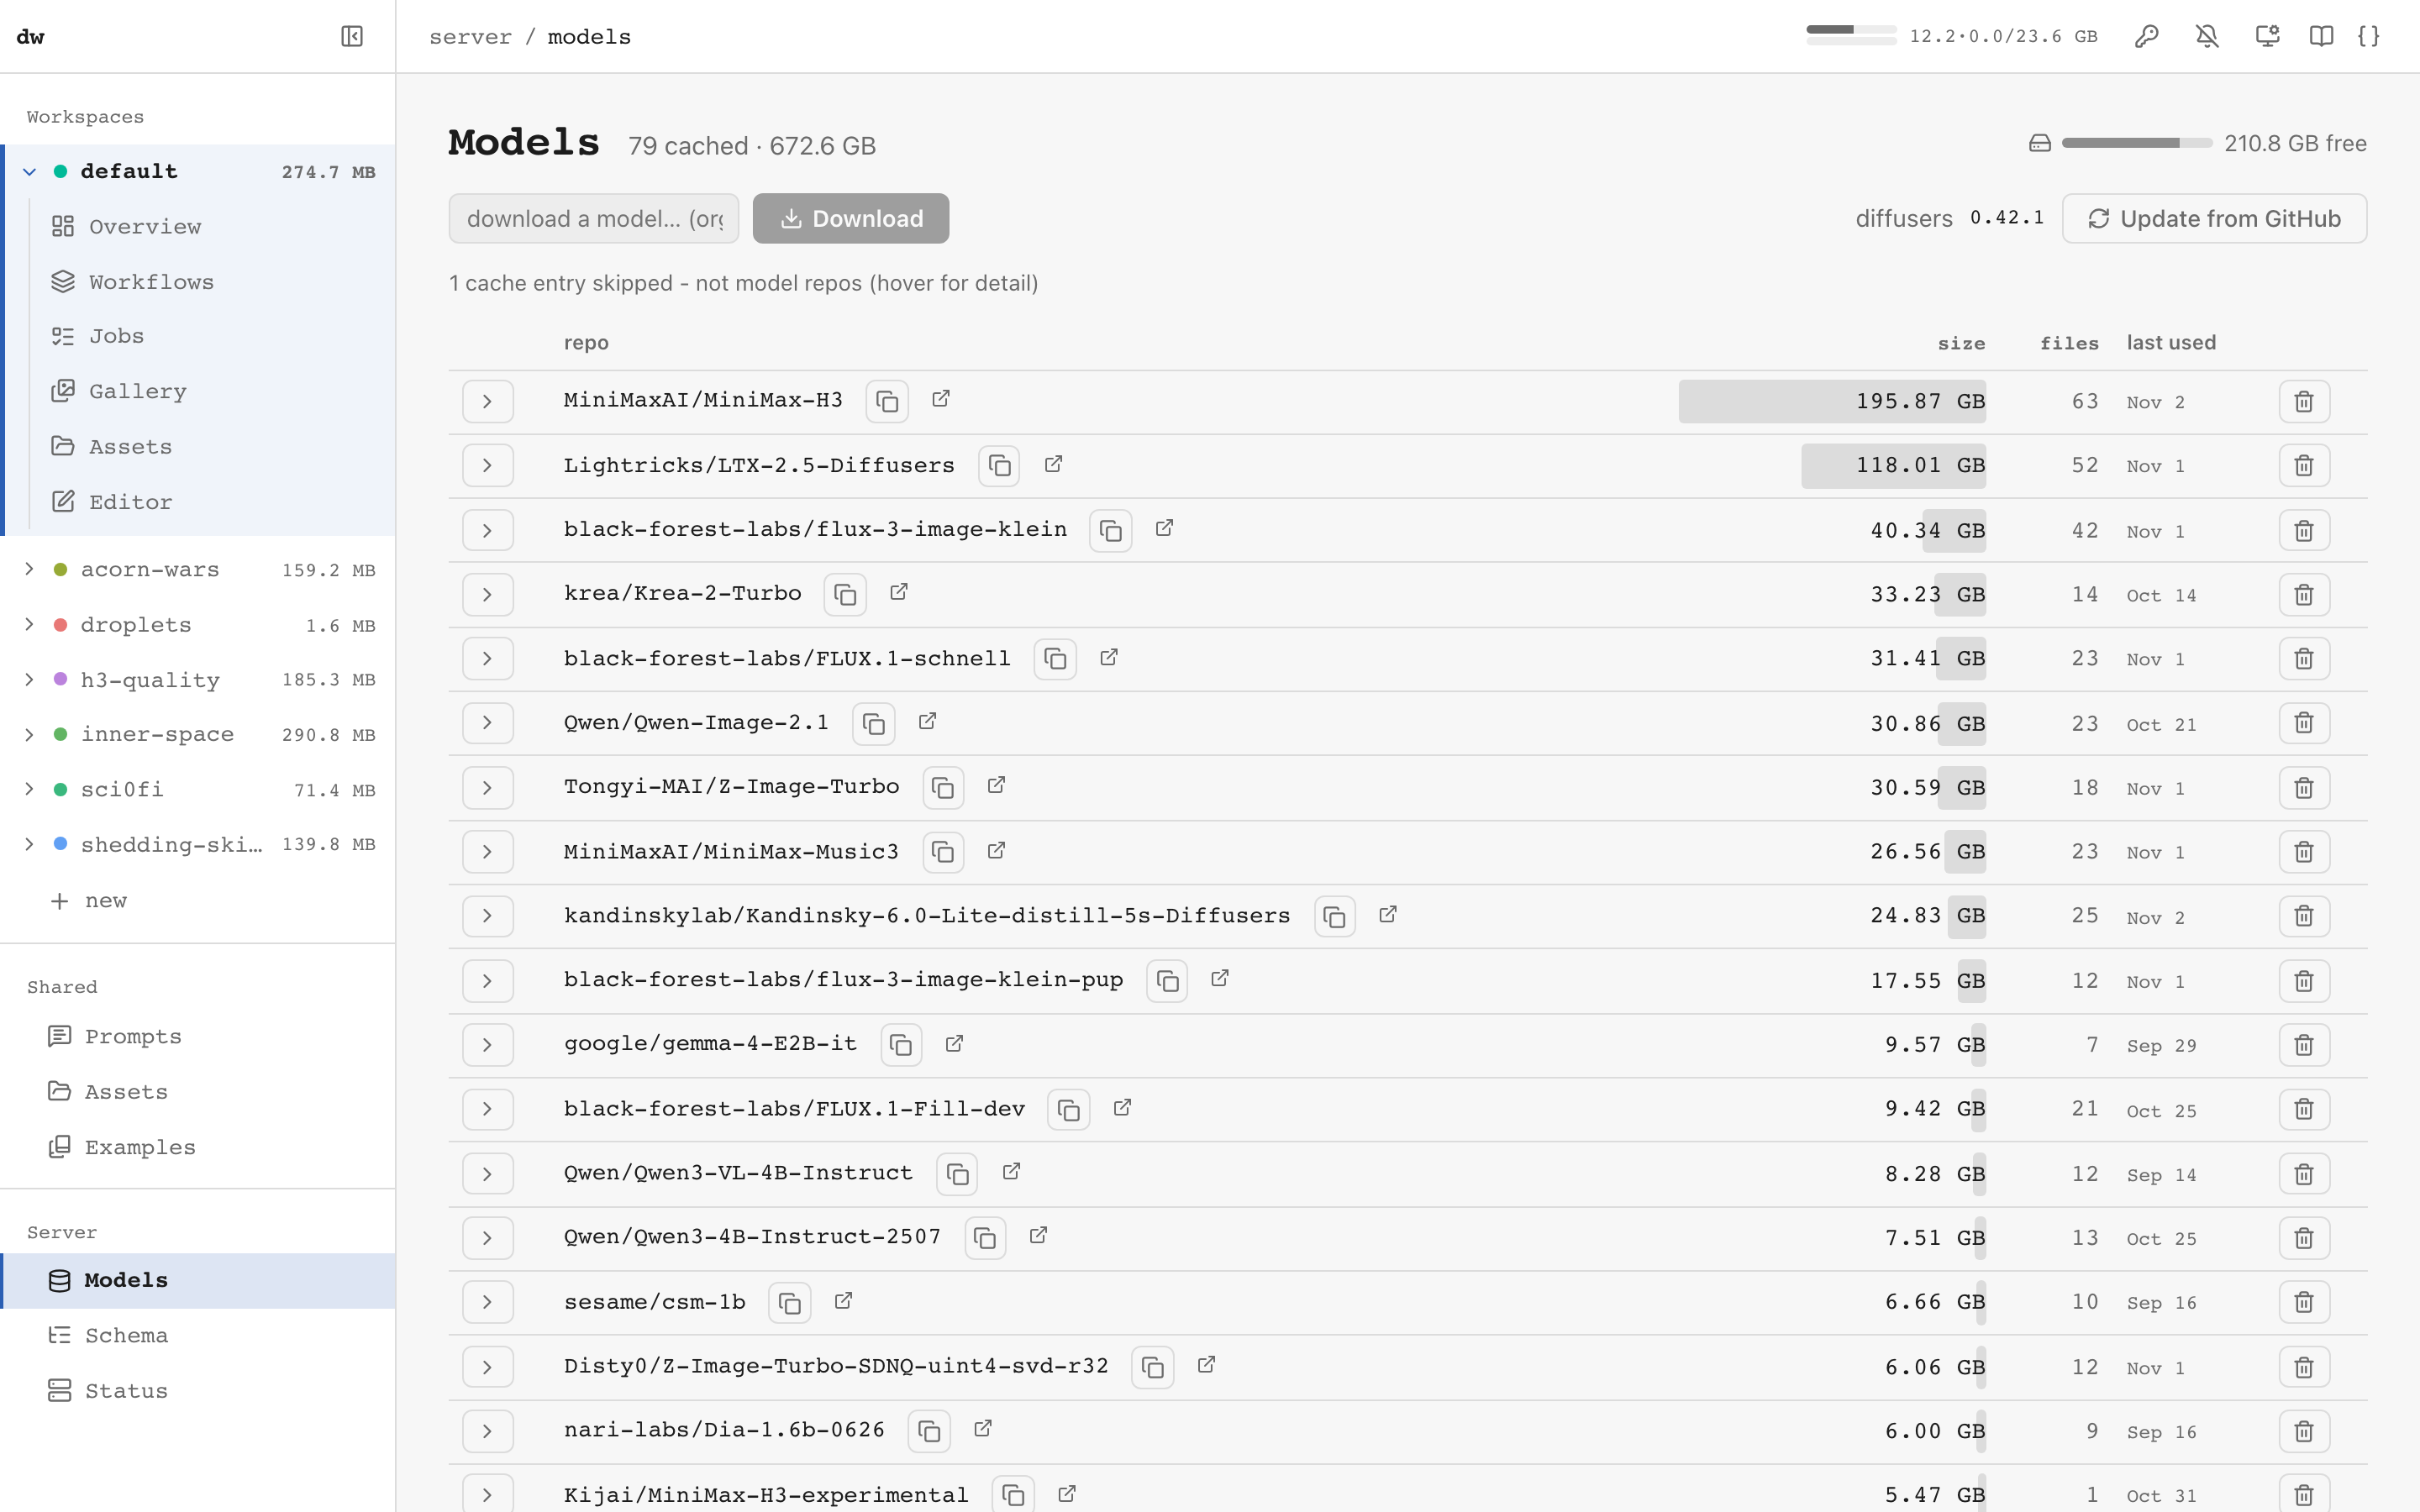
There is also a prompt library, with an Enhance with AI panel that expands an idea into a full prompt using a local language model. The model manager shows the Hugging Face cache (size, last use, free disk) and downloads or deletes models with live progress.
The pages are described in Server & Web UI. The UI and the agent
both use the server's HTTP API, which you can browse at /docs on a running server
(see The HTTP API).
Underneath
Every front end reads and writes the same thing: a JSON workflow of named steps,
each a diffusers pipeline or a utility task. Its arguments are references to
variables, earlier steps' results, stored prompts and assets, not hard-coded
values. That is how text-to-image chains into image-to-video, and how a generated
image reopens as the recipe that made it. You rarely need to write one by hand. When
you do, the Workflow Guide is the reference, the
JSON Schema is the exact structure, and
workflows/ has runnable examples for each model family. There is also
a command-line client, python -m dw.run workflow.json prompt="a cat", which queues
a job on a running server (see Server & Web UI).
The engine also covers:
- Quantization: BitsAndBytes, TorchAO, GGUF, SDNQ and optimum-quanto, set per component.
- Acceleration: FirstBlockCache, FasterCache, MagCache, TaylorSeerCache,
torch.compileand attention backends. - Adapters and prompts: LoRA, IP-Adapter and A1111-style prompt weighting.
- Long video and caching: long-video chaining with audio-driven length, and step-output caching, so re-running a fixed-seed workflow finishes instantly.
- Utility tasks: upscaling, face restoration, segmentation, captioning, frame interpolation, audio slicing, cut-and-score assembly and more.
A workflow can reach any diffusers pipeline or quantization backend by dynamic
import, so loading one can execute arbitrary Python. Treat a workflow file from
someone else the way you'd treat a .py script. See
Trust model.
Field reports. At the end of a session, ask the agent what got in its way, and
have it file each bug or gap as an issue on dkackman/diffusers-workflow with the
field-report label. The label marks a report as coming from real use. A report
from anyone but the maintainer is reviewed before the agent loop
acts on it.
Documentation
Using it
- MCP Server - the agent's tool surface (Claude Code, Claude Desktop, other MCP hosts)
- dw plugin - the model-family and composition skills
- Server & Web UI - the web UI, the command line, and the HTTP API with its OpenAPI spec
- Workspaces - where your content lives, run directories, several workspaces on one server
- Remote GPU server - the server, UI and MCP from another machine
- Docker - the server in a container on a Linux NVIDIA box
Workflows in depth
- Workflow Guide - JSON structure, variables, steps, data flow, references
- Tasks - image, video and audio utility tasks, ControlNet preprocessors
- Quantization - BitsAndBytes, TorchAO, GGUF, SDNQ
- Inference Acceleration - caches,
torch.compile, attention backends, MPS - Fast on 24GB - tested speed/memory settings per model family
- LoRA, IP-Adapter, Prompt Weighting
Reference
- Architecture - each concept, the module that owns it, and the check that enforces it
- Worker Guide - the persistent GPU worker and troubleshooting
- Security - validators and the trust gate (quick reference)
- Dependencies, Testing, Releasing
- Agent Loop - what the automated implementer/tester labels mean
- Attributions - code from other projects, and the projects whose ideas dw reimplemented
Perguntas sobre o MCP diffusers-workflow
Como conecto o MCP server diffusers-workflow ao Claude Code?
Registre o MCP server usando o caminho absoluto para o dw-mcp no seu ambiente virtual, por exemplo: claude mcp add dw -- "$(pwd)/venv/bin/dw-mcp". Certifique-se de usar um caminho absoluto, pois caminhos relativos são o erro de configuração mais comum.
Posso rodar o diffusers-workflow em uma GPU remota ou no Docker?
Sim. Inicie o engine na máquina com GPU usando --mcp e conecte-se via HTTP; não é necessário instalar nada no cliente. No Linux com uma GPU NVIDIA, você também pode rodar a imagem Docker.
Por que minha execução falhou com um erro 401/403 do Hugging Face?
A maioria dos modelos disponibilizados possui acesso restrito (gated). Solicite acesso na página do modelo no Hugging Face e execute hf auth login uma vez. O workflow templates/text-to-image usa um modelo pequeno sem restrições, por isso funciona na primeira execução.
Um agente pode estimar o custo da GPU antes de iniciar um job?
Sim. O validate_workflow verifica o workflow em relação ao schema e às assinaturas do pipeline sem carregar os modelos e fornece uma estimativa em minutos de GPU. Trabalhos que consomem tempo de GPU ou disco exigem que o agente passe pelo acknowledged_cost primeiro.
O que é um MCP server para diffusers?
Ele permite que um cliente MCP como o Claude Code crie, valide e execute fluxos de trabalho de geração de imagem, vídeo e áudio do Diffusers na sua GPU, enquanto você revisa e edita os resultados em uma interface web.