
live-memory MCP server
✓ VerifiedMenyediakan memori codebase yang persisten dan read-only untuk Claude Code guna mengurangi biaya token dan proses pembacaan ulang file.
Juga dikenal sebagai shofer-dev/claude-code-live-memory, claude-code-live-memory, shofer-live-memory
- Stars
- 7
- Tools
- 2
- Unduhan, 30 hari
- 74
- Versi terbaru
- 0.6.0
- Commit terakhir
- 1 Agu 2026
- Lisensi
- Apache-2.0
Apa itu live-memory MCP?
live-memory adalah MCP server. Menyediakan memori codebase yang persisten dan read-only untuk Claude Code guna mengurangi biaya token dan proses pembacaan ulang file. Server ini menyediakan 2 tool, seperti ask_live_memory_submit, ask_live_memory_result.
Ringkasan dibuat dari README proyek
Tentang live-memory MCP server
Live Memory adalah MCP server yang dirancang untuk Claude Code guna menyediakan memori codebase yang persisten dan read-only. Ia berfungsi sebagai singleton berjangka panjang yang mengumpulkan pengetahuan tentang repository Anda di berbagai sesi, memungkinkan AI agent untuk mengajukan pertanyaan alih-alih membaca ulang file secara berulang kali. Pendekatan ini membantu mengurangi biaya token dan mempercepat fase pemahaman dalam tugas-tugas pengembangan.
Server ini berjalan sebagai layanan HTTP independen dan dapat dikonfigurasi untuk menggunakan model lokal atau endpoint apa pun yang kompatibel dengan OpenAI. Bagi pengguna dengan langganan Claude, tersedia setup zero-config menggunakan Haiku via OAuth. Ia belajar secara pasif dengan menggunakan hooks untuk menangkap konten file selama proses read dan edit agent yang biasa, memastikan memori tetap mutakhir seiring perubahan codebase. Sistem ini bersifat path-jailed dan read-only, yang berarti ia tidak dapat memodifikasi atau mengeksekusi file apa pun di workspace Anda.
Apa yang bisa Anda lakukan dengannya
- 1Mengurangi biaya pemahaman codebaseAI agent dapat menggunakan server memori untuk menjawab pertanyaan arsitektur yang luas alih-alih membaca setiap file di dalam repository.
- 2Otomatisasi pembelajaran codebaseSistem membangun pemahamannya tentang proyek Anda secara otomatis dengan mengamati file yang berinteraksi dengan agent Anda.
Ditulis berdasarkan README proyek. Setiap use case diperiksa terhadap kutipan dari README tersebut.
Cara menginstal live-memory MCP
Format diverifikasi 10 Nov 2026Tambahkan ke CursorTambahkan ke GooseInstal live-memory MCP di Claude Code
$ claude mcp add claude-code-live-memory -- uvx shofer-live-memoryInstal live-memory MCP di Cursor
~/.cursor/mcp.json
{
  "mcpServers": {
    "claude-code-live-memory": {
      "command": "uvx",
      "args": [
        "shofer-live-memory"
      ]
    }
  }
}Instal live-memory MCP di VS Code
.vscode/mcp.json
{
  "servers": {
    "claude-code-live-memory": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "shofer-live-memory"
      ]
    }
  }
}Instal live-memory MCP di VS Code CLI
$ code --add-mcp '{"name":"claude-code-live-memory","type":"stdio","command":"uvx","args":["shofer-live-memory"]}'Instal live-memory MCP di Claude Desktop
claude_desktop_config.json
{
  "mcpServers": {
    "claude-code-live-memory": {
      "command": "uvx",
      "args": [
        "shofer-live-memory"
      ]
    }
  }
}Instal live-memory MCP di Codex
$ codex mcp add claude-code-live-memory -- uvx shofer-live-memoryInstal live-memory MCP di Codex config.toml
~/.codex/config.toml
[mcp_servers.claude-code-live-memory]
command = "uvx"
args = ["shofer-live-memory"]
Instal live-memory MCP di Gemini CLI
$ gemini mcp add -s user claude-code-live-memory uvx -- shofer-live-memoryInstal live-memory MCP di Gemini settings.json
~/.gemini/settings.json
{
  "mcpServers": {
    "claude-code-live-memory": {
      "command": "uvx",
      "args": [
        "shofer-live-memory"
      ]
    }
  }
}Tool live-memory MCP 2
Terdeteksi dari READMEask_live_memory_submitask_live_memory_result
| ask_live_memory_submit | — | |
| ask_live_memory_result | — |
Konfigurasi
LIVE_MEMORY_API_KEYLIVE_MEMORY_PRELOAD_GLOBSLIVE_MEMORY_PROVIDER
| Nama | Deskripsi | Tipe |
|---|---|---|
| LIVE_MEMORY_API_KEY | — | |
| LIVE_MEMORY_PRELOAD_GLOBS | — | |
| LIVE_MEMORY_PROVIDER | — |
Pengecekan otomatis
Berjalan 14 Nov 2026Laporan lengkap →Lolos checks otomatis kami. Ini bukan audit keamanan: baca kodenya dan berikan server akses paling terbatas yang dibutuhkannya. Cara kerja checks

- Source repository terhubung dan dapat dijangkaushofer-dev/claude-code-live-memory is public and reachablegithub.com/shofer-dev/claude-code-live-memory ↗Lolos
- Nama paket mencantumkan repositori ini sebagai sumbernyashofer-live-memory names shofer-dev/claude-code-live-memory as sourcepypi.org/project/shofer-live-memory/ ↗Lolos
- Provenance build (atestasi Sigstore)No build attestation published for this releaseTidak diperiksa
- Lisensi open source (OSI)Apache-2.0spdx.org/licenses/Apache-2.0.html ↗Lolos
- Ada commit atau release dalam satu tahun terakhirLast commit or release 2026-08-01github.com/shofer-dev/claude-code-live-memory ↗Lolos
- OpenSSF ScorecardTidak diperiksa
- Nama package tidak mirip dengan package populerNo popular package one edit away from shofer-live-memoryLolos
- Tidak ada advisory kritis pada paket atau dependensinya34 resolved dependencies checked; no critical advisoryosv.dev ↗Lolos
- Tidak ada instruksi tersembunyi untuk model2 tool descriptions and the README read; no override phrases, credential paths or hidden charactersLolos
- Tools yang bersifat destruktif telah diberi labelNo tool named like delete, drop or execLolos
- Endpoint remote merespons handshake MCPTidak diperiksa
README
Lihat di GitHub██╗ ██╗██╗ ██╗███████╗
██║ ██║██║ ██║██╔════╝
██║ ██║██║ ██║█████╗
██║ ██║╚██╗ ██╔╝██╔══╝
███████╗██║ ╚████╔╝ ███████╗
╚══════╝╚═╝ ╚═══╝ ╚══════╝
███╗ ███╗███████╗███╗ ███╗ ██████╗ ██████╗ ██╗ ██╗
████╗ ████║██╔════╝████╗ ████║██╔═══██╗██╔══██╗╚██╗ ██╔╝
██╔████╔██║█████╗ ██╔████╔██║██║ ██║██████╔╝ ╚████╔╝
██║╚██╔╝██║██╔══╝ ██║╚██╔╝██║██║ ██║██╔══██╗ ╚██╔╝
██║ ╚═╝ ██║███████╗██║ ╚═╝ ██║╚██████╔╝██║ ██║ ██║
╚═╝ ╚═╝╚══════╝╚═╝ ╚═╝ ╚═════╝ ╚═╝ ╚═╝ ╚═╝
always-up-to-date codebase memory for Claude Code · ask, don't re-read
Live Memory — Claude Code plugin
A cheap, always-on model that learns your repo — so your agent stops re-reading it.
Live Memory runs a separate, cheap large-context model as a long-lived MCP server that accumulates
knowledge of your codebase across sessions. Instead of re-reading the same files every session, your
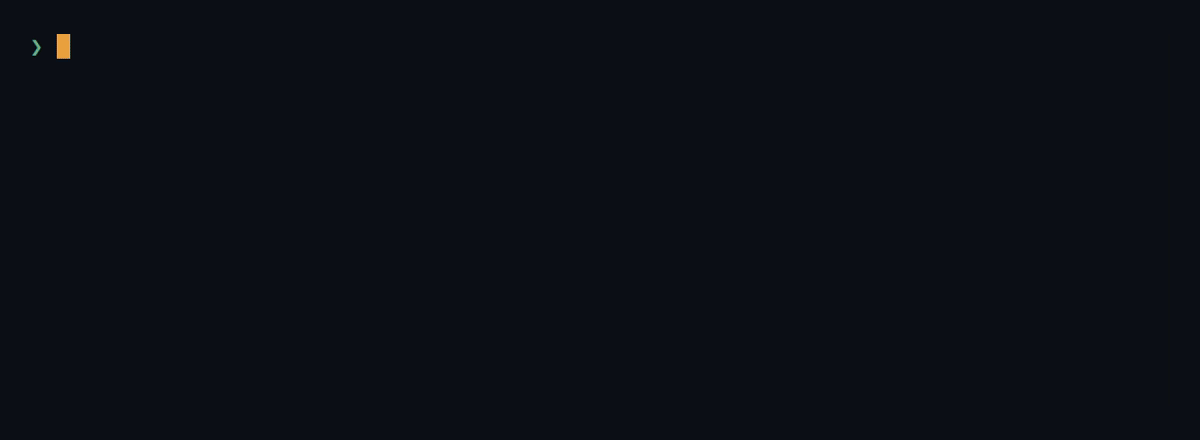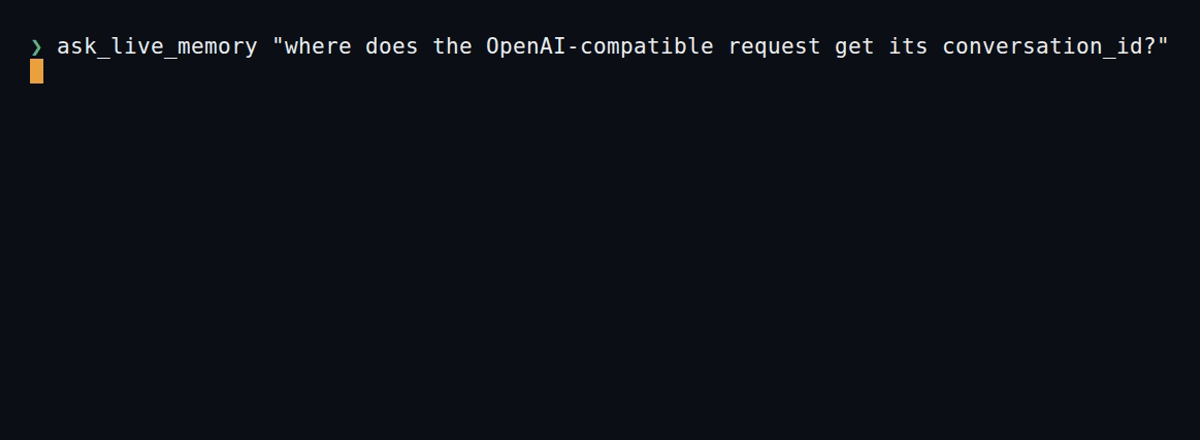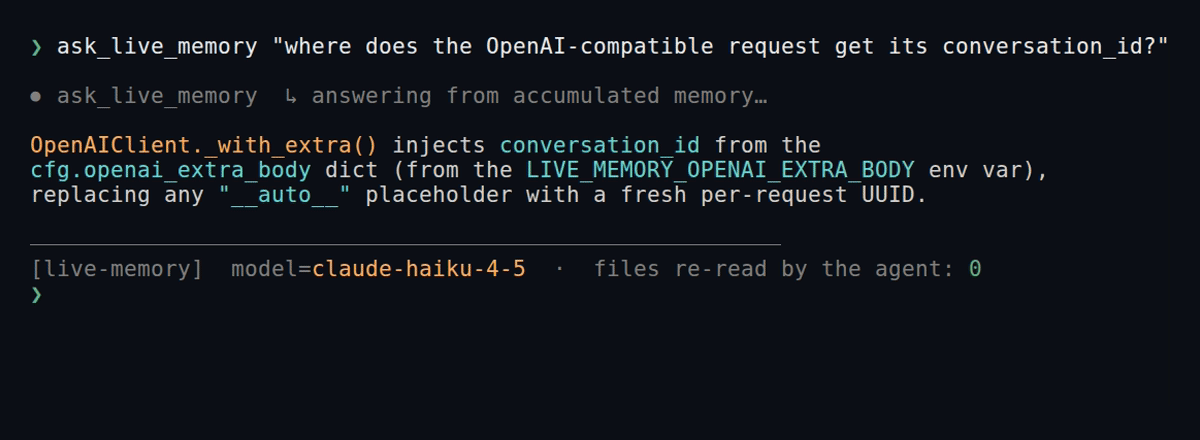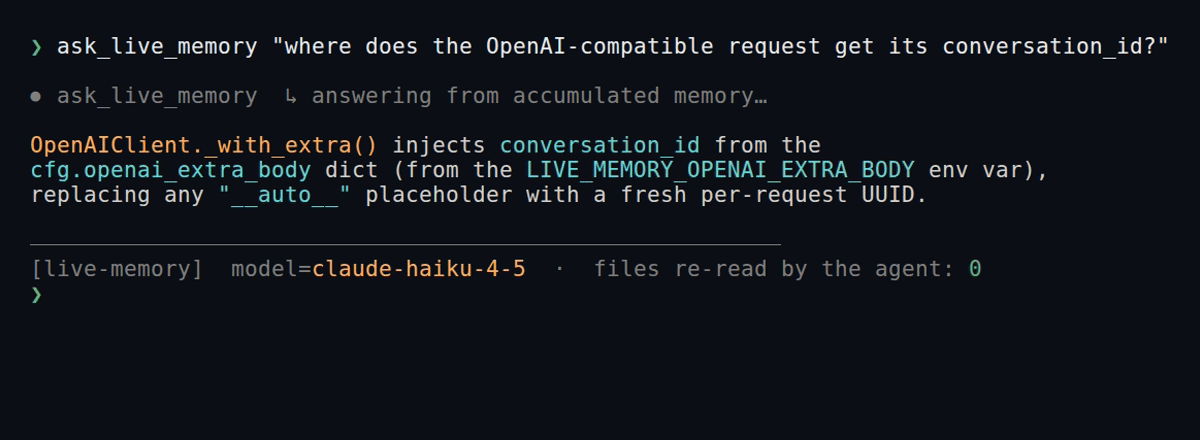
agent asks one read-only tool, ask_live_memory, the broad-understanding questions — "where is X,
how does Y work, what calls Z" — and Live Memory answers in a way that bootstraps the primary agent to
start doing productive work (e.g., edits). It learns passively from your agent's own reads and edits
(teed via hooks — no extra reading) and stays current as the repo changes (modifications and deletions).
Read-only and path-jailed (it can never edit, create, or run anything); zero-config on a Claude
subscription (Haiku, no API key); the memory model is pluggable — point it at a local model or any
OpenAI-compatible endpoint.
How it works
flowchart LR
  repo[("Your repo")]
  subgraph sessions["Claude Code sessions — premium model (many, over time)"]
    agent["Agent"]
  end
  agent -->|"reads / edits files"| repo
  agent -. "PostToolUse / FileChanged hooks<br/>tee file content — passive learning (free)" .-> lm
  agent ==>|"ask_live_memory(question, cwd)<br/>one read-only MCP tool"| lm
  lm ==>|"grounded answer — no file re-reading"| agent
  subgraph server["Live Memory — one MCP server per workspace (singleton)"]
    lm["Cheap / local large-context model<br/>+ accumulating context window<br/>append-only · neutral compaction to a ledger"]
    lm --> snap[("Local JSON snapshot<br/>persists across sessions")]
  end
Your agent reads or edits files as usual; hooks quietly tee that content to the server so it learns
for free. When the agent needs to understand something, it asks ask_live_memory instead of
re-reading — the server answers from its accumulated, per-workspace memory (or reads the code itself,
read-only, if it hasn't seen it yet). One server serves every session and persists across sessions.
Benchmarks
A/B on a real repo, cost per task, run to completion. Cost is shown three ways: the premium (building) model's bill — what your expensive model spends, since the companion runs on a cheap or local model — and all-in, also counting the companion's own cost on DeepSeek-v4-flash or Haiku:
| per task | premium-model bill | all-in · DeepSeek-flash† | all-in · Haiku | faster |
|---|---|---|---|---|
| Understanding-heavy (trace / comprehend) | −61% | −57% | −25% | ~22% |
| Hybrid (understand-then-edit: bug fixes + features) | −28% | −26% | −11% | ~11% |
| Pure edit / execution | ~break-even | ~break-even | ~break-even | ~0 |
Understanding-heavy work also offloads ~93% of the premium model's codebase-reading tokens (with lower
cost variance), and correctness never regressed on the hybrid tasks (12/12 passed with and without
it). DeepSeek-v4-flash matched Haiku's answer accuracy (98% vs 91% over 3 reps) at ~8× lower token
price; a local companion is ≈ free, so all-in ≈ the premium-model bill. Fully reproducible + audited
(human + Fable). Full numbers + methodology: benchmark/results/RESULTS.md.
† companion re-priced at DeepSeek-v4-flash rates (~8× cheaper than Haiku); exact for the understanding case, derived from the measured cost ratio for the hybrid case.
Lineage: Live Memory began as a feature of shofer.dev (Arkware's
parallel multi-agent coding platform), where sessions share an in-sync codebase memory. This is that
idea as a standalone Claude Code plugin — a fresh implementation, self-contained, with no
dependency on shofer. Part of the shofer Claude Code plugin family (with
slang-workflows).
Design: DESIGN.md · How it compares to Copilot/Cursor: COMPARISON.md · Testing: TESTING.md · Privacy: PRIVACY.md.
Quickstart
live-memory is an HTTP MCP server you run once (a singleton that serves every Claude Code session)
plus a plugin that registers ask_live_memory, the hooks, and the slash commands. Start the server
first — Claude Code only connects to it (it never spawns it), so if it isn't running you'll get a
connection error.
1 — Start the server (zero-config on a Claude subscription → Haiku; no API key needed):
git clone https://github.com/shofer-dev/claude-code-live-memory
cd claude-code-live-memory/deploy && ./install-service.sh   # venv + user systemd service, auto-starts on boot
# …or just run it in a terminal:
#   cd claude-code-live-memory/server && pip install -e . && python -m live_memory
2 — Install the plugin (inside a Claude Code session):
/plugin marketplace add shofer-dev/claude-code-live-memory
/plugin install live-memory@shofer-live-memory
Ask your agent a whole-repo question — it'll call ask_live_memory instead of reading files.
/live-memory-stats shows accumulated knowledge + cost · /live-memory-config switches
model/provider · /live-memory-empty wipes memory · /live-memory-reset starts a workspace
over with its configured preload docs re-loaded. Providers, systemd, workspaces, and concurrency
are detailed below.
Shape
live-memory/
├── .claude-plugin/plugin.json     # plugin manifest
├── .mcp.json                      # registers the server (type:http, explicit timeout)
├── hooks/                         # PostToolUse(Read|Write|Edit|…) + FileChanged → TEE file content (passive learning)
│   ├── hooks.json
│   └── notify.py
├── skills/live-memory/SKILL.md    # tells the agent when/why to call ask_live_memory
├── commands/                      # USER-facing slash commands (not agent tools)
│   ├── live-memory-stats.md       # /live-memory-stats  → GET /stats
│   ├── live-memory-config.md      # /live-memory-config → set model/provider, hot-reload
│   ├── live-memory-empty.md       # /live-memory-empty  → wipe memory (this workspace or `all`)
│   ├── live-memory-reset.md       # /live-memory-reset  → drop history + re-preload configured docs
│   ├── stats.py · config.py · empty.py · reset.py
├── settings.json
├── deploy/                        # systemd unit + env example + install-service.sh
└── server/                        # the long-running MCP server (Python, asyncio)
    ├── pyproject.toml             # deps + mypy(strict) + pytest config
    ├── tests/                     # pytest unit suite (mocked; no network)
    └── live_memory/
        ├── __main__.py            # entrypoint: python -m live_memory
        ├── server.py              # MCP (HTTP) ask_live_memory + /health + /stats + /notify + /clear + /reset + /reload
        ├── workspace.py           # per-cwd state registry (window + queue + store); fork/commit
        ├── manager.py             # the agent loop (process one question); compaction
        ├── context_window.py      # budget; file-context evict, Q&A summarize; fork/clone
        ├── summarizer.py          # NEUTRAL, query-agnostic knowledge-ledger summarization
        ├── question_queue.py      # per-workspace admission (serial/parallel) + per-entry timeout
        ├── async_jobs.py          # opt-in fire-and-forget job registry (submit/poll)
        ├── keep_warm.py           # background KV/prompt-cache keep-warm loop
        ├── conversation_store.py  # versioned JSON snapshot (SHA-256 file validation)
        ├── llm_client.py          # provider-pluggable: Anthropic Messages | OpenAI-compatible
        ├── oauth.py               # subscription OAuth credential + auto-refresh (zero-config)
        ├── config.py              # layered config (env > config.json > defaults) + provider knowledge
        ├── constants.py           # ALL tunable magic numbers + defaults, centralized (config sources its defaults here)
        ├── models.py              # core dataclasses (ChatMessage, FileContext, QuestionResult, …)
        ├── tool_executor.py       # read-only tools (Read/Grep/Glob/find_paths/git/…), path-jailed
        ├── preload.py             # configured preload globs → verbatim docs on workspace load
        ├── directory_tree.py      # workspace scan, ~10% context cap
        ├── pricing.py             # per-model USD cost (+ env overrides)
        ├── logging_setup.py       # stderr→journald + optional rotating file
        └── prompts.py             # system prompt + neutral-summary prompt
Architecture (see DESIGN.md for the full rationale)
- One externally-supervised, idempotent HTTP MCP server (singleton) serves all
Claude Code sessions; state is keyed per workspace (
cwd). - Model = independent + provider-pluggable: the server runs its own cheap
model (not the session's). Two adapters cover ~everything — Anthropic Messages
(with
cache_control) and OpenAI-compatible (DeepSeek/OpenAI/gateways). Zero-config: with no key but a Claude subscription, it uses the subscription OAuth token (auto-refreshed) on Haiku. - Passive (organic) learning: PostToolUse/FileChanged hooks tee the content
of the files your agent reads/edits into the memory, so it warms up for free from
real work;
ask_live_memoryis the active fallback for anything unseen. - Preload globs (opt-in):
preload_globs(e.g.docs/*.md) names reference docs loaded verbatim into the system prompt whenever a workspace is (re)loaded — the memory starts out knowing them. They behave like observations: compaction later distills them into the knowledge ledger under pressure./live-memory-resetdrops a workspace's history trail and re-preloads them fresh. - Append-only window between compactions; compaction = batched neutral summarization with a high/low-watermark (rare, batched) — observed files + Q&A distilled into a query-agnostic knowledge ledger — never front-truncation.
- Frozen volatile block + observation deltas (KV-cache preservation): the volatile system block (ledger + preloaded/observed content + manifest) is frozen between compactions and re-sent byte-identical; changes that arrive in between (a teed file, a staleness notice) are appended to the history as delta messages instead of mutating the block — so the provider's prefix cache keeps matching instead of truncating at the first changed byte.
- Two-tier timeout:
ask_live_memory(question, cwd, max_answer_tokens?)blocks up to the server-configured soft budget (default_timeout_s, default 60s — no longer a tool argument) and returns a best-effort answer before the hard.mcp.jsonMCP timeout. - Disclosed answer-length budget: the answer is hard-capped (default
LIVE_MEMORY_MAX_ANSWER_TOKENS) and the model is told the cap, so it self-regulates instead of being truncated mid-sentence; the optionalmax_answer_tokensarg overrides it per question. - Human status via the
/live-memory-statsslash command (→/stats), kept off the agent's tool surface.
Installation
Prerequisites: Python ≥ 3.10; ripgrep (rg) recommended (powers
Grep); git optional (powers git_search / get_changed_files).
1. Install the server:
cd server
pip install -e .          # runtime deps (mcp, anthropic, starlette, uvicorn, watchdog, httpx)
# for development/tests:  pip install -e ".[dev]"   # adds mypy, pytest, pytest-asyncio
2. Install the plugin into Claude Code so it reads .mcp.json, the hooks, the
skill, and the slash commands. The repo root doubles as a single-plugin
marketplace (.claude-plugin/marketplace.json); /plugin install only
installs from a marketplace, never a bare directory — so add the marketplace
first, then install from it. Inside a Claude Code session:
/plugin marketplace add https://github.com/shofer-dev/claude-code-live-memory
/plugin install live-memory@shofer-live-memory
shofer is the marketplace name; live-memory is the plugin name. To install
from a local clone instead, point add at the checkout directory:
/plugin marketplace add /ABSOLUTE/PATH/TO/claude-code-live-memory
/plugin install live-memory@shofer-live-memory
After editing plugin files later, run /plugin marketplace update shofer then
/reload-plugins (installed plugins are cached under ~/.claude/plugins/, so
source edits aren't picked up live).
For local development, skip the marketplace entirely and launch Claude Code
with the plugin loaded directly — this does pick up edits via /reload-plugins:
claude --plugin-dir /ABSOLUTE/PATH/TO/claude-code-live-memory
(The server in step 3 must be running before Claude Code connects — .mcp.json
points at a type:http endpoint Claude Code only connects to, never spawns; if
the server is down you'll see a connection error in /plugin's Errors tab.)
3. Run the server (next section). 4. Dev checks: mypy live_memory/ && pytest.
Running the server
The HTTP transport requires the server to be already running before Claude
Code connects (Claude Code does not start type:http servers) — run it under an
external supervisor (systemd/container/etc.).
Zero-config (no API key): if you're logged into a Claude subscription, it just works — the server reuses that credential (auto-refreshed) on Haiku.
cd server && pip install -e .
python -m live_memory
# serves MCP at http://127.0.0.1:7711/mcp  (+ /health, /stats, /notify, /reload)
The subscription path draws on your subscription's rate-limit budget (not $-metered) — a documented ToS gray area. For an always-on service prefer a key.
Pick any model/provider — env vars or the /live-memory-config slash
command (writes config.json, hot-reloads, no restart):
# DeepSeek (cheap, recommended), via env:
LIVE_MEMORY_PROVIDER=openai LIVE_MEMORY_BASE_URL=https://api.deepseek.com \
  LIVE_MEMORY_API_KEY=sk-... LIVE_MEMORY_MODEL=deepseek-chat  python -m live_memory

# …or at runtime, from inside Claude Code:
/live-memory-config set provider=openai base_url=https://api.deepseek.com model=deepseek-chat api_key=sk-...
/live-memory-config show
Supported providers: anthropic (Messages API + Bedrock/Vertex/gateways, API key
or subscription OAuth) and openai (any OpenAI-compatible endpoint: OpenAI,
DeepSeek, local models, gateways). Then enable the plugin so Claude Code reads
.mcp.json and connects.
Run as a systemd service
deploy/ has the boilerplate. One command registers and starts it:
cd deploy
./install-service.sh            # user service (recommended — see below)
./install-service.sh --system   # system-wide (best for API-key setups)
It creates a venv + installs the server, writes a config at
~/.config/live-memory/live-memory.env (from live-memory.env.example — edit it
for provider/model/key), installs live-memory.service, enables lingering, and
starts it. Config is supplied to the process by systemd via EnvironmentFile=.
- Persistence survives restarts automatically: per-workspace snapshots live
in
LIVE_MEMORY_DATA_DIR(default~/.claude/plugins/data/live-memory), so a restart reloads each workspace's memory on its next query. - Subscription (zero-config) auth needs a user service (the default): it
runs as you, so it can read
~/.claude/.credentials.jsonand reuse your Claude login (auto-refreshed). A--systemservice can also do this, but the unit must setUser=+Environment=HOME=…(the installer does this for you).
systemctl --user status live-memory
journalctl --user -u live-memory -f
systemctl --user restart live-memory     # after editing the env file
Logs
By default the server logs to stderr, which systemd captures into the journal — the idiomatic place, with rotation and unit/PID metadata:
journalctl --user -u live-memory -f          # user service
sudo journalctl -u live-memory -f            # system service
Two caveats and the escape hatch:
- A user service's journal only persists across reboots if journald has
persistent storage (
/var/log/journalexists). If yours is volatile, those logs vanish on reboot. - For a durable, greppable plain-text log regardless, set
LIVE_MEMORY_LOG_FILE(e.g./var/log/live-memory/live-memory.logfor a system service, or an absolute path under~/.local/state/live-memory/for a user one). It's a rotating handler (LIVE_MEMORY_LOG_MAX_BYTES×LIVE_MEMORY_LOG_BACKUPS) and writes in addition to journald.LIVE_MEMORY_LOG_LEVEL(defaultINFO) tunes verbosity.
Workspaces & cwd
Memory is keyed per workspace, from the cwd passed to ask_live_memory.
cwd must be an absolute path (a relative path is rejected — the shared
server can't resolve it against your session). By default the server snaps each
cwd to its enclosing git repo root, so a subdirectory and the repo root
share one memory:
| Env var | Default | Effect |
|---|---|---|
LIVE_MEMORY_CANONICALIZE_WORKSPACE |
true |
Snap cwd to its git repo root. Set false for a distinct memory per exact directory. |
LIVE_MEMORY_REPO_ROOT_MODE |
nearest |
Inside a submodule/worktree: nearest = the submodule's own root (git's default); outermost = the superproject root (fold submodule questions into the parent's memory). |
Preload globs — start out knowing your docs
preload_globs names glob patterns (relative to each workspace root) whose
matching files are read from disk and loaded verbatim into the system prompt
every time a workspace is (re)loaded — reference material the memory knows
before its first question. Preloaded content is treated like an observation:
rendered inline under its own heading until compaction distills it into the
knowledge ledger and sheds the raw bytes under budget pressure.
/live-memory-config set preload_globs=docs/*.md,README.md      # or:
LIVE_MEMORY_PRELOAD_GLOBS="docs/*.md,README.md"
| Env var | Default | Effect |
|---|---|---|
LIVE_MEMORY_PRELOAD_GLOBS |
(empty) | Comma-separated globs (relative to the workspace root, ** supported) preloaded verbatim on workspace load. Absolute patterns and matches escaping the workspace (symlinks) are skipped, as are binary files. |
LIVE_MEMORY_PRELOAD_MAX_TOTAL_BYTES |
2097152 |
Total cap across all preloaded files per workspace (per-file cap is LIVE_MEMORY_PASSIVE_MAX_FILE_BYTES). The effective cap is additionally clamped to the window budget (compaction_floor × LIVE_MEMORY_MAX_CONTEXT_TOKENS) — preloading past the floor would just make the first question distill + shed the docs immediately. To preload a corpus bigger than ~300 KB, raise LIVE_MEMORY_MAX_CONTEXT_TOKENS too. |
Notes:
- Preload runs when a workspace is loaded — its first query after a server
start,
/live-memory-empty, or a config change. A glob change via/live-memory-configapplies to already-loaded workspaces on their next reset/restart, not retroactively. /live-memory-resetstarts a workspace over in one step: it drops the current history trail (Q&A history, knowledge ledger, file manifest — memory and on-disk snapshot) and immediately re-preloads the configured globs fresh from disk. Use it when the accumulated trail has gone stale but you want the verbose reference docs back. (/live-memory-emptyis the same wipe without the eager re-preload — the docs still load lazily on the next question.)
Monitoring scope (file_globs) and the question timeout
| Env var / config key | Default | Effect |
|---|---|---|
LIVE_MEMORY_FILE_GLOBS / file_globs |
(empty — monitor everything) | Comma-separated fnmatch patterns (workspace-relative; * also crosses /). When set, the file-change feed — passive ingestion, stale/deleted tracking, modified hints — applies only to matching paths; everything else is dropped at the workspace boundary. Pair it with preload_globs for a docs-only memory: /live-memory-config set preload_globs=docs/*.md file_globs=docs/*.md. |
LIVE_MEMORY_DEFAULT_TIMEOUT_S / default_timeout_s |
60 |
The soft per-question time budget. ask_live_memory no longer takes a timeout argument — callers get this configured budget; the model is told it and returns a best-effort answer at the deadline. Keep it below the hard .mcp.json MCP timeout. |
Scoping matters for cache stability too: an unscoped feed tees every file your agents touch, and each new observation is a delta the next question must carry. A docs-only scope keeps the memory focused and its prompt small.
Concurrency
Questions to the same workspace are admitted by one of two models:
| Env var | Default | Effect |
|---|---|---|
LIVE_MEMORY_CONCURRENCY |
parallel |
parallel (default) = no queue delay — each question forks the window, up to MAX_PARALLEL_QUERIES run at once, and the fork that explored the most codebase commits back (others still return their answer but don't update shared memory). serial = one question at a time per workspace (shared window grows in place; strongest cache locality, concurrent callers wait). |
LIVE_MEMORY_MAX_PARALLEL_QUERIES |
4 |
Max concurrent questions per workspace in parallel mode. |
(Questions to different workspaces always run concurrently, regardless of this setting.)
Async (fire-and-forget) tools — opt-in
MCP tool calls block the caller's turn until they return. If you want the agent
to submit a slow query, keep working, and collect the answer later, set
LIVE_MEMORY_ASYNC_TOOLS=true to additionally expose:
ask_live_memory_submit(question, cwd)→ returns ajob_idimmediately.ask_live_memory_result(job_id)→ the answer when ready, or[running]to poll again.
The agent drives the polling (Claude Code can't push completion into a running
turn). Off by default; ask_live_memory (synchronous) is always available.
Cache keep-warm
Off by default — opt in with LIVE_MEMORY_KEEP_WARM=true, or via the slash
command: /live-memory-config set keep_warm=true. A background loop pings each
recently-active workspace's prefix (max_tokens=1, output discarded) so the
provider's KV/prompt cache doesn't go cold between questions — keeping the next
real query on cache-hit pricing instead of a full cold re-read. The heartbeat
interval is provider knowledge: 4 minutes (240s) for Anthropic/OpenAI (just
under their minute-scale cache TTLs), and auto-set very long for DeepSeek
(its disk cache lasts hours/days, so even enabled it self-disables there).
Override with LIVE_MEMORY_KEEP_WARM_INTERVAL_S /
/live-memory-config set keep_warm_interval_s=…, or stop warming idle
workspaces sooner with LIVE_MEMORY_KEEP_WARM_MAX_IDLE_S.
/live-memory-stats shows when the cache was last refreshed.
Pertanyaan tentang live-memory MCP
Bagaimana cara menambahkan live-memory MCP ke Claude Code?
Jalankan claude mcp add claude-code-live-memory -- uvx shofer-live-memory di terminal Anda. Tambahkan --scope user agar tersedia di semua proyek.
Bagaimana cara menambahkan live-memory MCP ke Cursor?
Buka ~/.cursor/mcp.json dan tambahkan server di bawah mcpServers, menggunakan config Cursor yang ditunjukkan di bagian instalasi di atas.
Tool apa yang disediakan live-memory MCP?
Server ini menyediakan 2 tool, termasuk ask_live_memory_submit, ask_live_memory_result.
Bagaimana Live Memory mempelajari codebase saya?
Ia belajar secara pasif melalui hooks yang menyalin konten file dari aktivitas read dan edit agent Anda, serta melalui tool aktif 'ask_live_memory'.
Apakah tool memori ini aman digunakan dengan file saya?
Ya, tool ini bersifat read-only dan path-jailed, yang berarti ia tidak dapat mengedit, membuat, atau menjalankan apa pun di dalam repository Anda.
Apakah saya memerlukan API key untuk menggunakannya dengan Claude?
Jika Anda memiliki langganan Claude, tool ini dapat bekerja tanpa konfigurasi menggunakan token OAuth langganan Anda pada Haiku.