
Menyediakan pipeline memori persisten bagi AI agent untuk menyimpan, mengambil, merangkum, dan memangkas interaksi guna menjaga konteks tanpa membengkakkan penggunaan token.
Juga dikenal sebagai isiomaC/memstack, @memstack/mcp
- Stars
- 0
- Tools
- —
- Unduhan, 30 hari
- —
- Versi terbaru
- 0.8.5
- Commit terakhir
- 1 Nov 2026
- Lisensi
- MIT
Apa itu MemStack MCP?
MemStack adalah MCP server. Menyediakan pipeline memori persisten bagi AI agent untuk menyimpan, mengambil, merangkum, dan memangkas interaksi guna menjaga konteks tanpa membengkakkan penggunaan token.
Ringkasan dibuat dari README proyek
Tentang MemStack MCP server
MemStack menyediakan pipeline memori persisten yang dirancang untuk membantu AI agent menjaga konteks tanpa meningkatkan biaya token. Sistem ini berfungsi sebagai lapisan tengah antara agent dan large language model, mengelola siklus hidup informasi melalui proses penyimpanan, pengambilan, perangkuman, dan pemangkasan interaksi. Sistem ini sangat berguna bagi developer yang menggunakan coding agent seperti Claude Code dan Codex, karena memungkinkan berbagai agent untuk berbagi satu memori yang sama per proyek.
Anda dapat mengimplementasikannya melalui command line interface atau dengan mengintegrasikan core SDK ke dalam aplikasi Anda sendiri. Server ini mendukung berbagai provider LLM termasuk OpenAI, DeepSeek, dan Gemini melalui adapter yang bersifat pluggable. MemStack menangani tugas manajemen memori yang kompleks seperti recency weighting, importance scoring, dan deduplikasi otomatis. Karena bersifat open source dan memungkinkan penggunaan custom storage serta embedding adapter, developer memiliki kontrol penuh atas data dan infrastruktur mereka tanpa adanya vendor lock-in.
Apa yang bisa Anda lakukan dengannya
- 1Sinkronisasi pengetahuan antar coding agentMemastikan bahwa konvensi yang dipelajari dalam satu sesi agent dapat segera digunakan oleh agent lain yang mengerjakan proyek yang sama.
- 2Mengelola konteks agent jangka panjangMencegah pembengkakan context window dengan mengompresi interaksi lama menjadi ringkasan dan menghapus data yang sudah tidak relevan.
- 3Membangun chatbot dengan fitur memori kustomMengintegrasikan subsystem memori ke dalam bot support untuk mengingat masalah spesifik pengguna dan laporan error sebelumnya.
- 4Implementasi penyimpanan memori yang amanMelindungi informasi sensitif dengan menggunakan sistem yang secara otomatis menolak untuk menyimpan kredensial atau rahasia.
Ditulis berdasarkan README proyek. Setiap use case diperiksa terhadap kutipan dari README tersebut.
Cara menginstal MemStack MCP
Format diverifikasi 10 Nov 2026Tambahkan ke CursorTambahkan ke GooseInstal MemStack MCP di Claude Code
$ claude mcp add memstack -- npx -y @memstack/mcpInstal MemStack MCP di Cursor
~/.cursor/mcp.json
{
  "mcpServers": {
    "memstack": {
      "command": "npx",
      "args": [
        "-y",
        "@memstack/mcp"
      ]
    }
  }
}Instal MemStack MCP di VS Code
.vscode/mcp.json
{
  "servers": {
    "memstack": {
      "type": "stdio",
      "command": "npx",
      "args": [
        "-y",
        "@memstack/mcp"
      ]
    }
  }
}Instal MemStack MCP di VS Code CLI
$ code --add-mcp '{"name":"memstack","type":"stdio","command":"npx","args":["-y","@memstack/mcp"]}'Instal MemStack MCP di Claude Desktop
claude_desktop_config.json
{
  "mcpServers": {
    "memstack": {
      "command": "npx",
      "args": [
        "-y",
        "@memstack/mcp"
      ]
    }
  }
}Instal MemStack MCP di Codex
$ codex mcp add memstack -- npx -y @memstack/mcpInstal MemStack MCP di Codex config.toml
~/.codex/config.toml
[mcp_servers.memstack]
command = "npx"
args = ["-y", "@memstack/mcp"]
Instal MemStack MCP di Gemini CLI
$ gemini mcp add -s user memstack npx -- -y @memstack/mcpInstal MemStack MCP di Gemini settings.json
~/.gemini/settings.json
{
  "mcpServers": {
    "memstack": {
      "command": "npx",
      "args": [
        "-y",
        "@memstack/mcp"
      ]
    }
  }
}Pengecekan otomatis
Berjalan 14 Nov 2026Laporan lengkap →Lolos checks otomatis kami. Ini bukan audit keamanan: baca kodenya dan berikan server akses paling terbatas yang dibutuhkannya. Cara kerja checks

- Source repository terhubung dan dapat dijangkauisiomac/memstack is public and reachablegithub.com/isiomac/memstack ↗Lolos
- Nama paket mencantumkan repositori ini sebagai sumbernya@memstack/mcp names isiomac/memstack as sourcenpmjs.com/package/@memstack/mcp ↗Lolos
- Provenance build (atestasi Sigstore)Sigstore attestation for @memstack/mcpnpmjs.com/package/@memstack/mcp/v/0.8.5#provenance ↗Lolos
- Lisensi open source (OSI)MITspdx.org/licenses/MIT.html ↗Lolos
- Ada commit atau release dalam satu tahun terakhirLast commit or release 2026-11-01github.com/isiomac/memstack ↗Lolos
- OpenSSF ScorecardTidak diperiksa
- Nama package tidak mirip dengan package populerNo popular package one edit away from @memstack/mcpLolos
- Tidak ada advisory kritis pada paket atau dependensinya100 resolved dependencies checked; no critical advisoryosv.dev ↗Lolos
- Tidak ada instruksi tersembunyi untuk model0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersLolos
- Tools yang bersifat destruktif telah diberi labelTidak diperiksa
- Endpoint remote merespons handshake MCPTidak diperiksa
README
Lihat di GitHubMemStack
Persistent memory for AI agents. Claude Code and Codex share one memory per project, and your own agents get the same pipeline: store, retrieve, summarize, and prune.
Website and install guides: memstack.stalewell.com



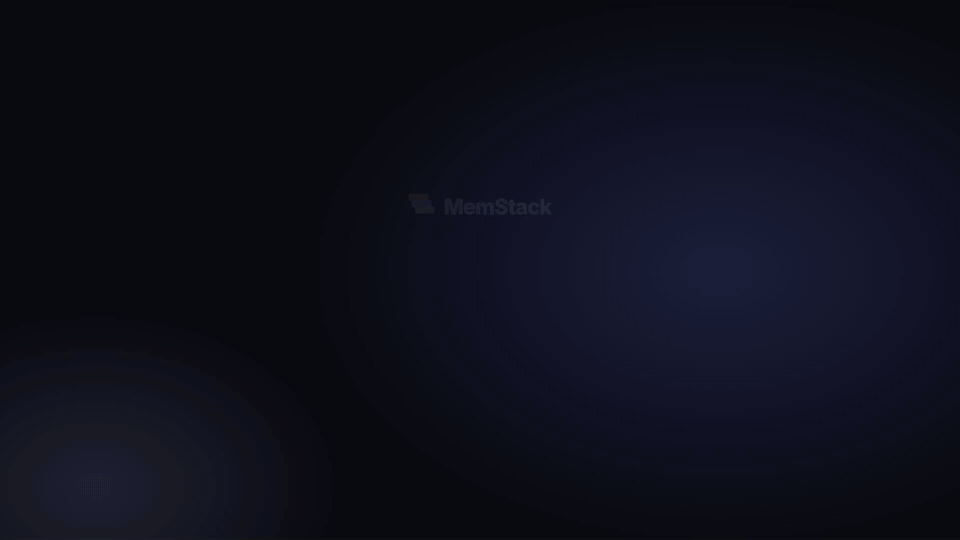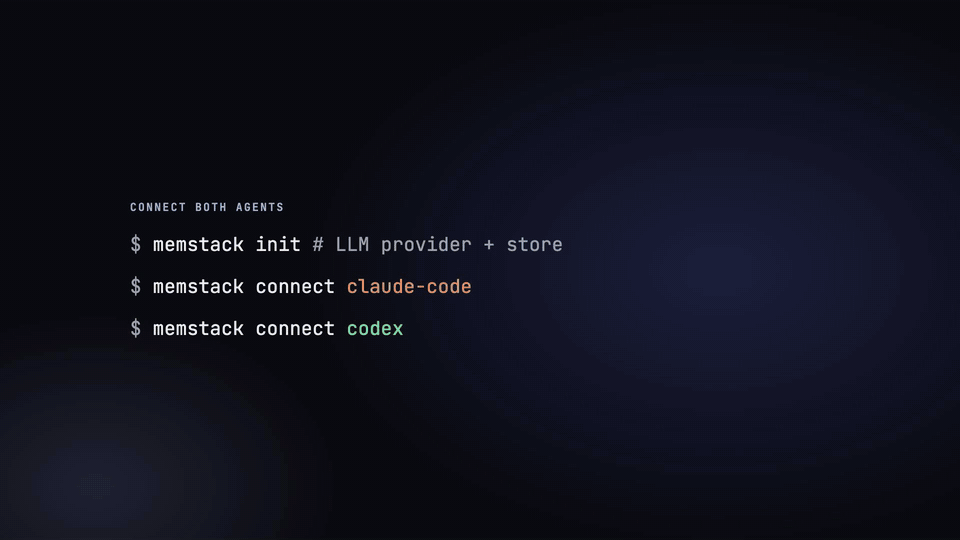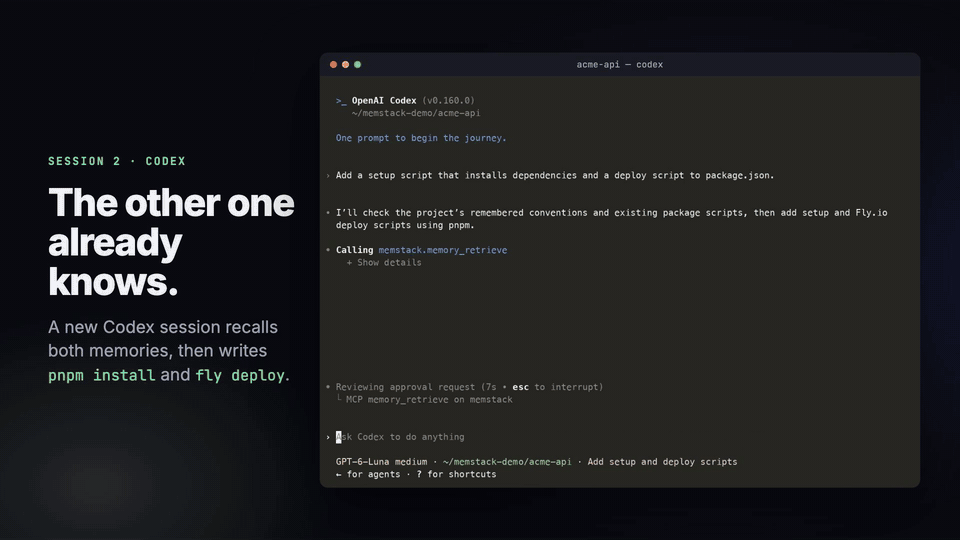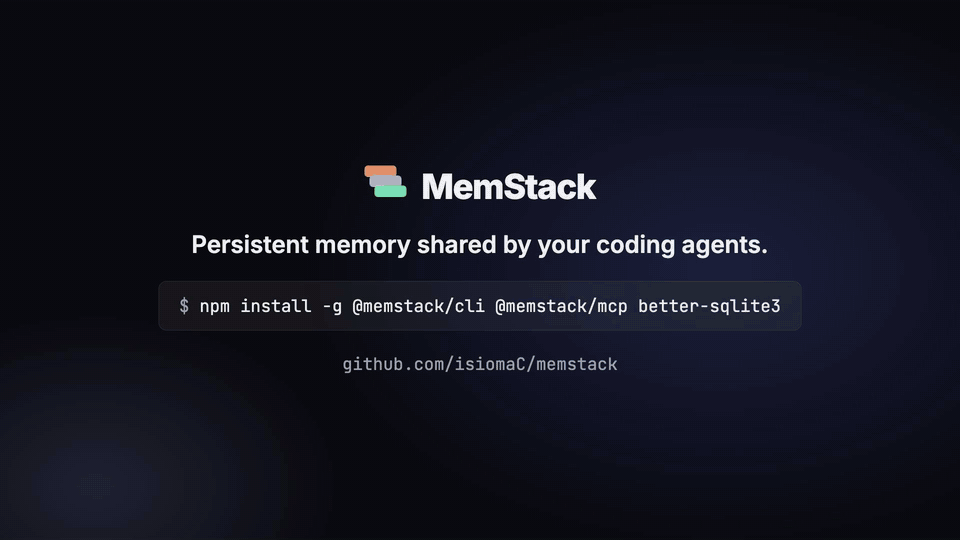
Tell one agent how your project works. The other already knows. Claude Code learns a convention; a new Codex session recalls it and gets the task right:
npm install -g @memstack/cli @memstack/mcp better-sqlite3@^11.10.0   # MemStack never installs storage drivers
memstack init                  # LLM provider (optional) + store
memstack connect claude-code
memstack connect codex
Every session then starts with the project's key memories, and both agents save what you ask them to remember. How harness memory works.
Building your own agent?
# Use MemStack in your application
npm install @memstack/core

# Give your coding agents the MemStack skill (-g: every project; omit it for this project only)
npx skills add isiomaC/memstack -g
@memstack/core is the runtime SDK; the Agent Skill teaches compatible coding agents how to integrate and operate MemStack correctly. Without -g, the skill installs into the current project (.agents/skills/, plus a .claude/skills/ link for Claude Code). Update it later with npx skills update.
The problem: AI agents forget. Every interaction starts from zero. You either stuff everything into the context window (expensive, slow, degrades output quality) or the agent has no memory of past conversations.
What MemStack does: A persistent memory pipeline that lives between your agent and the LLM. It stores every interaction, retrieves only what's relevant, summarizes old memories to save tokens, and prunes stale ones automatically. One method call, no infrastructure required.
Think of it as the open-source alternative to Mem0 — pluggable storage, bring your own LLM, zero vendor lock-in.

Table of Contents
- Why MemStack
- Quick Start
- Harness Memory (Claude Code & Codex)
- The Memory Pipeline
- Real-World Use Cases
- Memory Type Reference
- Retrieval Strategies
- Embeddings
- Adapters
- Full API Reference
- Configuration
- Advanced Usage
- LongMemEval-S Retrieval Benchmark
- Development
- Publishing to npm
- Contributing
- License
Why MemStack
LLMs have context windows, not memory. The difference matters.
| Approach | Problem |
|---|---|
| Stuff everything in context | Cost is O(n²). 100 conversations = thousands of tokens = dollars per call. Quality degrades from "lost in the middle" effect. |
| Use a vector DB directly | You get similarity search. You don't get summarization, pruning, recency weighting, deduplication, or token budget management. You're building the pipeline yourself. |
| Use Mem0 | Proprietary, cloud-only with their hosted API. You don't control where your data lives. |
| Use MemStack | Full pipeline. Pluggable everything. Your data, your infrastructure. Open source. |
What MemStack handles that raw vector DBs don't:
- Summarization — compress 100 old interactions into one paragraph, keep meaning, save tokens
- Recency weighting — recent memories matter more; MemStack sorts them higher
- Importance scoring — not all memories are equal; high-importance ones survive pruning
- Deduplication — identical or near-identical memories are collapsed in context assembly
- Token budget —
compileContext()tells you how many tokens you're spending before the LLM call - Memory-type routing — interactions, summaries, observations treated differently at retrieval time
- Auto-pruning — old, low-importance memories clean themselves up
Quick Start
Claude Code and Codex
Persistent memory across agent harnesses: what you tell Claude Code, Codex recalls in the same project, and the reverse.
npm install -g @memstack/cli @memstack/mcp better-sqlite3@^11.10.0  # MemStack never installs storage drivers for you
memstack init                  # choose an LLM provider and a store
memstack connect claude-code
memstack connect codex
Then, in Claude Code: "Remember that this project uses Hono." In Codex, in the same repository: "What framework does this project use?" Codex answers Hono. See Harness Memory for how it works.
As a library
npm install @memstack/core
OpenAI
import { MemStack, OpenAILLMAdapter, OpenAIEmbeddingAdapter, InMemoryStorageAdapter } from "@memstack/core";

const llm = new OpenAILLMAdapter({ apiKey: process.env.OPENAI_API_KEY! });

const memstack = new MemStack({
  llm,
  embedding: new OpenAIEmbeddingAdapter({ apiKey: process.env.OPENAI_API_KEY! }),
  storage: new InMemoryStorageAdapter(),
});
DeepSeek (no embeddings)
DeepSeek provides chat completions but has no embedding API. Use the OpenAI-compatible LLM adapter with baseURL and omit the embedding adapter — retrieval falls back to keyword + recency + importance ranking. You still get the full pipeline: store, summarize, prune, and compileContext.
import { MemStack, OpenAILLMAdapter, InMemoryStorageAdapter } from "@memstack/core";

const llm = new OpenAILLMAdapter({
  apiKey: process.env.DEEPSEEK_API_KEY!,
  baseURL: "https://api.deepseek.com/v1",
  defaultModel: "deepseek-flash",
});

const memstack = new MemStack({
  llm,
  storage: new InMemoryStorageAdapter(),
  // No embedding adapter — retrieval uses keyword matching
});
OpenRouter / Together AI / any OpenAI-compatible API
Same pattern — change baseURL and defaultModel:
// OpenRouter
const llm = new OpenAILLMAdapter({
  apiKey: process.env.OPENROUTER_API_KEY!,
  baseURL: "https://openrouter.ai/api/v1",
  defaultModel: "openai/gpt-4o-mini",
});

// Together AI
const llm = new OpenAILLMAdapter({
  apiKey: process.env.TOGETHER_API_KEY!,
  baseURL: "https://api.together.xyz/v1",
  defaultModel: "meta-llama/Llama-3.3-70B-Instruct-Turbo",
});

// Gemini (OpenAI-compatible endpoint)
const llm = new OpenAILLMAdapter({
  apiKey: process.env.GEMINI_API_KEY!,
  baseURL: "https://generativelanguage.googleapis.com/v1beta/openai",
  defaultModel: "gemini-2.0-flash",
});
Store and retrieve
// 1. Store what happened
await memstack.memory.store({
  actorId: "support-bot-42",
  content: "User reports login failing with error 503 on Chrome 125.",
  tags: ["login", "bug", "chrome"],
  importance: 0.8,
});

// 2. Later, retrieve relevant context
const memories = await memstack.memory.retrieve({
  actorId: "support-bot-42",
  query: "login error",
  strategy: "hybrid",
});

// 3. Assemble an LLM-ready context
const ctx = await memstack.memory.compileContext({
  actorId: "support-bot-42",
  maxTokens: 2000,
});

const response = await llm.complete({
  system: `You are a support bot. Here is what you remember:\n${ctx.systemPrompt}`,
  user: "The user is back and still can't log in. What do you do?",
});

console.log(response.text);
// "Based on our history, the user has been experiencing 503 errors on Chrome 125..."

// 4. Every 100 interactions, summarization triggers automatically.
// Old interactions are compressed into a paragraph. Token costs stay flat.
Harness Memory (Claude Code & Codex)
Coding agents forget everything between sessions, and they don't share what they learn with each other. MemStack gives Claude Code and Codex one memory per project: a decision made with one agent is known to the other, and to every later session.
How it works
- Saving. Each agent gets five MemStack tools (
memory_store,memory_retrieve,memory_get,memory_delete,memory_stats) through the MCP harness profile. When you say "remember that…", or the agent learns a durable fact, decision, preference, or rule, it callsmemory_store. MemStack asks your LLM for a few topic tags, so "uses Hono" can later be found by "which framework?". If tagging fails, the memory is still saved. - Recalling. A session-start hook loads the project's most important
memories into every new session, so the agent starts out knowing them.
During a session the agent calls
memory_retrievewith plain questions. Recall runs locally with keyword ranking (BM25 with stemming) and never calls the LLM, so it is fast and works offline. - Scope. Memories belong to the current project. Preferences that apply
everywhere can be saved as global (
scope: "global") and are recalled in every project. One project can never read or delete another's memories. - Safety. Agents don't get bulk or destructive tools, and the LLM key stays
in
~/.memstack/config.json(readable only by you), never in agent configs. Agents are told never to store secrets, and MemStack checks too: a memory that contains a credential (a private key, a cloud or source-host token, a JWT, a password in a connection string, apassword = "..."assignment) is refused before the LLM or the store sees it, and the error names the kind of secret without repeating it. The check is pattern-based, so a secret in a format it doesn't know will pass;MEMSTACK_SECRET_POLICY=redactstores the memory with[REDACTED:<kind>]in place of the secret, andoffdisables the check.
Commands
| Command | What it does |
|---|---|
memstack init |
Choose an LLM provider (optional) and a store. Verifies the key with a real request and writes ~/.memstack/config.json. Without a key, memories are saved without topic tags and recall works the same. Non-interactive: --provider, --base-url, --model, --api-key-env <VAR>, --no-llm, --store, --path, --url, --yes. |
memstack connect <claude-code|codex> |
Registers MemStack with the agent. Checks the server works first, and undoes everything if a step fails. --dry-run shows the changes; --no-hooks and --no-agents-md skip those parts. |
memstack disconnect <claude-code|codex> |
Removes everything connect added. Your memories are kept. |
memstack status |
Config, storage, the current project, and what each agent has connected. |
memstack doctor |
Diagnoses setup problems and prints the fix for each. --live also tests the LLM key. |
memstack memories [query] |
Lists or searches this project's memories. --global for global ones, --delete <id> to remove one. |
memstack project |
Shows this repository's project ID. project pin <id> fixes it in .memstack.json; project merge <old-id> moves memories from an old ID. |
What connect changes
connect changes only these entries, backs up each file first, and
disconnect restores each file exactly:
| Agent | File | Change |
|---|---|---|
| Claude Code | ~/.claude.json |
A user-scope memstack MCP server, added with claude mcp add-json. |
| Claude Code | ~/.claude/settings.json |
A SessionStart hook running memstack-mcp hook session-start. |
| Codex | ~/.codex/config.toml |
A memstack MCP server, added with codex mcp add. |
| Codex | ~/.codex/hooks.json |
A SessionStart hook. Codex runs it after you approve it once with /hooks. |
| Codex | ~/.codex/AGENTS.md |
A short block between memstack:begin/memstack:end markers telling Codex to save memories with memory_store. |
The registered command is the memstack-mcp you installed, run by absolute
path, so it works even when the agent starts without your shell's PATH.
Restart Claude Code, or start a new Codex session, to load it.
Projects
The project ID comes from the repository itself, with nothing stored, so it stays the same across clones, worktrees, renamed remotes, moved folders, new machines, and storage switches:
- a pinned ID in
.memstack.jsonat the repository root (memstack project pin <id>; commit it to share it with your team); - otherwise, the repository's first commit;
- for shallow clones, the
originremote; - for repositories without commits, the git directory, and outside git, the folder. Memories saved before a repository's first commit move to the new ID automatically.
A fork shares its first commit with the original repository, so on one store
the two share memories until one of them runs memstack project pin.
Storage
Any supported store works; pick it in memstack init. MemStack never installs
storage drivers: install the one you need alongside @memstack/mcp.
| Store | Driver to install | Notes |
|---|---|---|
sqlite |
better-sqlite3@^11.10.0 |
Default; one local file, safe for both agents at once. |
postgres |
postgres@^3.4.9 |
Shared across machines. |
redis |
ioredis@^5.11.1 |
|
disk, markdown |
none | Single process only; doctor warns when both agents use them. |
Switching stores keeps project IDs; move memories with memstack export and
memstack import.
Troubleshooting
Run memstack doctor first; it checks the config file and its permissions,
the LLM key, the storage driver, each agent's registration, hook, and
guidance, and starts the server to confirm it answers.
- "memstack-mcp is not installed" or a missing driver: run the
npm install -g …command it prints. - Codex doesn't load memories at session start: approve the MemStack hook
in Codex with
/hooks. - Codex doesn't save when asked: check
memstack statusshows theAGENTS.mdguidance as present; reconnect if not. - Memories seem missing:
memstack projectshows which project you are in. Usememstack project merge <old-id>to bring memories from an old ID.
Details on the MCP server itself: docs/MCP_SETUP.md.
The Memory Pipeline
MemStack's core is a five-stage pipeline. Each stage can be used independently.
1. Store
Every agent interaction becomes a Memory with metadata that controls how it's retrieved, summarized, and pruned later.
interface Memory {
  id: string;
  actorId: string;               // Who this memory belongs to (user ID, agent ID, session ID)
  memoryType: MemoryType;        // "interaction" | "summary" | "observation" | "fact" | "reflection" | "preference" | "decision" | "instruction"
  content: string;               // The actual text
  importance: number;            // 0-1 — higher = survives pruning, ranks higher in retrieval
  emotionalValence: number;      // -1 to 1 — for tone-aware retrieval
  tags: string[];                // Filter by tag: "bug", "billing", "urgent", etc.
  embedding?: number[];          // Computed automatically if embedding adapter is configured
  metadata?: Record<string, unknown>;  // Your custom fields
  expiresAt?: Date;              // Auto-pruned after this date
  sourceId?: string;             // Link back to the originating event
  createdAt: Date;
}
// Simple store
await ms.memory.store({
  actorId: "agent-7",
  content: "Customer asked about refund policy for Q2 purchases.",
  tags: ["billing", "refund"],
});

// Batch store — embeddings are batched into one API call for efficiency
await ms.memory.storeBatch([
  { actorId: "agent-7", content: "First interaction" },
  { actorId: "agent-7", content: "Second interaction" },
  { actorId: "agent-7", content: "Third interaction" },
]);
2. Retrieve
Pull back what's relevant — by keyword, by meaning (semantic), by recency, or by importance.
const memories = await ms.memory.retrieve({
  actorId: "agent-7",              // Scope to one actor
  query: "refund policy",          // What to search for
  strategy: "hybrid",              // How to rank: "recent" | "important" | "semantic" | "hybrid"
  limit: 10,                       // Max results
  memoryTypes: ["interaction"],    // Only certain types
  tags: ["billing"],               // Only certain tags
});
Strategy behavior:
| Strategy | Sorts by | Requires embeddings | Best for |
|---|---|---|---|
recent |
Newest first | No | Knowing what just happened |
important |
Highest importance first | No | Filtering noise, keeping signal |
semantic |
Cosine similarity to query | Yes | "Find memories about X" |
hybrid |
Semantic + importance blend | Yes | Best of both worlds |
No embedding adapter? semantic and hybrid fall back to keyword matching + importance sort. No API costs, just less precise.
3. Compile Context
compileContext() takes retrieval results and assembles an LLM-ready system prompt — deduplicated, sorted by recency and importance, with a token estimate so you know the cost before calling the LLM.
const ctx = await ms.memory.compileContext({
  actorId: "agent-7",
  maxTokens: 2000,               // Budget — assembler stops when it hits this
  memoryTypes: ["interaction", "summary"],
});

// ctx.systemPrompt:
// ## Important Memories
// - The customer has been attempting login for 3 days. (importance: 0.85)
// - Refund was processed for order #4521 on Jan 12. (importance: 0.72)
//
// ## Recent Interactions
// - Customer asked about refund policy for Q2 purchases.
// - Customer reported login error 503 on Chrome 125.

console.log(ctx.tokenEstimate);  // ~280

// Inject into your LLM call
const currentMessage = "The user is asking about their refund status.";
const response = await llm.complete({
  system: ctx.systemPrompt,
  user: currentMessage,
});

console.log(response.text);
compileContext() handles deduplication, token budgeting, and splits context into important-vs-recent sections. Without it, you'd be concatenating raw retrieval results and risking context-window overflow.
4. Summarize
When an actor has hundreds of interactions, retrieval gets expensive and context gets bloated. Summarization compresses old interactions into a single paragraph using the configured LLM.
const { summary, deletedCount } = await ms.memory.summarize({
  actorId: "agent-7",
  olderThan: new Date(Date.now() - 7 * 86400000),  // Older than 7 days
  skipMostRecent: 10,        // Never touch the 10 most recent
  targetCount: 50,           // Summarize at most 50 memories
  memoryTypes: ["interaction"],
  keepOriginals: false,      // Delete originals after summary
});

// summary.content:
// "Over the past week, the customer reported recurring login failures (error 503)
//  on Chrome 125. Multiple troubleshooting attempts including cache clearing and
//  password reset were unsuccessful. A refund was processed for order #4521."

console.log(deletedCount);   // 47 — 47 interactions compressed into 1 summary memory
Auto-summarization: Set summarizationThreshold in config (default: 100). Every 100th interaction for an actor triggers summarization automatically.
Warning: keepOriginals: false deletes the summarized memories. Set keepOriginals: true to preserve them alongside the summary.
Custom summarization prompt:
const ms = new MemStack({
  llm,
  defaults: {
    summarizationPrompt:
      "You are an enterprise support memory compressor. Highlight: customer name,
       product, severity, resolution status, and any open issues.",
  },
});
5. Prune
Not all memories deserve to live forever. Pruning removes low-value memories to keep storage and retrieval fast.
// Remove memories older than 30 days
await ms.memory.prune({ type: "byAge", maxAge: 30 * 86400000 });

// Keep only memories above importance 0.3
await ms.memory.prune({ type: "byImportance", minImportance: 0.3 });

// Keep at most 500 memories per actor
await ms.memory.prune({ type: "byCount", maxPerActor: 500 });

// Remove specific types
await ms.memory.prune({ type: "byType", memoryTypes: ["observation"] });

// Custom logic
await ms.memory.prune({
  type: "custom",
  shouldRemove: (memory) => memory.content.includes("[RESOLVED]"),
});

// Dry run first — see what would be removed
const { wouldPrune, count } = await ms.memory.dryRunPrune({
  type: "byAge",
  maxAge: 86400000,
});
console.log(`Would remove ${count} memories:`, wouldPrune);
Auto-prune on every process() call by setting pruneStrategy in config:
const ms = new MemStack({
  llm,
  defaults: {
    pruneStrategy: { type: "byImportance", minImportance: 0.05 },
  },
});
Real-World Use Cases
Pertanyaan tentang MemStack MCP
Bagaimana cara menambahkan MemStack MCP ke Claude Code?
Jalankan claude mcp add memstack -- npx -y @memstack/mcp di terminal Anda. Tambahkan --scope user agar tersedia di semua proyek.
Bagaimana cara menambahkan MemStack MCP ke Cursor?
Buka ~/.cursor/mcp.json dan tambahkan server di bawah mcpServers, menggunakan config Cursor yang ditunjukkan di bagian instalasi di atas.
Bagaimana MemStack membantu mengelola context window LLM?
MemStack mencegah kebutuhan untuk memasukkan semua data ke dalam context window dengan cara menyimpan interaksi, mengambil hanya informasi yang relevan, dan merangkum memori lama untuk menghemat token.
Apakah MemStack bisa digunakan dengan berbagai provider LLM?
Ya, MemStack bersifat pluggable dan mendukung berbagai adapter LLM termasuk OpenAI, DeepSeek, OpenRouter, Together AI, dan Gemini.
Apakah MemStack melindungi informasi sensitif?
Ya, sistem ini menyertakan pengecekan berbasis pola yang akan menolak menyimpan memori yang mengandung kredensial seperti private keys, password, atau token.
Bagaimana MemStack menangani memori untuk coding agent seperti Claude Code?
MemStack menyediakan memori bersama per proyek, sehingga memungkinkan berbagai agent untuk mengingat keputusan dan konvensi yang telah dibuat pada sesi sebelumnya.