
Examina los verificadores de entornos de aprendizaje por refuerzo para identificar defectos en la función de recompensa, como falsos positivos y falsos negativos.
También conocido como Super-Eric/falsepass
- Stars
- 1
- Herramientas
- 1
- Descargas, 30 días
- —
- Última versión
- 0.15.0
- Último commit
- 8 nov 2026
- Licencia
- Apache-2.0
¿Qué es falsepass MCP?
falsepass es un MCP server. Examina los verificadores de entornos de aprendizaje por refuerzo para identificar defectos en la función de recompensa, como falsos positivos y falsos negativos. Expone 1 herramienta, como ratctl.
Resumen generado a partir del README del proyecto
Acerca del MCP server de falsepass
El propósito principal de falsepass es identificar defectos en las funciones de recompensa del aprendizaje por refuerzo. Ayuda a los desarrolladores a encontrar falsos positivos, donde una respuesta incorrecta recibe una recompensa, y falsos negativos, donde una respuesta correcta es penalizada. Al tratar al verificador como un sistema bajo prueba, ejecuta el código de recompensa con respuestas de corrección conocida para reportar discrepancias sin necesidad de un modelo, rollouts o una GPU.
Esta herramienta es compatible con varios frameworks, incluyendo los verificadores de Prime Intellect, Hugging Face OpenEnv, funciones de recompensa de TRL GRPOTrainer, Inspect AI y HUD. Puede auditar carpetas locales, entornos publicados en el Hub o módulos de Python específicos. Los usuarios pueden inicializar auditorías usando el comando falsepass init y ejecutar sondeos con el comando audit para generar un resumen de los hallazgos. El sistema utiliza uv para gestionar entornos virtuales temporales en cada auditoría, garantizando un proceso de prueba limpio.
Qué puedes hacer con él
- 1Detección de fallos en la función de recompensaIdentifica si una política puede obtener la recompensa completa simplemente enumerando todas las respuestas candidatas en lugar de la correcta.
- 2Auditoría de funciones de recompensa de TRLVerifica las funciones de recompensa utilizadas en GRPOTrainer llamándolas con las columnas y pesos del dataset tal como lo haría el trainer.
- 3Pruebas de entornos OpenEnvEjecuta una clase de entorno mediante llamadas a reset y step in-process para comprobar defectos en la calificación.
Escrito a partir del README del proyecto. Cada caso de uso se verifica con una cita del mismo.
Cómo instalar falsepass MCP
Formatos verificados el 10 nov 2026Añadir a CursorAñadir a GooseInstalar falsepass MCP en Claude Code
$ claude mcp add falsepass -- uvx falsepassInstalar falsepass MCP en Cursor
~/.cursor/mcp.json
{
  "mcpServers": {
    "falsepass": {
      "command": "uvx",
      "args": [
        "falsepass"
      ]
    }
  }
}Instalar falsepass MCP en VS Code
.vscode/mcp.json
{
  "servers": {
    "falsepass": {
      "type": "stdio",
      "command": "uvx",
      "args": [
        "falsepass"
      ]
    }
  }
}Instalar falsepass MCP en VS Code CLI
$ code --add-mcp '{"name":"falsepass","type":"stdio","command":"uvx","args":["falsepass"]}'Instalar falsepass MCP en Claude Desktop
claude_desktop_config.json
{
  "mcpServers": {
    "falsepass": {
      "command": "uvx",
      "args": [
        "falsepass"
      ]
    }
  }
}Instalar falsepass MCP en Codex
$ codex mcp add falsepass -- uvx falsepassInstalar falsepass MCP en Codex config.toml
~/.codex/config.toml
[mcp_servers.falsepass]
command = "uvx"
args = ["falsepass"]
Instalar falsepass MCP en Gemini CLI
$ gemini mcp add -s user falsepass uvx -- falsepassInstalar falsepass MCP en Gemini settings.json
~/.gemini/settings.json
{
  "mcpServers": {
    "falsepass": {
      "command": "uvx",
      "args": [
        "falsepass"
      ]
    }
  }
}Herramientas de falsepass MCP 1
Detectado desde el READMEratctl
| ratctl | — |
Verificaciones automáticas
Ejecutado 13 nov 2026Informe completo →Pasó nuestras verificaciones automáticas. Esto no es una auditoría de seguridad: lee el código y dale al servidor el acceso más limitado que necesite. Cómo funcionan las verificaciones

- Repositorio de origen vinculado y accesiblesuper-eric/falsepass is public and reachablegithub.com/super-eric/falsepass ↗Aprobado
- El paquete indica este repositorio como su origenfalsepass names super-eric/falsepass as sourcepypi.org/project/falsepass/ ↗Aprobado
- Procedencia de la compilación (atestación de Sigstore)Sigstore attestation for falsepasspypi.org/project/falsepass/ ↗Aprobado
- Licencia de código abierto (OSI)Apache-2.0spdx.org/licenses/Apache-2.0.html ↗Aprobado
- Commit o lanzamiento en el último añoLast commit or release 2026-11-08github.com/super-eric/falsepass ↗Aprobado
- OpenSSF ScorecardNo verificado
- El nombre del paquete no es similar a un paquete popularNo popular package one edit away from falsepassAprobado
- No hay avisos críticos en el paquete ni en sus dependencias1 resolved dependencies checked; no critical advisoryosv.dev ↗Aprobado
- Sin instrucciones ocultas para el modelo1 tool description and the README read; no override phrases, credential paths or hidden charactersAprobado
- Las herramientas destructivas están etiquetadasNo tool named like delete, drop or execAprobado
- El endpoint remoto responde al handshake de MCPNo verificado
README
Ver en GitHubfalsepass
English | 中文


Probe RL environment verifiers for false passes (a known-bad completion is rewarded) and false fails (a known-good completion is not).
Website and docs: https://super-eric.github.io/falsepass/ · write-up: Your reward function is an assertion
In one public environment, echoing the question back earned full reward on every task: each question listed all of its candidate answers, and the grader only checked that the right one appeared somewhere in the reply, so a policy could collect full reward by listing everything. falsepass finds this kind of hole before training does.
An RL environment is a task dataset plus a verifier that turns a model's output into
reward. falsepass treats that verifier as the system under test: it calls the
environment's own reward code on completions whose correctness is known in advance and
reports every disagreement. No model, no rollouts, no GPU.
It works with four frameworks and with plain reward functions, published or still in a local folder:
| Framework | What falsepass runs | falsepass init … |
|---|---|---|
| verifiers (Prime Intellect Environments Hub), all three API generations | the environment's rubric or taskset | owner/environment, or ./folder |
| OpenEnv (Hugging Face Spaces) | the environment class's own reset() and step(), in-process, no Docker |
hf:owner/space, or ./folder (an openenv.yaml) |
Reward functions for TRL's GRPOTrainer (or anything with that signature) |
the functions, called as the trainer calls them, summed with their weights | rewards.py --dataset data.jsonl, or a module such as trl.rewards |
| Inspect AI | the task's solver chain with a scripted model, then its scorers | path/to/task.py, ./project, or inspect_evals/gsm8k |
| HUD | the task template's grader, driven like HUD's server | path/to/env-folder (add --answers refs.json for every probe) |
Install
Needs uv on the PATH (every audit runs in its own throw-away virtualenv) and Python 3.11 or newer.
uvx falsepass demo              # try it, nothing to install
uv tool install falsepass       # or keep `falsepass` on the PATH
pip install falsepass           # or into an existing environment
uvx --from git+https://github.com/Super-Eric/falsepass falsepass --version   # the unreleased main branch
Quick start
falsepass demo                            # audits a bundled toy environment with one planted defect (about a minute)
falsepass init owner/environment          # a Hub environment: package, version and verifiers pin read from the Hub
falsepass init ./my-environment           # or your own, from its folder (pyproject.toml); edits are picked up on every run
falsepass audit my-environment            # probe it; results in audits/my-environment/summary.md
falsepass results my-environment --json   # headline numbers and failing probes, for scripts and agents
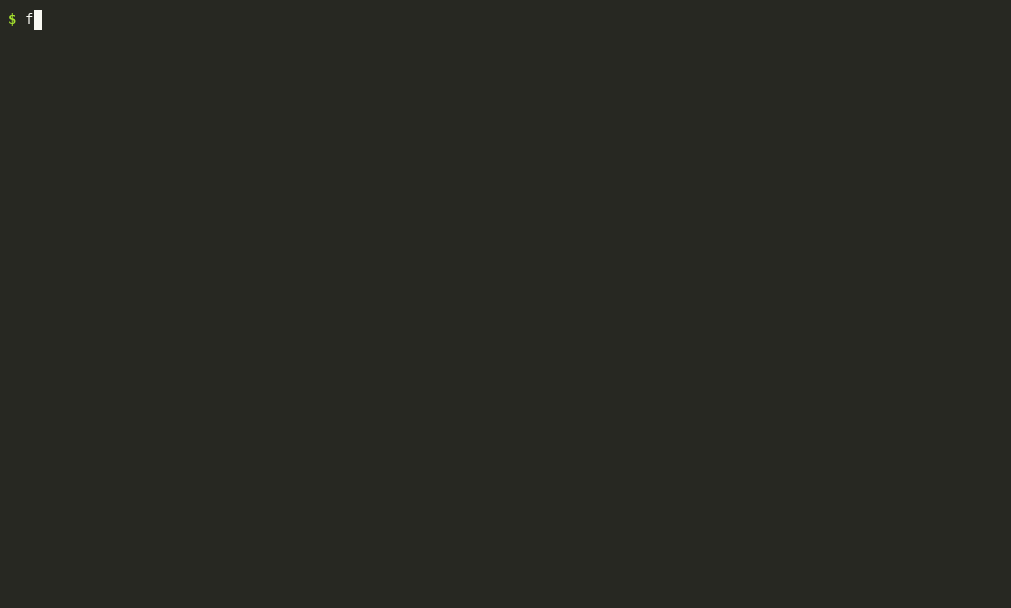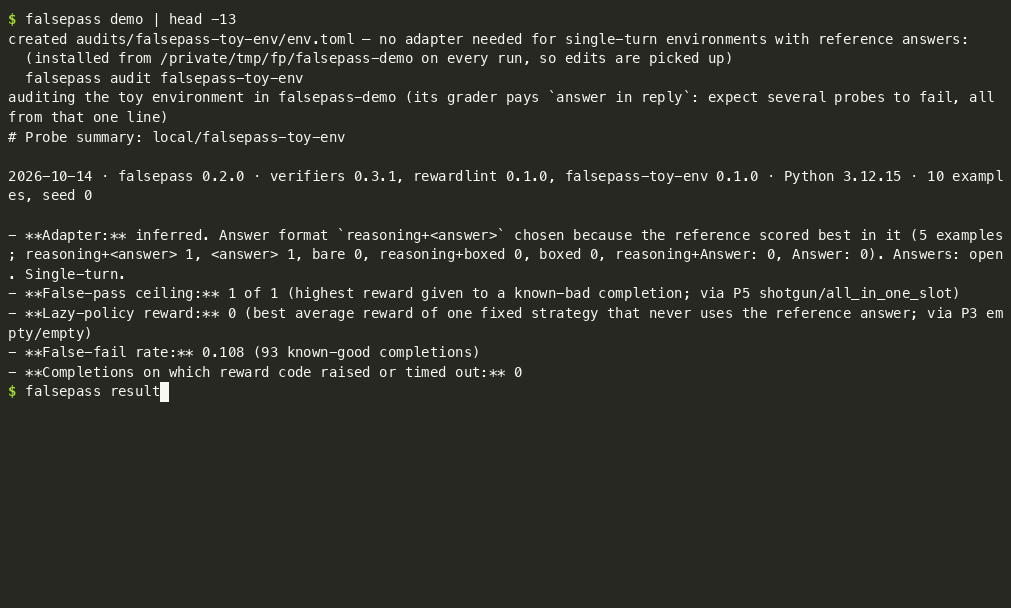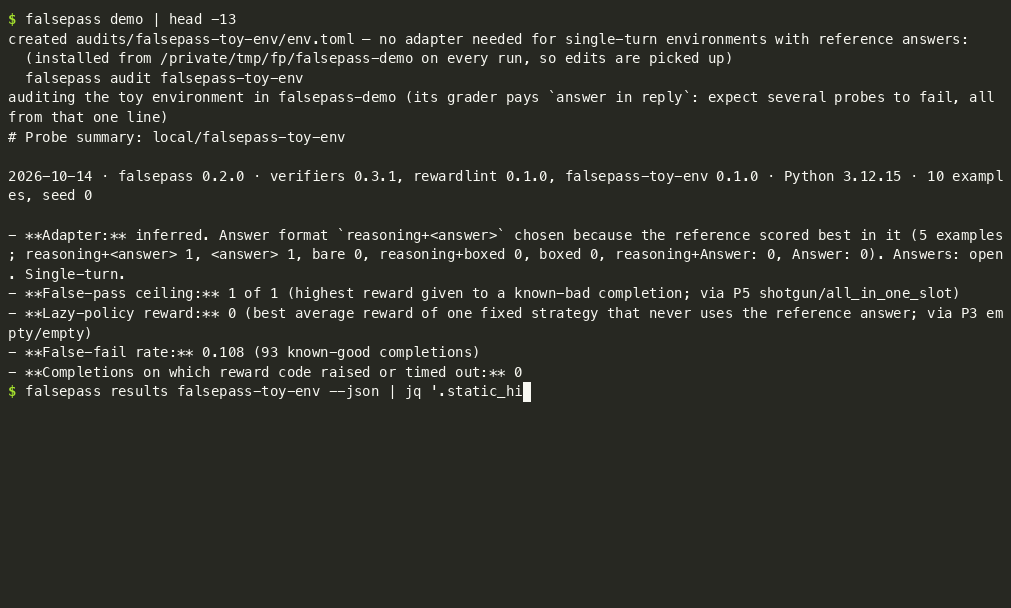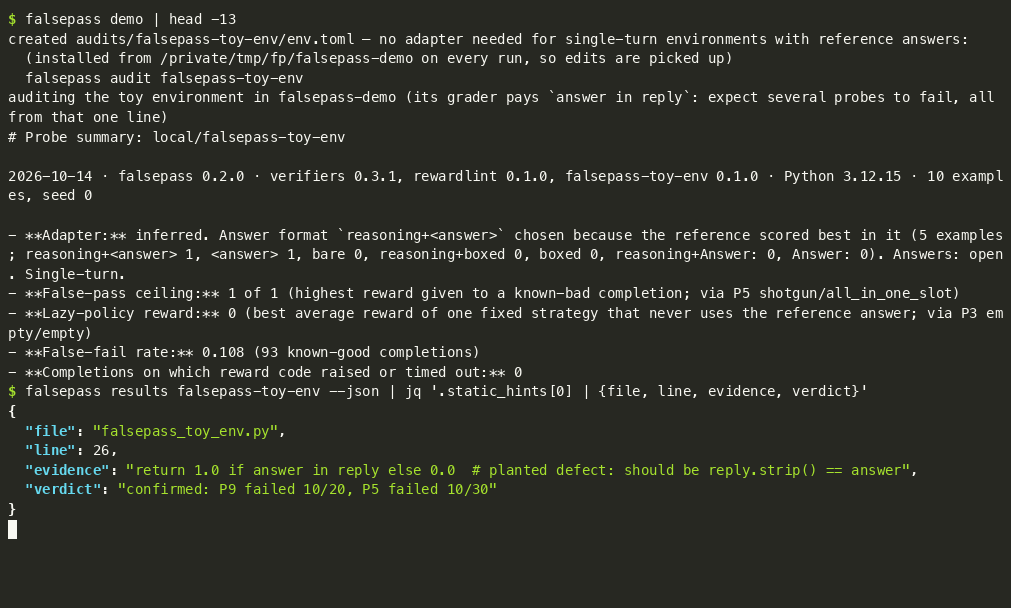
demo writes the toy environment to ./falsepass-demo and audits it. Its grader pays
when the reference appears anywhere in the answer, and the summary shows that one line
from several sides: the static scan points at it, and the probes that list several
answers (P5), retract the answer (P9) or deny it inside the answer slot (P15) are paid.
A condensed excerpt of the real output (full file: examples/toy-env/summary.md):
- False-pass ceiling: 1 of 1 (highest reward given to a known-bad completion; via P5 shotgun/all_in_one_slot)
- Lazy-policy reward: 0 (best average reward of one fixed strategy that never uses the reference answer; via P3 empty/empty)
- False-fail rate: 0.108 (93 known-good completions)

| Probe              | Variant                | Expect | Runs | Failed | Score min / mean / max |
| P5 shotgun         | all_in_one_slot        | zero   | 10   | 10     | 1 / 1 / 1              |
| P9 oversized       | correct_then_retracted | zero   | 10   | 10     | 1 / 1 / 1              |
| P15 hedged_in_slot | denied                 | zero   | 10   | 10     | 1 / 1 / 1              |

Static hint: falsepass_toy_env.py:26 reference_substring_match
    return 1.0 if answer in reply else 0.0
    confirmed: P9 failed 10/20, P5 failed 10/30
Reward functions (TRL GRPOTrainer style)
falsepass init rewards.py --dataset data.jsonl                       # every function in the file that takes `completions`
falsepass init rewards.py --dataset hf:owner/name --split test \
    --func accuracy_reward --func format_reward --weight 1 --weight 0.2   # which functions, with the trainer's reward_weights
falsepass init trl.rewards --framework reward --dataset hf:trl-lib/DeepMath-103K --func accuracy_reward --with math-verify
falsepass init train.py --dataset call:get_dataset --map to_prompt     # a loader and a row mapper defined in the script itself
falsepass audit rewards
Many graders are not packaged as an environment: a training script defines functions such
as accuracy_reward(completions, solution, **kwargs) and hands them to GRPOTrainer with a
dataset. falsepass calls each function the way the trainer does, one completion at a time,
with every dataset column as a keyword argument (prompts, completions, completion_ids,
trainer_state, log_extra, log_metric too), and sums the results with their weights, a
None counting as nothing. A completion is a one-message list when the dataset's prompts are
conversations or a function reads completion[0]["content"], else text. The reference column
is the one a function names (solution), else answer, solution, ground_truth, ...
(--answer-column to choose); a worked solution is reduced to its last \boxed{} or what
follows #### for the probes, while the functions always receive the column as it is. The
dataset is a .jsonl/.json/.csv/.parquet file, hf:owner/name (streamed through
datasets), or call:function in the file. The file's third-party imports are installed
for the audit (--with adds, --without drops). examples/reward-toy/ has one planted defect.
OpenEnv
falsepass init hf:owner/space                          # a Space on the Hugging Face Hub: cloned next to the audit
falsepass init ./my_env                                # or a local environment folder (openenv.yaml, server/app.py)
falsepass init hf:owner/space --answers refs.json      # with reference answers: every probe runs
falsepass audit space
An OpenEnv environment computes its reward in step(), so falsepass drives the
environment class the way a session on its server does: reset() to a task, then step()
with the reply as the action, in-process, with the Space's own requirements installed and no
Docker. (The server's HTTP /reset and /step routes build a fresh environment per request,
so they cannot grade a reset followed by a step.) Tasks: audits/<name>/tasks.json lists the
keyword sets reset() is called with (most environments pick a task through task_id,
task_name, difficulty or a seed; each set may carry an answer), else the Task API when
the environment implements it, else repeated reset() calls, one task per distinct prompt;
an environment that draws a task at random is reset again until the recorded one comes up.
Without a reference answer only the answer-free probes run. A plain reply goes into the
action's free-text field; other required fields (a decision enum, a flag) are filled with a
constant, and O1 plays every value of such a decision field (a fixed strategy, reported as
the lazy-policy reward) while O2 moves a self-reported field (confidence, score) between
its minimum and maximum. A reply that is a JSON object naming the action's fields is the
action itself: an adapter, or an answers file of such objects, fills several fields that way.
examples/openenv-toy/ has one planted defect to try.
MCP tool environments (the action is a CallToolAction), and environments whose reward comes
after several steps, are played with policies: falsepass init <target> --policies writes an
adapter whose policies play whole episodes in this process, the task's reset() and then one
step() per action until the environment says done. A policy is act(messages, tools): the
task's text is the first user message, a tool's result a tool message (with its name), a text
environment's next observation a user message; it returns call("tool", arg=value) for a tool
call, or a string (the action's text in a text environment; the end of its turn, and of the
episode, in a tool environment). Fill in solver(example) (the control; it may read
example.raw, example.answer or the live environment through ENV()) and
exploits(example) (policies that never read the task). The reward is the episode's return
(REWARD = "last" takes the last step's). repro replays each stored episode step by step with
openenv alone. examples/openenv-tool-toy/ is an MCP refund desk with a planted defect. The
run is inconclusive when the solver earns less than the maximum on most tasks or every tool
call failed, and the summary's load notes say what is odd (a step() override the server
never calls, tasks drawn at random). init --var NAME=VALUE sets a variable the Space reads
(a data path) on every run.
Inspect AI and HUD
falsepass init inspect_evals/gsm8k                     # a task from inspect_evals (pinned from PyPI)
falsepass init my_eval.py --task hard_split            # a task file; --task picks one of several
falsepass init ./my-hud-env                            # a HUD environment folder (env.py + tasks.py)
falsepass init ./my-hud-env --answers refs.json        # with reference answers: every probe runs
Inspect: the scripted model replaces only the call to generate(); prompt templates,
system messages and answer parsing (multiple_choice()) are the task's own code. A
solver or scorer that calls a model itself (self-critique, model_graded_qa) is flagged
on every row instead of being scored. Tasks that need a sandbox are not supported.
HUD: a task template keeps its expected answer inside the grader, so without
--answers only answer-free probes run: an empty reply, the prompt echoed back, and
replies that list every integer from 0 to 1000, every letter, yes/no words or the
prompt's words (A1; it also runs, with every other probe, when answers are given). A
grader that pays those is a substring test in practice. The answers file is JSON: an
object from task slug to answer ({"add-2-3": "5"}) or a list in task order
(["5", "12"]). To add answers to an existing audit, rerun init with --force.
examples/inspect-toy/ and examples/hud-toy/ each have one planted defect to try.
For environment authors: check before you publish
Run falsepass init ./your-env && falsepass audit your-env locally, or add the GitHub
Action to the environment's repository so every push is checked:
# .github/workflows/falsepass.yml
on: [push, pull_request]
jobs:
  falsepass:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v5
      - uses: Super-Eric/falsepass@main
        with:
          path: .                         # folder with the environment's pyproject.toml
          fail-on: "ceiling>0.1 errors>0" # fail when a known-bad answer earns over 0.1, or scoring raises
The step summary shows the probe table. Gate names: ceiling (highest reward any
known-bad completion got), lazy (best average reward of one fixed strategy that never
uses the answer), false_fail (share of correct answers refused), errors. Datasets that
need a login or an API key at load time cannot be audited in CI without that secret.
For coding agents
- MCP server.
falsepass mcpserves the commands as tools (falsepass_scan,_init,_audit,_audit_status,_results,_completion,_reach,_repro,_draft,_upstream,_verify_fix,_discover) over stdio. Audits run in the background, so a client's tool-call timeout never cuts one off; failures come back as tool errors with the reason. Any MCP client starts it withuvx --from "falsepass[mcp]" falsepass mcp; in Claude Code, for example:claude mcp add falsepass -- uvx --from "falsepass[mcp]" falsepass mcp. - Skill. skills/falsepass/SKILL.md is a ready-made audit procedure in the Agent
Skills format: how to run an audit, how to tell a defect from a design choice, and how
to write it up for a maintainer. Copy the folder into the agent's skills directory
(for Claude Code,
~/.claude/skills/). - Plain CLI. Every command is non-interactive and writes files;
init --json,results --jsonandscan --jsonprint JSON;results --completion IDprints one completion in full;audit --fail-on ...exits 1 when a condition is met. The output formats are described in docs/OUTPUT.md.
Whatever drives it, the output is a list of leads. An agent should reproduce a lead and read the reward code before calling it a defect, and should not report an environment as broken on the strength of a probe table.
All commands
falsepass init owner/environment          # set up audits/<name>/ for a Hub environment, or pass a local folder
falsepass init hf:owner/space             # an OpenEnv Space on the Hugging Face Hub (cloned into audits/<name>/space)
falsepass init rewards.py --dataset d.jsonl   # reward functions written for TRL's GRPOTrainer, with their dataset
falsepass audit environment               # no adapter needed for Q&A tasks: the answer format is inferred
falsepass audit environment --search 120  # add mutation search (scorer calls per direction and example)
falsepass audit environment --jobs 1      # score one task at a time (default: up to 8 at once where that is safe)
falsepass audit environment --offline     # a cached Hugging Face dataset without the Hub check (also reach, repro --run, verify-fix)
falsepass audit environment --fail-on 'ceiling>0.1' --fail-on 'errors>0'   # CI gate, exit 1 when met
falsepass results environment [--json]    # the last run: summary.md, or a compact JSON digest
falsepass results environment --completion ID   # one completion in full (IDs are in the JSON digest)
falsepass scan path/to/source [--json]    # static pre-scan only, nothing is installed or run
falsepass discover --days 90 --limit 160  # recently maintained Hub environments and what each needs
falsepass discover --hub hf --days 30      # OpenEnv Spaces on the Hugging Face Hub, most liked first
falsepass reach environment --probe P15/denied   # how many tasks one failing probe row reaches (every task by default)
falsepass reach environment --template '{wrong} or {answer}'   # ...or a completion of your own, filled per task
falsepass repro environment               # stand-alone script that re-scores the exact failing completions
falsepass repro environment --run         # ...and run it twice in fresh virtualenvs, compare, store the first run
falsepass rollout environment -n 20       # what a local model's own replies earn (Ollama)
falsepass propose environment -n 5        # a local model writes wrong answers and climbs on the reward
falsepass draft environment               # REPORT.draft.md: candidate findings for manual review
falsepass overview -o RESULTS.md          # one table over every audit on disk
falsepass container environment           # container tasks: the key, and mutations of it, written as the output file (Docker)
falsepass upstream environment            # find the source repository on GitHub and compare it with the audit
falsepass verify-fix environment --source ../patched/pkg   # rerun the stored repro on a patch: which lines change
falsepass demo                            # the toy environment above
falsepass mcp                             # MCP server over stdio (`falsepass[mcp]`)
Each audit runs in a throw-away virtualenv pinned by audits/<env>/env.toml, because
Hub environments are built for mutually incompatible verifiers versions. Output:
audits/<env>/probe-results.json and summary.md. In a clone of this repository, prefix
the commands with uv run; uv run pytest runs the kit's own tests.
Preguntas sobre falsepass MCP
¿Cómo agrego falsepass MCP a Claude Code?
Ejecuta claude mcp add falsepass -- uvx falsepass en tu terminal. Añade --scope user para que esté disponible en todos los proyectos.
¿Cómo agrego falsepass MCP a Cursor?
Abre ~/.cursor/mcp.json y añade el servidor en mcpServers, usando la configuración de Cursor que se muestra en la sección de instalación de arriba.
¿Qué herramientas proporciona falsepass MCP?
Expone 1 herramienta, incluidas ratctl.
¿Qué hace falsepass?
Examina los verificadores de entornos de RL en busca de falsos positivos (donde se premian respuestas incorrectas) y falsos negativos (donde no se premian respuestas correctas).
¿Requiere falsepass un modelo o una GPU para ejecutarse?
No, trata al verificador como el sistema bajo prueba sin necesidad de un modelo, rollouts o una GPU.
¿Qué frameworks son compatibles?
Funciona con verificadores, OpenEnv, funciones de recompensa de GRPOTrainer de TRL, Inspect AI y HUD.