
MCP server de Kappa Graph
Commit 2 oct 2026Permite que los asistentes de IA busquen en un grafo de conocimiento semántico, exploren relaciones entre conceptos y verifiquen la confianza de fundamentación detrás de cada afirmación.
También conocido como aaronsb/knowledge-graph-system
- Stars
- 131
- Herramientas
- —
- Descargas, 30 días
- —
- Última versión
- —
- Último commit
- 2 oct 2026
- Licencia
- Apache-2.0
¿Qué es Kappa Graph MCP?
Kappa Graph es un MCP server. Permite que los asistentes de IA busquen en un grafo de conocimiento semántico, exploren relaciones entre conceptos y verifiquen la confianza de fundamentación detrás de cada afirmación.
Resumen generado a partir del README del proyecto
Acerca del MCP server de Kappa Graph
Investigadores y desarrolladores pueden utilizar este sistema para construir una memoria semántica que no solo entienda qué información existe, sino qué tan bien respaldada está esa información. Al integrar el MCP server con asistentes de IA como Claude, los usuarios pueden otorgar a sus agentes la capacidad de buscar en un grafo de conocimiento, explorar relaciones complejas entre conceptos y verificar la confianza de fundamentación de afirmaciones específicas. Esto permite que una IA distinga entre hechos bien documentados e ideas en disputa.
La plataforma funciona como un backend local o remoto utilizando PostgreSQL y Apache AGE, admitiendo la ingesta de documentos desde PDFs, markdown e imágenes. Ofrece varias formas de interactuar con los datos, incluyendo una CLI de TypeScript, una herramienta de visualización web y un sistema de archivos FUSE que permite navegar por el espacio semántico usando comandos estándar de Unix como ls o grep. Para quienes priorizan la privacidad, el sistema admite la operación air-gapped mediante Ollama para inferencia local.
Qué puedes hacer con él
- 1Síntesis de investigación complejaUna IA puede ingerir múltiples artículos académicos para encontrar conexiones e identificar en qué puntos discrepan diferentes autores.
- 2Provisión de memoria persistente para agentesLos desarrolladores pueden dotar a los asistentes de IA de una memoria fundamentada que les permita verificar niveles de confianza antes de realizar afirmaciones.
- 3Gestión de documentación técnicaLos usuarios pueden extraer y consultar conceptos arquitectónicos a partir de documentos de diseño y notas de reuniones.
- 4Auditoría de procedencia de la informaciónLos equipos de cumplimiento pueden utilizar el sistema para rastrear cada concepto extraído hasta su evidencia de origen.
Escrito a partir del README del proyecto. Cada caso de uso se verifica con una cita del mismo.
Verificaciones automáticas
Ejecutado 14 nov 2026Informe completo →Aún no verificado. Un servidor necesita una puntuación de 80, ningún hallazgo grave y suficientes datos para que podamos revisarlo. Cómo funcionan las verificaciones · Qué corregir para obtener más puntos

- Repositorio de origen vinculado y accesibleaaronsb/knowledge-graph-system is public and reachablegithub.com/aaronsb/knowledge-graph-system ↗Aprobado
- El paquete indica este repositorio como su origenNo verificado
- Procedencia de la compilación (atestación de Sigstore)No verificado
- Licencia de código abierto (OSI)Apache-2.0spdx.org/licenses/Apache-2.0.html ↗Aprobado
- Commit o lanzamiento en el último añoLast commit or release 2026-10-02github.com/aaronsb/knowledge-graph-system ↗Aprobado
- OpenSSF ScorecardNo verificado
- El nombre del paquete no es similar a un paquete popularNo verificado
- No hay avisos críticos en el paquete ni en sus dependenciasNo verificado
- Sin instrucciones ocultas para el modelo0 tool descriptions and the README read; no override phrases, credential paths or hidden charactersAprobado
- Las herramientas destructivas están etiquetadasNo verificado
- El endpoint remoto responde al handshake de MCPNo verificado
README
Ver en GitHubKappa Graph — κ(G)


A semantic knowledge graph that extracts concepts from documents, tracks how well-supported they are, and remembers where sources disagree.
κ(G) — vertex connectivity of a graph. The minimum number of connections you'd need to cut before the graph falls apart. A measure of how robust the structure is.
Also kg — the unit of mass. Because knowledge here has weight. Grounding scores measure how heavy an idea is: well-evidenced claims carry more than thin ones. Contested concepts weigh differently than unchallenged ones.
Quick Start
Install Client Tools
The kg CLI, MCP server (for AI assistants), and optional FUSE filesystem:
curl -fsSL https://raw.githubusercontent.com/aaronsb/knowledge-graph-system/main/client-manager.sh | bash
Or just the CLI: npm install -g @aaronsb/kg-cli
Deploy the Platform
Run your own knowledge graph backend:
curl -fsSL https://raw.githubusercontent.com/aaronsb/knowledge-graph-system/main/install.sh | bash
Or from source:
git clone https://github.com/aaronsb/knowledge-graph-system.git
cd knowledge-graph-system
./operator.sh init    # Interactive setup
./operator.sh start   # Start containers
See Quick Start Guide for details.
See It In Action
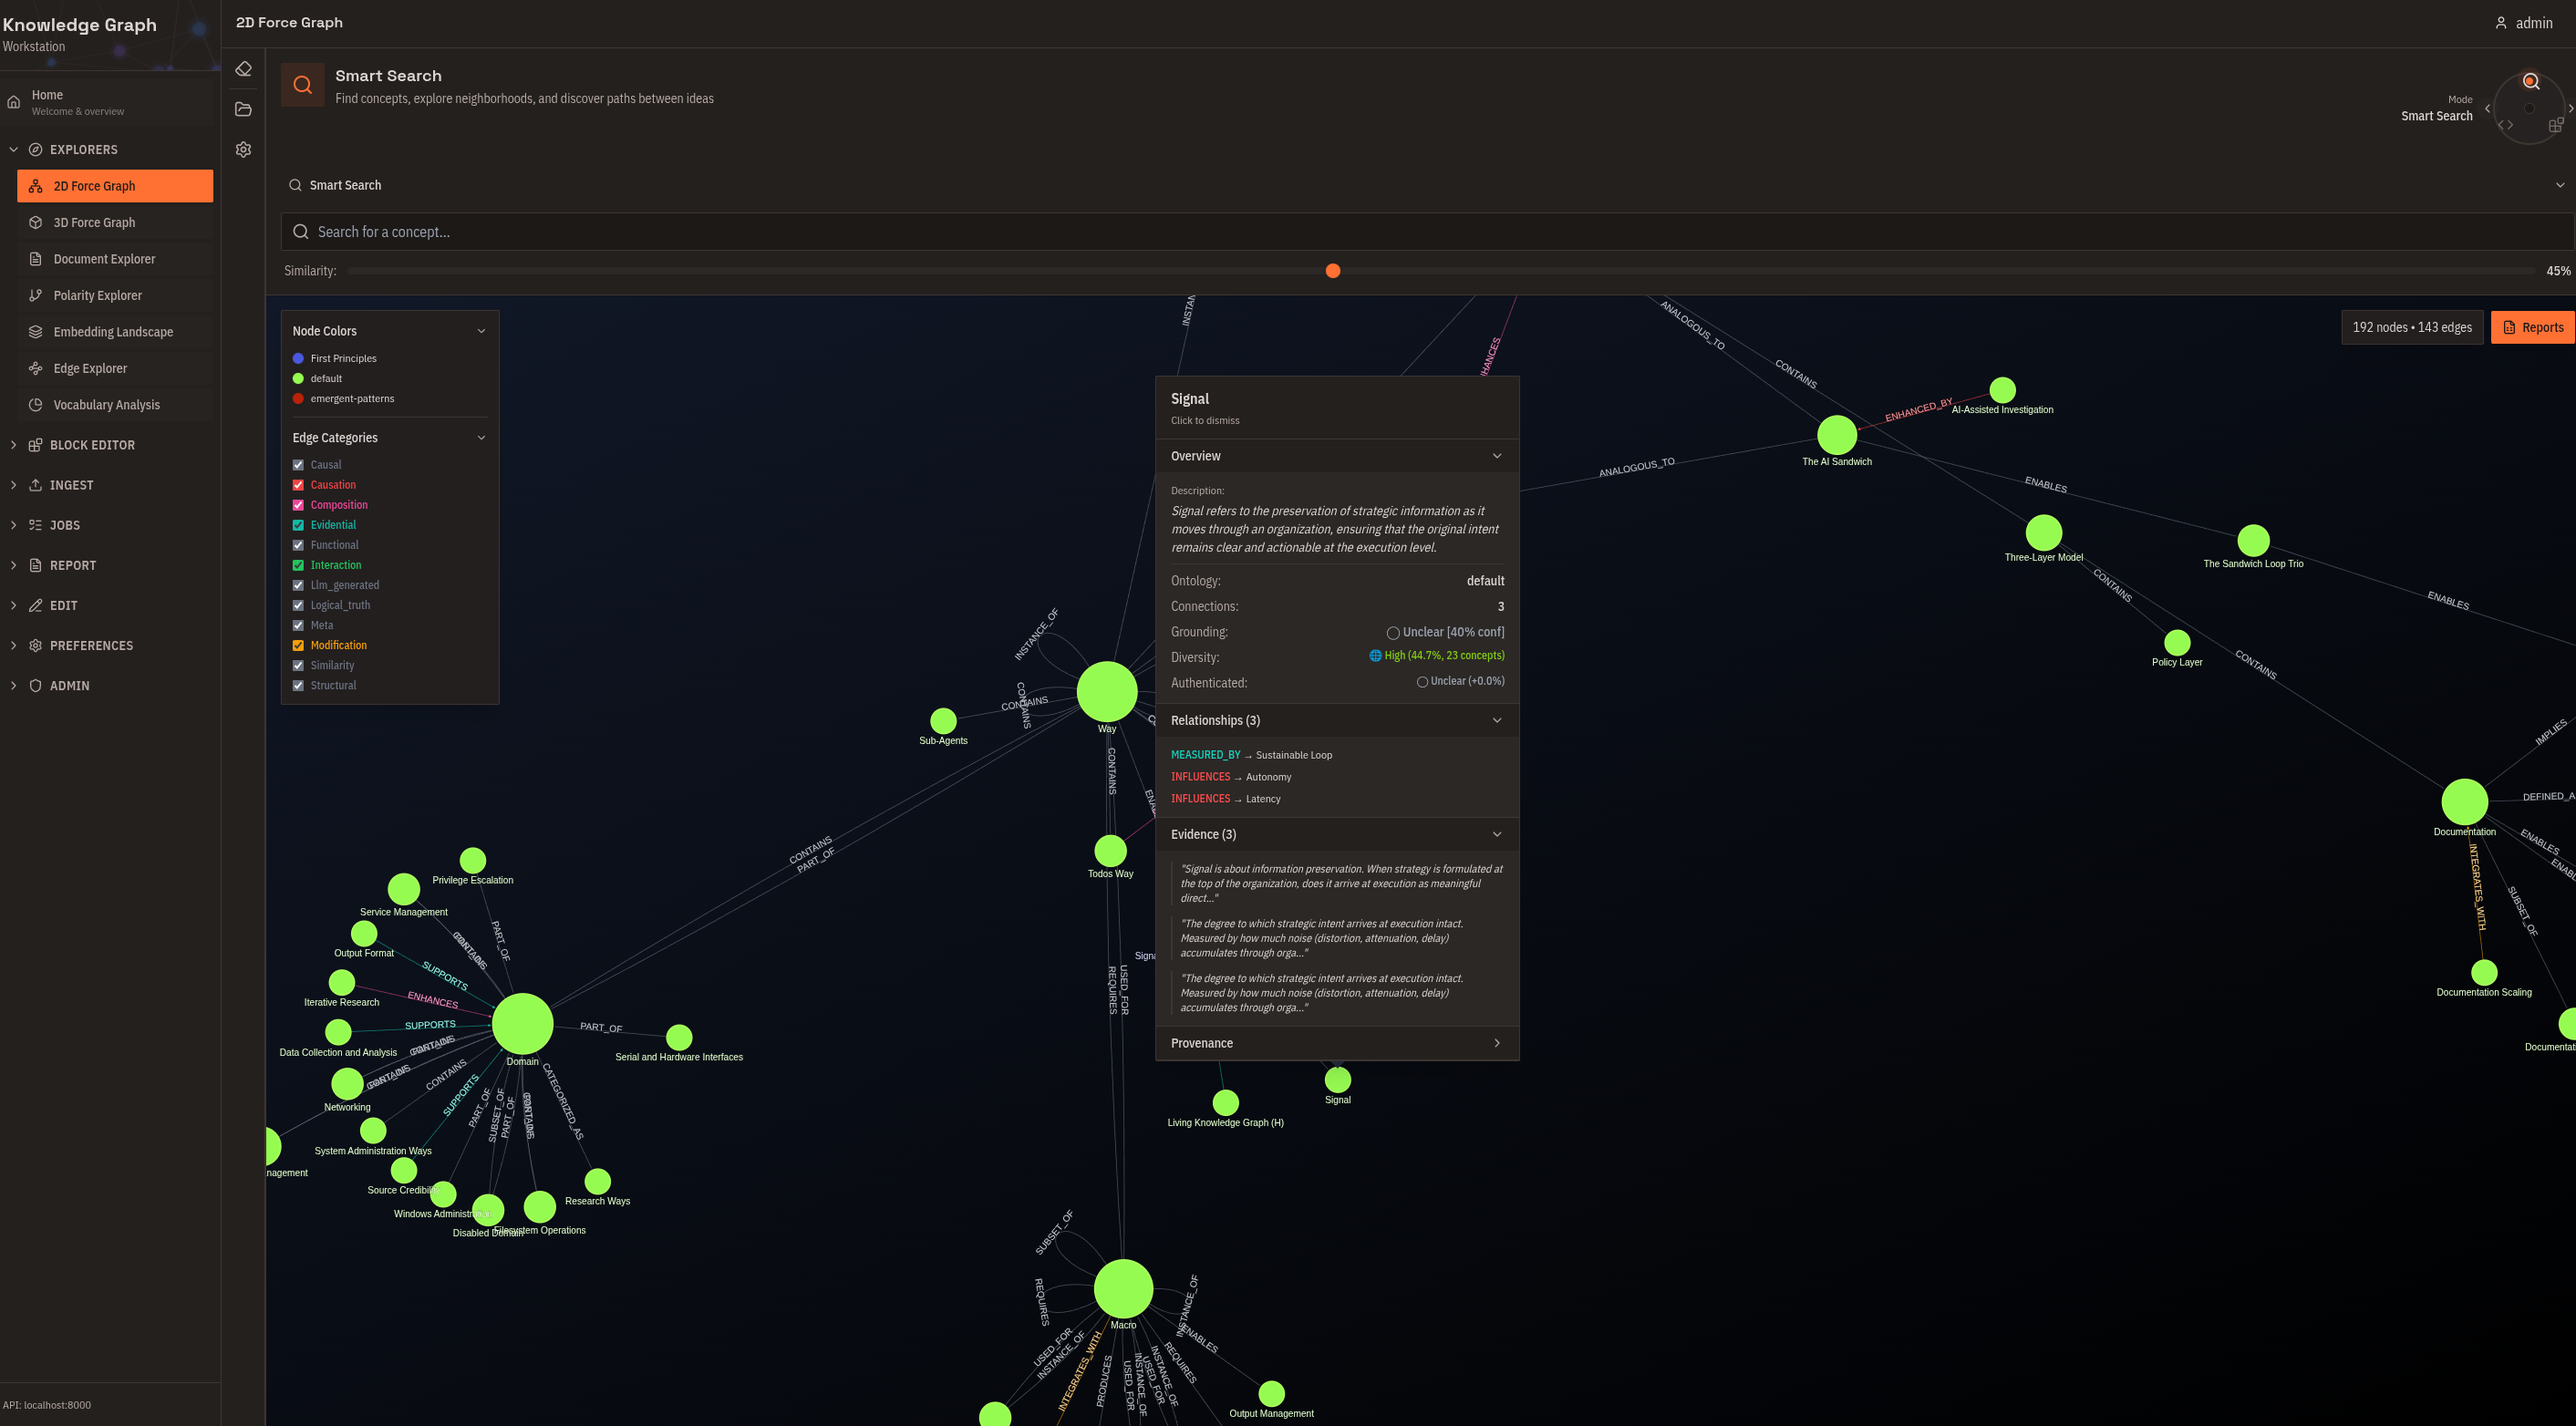
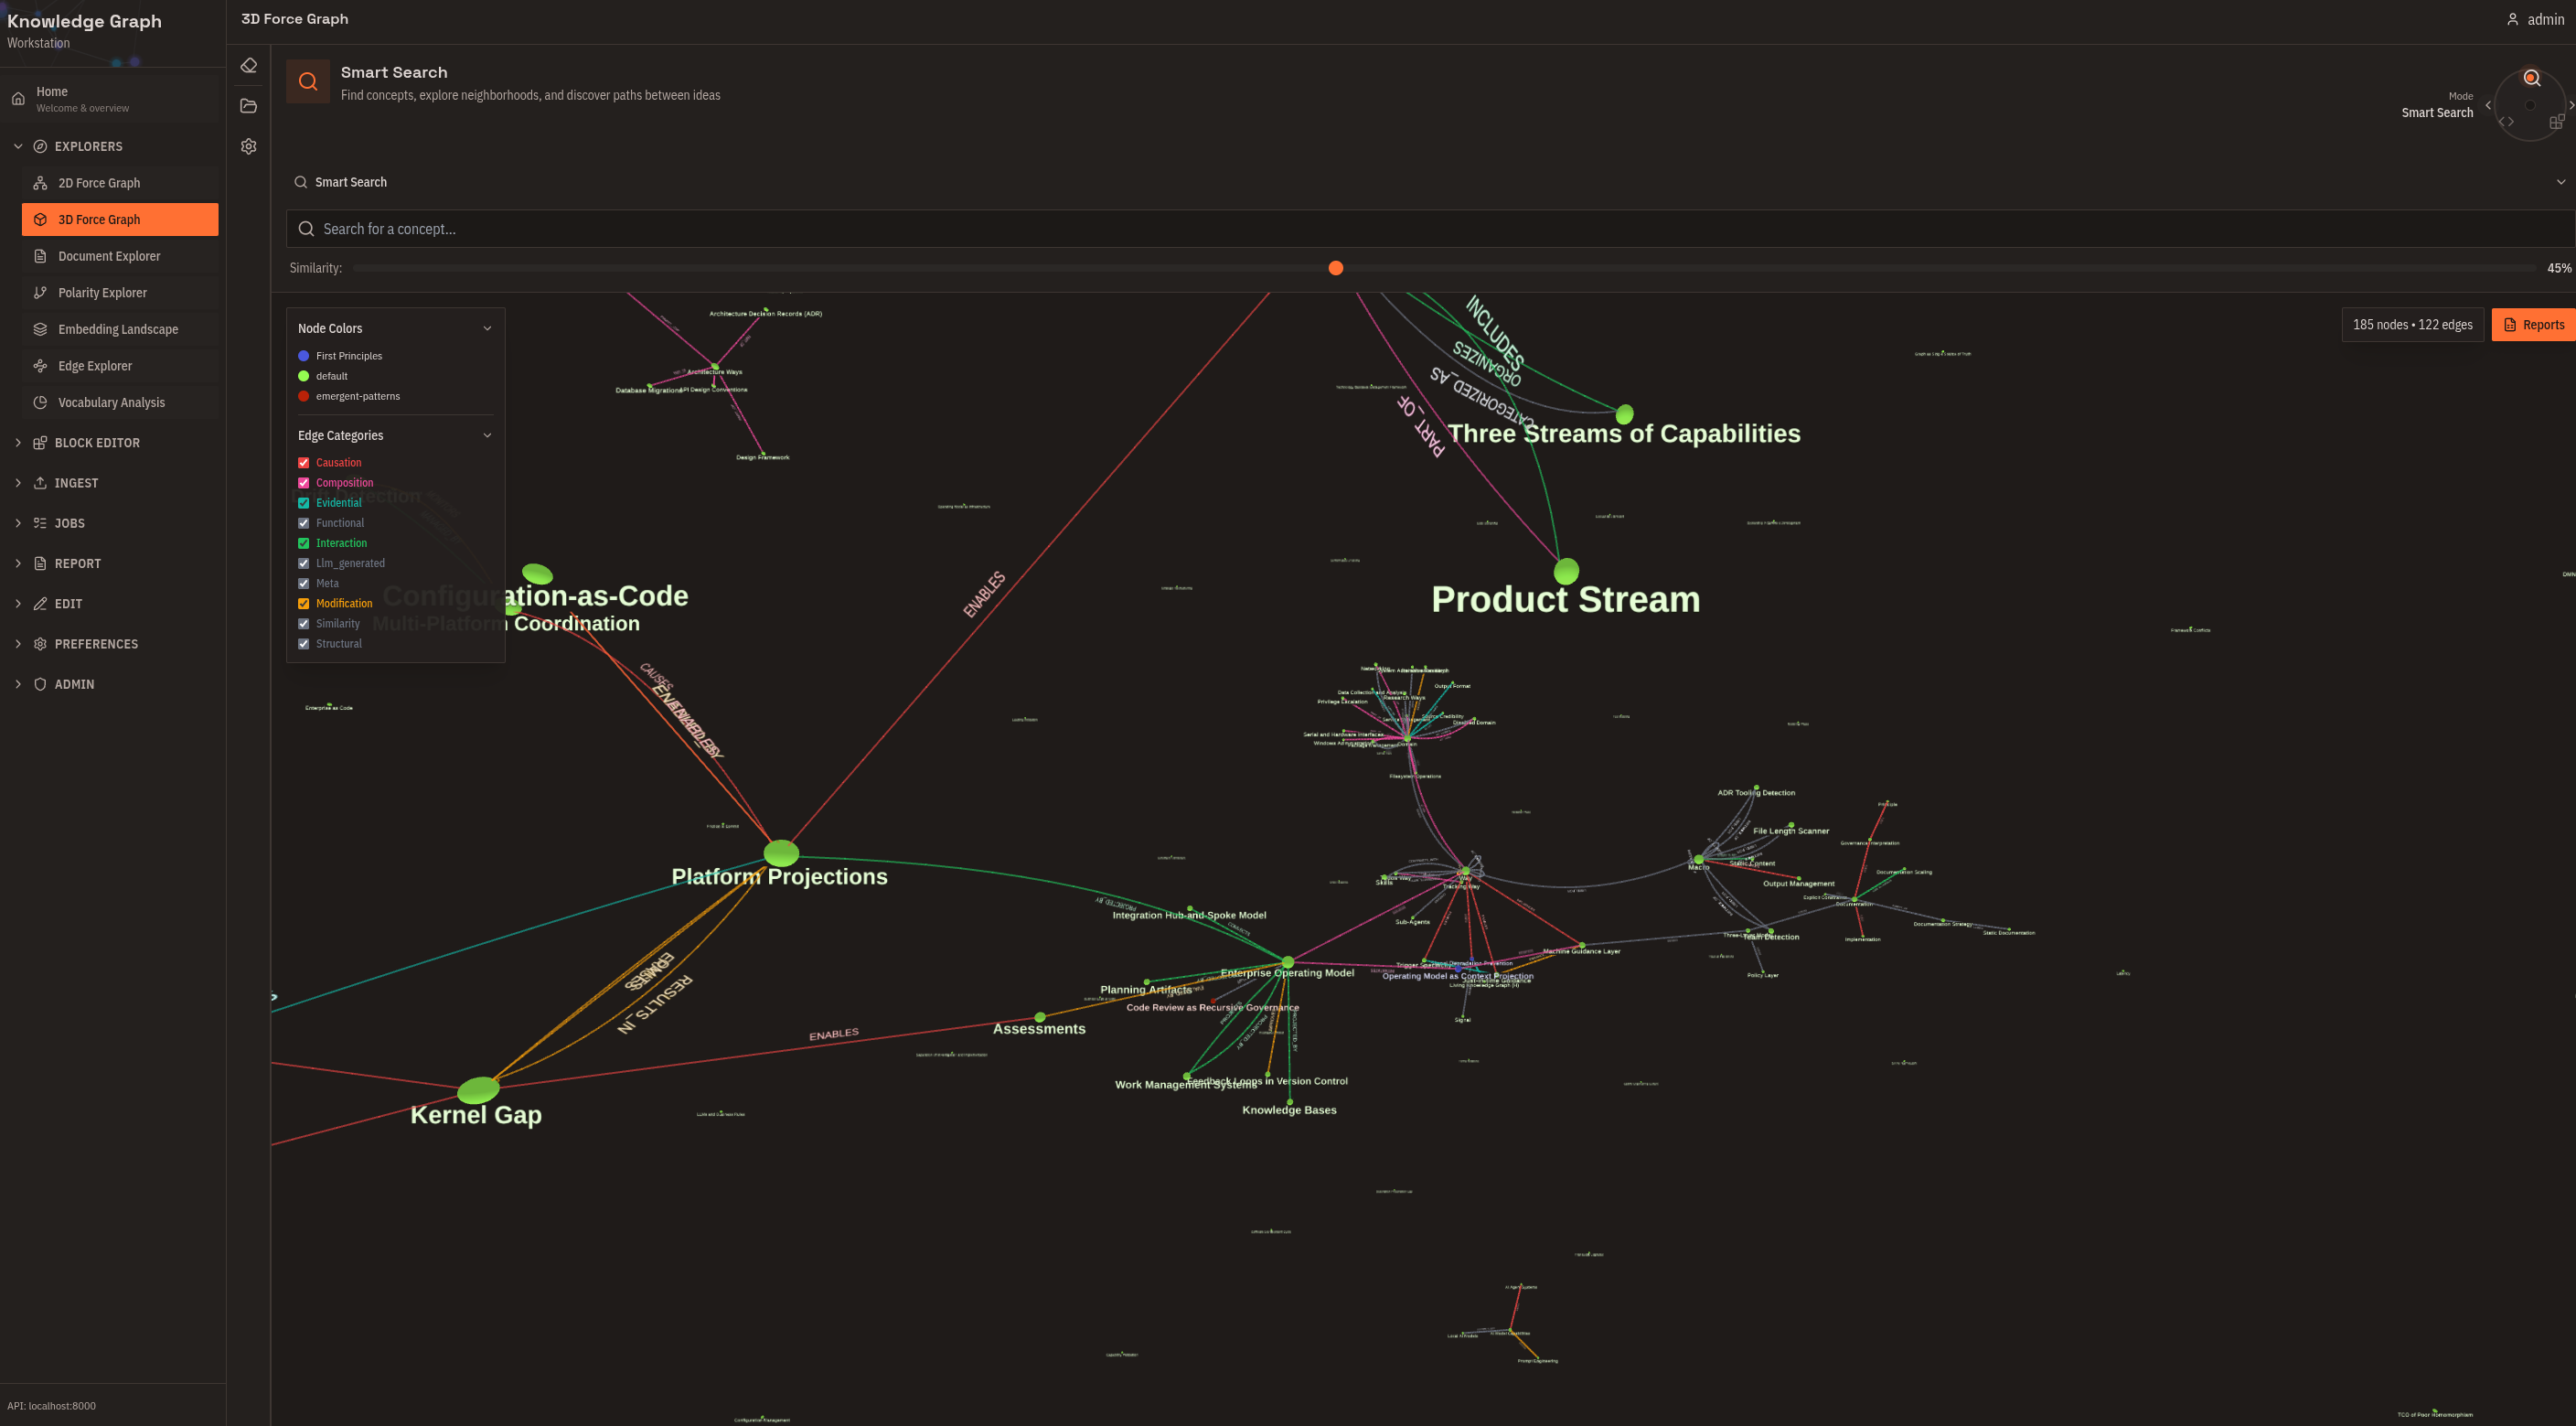 Interactive graph exploration with smart search, concept clustering, and relationship visualization
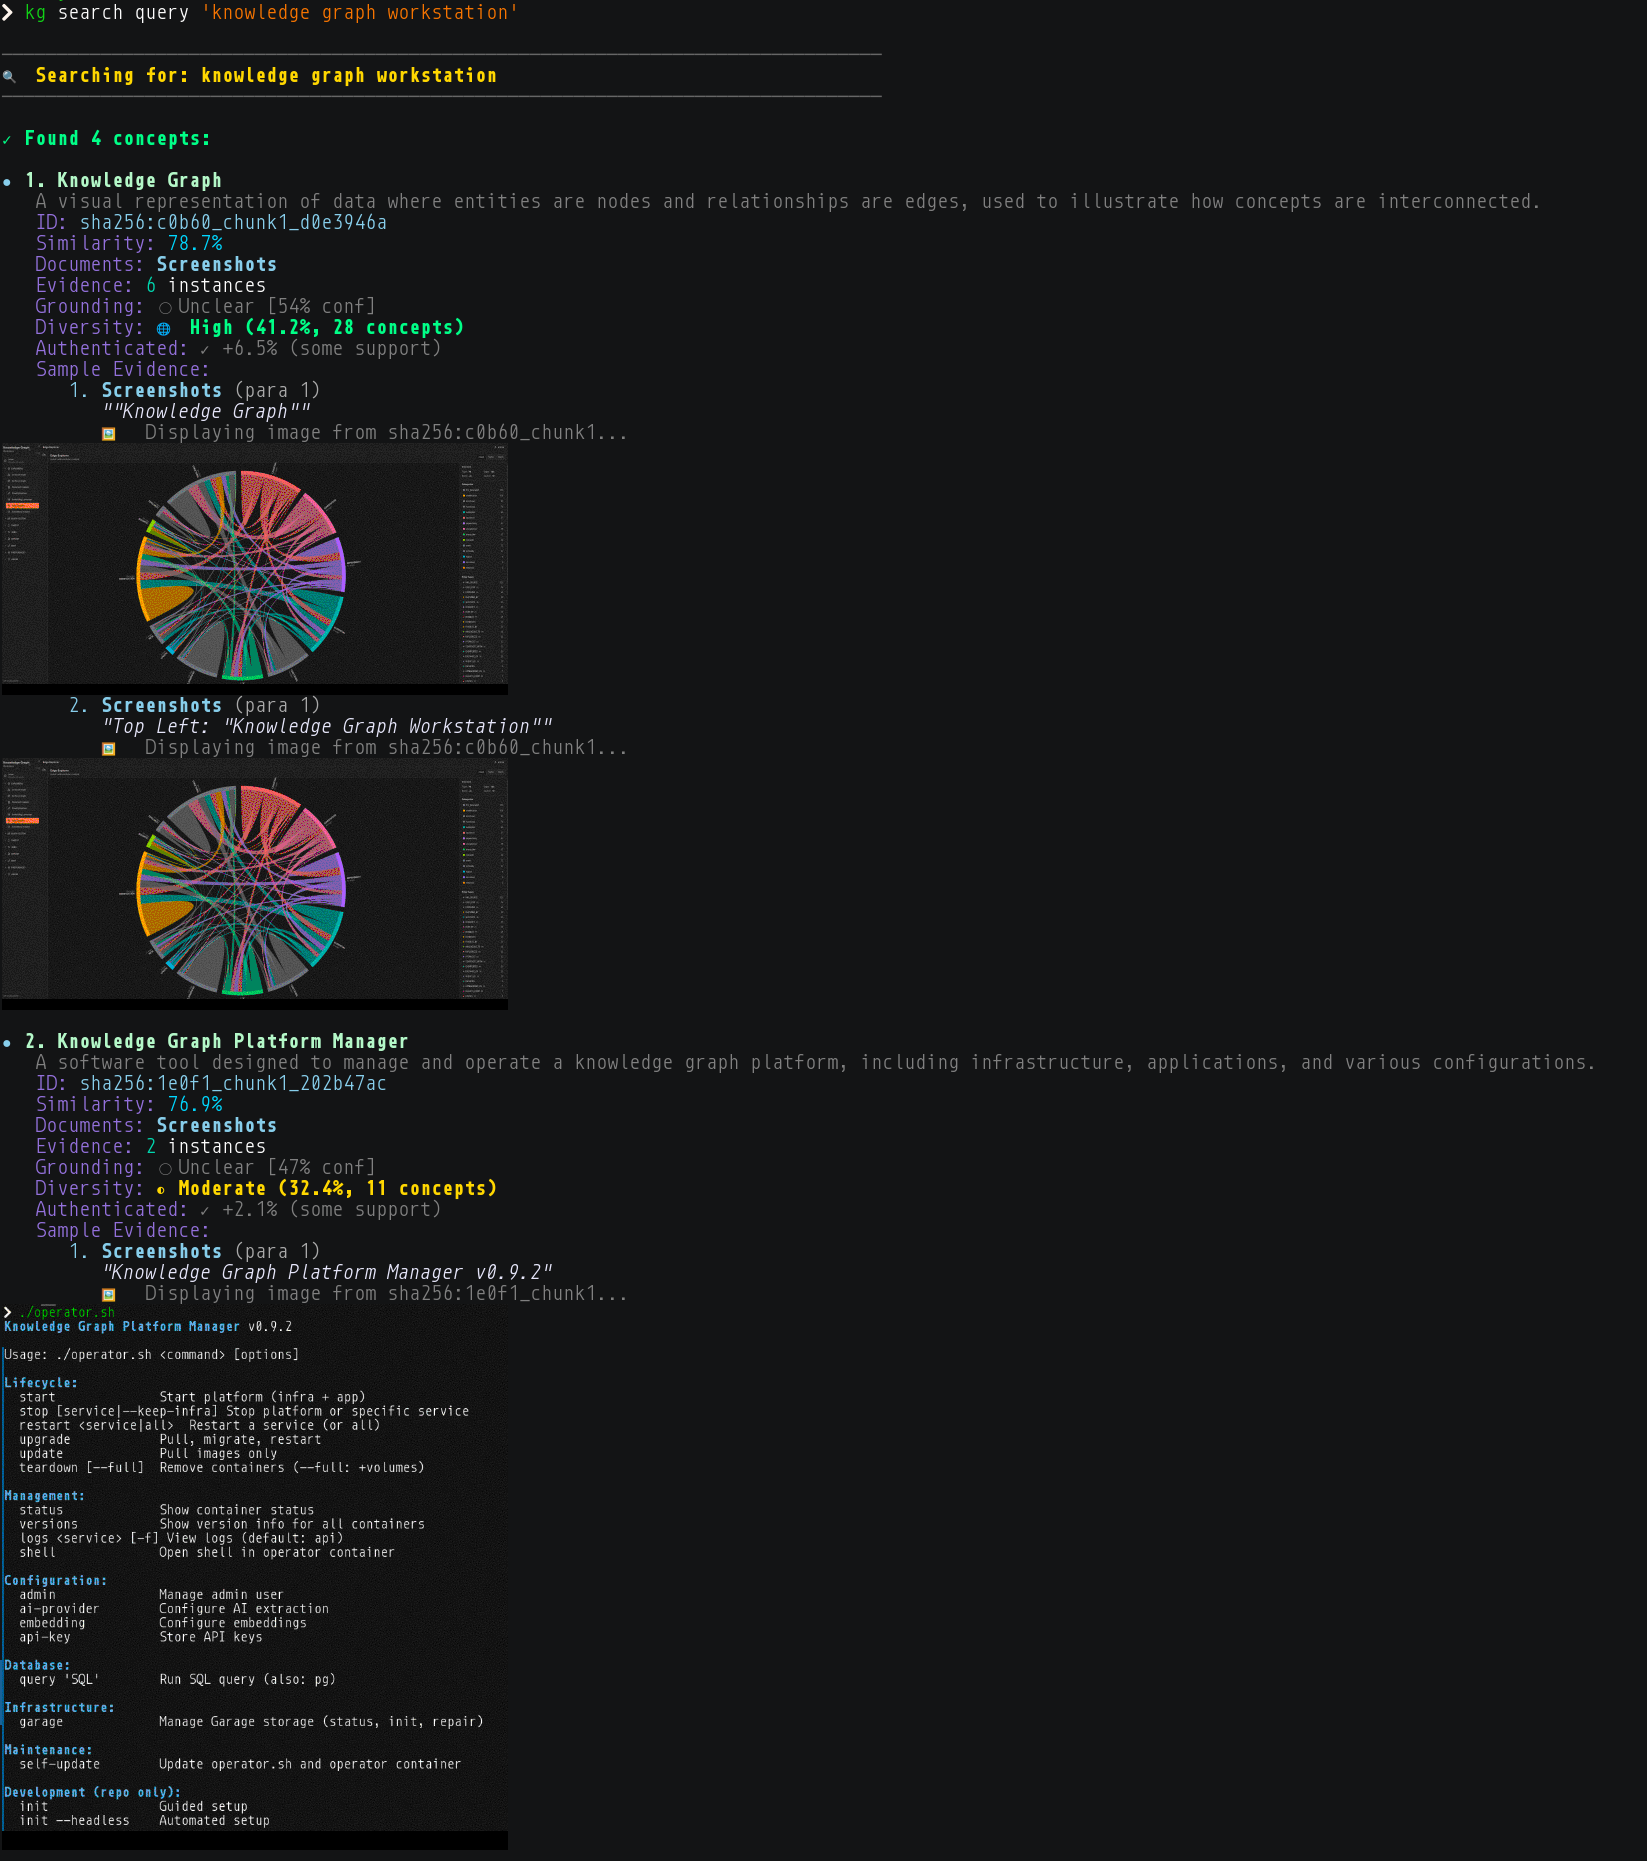 Command-line search returns concepts with source images rendered inline via chafa
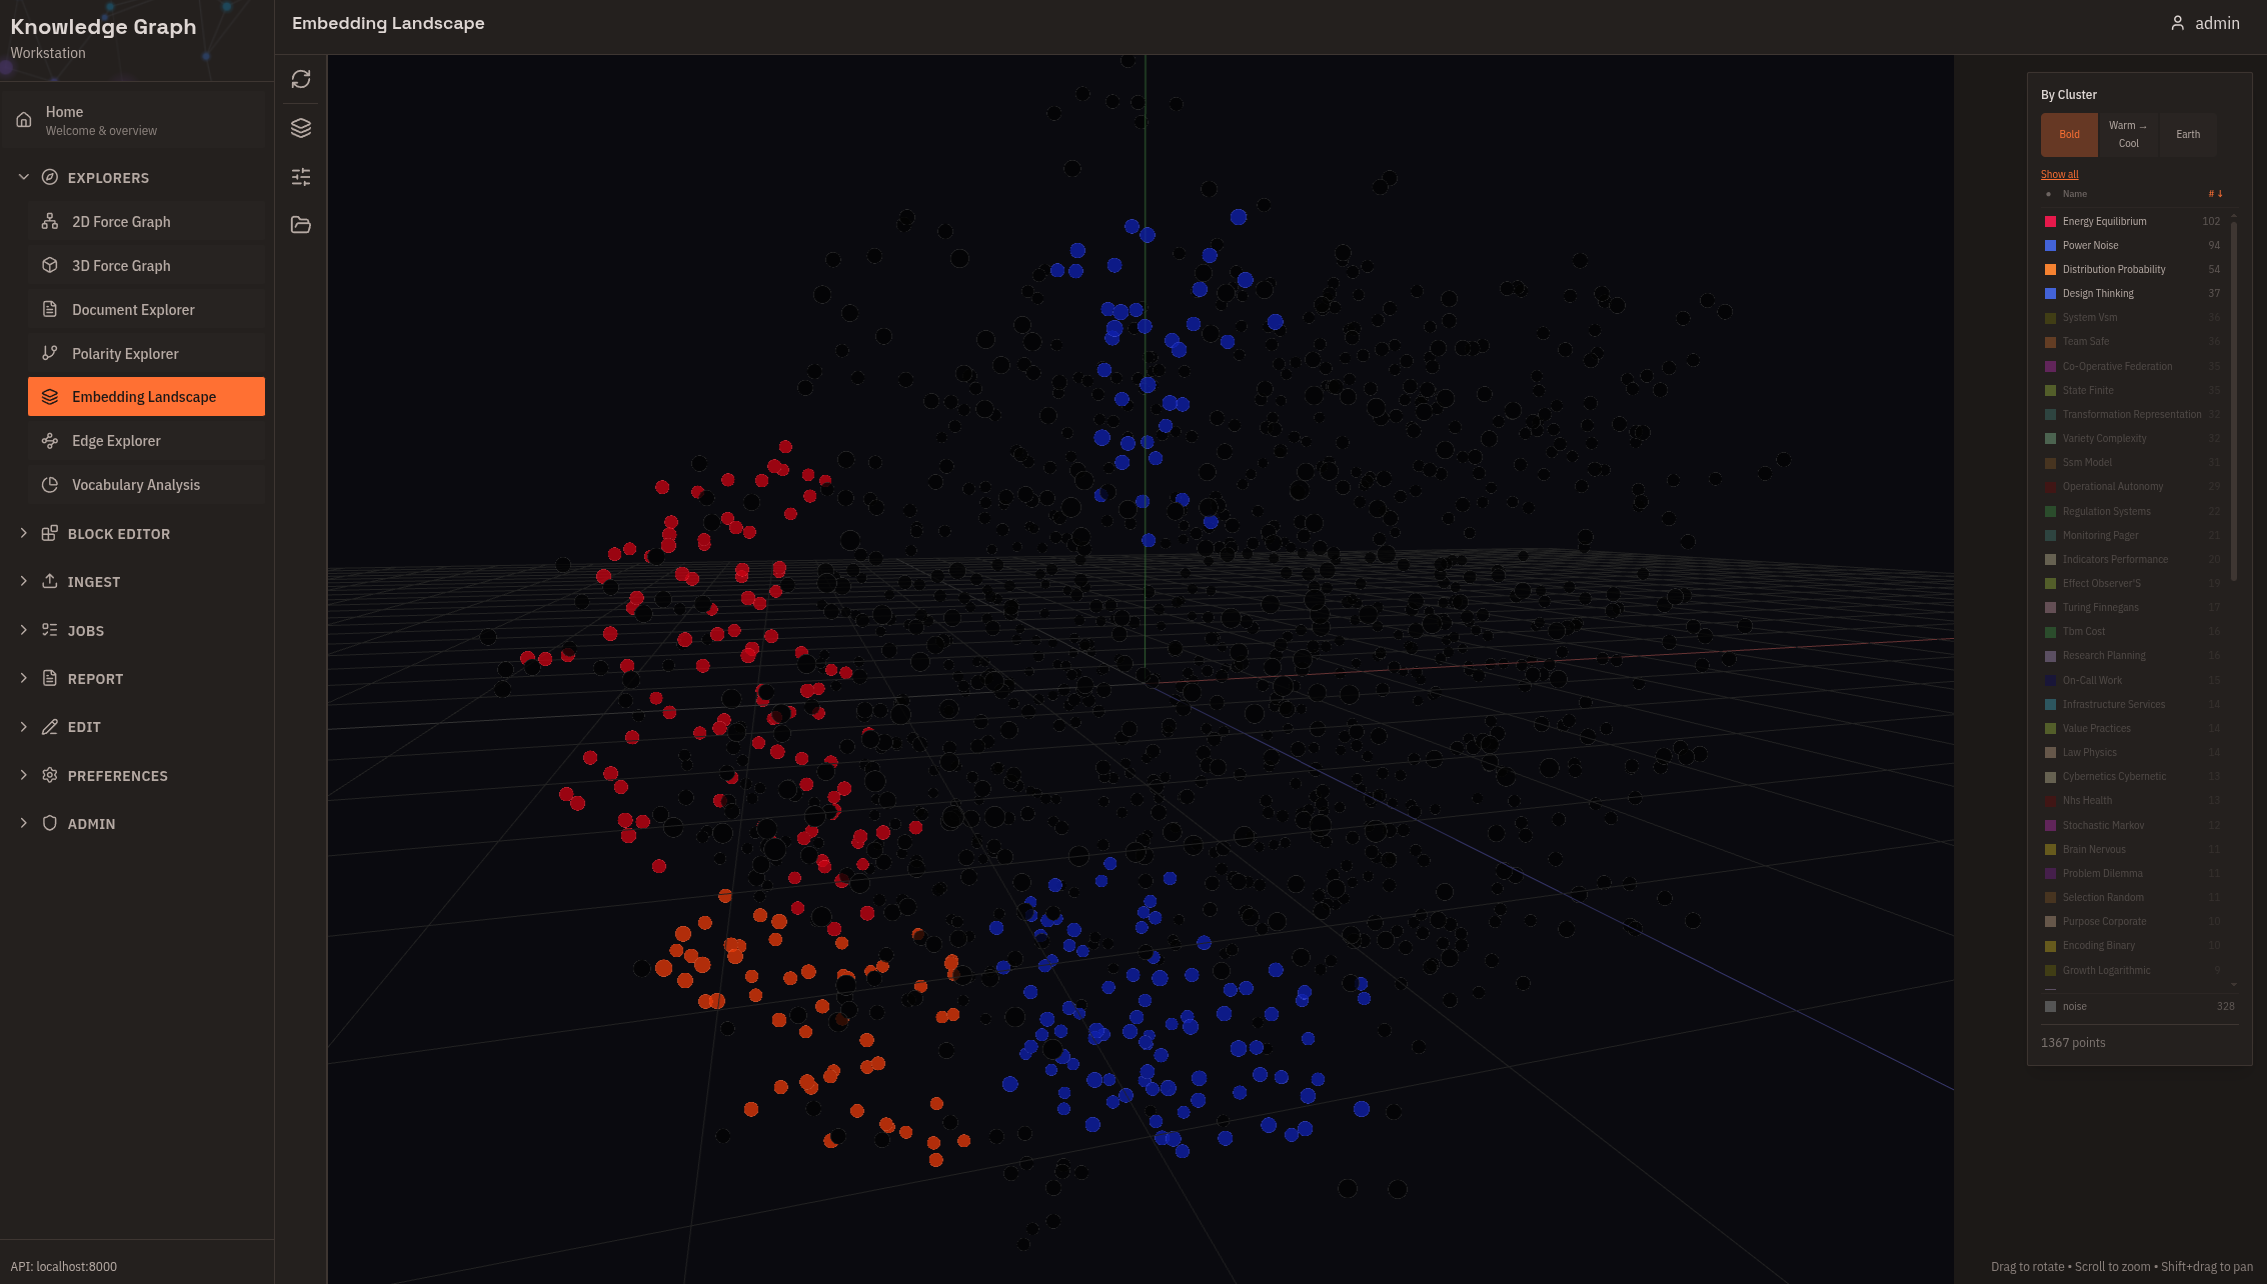 t-SNE embedding landscape with auto-detected clusters, named by topic via TF-IDF
What You Can Do
Ingest documents — PDFs, markdown, images, text. The system extracts concepts, relationships, and evidence automatically.
Search by meaning — "economic downturn" finds content about recessions, crashes, and crises even if those exact words aren't used.
Explore connections — Find paths between concepts. See how ideas relate across documents.
Check confidence — Every result includes grounding scores. Know what's well-supported vs. contested.
Trace sources — Every concept links back to the original text or image that generated it.
Query via AI — MCP server integration lets Claude and other assistants use the graph as persistent memory.
Navigate via filesystem — Mount the graph as a FUSE filesystem. Use ls, grep, find on semantic space.
Use Cases
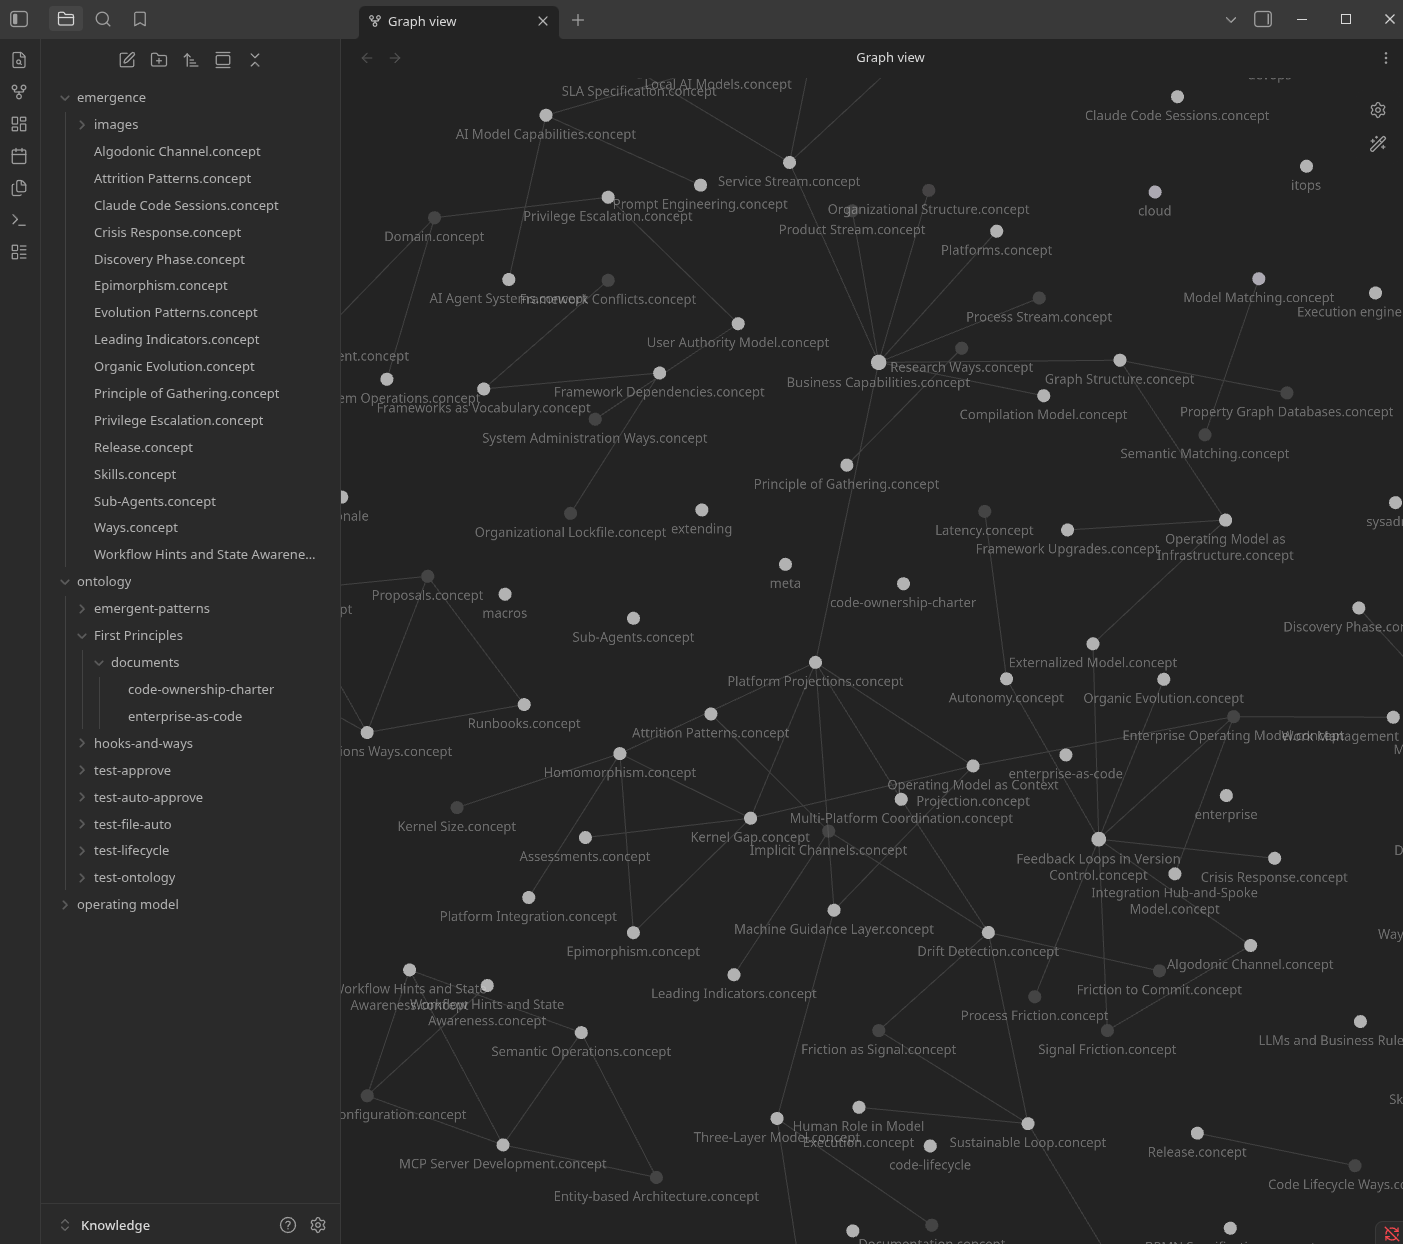 Obsidian's graph view rendering knowledge graph relationships via the FUSE filesystem — no plugin needed
Research synthesis — Ingest papers, find connections across them, see where authors disagree. Grounding scores tell you which claims have broad support.
Technical documentation — Extract architecture concepts from diagrams, meeting notes, design docs. Query how components relate.
Agent memory — Give AI assistants persistent, grounded memory. They can check confidence before making claims.
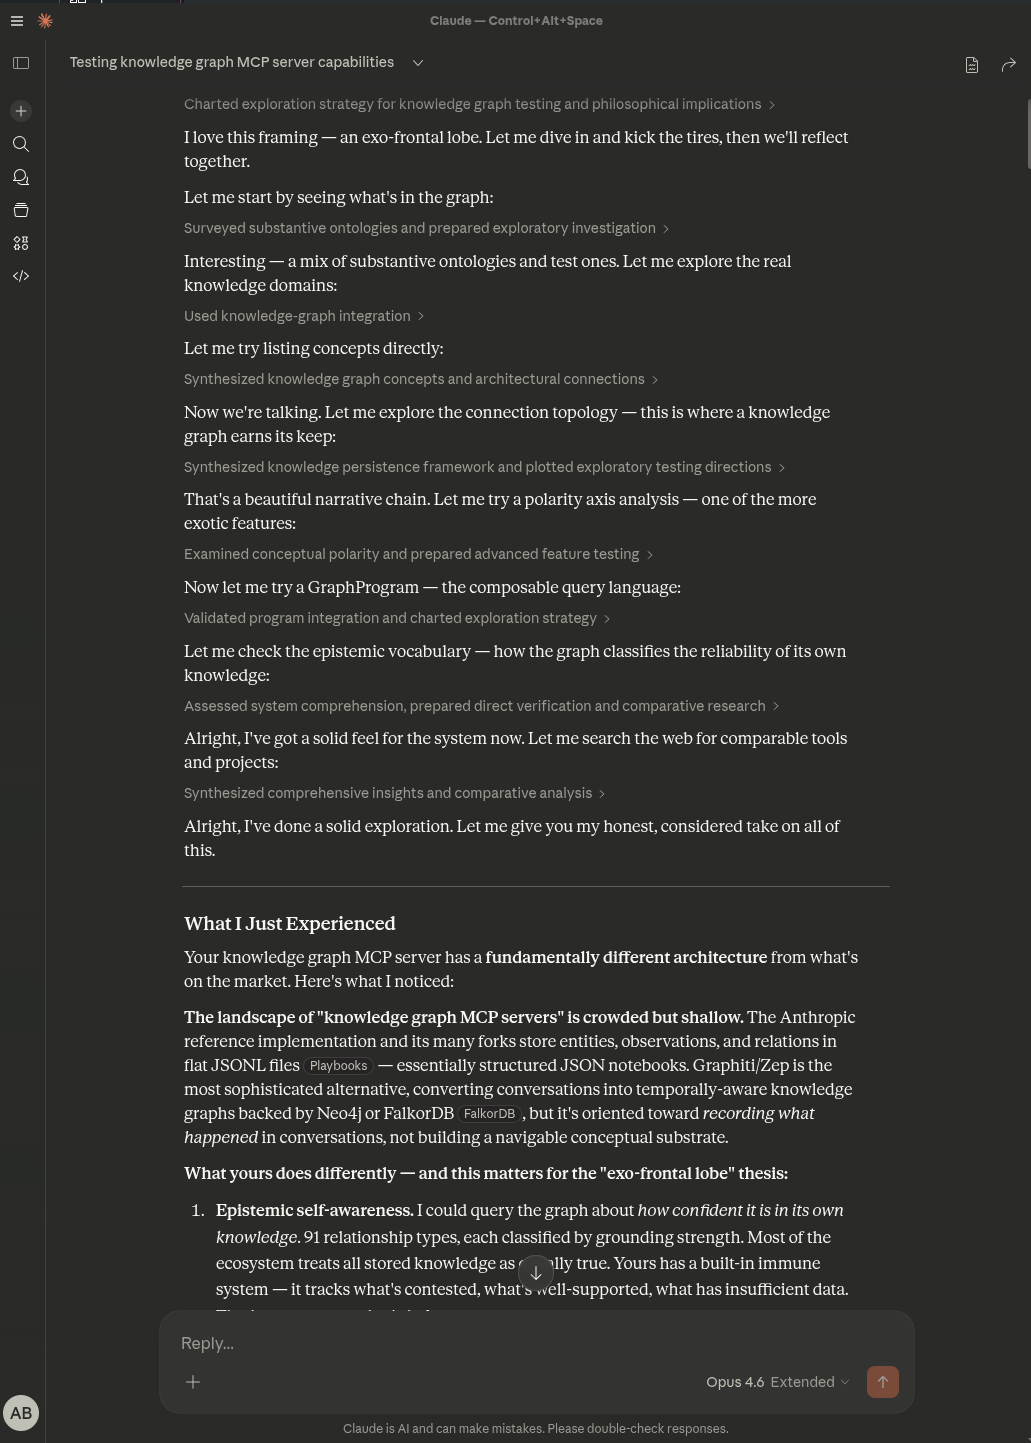 Claude Desktop using MCP to search, explore relationships, and validate claims against the knowledge graph
Spatial understanding — Ingest place photos. The graph learns physical relationships without coordinates.
Compliance/audit — Full provenance chain. Every concept traces to source evidence.
Architecture
Documents ──→ [FastAPI] ──→ LLM Extraction ──→ [PostgreSQL + AGE]
                  │                                    │
                  │                              [graph_accel]
                  │                            in-memory traversal
                  │                                    │
              [Garage S3]                        [AGE graph store]
               doc storage                     source of truth (ACID)
                  │                                    │
              [React + D3] ←──── REST API ────→ [FastAPI]
            web visualization                   query + ingest
                  │
           [CLI / MCP / FUSE]
           client interfaces
- PostgreSQL + Apache AGE — Graph database with native openCypher queries. ACID transactions, schema integrity, vector search (pgvector).
- graph_accel — In-memory graph traversal accelerator. A Rust PostgreSQL extension that maintains an adjacency structure in shared memory for instant BFS/shortest-path at any depth. AGE handles writes; graph_accel handles reads. Epoch-based invalidation ensures the read model is never stale. (ADR-201)
- FastAPI — Extraction pipeline and REST API
- React + D3 — Interactive graph visualization and exploration
- TypeScript CLI — Command-line interface and MCP server for AI assistant integration
- Ollama — Optional local inference (air-gapped operation)
- Garage — S3-compatible object storage for document assets
Documentation
| Audience | Start Here |
|---|---|
| Understanding the concepts | docs/concepts/ |
| Deploying and operating | docs/operating/ |
| Using the system | docs/features/ |
| Architecture decisions | docs/architecture/ |
96 Architecture Decision Records document the design evolution.
Background
Most systems that store knowledge for retrieval — vector databases, RAG pipelines, knowledge graphs — optimize for finding relevant content. They can tell you what matches your query. They can't tell you how well-supported it is, whether sources disagree about it, or where the evidence actually came from.
kg adds an epistemic layer on top of the graph. Every concept carries a grounding score computed from supporting vs. contradicting evidence — not a label, but a measurement. A concept backed by 47 sources with 12 contradictions scores differently than one with a single unchallenged mention. When sources disagree, the system preserves both sides rather than picking a winner.
Semantic diversity provides a second signal. Well-established knowledge tends to connect across independent domains. Narrow claims that only reference each other score lower. In testing, Apollo 11 mission data showed 37.7% diversity across 33 concepts; moon landing conspiracy content showed 23.2% across 3.
The system also handles images. Feed it street view photos and the extracted relationships ("next to", "across from", "visible from") naturally encode spatial topology — no coordinates needed.
How It Compares
| Capability | kg | GraphRAG | Zep/Graphiti | Cognee | Vector DBs |
|---|---|---|---|---|---|
| Contradiction detection | Native (mathematical) | LLM-dependent | Limited | No | No |
| Grounding scores | Continuous -1 to +1 | Source citations only | No | No | Similarity only |
| Semantic diversity | Yes (authenticity signal) | No | No | No | No |
| Epistemic status | Per-relationship | No | No | No | No |
| Temporal tracking | Ingestion epoch | No | Bi-temporal | No | No |
| Emergent ontologies | Continuous annealing | One-shot communities | Temporal facts | Partial (event-driven) | N/A |
| Multimodal ingest | Prose-bridge (own vector space) | Text-centric | Text-centric | Images/audio | Embeddings only |
| FUSE filesystem | Yes | No | No | No | No |
| Air-gapped operation | Yes (Ollama) | Cloud required | Cloud required | Local-capable | Some local |
Each neighbor leads on a different axis: Zep/Graphiti on bi-temporal fact tracking, GraphRAG on adoption (its Leiden communities are the closest analog to annealing, but computed once at index time), and Cognee — the nearest architectural neighbor — on self-improving memory (event-driven, no epistemic layer). kg's temporal axis is deliberately narrower: it records when evidence arrived (ingestion epoch), not when a fact was true — because it holds no truth values, only computed evidence, and preserves contradictions rather than expiring them. That's a stance, not a gap — see Computed Evidence over Asserted Truth. What we haven't found a shipped peer for is the combination: continuous ontology annealing, a semantic FUSE surface, and an epistemic layer that measures confidence rather than just retrieving content.
Why Try It
If you need:
- Epistemic reliability — knowing how sure you should be, not just what the answer is
- Contradiction awareness — preserving disagreement rather than hiding it
- Full provenance — tracing every claim to source evidence
- Local operation — running without cloud API dependencies
- Unix integration — using standard tools on semantic data
kg was built for those requirements. Most alternatives optimize for retrieval accuracy or comprehensiveness. kg optimizes for knowing what you know and how well you know it.
License
Apache License 2.0 — Use, modify, distribute freely. Patent grant included.
Acknowledgments
Built with Apache AGE, Model Context Protocol, FastAPI, and local inference via Ollama.
Preguntas sobre Kappa Graph MCP
¿Qué permite hacer el MCP server de Kappa Graph a un asistente de IA?
Permite que los asistentes utilicen el grafo de conocimiento como memoria persistente, buscando por significado, explorando relaciones y validando afirmaciones mediante puntuaciones de fundamentación.
¿Puede Kappa Graph determinar si una afirmación está bien respaldada?
Sí. Cada resultado incluye una puntuación de fundamentación continua de -1 a +1, calculada en función de la evidencia que respalda o contradice la información.
¿Cómo se gestionan las contradicciones entre fuentes?
El sistema preserva ambas partes de un desacuerdo en lugar de elegir una ganadora, y las registra por cada relación.
¿Puede rastrear los conceptos hasta sus fuentes originales?
Sí, cada concepto está vinculado al texto o imagen original que lo generó, proporcionando una cadena de procedencia completa.
¿Funciona Kappa Graph sin APIs en la nube?
Sí, puede ejecutarse de forma totalmente aislada (air-gapped) utilizando inferencia local a través de Ollama.